ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
Tokenizer Class Reference

A lightweight tokenizer implementation for text processing. More...

#include <tokenizer.h>
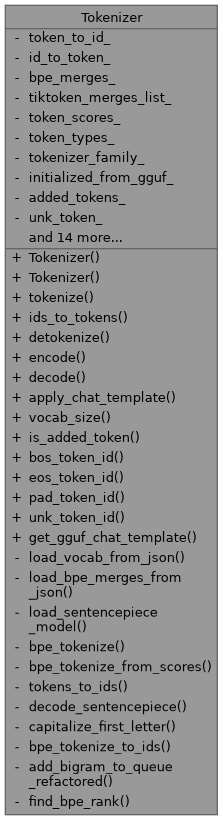
Collaboration diagram for Tokenizer:
Collaboration graph

Public Types

enum  PreTokenizeMethod { DEFAULT , LLAMA_REGEX }
 Enumeration of available pre-tokenization methods. More...
 
enum class  Type { UNKNOWN , SENTENCEPIECE_BPE , TIKTOKEN_BPE }
 

Public Member Functions

 Tokenizer (const std::string &vocab_path, const std::string &model_path, const ModelConfig &config)
 Constructs a tokenizer from vocabulary and model files (for Llama 2 style JSON)
 
 Tokenizer (const GGUFData &gguf_data, const ModelConfig &config)
 Constructs a tokenizer from GGUF format data.
 
std::vector< std::string > tokenize (const std::string &text) const
 Tokenizes input text into token strings.
 
std::vector< std::string > ids_to_tokens (const std::vector< int > &ids) const
 Converts token IDs back to token strings.
 
std::string detokenize (const std::vector< std::string > &tokens) const
 Combines tokens back into text.
 
std::vector< int > encode (const std::string &text, bool add_bos=true, bool add_eos=false, PreTokenizeMethod pre_tok_override=PreTokenizeMethod::DEFAULT) const
 Encodes text into token IDs with optional special tokens.
 
std::string decode (const std::vector< int > &ids, bool skip_special_tokens=true) const
 Decodes token IDs back to text.
 
std::string apply_chat_template (const std::string &user_prompt, const std::string &system_message, const ModelConfig &config) const
 Applies chat template formatting to the input prompt.
 
int vocab_size () const
 Returns the size of the vocabulary.
 
bool is_added_token (int id) const
 Checks if a token ID represents an added token.
 
int bos_token_id () const
 Gets the beginning-of-sequence token ID.
 
int eos_token_id () const
 Gets the end-of-sequence token ID.
 
int pad_token_id () const
 Gets the padding token ID.
 
int unk_token_id () const
 Gets the unknown token ID.
 
const std::string & get_gguf_chat_template () const
 

Private Member Functions

void load_vocab_from_json (const std::string &vocab_path, std::unordered_map< std::string, int > &token_to_id, std::vector< std::string > &id_to_token)
 Loads vocabulary from JSON file.
 
void load_bpe_merges_from_json (const std::string &model_path)
 Loads BPE merge rules from JSON file.
 
void load_sentencepiece_model (const std::string &model_path)
 Loads a SentencePiece model.
 
std::vector< std::string > bpe_tokenize (const std::string &text) const
 
std::vector< std::string > bpe_tokenize_from_scores (const std::string &text) const
 
std::vector< int > tokens_to_ids (const std::vector< std::string > &tokens) const
 
std::string decode_sentencepiece (const std::vector< int > &ids, bool skip_special_tokens) const
 
std::string capitalize_first_letter (std::string s) const
 
std::vector< int > bpe_tokenize_to_ids (const std::string &text, bool add_bos_token_param, bool add_eos_token_param, bool ignore_merges_param) const
 
void add_bigram_to_queue_refactored (const char *text_data_base, const std::vector< llm_symbol > &symbols, llm_symbol::index first_symbol_idx, std::priority_queue< std::pair< int, int >, std::vector< std::pair< int, int > >, std::greater< std::pair< int, int > > > &work_queue) const
 
int find_bpe_rank (const std::string &token_left, const std::string &token_right) const
 

Private Attributes

std::unordered_map< std::string, int > token_to_id_
 
std::vector< std::string > id_to_token_
 
std::unordered_map< std::string, int > bpe_merges_
 
std::vector< std::string > tiktoken_merges_list_
 
std::vector< float > token_scores_
 
std::vector< int32_t > token_types_
 
ModelConfig::TokenizerFamily tokenizer_family_ = ModelConfig::TokenizerFamily::UNKNOWN
 
bool initialized_from_gguf_ = false
 
std::unordered_map< std::string, int > added_tokens_
 
std::string unk_token_
 
std::string bos_token_
 
std::string eos_token_
 
std::string pad_token_
 
int unk_token_id_ = 0
 
int bos_token_id_ = -1
 
int eos_token_id_ = -1
 
int pad_token_id_ = -1
 
bool sentencepiece_model_loaded_ = false
 
std::string pre_tok_type_ = "unknown"
 
std::unordered_map< int, std::string > id_to_added_token_
 
std::unordered_set< std::string > chat_template_special_tokens
 
std::unordered_map< char, int > byte_char_to_id_
 
Type type_ = Type::UNKNOWN
 
std::string gguf_chat_template_
 

Detailed Description

A lightweight tokenizer implementation for text processing.

This tokenizer class provides basic text tokenization functionality without external dependencies. It supports multiple tokenization methods including space-based, BPE (Byte-Pair Encoding), and regex-based tokenization. The tokenizer can be initialized either from a vocabulary file or from GGUF format data.

Definition at line 61 of file tokenizer.h.

Member Enumeration Documentation

◆ PreTokenizeMethod

Enumeration of available pre-tokenization methods.

Enumerator
DEFAULT 

Use the default tokenization method specified during initialization

LLAMA_REGEX 

LLaMA-style regex-based tokenization

Definition at line 66 of file tokenizer.h.

66 {
67 DEFAULT,
69 };
@ LLAMA_REGEX
Definition tokenizer.h:68

◆ Type

Enumerator
UNKNOWN 
SENTENCEPIECE_BPE 
TIKTOKEN_BPE 

Definition at line 71 of file tokenizer.h.

Constructor & Destructor Documentation

◆ Tokenizer() [1/2]

Tokenizer::Tokenizer ( const std::string &  vocab_path,
const std::string &  model_path,
const ModelConfig &  config 
)

Constructs a tokenizer from vocabulary and model files (for Llama 2 style JSON)

Parameters
vocab_pathPath to the JSON vocabulary file
model_pathPath to the JSON model file containing BPE merges (optional)
configThe model configuration (used to get special token IDs if not in vocab file)

Definition at line 285 of file tokenizer.cpp.

288 : tokenizer_family_(config.tokenizer_family),
289 unk_token_("<unk>"),
290 bos_token_("<s>"),
291 eos_token_("</s>"),
292 pad_token_("<pad>") {
293 Logger::info("[Tokenizer Constructor JSON] vocab_path: '" + vocab_path + "', model_path: '" + model_path + "'"); // Diagnostic log
294 try {
295 std::filesystem::path vocab_json_path_abs(vocab_path);
296 if (!std::filesystem::exists(vocab_json_path_abs)) {
297 throw std::runtime_error("Tokenizer vocab_path (tokenizer.json) does not exist: " + vocab_json_path_abs.string());
298 }
299
300 Logger::info(std::string("Loading tokenizer and vocab from: ") + vocab_json_path_abs.string());
301 std::string family_str = "UNKNOWN";
304 Logger::info(std::string("Tokenizer family based on config: ") + family_str);
305
307
309 Logger::info("LLAMA_SENTENCEPIECE family detected for JSON constructor, attempting to load BPE merges from: " + vocab_json_path_abs.string());
311 }
312
313 unk_token_id_ = (token_to_id_.count(unk_token_)) ? token_to_id_[unk_token_] : config.bos_token_id; // Fallback to BOS if UNK not in vocab
317
318 if (bos_token_id_ >= 0 && static_cast<size_t>(bos_token_id_) < id_to_token_.size() && !token_to_id_.count(bos_token_)) bos_token_ = id_to_token_[bos_token_id_];
319 if (eos_token_id_ >= 0 && static_cast<size_t>(eos_token_id_) < id_to_token_.size() && !token_to_id_.count(eos_token_)) eos_token_ = id_to_token_[eos_token_id_];
320 if (unk_token_id_ >= 0 && static_cast<size_t>(unk_token_id_) < id_to_token_.size() && !token_to_id_.count(unk_token_)) unk_token_ = id_to_token_[unk_token_id_];
321 if (pad_token_id_ >= 0 && static_cast<size_t>(pad_token_id_) < id_to_token_.size()) pad_token_ = id_to_token_[pad_token_id_];
322
323 Logger::info("Final Special Tokens (JSON constructor path): BOS=" + std::to_string(bos_token_id_) +
324 " ('" + bos_token_ + "'), EOS=" + std::to_string(eos_token_id_) + " ('" +
325 eos_token_ + "'), UNK=" + std::to_string(unk_token_id_) + " ('" +
326 unk_token_ + "'), PAD=" + std::to_string(pad_token_id_) + " ('" +
327 pad_token_ + "')"); // Removed extra backslashes from PAD log
328
329 std::string init_log_message = "Tokenizer successfully initialized from JSON/Config. Detected type based on config: ";
331 (tokenizer_family_ == ModelConfig::TokenizerFamily::LLAMA_SENTENCEPIECE ? "LLAMA_SENTENCEPIECE (assumed BPE/SPM)" : "UNKNOWN"));
333
334 if (model_path.size() > 0) {
335 if (model_path.size() > 6 &&
336 model_path.substr(model_path.size() - 6) == ".model") {
337 Logger::info("Loading SentencePiece model: " + model_path);
339 } else if (model_path.size() > 5 &&
340 model_path.substr(model_path.size() - 5) == ".json") {
341 Logger::info("Loading BPE merges from JSON: " + model_path);
343 } else {
344 Logger::info("Unsupported model format: " + model_path +
345 " - falling back to space tokenization");
346 }
347 } else {
349 "No model path provided - falling back to space tokenization");
350 }
351 } catch (const std::exception& e) {
352 std::cerr << "Failed to load tokenizer or vocab from " << vocab_path << ": "
353 << e.what() << std::endl;
354 Logger::error(std::string("Failed to load tokenizer or vocab from \"") +
355 vocab_path + "\": " + e.what());
356 throw;
357 }
358
359 if (id_to_token_.empty()) {
360 throw std::runtime_error(
361 "Failed to initialize tokenizer vocabulary from: " + vocab_path);
362 }
363
364 Logger::info("Loaded " + std::to_string(id_to_token_.size()) +
365 " tokens from vocabulary file: " + vocab_path);
366
367 if (id_to_token_.size() > 0) {
368 std::string first_few_tokens_log = "First few (up to 10 or vocab size) tokens from " + vocab_path + ": ";
369 for (size_t i = 0; i < std::min((size_t)10, id_to_token_.size()); ++i) {
370 first_few_tokens_log += "ID[" + std::to_string(i) + "]=";
371 std::string escaped_token;
372 for (char c_tok : id_to_token_[i]) {
373 if (c_tok == '\\') {
374 escaped_token += "\\\\";
375 } else if (c_tok == '\'') {
376 escaped_token += "\\'";
377 } else if (std::isprint(static_cast<unsigned char>(c_tok))) {
379 } else {
380 std::stringstream ss_hex;
381 ss_hex << "<0x" << std::hex << std::setw(2) << std::setfill('0') << static_cast<int>(static_cast<unsigned char>(c_tok)) << ">";
382 escaped_token += ss_hex.str();
383 }
384 }
385 first_few_tokens_log += "'" + escaped_token + "' "; // Enclose in single quotes
386 }
388 }
389
390 const std::vector<std::pair<std::string, int>> known_chat_tokens = {
391 {"<|system|>", 32000}, {"<|user|>", 32001}, {"<|assistant|>", 32002}};
393 size_t vocab_size = id_to_token_.size();
394 for (const auto& pair : known_chat_tokens) {
395 const std::string& tok = pair.first;
396 int id = pair.second;
397
398 if (added_tokens_.find(tok) == added_tokens_.end() &&
399 static_cast<size_t>(id) >= vocab_size) {
403 Logger::info("[MANUAL INJECT] Added missing chat token: '" + tok +
404 "' with assumed ID: " + std::to_string(id));
405 } else if (added_tokens_.find(tok) != added_tokens_.end()) {
406 Logger::debug("[MANUAL INJECT] Chat token '" + tok +
407 "' already loaded from JSON. Skipping injection.");
408 } else {
409 Logger::warning("[MANUAL INJECT] Cannot add chat token '" + tok +
410 "', assumed ID " + std::to_string(id) +
411 " clashes with loaded vocab size (" +
412 std::to_string(vocab_size) + ").");
413 }
414 }
415 if (manually_injected_count > 0) {
416 Logger::info("Manually injected " +
417 std::to_string(manually_injected_count) +
418 " missing chat tokens.");
419 }
420}
static void debug(const std::string &message)
Definition logger.cpp:131
static void warning(const std::string &message)
Definition logger.cpp:139
static void info(const std::string &message)
Definition logger.cpp:135
static void error(const std::string &message)
Definition logger.cpp:143
int eos_token_id_
Definition tokenizer.h:224
int bos_token_id_
Definition tokenizer.h:223
std::unordered_map< std::string, int > token_to_id_
Definition tokenizer.h:205
std::unordered_map< int, std::string > id_to_added_token_
Definition tokenizer.h:229
void load_bpe_merges_from_json(const std::string &model_path)
Loads BPE merge rules from JSON file.
int pad_token_id_
Definition tokenizer.h:225
ModelConfig::TokenizerFamily tokenizer_family_
Definition tokenizer.h:211
void load_sentencepiece_model(const std::string &model_path)
Loads a SentencePiece model.
std::string unk_token_
Definition tokenizer.h:216
int unk_token_id_
Definition tokenizer.h:222
std::string eos_token_
Definition tokenizer.h:218
int vocab_size() const
Returns the size of the vocabulary.
void load_vocab_from_json(const std::string &vocab_path, std::unordered_map< std::string, int > &token_to_id, std::vector< std::string > &id_to_token)
Loads vocabulary from JSON file.
int eos_token_id() const
Gets the end-of-sequence token ID.
Definition tokenizer.h:169
std::string pad_token_
Definition tokenizer.h:219
int bos_token_id() const
Gets the beginning-of-sequence token ID.
Definition tokenizer.h:163
std::unordered_map< std::string, int > added_tokens_
Definition tokenizer.h:213
std::vector< std::string > id_to_token_
Definition tokenizer.h:206
std::string bos_token_
Definition tokenizer.h:217
Tok tok
size_t j

References added_tokens_, bos_token_, bos_token_id_, Logger::debug(), eos_token_, eos_token_id_, Logger::error(), id, id_to_added_token_, id_to_token_, Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, ModelConfig::LLAMA_SENTENCEPIECE, load_bpe_merges_from_json(), load_sentencepiece_model(), load_vocab_from_json(), pad_token_, pad_token_id_, tok, token_to_id_, tokenizer_family_, unk_token_, unk_token_id_, vocab_size(), and Logger::warning().

◆ Tokenizer() [2/2]

Tokenizer::Tokenizer ( const GGUFData &  gguf_data,
const ModelConfig &  config 
)
explicit

Constructs a tokenizer from GGUF format data.

Parameters
gguf_dataThe GGUF data containing tokenizer information
configThe model configuration (contains tokenizer_family, special token IDs etc.)

Definition at line 516 of file tokenizer.cpp.

517 : tokenizer_family_(config.tokenizer_family),
519 Logger::info("Initializing Tokenizer from GGUFData...");
520 std::string family_str_gguf = "UNKNOWN";
523 Logger::info(std::string("Tokenizer family from ModelConfig: ") + family_str_gguf);
524
525 // Attempt to load chat template from GGUF metadata
526 try {
527 auto it = gguf_data.metadata.find("tokenizer.chat_template");
528 if (it != gguf_data.metadata.end()) {
529 if (std::holds_alternative<std::string>(it->second)) {
530 gguf_chat_template_ = std::get<std::string>(it->second);
531 if (!gguf_chat_template_.empty()) {
532 Logger::info("[Tokenizer GGUF Init] Found and loaded 'tokenizer.chat_template' from GGUF metadata.");
533 // Further log the template content if it's not too long, or a snippet
534 size_t log_len = std::min(gguf_chat_template_.length(), (size_t)70); // Log up to 70 chars
535 std::string template_snippet = gguf_chat_template_.substr(0, log_len);
536 if (gguf_chat_template_.length() > log_len) template_snippet += "...";
537 // Replace newlines with printable \n for one-line logging
538 std::string loggable_snippet;
539 for (char ch : template_snippet) {
540 if (ch == '\n') loggable_snippet += "\\n";
541 else if (ch == '\r') loggable_snippet += "\\r";
542 else if (ch == '\t') loggable_snippet += "\\t";
543 else if (std::isprint(static_cast<unsigned char>(ch))) loggable_snippet += ch;
544 else loggable_snippet += "."; // Replace non-printable with a dot
545 }
546 Logger::debug("[Tokenizer GGUF Init] Chat template snippet: " + loggable_snippet);
547 } else {
548 Logger::info("[Tokenizer GGUF Init] 'tokenizer.chat_template' found in GGUF metadata but is empty.");
549 }
550 } else {
551 Logger::warning("[Tokenizer GGUF Init] 'tokenizer.chat_template' found in GGUF metadata but is not a string type.");
552 }
553 } else {
554 Logger::info("[Tokenizer GGUF Init] 'tokenizer.chat_template' not found in GGUF metadata.");
555 }
556 } catch (const std::exception& e) {
557 Logger::error("[Tokenizer GGUF Init] Exception while trying to access 'tokenizer.chat_template': " + std::string(e.what()));
558 }
559
560 if (gguf_data.tokenizer_tokens.empty()) {
561 throw std::runtime_error(
562 "GGUF data does not contain 'tokenizer.ggml.tokens'");
563 }
564
565 // Common vocabulary loading
566 id_to_token_ = gguf_data.tokenizer_tokens;
567 token_to_id_.clear(); // Ensure map is clear before populating
568 token_to_id_.reserve(id_to_token_.size());
569 for (size_t i = 0; i < id_to_token_.size(); ++i) {
570 token_to_id_[id_to_token_[i]] = static_cast<int>(i);
571
572 if (static_cast<int>(i) == 1734) {
573 const std::string& token_at_1734 = id_to_token_[i];
574 std::string escaped_token_1734;
575 for (char c : token_at_1734) {
576 if (c == '\n') escaped_token_1734 += "\\n";
577 else if (c == '\r') escaped_token_1734 += "\\r";
578 else if (c == '\t') escaped_token_1734 += "\\t";
579 else if (c == '\\') escaped_token_1734 += "\\\\";
580 else if (std::isprint(static_cast<unsigned char>(c))) escaped_token_1734 += c;
581 else {
582 std::stringstream ss_hex;
583 ss_hex << "<0x" << std::hex << std::setw(2) << std::setfill('0') << static_cast<int>(static_cast<unsigned char>(c)) << ">";
584 escaped_token_1734 += ss_hex.str();
585 }
586 }
587 Logger::info("[GGUF_VOCAB_SCAN] Token string at ID 1734 is: '" + escaped_token_1734 + "' (length: " + std::to_string(token_at_1734.length()) + ")");
588 }
589
590 }
591 Logger::info("Loaded " + std::to_string(id_to_token_.size()) +
592 " tokens from GGUF tokenizer_tokens.");
593
594 // Log first few tokens for inspection
595 if (id_to_token_.size() > 0) {
596 std::string first_few_tokens_log = "First few (up to 10 or vocab size) GGUF tokens: ";
597 for (size_t i = 0; i < std::min((size_t)10, id_to_token_.size()); ++i) {
598 first_few_tokens_log += "ID[" + std::to_string(i) + "]='";
599 // Safely print token, escaping non-printables for logging
600 for (char c_tok : id_to_token_[i]) {
601 if (std::isprint(static_cast<unsigned char>(c_tok))) {
603 } else {
604 std::stringstream ss_hex;
605 ss_hex << "<0x" << std::hex << std::setw(2) << std::setfill('0') << static_cast<int>(static_cast<unsigned char>(c_tok)) << ">";
607 }
608 }
609 first_few_tokens_log += "' ";
610 }
612 }
613
614 // Conditional loading based on family
617 Logger::info("Configuring for LLAMA3_TIKTOKEN (gpt2-style BPE).");
618
619 if (gguf_data.tokenizer_merges.empty()) {
620 Logger::warning("Llama 3 Tiktoken family specified, but GGUF data does not contain 'tokenizer.ggml.merges'. Tiktoken BPE may not function correctly without explicit merges.");
621 } else {
622 bpe_merges_.clear();
623 int rank = 0;
624 // Removed sample_merges vector and related logging logic
625 for (const std::string& merge_str : gguf_data.tokenizer_merges) {
626 std::string part1, part2;
627 size_t space_pos = merge_str.find(' ');
628 if (space_pos != std::string::npos && space_pos > 0 && space_pos < merge_str.length() - 1) {
629 part1 = merge_str.substr(0, space_pos);
630 part2 = merge_str.substr(space_pos + 1);
631 std::string merged = part1 + part2;
632 bpe_merges_[merged] = rank++; // Simplified rank assignment
633 } else {
634 Logger::warning("Skipping malformed Tiktoken merge rule from GGUF: '" + merge_str + "'");
635 }
636 }
637
638 Logger::info("Processed " + std::to_string(bpe_merges_.size()) +
639 " Tiktoken merges from GGUF tokenizer_merges into bpe_merges_ map with ranks.");
640 }
641 // Scores are usually not the primary driver for Tiktoken BPE but load if present.
642 if (!gguf_data.tokenizer_scores.empty()) {
643 Logger::info("Llama 3 GGUF contains " + std::to_string(gguf_data.tokenizer_scores.size()) + " scores. Loaded.");
644 token_scores_ = gguf_data.tokenizer_scores;
645 }
646
647 // DEBUGGING: Log vocab/merges for neoplasm
648 Logger::debug("[DEBUG_VOCAB] LLAMA3_TIKTOKEN bpe_merges_ size: " + std::to_string(bpe_merges_.size()));
649 std::string target_token_neoplasm = BPE_SPACE_CHAR + "neoplasm"; // "Ä neoplasm"
650 std::string target_sub_ne = BPE_SPACE_CHAR + "ne"; // "Ä ne"
651 std::string target_sub_o = BPE_SPACE_CHAR + "o"; // "Ä o"
652 std::string target_sub_oplasm = "oplasm";
653 std::string target_sub_goplasm = BPE_SPACE_CHAR + "oplasm"; // "Ä oplasm"
654
655 auto check_and_log_vocab = [&](const std::string& token_to_check) {
656 if (token_to_id_.count(token_to_check)) {
657 Logger::debug("[DEBUG_VOCAB] Found '" + token_to_check + "' in vocab with ID: " + std::to_string(token_to_id_.at(token_to_check)));
658 } else {
659 Logger::debug("[DEBUG_VOCAB] Token '" + token_to_check + "' NOT FOUND in vocab.");
660 }
661 };
662
663 auto check_and_log_merge = [&](const std::string& p1, const std::string& p2) {
664 auto merge_it = bpe_merges_.find(p1 + p2);
665 if (merge_it != bpe_merges_.end()) {
666 Logger::debug("[DEBUG_VOCAB] Found merge for '" + p1 + "' + '" + p2 + "' ('" + (p1+p2) + "') with rank: " + std::to_string(merge_it->second));
667 } else {
668 Logger::debug("[DEBUG_VOCAB] Merge for '" + p1 + "' + '" + p2 + "' ('" + (p1+p2) + "') NOT FOUND.");
669 }
670 };
671
674 Logger::info("Configuring for LLAMA_SENTENCEPIECE.");
675 if (!gguf_data.tokenizer_scores.empty()) {
676 token_scores_ = gguf_data.tokenizer_scores;
677 Logger::info("Loaded " + std::to_string(token_scores_.size()) + " token scores from GGUF for SentencePiece style.");
678 if (id_to_token_.size() != token_scores_.size()) {
679 Logger::warning("GGUF (SentencePiece path) token and score array sizes mismatch: tokens=" +
680 std::to_string(id_to_token_.size()) + ", scores=" + std::to_string(token_scores_.size()));
681 }
682 } else {
683 Logger::warning("SentencePiece family: No scores found. BPE merging will likely not work if no other SP model data is available.");
684 }
685
686
687 if (!gguf_data.tokenizer_merges.empty()) {
688 Logger::info("SentencePiece family path: Found 'tokenizer.ggml.merges' in GGUF. Loading them into bpe_merges_ map.");
689 bpe_merges_.clear();
690 int rank = 0;
691 for (const std::string& merge_str : gguf_data.tokenizer_merges) {
692 std::string part1, part2;
693 size_t space_pos = merge_str.find(' ');
694 if (space_pos != std::string::npos && space_pos > 0 && space_pos < merge_str.length() - 1) {
695 part1 = merge_str.substr(0, space_pos);
696 part2 = merge_str.substr(space_pos + 1);
697 bpe_merges_[part1 + part2] = rank++;
698 } else {
699 Logger::warning("Skipping malformed SentencePiece merge rule from GGUF: '" + merge_str + "'");
700 }
701 }
702 Logger::info("Processed " + std::to_string(bpe_merges_.size()) +
703 " merges from GGUF tokenizer_merges into bpe_merges_ map (SentencePiece path).");
704 } else {
705 Logger::warning("SentencePiece family path: No 'tokenizer.ggml.merges' found in GGUF. Attempting to generate merges from vocabulary and scores...");
706
707 // Generate BPE merges from vocabulary and scores (llama.cpp approach)
709 if (!generated_merges.empty()) {
710 bpe_merges_ = std::move(generated_merges);
711 Logger::info("Successfully generated " + std::to_string(bpe_merges_.size()) + " BPE merges from vocabulary and scores for SentencePiece tokenizer");
712 } else {
713 Logger::warning("Failed to generate BPE merges. Tokenization may be suboptimal for this model.");
714 }
715 }
716
717
718 } else { // UNKNOWN tokenizer family
720 Logger::warning("Tokenizer family is UNKNOWN. Tokenizer may not function as expected. Will attempt to load basic vocab and scores if present.");
721 if (!gguf_data.tokenizer_scores.empty()) {
722 token_scores_ = gguf_data.tokenizer_scores;
723 Logger::info("Loaded " + std::to_string(token_scores_.size()) + " token scores from GGUF for UNKNOWN family as a fallback.");
724 }
725 }
726
727 if (!gguf_data.tokenizer_token_types.empty() && gguf_data.tokenizer_token_types.size() == id_to_token_.size()){
728 token_types_.resize(gguf_data.tokenizer_token_types.size());
729 std::transform(gguf_data.tokenizer_token_types.begin(),
730 gguf_data.tokenizer_token_types.end(), token_types_.begin(),
731 [](unsigned int u) { return static_cast<int32_t>(u); });
732 Logger::info("Loaded and transformed " + std::to_string(token_types_.size()) + " token types from GGUF.");
733
734 // Populate byte_char_to_id_ and added_tokens_ using token_types_
735 byte_char_to_id_.clear();
736 added_tokens_.clear();
737 id_to_added_token_.clear();
738 int byte_tokens_from_type = 0;
740
741 for (size_t i = 0; i < token_types_.size(); ++i) {
743 const std::string& token_str = id_to_token_[i];
744 int token_id = static_cast<int>(i);
745 bool processed_as_byte = false; // Flag to track if token was handled as byte
746
747 if (tt == 6) { // LLAMA_TOKEN_TYPE_BYTE
748 bool added_byte = false;
749 if (token_str.length() == 1) {
751 added_byte = true;
752 } else if (token_str.rfind("<0x", 0) == 0 && token_str.back() == '>' && token_str.length() == 6) {
753 try {
754 int byte_val = std::stoi(token_str.substr(3, 2), nullptr, 16);
755 byte_char_to_id_[static_cast<char>(byte_val)] = token_id;
756 added_byte = true;
757 } catch (const std::exception& e) {
758 Logger::warning("Could not parse byte value from type-BYTE (6) token string: '" + token_str + "'");
759 }
760 } else {
761 // Log if a token is marked as BYTE but doesn't match expected formats
762 Logger::warning("Token type is BYTE (6) but does not match single char or <0xNN> format: '" + token_str + "' ID: " + std::to_string(token_id));
763 }
764
765 if(added_byte) {
767 processed_as_byte = true;
768 }
769 }
770 if (!processed_as_byte && (tt == 2 || tt == 3 || tt == 4 || tt == 5)) {
771 if (added_tokens_.find(token_str) == added_tokens_.end()) {
775 }
776 }
777 }
778 // Log message now reflects bytes identified from type 6 tokens
779 Logger::info("From GGUF token_types (BYTE=6): Identified " + std::to_string(byte_tokens_from_type) + " byte tokens (for byte_char_to_id_). " +
780 "Identified " + std::to_string(special_tokens_from_type) + " other special/added tokens (types 2,3,4,5).");
781
782
783 // If token types were processed but yielded no byte tokens for Tiktoken, try the fallback vocab scan.
785 Logger::warning("No byte tokens identified via token_types metadata for Tiktoken. Attempting fallback scan of vocabulary.");
786 // Manually populate byte_char_to_id_ by checking vocab for <0xNN> and literal byte strings
787 byte_char_to_id_.clear(); // Clear again in case some non-byte type 3 were added incorrectly before
789 for (int i = 0; i < 256; ++i) {
790 std::stringstream ss_hex_repr;
791 ss_hex_repr << "<0x" << std::hex << std::setw(2) << std::setfill('0') << i << ">";
792 std::string byte_token_str_repr = ss_hex_repr.str();
793 std::string literal_byte_char_str(1, static_cast<char>(i));
794 bool is_space_char = (static_cast<char>(i) == ' ');
795
796
797 if (is_space_char) {
798 Logger::debug("[BYTE_FALLBACK_DEBUG] Checking for SPACE (byte 32). Looking for '<0x20>' and ' '.");
799 }
800
801
803 if (it != token_to_id_.end()) {
804
805 if (is_space_char) {
806 Logger::debug("[BYTE_FALLBACK_DEBUG] Found '<0x20>' token with ID: " + std::to_string(it->second) + ". Adding to map.");
807 }
808
809 byte_char_to_id_[static_cast<char>(i)] = it->second;
811 } else {
812 // Also check for literal single-byte characters if they are printable
813 if (std::isprint(static_cast<unsigned char>(i))) {
815 if (lit_it != token_to_id_.end()) {
816
817 if (is_space_char) {
818 Logger::debug("[BYTE_FALLBACK_DEBUG] Did not find '<0x20>', but found literal ' ' token with ID: " + std::to_string(lit_it->second));
819 }
820
821
822 // Ensure this token ID hasn't already been mapped (e.g., by a <0xNN> entry)
823 bool id_already_mapped = false;
824 for(const auto& pair : byte_char_to_id_) { if (pair.second == lit_it->second) { id_already_mapped = true; break; } }
825 if (!id_already_mapped) {
826
827 if (is_space_char) {
828 Logger::debug("[BYTE_FALLBACK_DEBUG] ID " + std::to_string(lit_it->second) + " for ' ' not already mapped. Adding to map.");
829 }
830
831 byte_char_to_id_[static_cast<char>(i)] = lit_it->second;
833 // Don't need a continue here, just prevents double-counting if somehow both exist
834 } else {
835
836 if (is_space_char) {
837 Logger::debug("[BYTE_FALLBACK_DEBUG] ID " + std::to_string(lit_it->second) + " for ' ' was already mapped (likely by <0x20>). Skipping literal add.");
838 }
839
840 }
841 } else {
842
843 if (is_space_char) {
844 Logger::debug("[BYTE_FALLBACK_DEBUG] Did not find '<0x20>' OR literal ' ' token in vocab.");
845 }
846
847 }
848 } else {
849
850 if (is_space_char) {
851 Logger::debug("[BYTE_FALLBACK_DEBUG] Did not find '<0x20>' token, and space is not printable, so didn't check for literal ' '.");
852 }
853
854 }
855 }
856 }
857 Logger::info("Fallback byte_char_to_id_ map population: Found representations for " + std::to_string(bytes_found_in_vocab_fallback) +
858 " byte values in GGUF vocab (using <0xNN> or literal). Intended for Tiktoken BPE.");
860 }
861
862
863 } else {
864 Logger::warning("GGUF tokenizer_token_types array missing or size mismatch. Byte token and special token identification will be limited.");
866 byte_char_to_id_.clear();
868 for (int i = 0; i < 256; ++i) {
869 std::stringstream ss_hex_repr;
870 ss_hex_repr << "<0x" << std::hex << std::setw(2) << std::setfill('0') << i << ">";
871 std::string byte_token_str_repr = ss_hex_repr.str();
872 std::string literal_byte_char_str(1, static_cast<char>(i));
873 bool is_space_char = (static_cast<char>(i) == ' ');
874
875
876 if (is_space_char) {
877 Logger::debug("[BYTE_FALLBACK_DEBUG] Checking for SPACE (byte 32). Looking for '<0x20>' and ' '.");
878 }
879
880
882 if (it != token_to_id_.end()) {
883
884 if (is_space_char) {
885 Logger::debug("[BYTE_FALLBACK_DEBUG] Found '<0x20>' token with ID: " + std::to_string(it->second) + ". Adding to map.");
886 }
887
888 byte_char_to_id_[static_cast<char>(i)] = it->second;
890 } else {
891 // Also check for literal single-byte characters if they are printable
892 if (std::isprint(static_cast<unsigned char>(i))) {
894 if (lit_it != token_to_id_.end()) {
895
896 if (is_space_char) {
897 Logger::debug("[BYTE_FALLBACK_DEBUG] Did not find '<0x20>', but found literal ' ' token with ID: " + std::to_string(lit_it->second));
898 }
899
900
901 // Ensure this token ID hasn't already been mapped (e.g., by a <0xNN> entry)
902 bool id_already_mapped = false;
903 for(const auto& pair : byte_char_to_id_) { if (pair.second == lit_it->second) { id_already_mapped = true; break; } }
904 if (!id_already_mapped) {
905
906 if (is_space_char) {
907 Logger::debug("[BYTE_FALLBACK_DEBUG] ID " + std::to_string(lit_it->second) + " for ' ' not already mapped. Adding to map.");
908 }
909
910 byte_char_to_id_[static_cast<char>(i)] = lit_it->second;
912 continue;
913 } else {
914
915 if (is_space_char) {
916 Logger::debug("[BYTE_FALLBACK_DEBUG] ID " + std::to_string(lit_it->second) + " for ' ' was already mapped (likely by <0x20>). Skipping literal add.");
917 }
918
919 }
920 } else {
921
922 if (is_space_char) {
923 Logger::debug("[BYTE_FALLBACK_DEBUG] Did not find '<0x20>' OR literal ' ' token in vocab.");
924 }
925
926 }
927 } else {
928
929 if (is_space_char) {
930 Logger::debug("[BYTE_FALLBACK_DEBUG] Did not find '<0x20>' token, and space is not printable, so didn't check for literal ' '.");
931 }
932
933 }
934 }
935 }
936 Logger::info("Fallback byte_char_to_id_ map population: Found representations for " + std::to_string(bytes_found_in_vocab_fallback) +
937 " byte values in GGUF vocab (using <0xNN> or literal). Intended for Tiktoken BPE.");
938 }
939 }
940
941
942 if (byte_char_to_id_.find(' ') == byte_char_to_id_.end()) {
943 Logger::info("[GENERAL_BYTE_FALLBACK] Space ' ' not found in byte_char_to_id_. Attempting to populate from vocab.");
945 for (int i = 0; i < 256; ++i) {
946 char current_char = static_cast<char>(i);
947 // Only add if not already present from a more primary source (like token_types)
948 if (byte_char_to_id_.count(current_char)) {
949 continue;
950 }
951
952 std::stringstream ss_hex_repr;
953 ss_hex_repr << "<0x" << std::hex << std::setw(2) << std::setfill('0') << i << ">";
954 std::string byte_token_str_repr = ss_hex_repr.str();
955 std::string literal_byte_char_str(1, current_char);
956
958 if (it_hex != token_to_id_.end()) {
961 if (current_char == ' ') Logger::debug("[GENERAL_BYTE_FALLBACK] Found space as '" + byte_token_str_repr + "' -> ID: " + std::to_string(it_hex->second));
962 } else {
964 if (it_lit != token_to_id_.end()) {
967 if (current_char == ' ') Logger::debug("[GENERAL_BYTE_FALLBACK] Found space as literal '" + literal_byte_char_str + "' -> ID: " + std::to_string(it_lit->second));
968 }
969 }
970 }
971 Logger::info("[GENERAL_BYTE_FALLBACK] Added " + std::to_string(general_fallback_bytes_added) +
972 " new entries to byte_char_to_id_ map. Final size: " + std::to_string(byte_char_to_id_.size()));
973 if (byte_char_to_id_.find(' ') == byte_char_to_id_.end()) {
974 Logger::warning("[GENERAL_BYTE_FALLBACK] Space ' ' still not found in byte_char_to_id_ after fallback scan!");
975 }
976
977
978 if (byte_char_to_id_.find(' ') == byte_char_to_id_.end()) { // Check again if space wasn't found by hex/literal
979 const std::string sp_space_token = "\xE2\x96\x81"; // U+2581
981 if (it_sp_space != token_to_id_.end()) {
982 byte_char_to_id_[' '] = it_sp_space->second; // Map standard space char to the ID of the SP space token
983 Logger::info("[GENERAL_BYTE_FALLBACK] SUCCESS: Found SentencePiece space token '" + sp_space_token +
984 "' (ID: " + std::to_string(it_sp_space->second) + "). Mapped standard space ' ' to this ID.");
985 } else {
986 // This is the final warning if space still not found
987 Logger::warning("[GENERAL_BYTE_FALLBACK] Space ' ' still not found in byte_char_to_id_ after fallback scan AND specific SP space check!");
988 }
989 }
990 }
991
992
993bos_token_id_ = config.bos_token_id;
994 eos_token_id_ = config.eos_token_id;
995 unk_token_id_ = config.unk_token_id;
996 pad_token_id_ = config.pad_token_id;
997
998
999 // Ensure UNK token ID is valid (non-negative). Default to 0 if invalid.
1000 if (unk_token_id_ < 0) {
1001 Logger::warning("[Tokenizer GGUF Init] UNK token ID from config was invalid (" + std::to_string(unk_token_id_) + "). Forcing to 0.");
1002 unk_token_id_ = 0;
1003 }
1004
1005
1006 auto setup_special_token = [&](const std::string& name, int& id_field, std::string& str_field, const std::string& default_str_val) {
1007 if (id_field >= 0 && static_cast<size_t>(id_field) < id_to_token_.size()) {
1009 } else {
1010 str_field = default_str_val; // Use default string if ID is invalid or -1
1011 if (id_field != -1) { // Log warning only if ID was supposed to be valid but wasn't found
1012 Logger::warning(name + " token ID " + std::to_string(id_field) +
1013 " from config is out of vocab bounds or invalid. Using default string: '" + default_str_val + "'.");
1014 }
1015 // Attempt to find the default string in the vocab to set its ID, if ID was bad
1016 auto it = token_to_id_.find(default_str_val);
1017 if (it != token_to_id_.end()) {
1018 if (id_field == -1 || (id_field >=0 && static_cast<size_t>(id_field) >= id_to_token_.size()) ) { // If original ID was invalid/none
1019 id_field = it->second;
1020 Logger::info("Set " + name + " token ID to " + std::to_string(id_field) + " based on default string '" + default_str_val + "'.");
1021 }
1022 } else if (id_field != -1) {
1023 Logger::warning("Default string '" + default_str_val + "' for " + name + " token also not found in vocab.");
1024 }
1025 }
1026 };
1027
1031 // For PAD, if config.pad_token_id is -1, it means no pad token. String should be empty.
1032 // If it's a valid ID, str_field will be set. If it's an invalid positive ID, str_field becomes <pad> by default.
1033 if (config.pad_token_id == -1) {
1034 pad_token_ = ""; // Explicitly empty if ID is -1
1035 // bos_token_id_ etc are already set directly from config so no change needed for id_field here for pad_token_id_ == -1
1036 } else {
1038 }
1039
1040 Logger::info("Final Special Tokens (GGUF constructor): BOS ID=" + std::to_string(bos_token_id_) +
1041 " ('" + bos_token_ + "'), EOS ID=" + std::to_string(eos_token_id_) + " ('" + eos_token_ +
1042 "'), UNK ID=" + std::to_string(unk_token_id_) + " ('" + unk_token_ +
1043 "'), PAD ID=" + std::to_string(pad_token_id_) + " ('" + pad_token_ + "\\\\')");
1044
1045 Logger::info(std::string("Tokenizer successfully initialized from GGUFData. Final type: ") +
1046 (type_ == Type::TIKTOKEN_BPE ? "TIKTOKEN_BPE" :
1047 (type_ == Type::SENTENCEPIECE_BPE ? "SENTENCEPIECE_BPE" : "UNKNOWN")));
1048}
std::vector< float > token_scores_
Definition tokenizer.h:209
bool initialized_from_gguf_
Definition tokenizer.h:212
std::unordered_map< char, int > byte_char_to_id_
Definition tokenizer.h:231
std::vector< int32_t > token_types_
Definition tokenizer.h:210
std::unordered_map< std::string, int > bpe_merges_
Definition tokenizer.h:207
std::string gguf_chat_template_
Definition tokenizer.h:234
Type type_
Definition tokenizer.h:233
const char * name
float c
int token_id(const std::vector< std::string > &tokens, const std::string &text)
const std::string BPE_SPACE_CHAR
Definition tokenizer.cpp:26
static std::unordered_map< std::string, int > generate_bpe_merges_from_vocab_scores(const std::vector< std::string > &id_to_token, const std::vector< float > &token_scores)

References added_tokens_, bos_token_, bos_token_id_, bpe_merges_, BPE_SPACE_CHAR, byte_char_to_id_, c, Logger::debug(), eos_token_, eos_token_id_, Logger::error(), generate_bpe_merges_from_vocab_scores(), gguf_chat_template_, id_to_added_token_, id_to_token_, Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, ModelConfig::LLAMA_SENTENCEPIECE, name, pad_token_, pad_token_id_, SENTENCEPIECE_BPE, TIKTOKEN_BPE, token_scores_, token_to_id_, token_types_, tokenizer_family_, type_, unk_token_, unk_token_id_, UNKNOWN, and Logger::warning().

Member Function Documentation

◆ add_bigram_to_queue_refactored()

void Tokenizer::add_bigram_to_queue_refactored ( const char *  text_data_base,
const std::vector< llm_symbol > &  symbols,
llm_symbol::index  first_symbol_idx,
std::priority_queue< std::pair< int, int >, std::vector< std::pair< int, int > >, std::greater< std::pair< int, int > > > &  work_queue 
) const
private

Definition at line 2398 of file tokenizer.cpp.

2403 {
2404 if (first_symbol_idx < 0 || static_cast<size_t>(first_symbol_idx) >= symbols.size()) {
2405 Logger::error(std::string("[ADD_BIGRAM_REFACTORED] Invalid first_symbol_idx: ") + std::to_string(first_symbol_idx));
2406 return;
2407 }
2408
2411
2412 if (s2_idx < 0 || static_cast<size_t>(s2_idx) >= symbols.size() || s2_idx <= first_symbol_idx) {
2413 return;
2414 }
2415 const llm_symbol& s2 = symbols[s2_idx];
2416
2417 if (s1.n == 0 || s2.n == 0) {
2418 return;
2419 }
2420
2421 std::string token_left_str(s1.text, s1.n);
2422 std::string token_right_str(s2.text, s2.n);
2423
2424 std::vector<std::string> merge_attempts;
2425
2426 // First priority: If we see Ä , try it with a following space
2429 Logger::debug("[ADD_BIGRAM] Attempting Ä +space merge: '" + (BPE_SPACE_CHAR + " " + token_right_str) + "'");
2430 }
2431
2432 // Second priority: Standard merge without space
2434 Logger::debug("[ADD_BIGRAM] Attempting standard merge: '" + (token_left_str + token_right_str) + "'");
2435
2436 // Third priority: If left token starts with Ä  but isn't just Ä , try with space
2439 Logger::debug("[ADD_BIGRAM] Attempting Ä word+space merge: '" + (token_left_str + " " + token_right_str) + "'");
2440 }
2441
2442 // Fourth priority: Special case for character splits with space
2443 if (token_left_str.length() == 2 && token_right_str.length() == 1) {
2444 std::string attempt = token_left_str.substr(0, 1) + " " + token_right_str;
2445 merge_attempts.push_back(attempt);
2446 Logger::debug("[ADD_BIGRAM] Attempting char split merge: '" + attempt + "'");
2447 }
2448
2449 int best_rank = std::numeric_limits<int>::max();
2450 bool found_merge = false;
2451 std::string matched_merge;
2452
2453 for (const auto& merge_attempt : merge_attempts) {
2454 auto it = bpe_merges_.find(merge_attempt);
2455 if (it != bpe_merges_.end() && it->second < best_rank) {
2456 best_rank = it->second;
2457 found_merge = true;
2459 }
2460 }
2461
2462 if (found_merge) {
2464 Logger::debug("[ADD_BIGRAM] Found merge: '" + matched_merge + "' with rank " + std::to_string(best_rank));
2465 } else {
2466 Logger::debug("[ADD_BIGRAM] No valid merges found for attempts with left='" + token_left_str +
2467 "' right='" + token_right_str + "'");
2468 }
2469}
index next
Definition tokenizer.h:24

References bpe_merges_, BPE_SPACE_CHAR, Logger::debug(), Logger::error(), j, and llm_symbol::next.

Referenced by bpe_tokenize_to_ids().

◆ apply_chat_template()

std::string Tokenizer::apply_chat_template ( const std::string &  user_prompt,
const std::string &  system_message,
const ModelConfig &  config 
) const

Applies chat template formatting to the input prompt.

Parameters
user_promptThe user's input text
system_messageThe system message to prepend
configModel configuration containing template information
Returns
Formatted chat text

Definition at line 1663 of file tokenizer.cpp.

1665 {
1666 // Check if the GGUF template seems like a Jinja2 template
1667 bool is_jinja_template = (!gguf_chat_template_.empty() &&
1668 (gguf_chat_template_.find("{%") != std::string::npos ||
1669 gguf_chat_template_.find("{{") != std::string::npos));
1670
1671 // Log the determined template type and GGUF template content for debugging
1672 if (!gguf_chat_template_.empty()) {
1673 Logger::debug("[apply_chat_template] GGUF chat template content (first 100 chars): " + gguf_chat_template_.substr(0, 100));
1674 if (is_jinja_template) {
1675 Logger::info("[apply_chat_template] GGUF chat template detected as Jinja2-like.");
1676 } else {
1677 Logger::info("[apply_chat_template] GGUF chat template detected as simple placeholder template.");
1678 }
1679 }
1680
1681 if (!gguf_chat_template_.empty() && !is_jinja_template) {
1682 Logger::info("[apply_chat_template] Using simple GGUF chat template (non-Jinja).");
1684
1685 std::string bos_s = this->bos_token_id_ != -1 ? this->bos_token_ : "";
1686 std::string eos_s = this->eos_token_id_ != -1 ? this->eos_token_ : "";
1687
1688 processed_template = replace_all(processed_template, "{{bos_token}}", bos_s);
1691 if (!system_message.empty()) {
1693 } else {
1694 processed_template = replace_all(processed_template, "{{system_message}}", "");
1695 }
1696
1697 std::string snippet_to_log = processed_template.substr(0, std::min((size_t)100, processed_template.length()));
1698 Logger::debug(std::string("[apply_chat_template] Processed simple GGUF template. Snippet: ") + snippet_to_log);
1699 return processed_template;
1700 } else {
1701 if (is_jinja_template) {
1702 Logger::warning("[apply_chat_template] GGUF chat template appears to be Jinja2, which is not fully supported by this C++ implementation. Falling back to hardcoded Llama 3 Instruct template. The model's intended GGUF chat template will be ignored.");
1703 } else { // Empty GGUF template
1704 Logger::info("[apply_chat_template] GGUF chat template not found or empty. Falling back to hardcoded Llama 3 Instruct template.");
1705 }
1706
1707 // Fallback to a hardcoded Llama 3 Instruct style template
1708 auto find_added_token_str_fallback = [&](const std::string& content,
1709 const std::string& fallback_value) -> std::string {
1710 if (this->added_tokens_.count(content)) return content;
1711 if (this->token_to_id_.count(content)) return content;
1712 if ((!this->added_tokens_.empty() || !this->token_to_id_.empty()) && content.rfind("<",0) == 0 && content.rfind("|",0) != std::string::npos && content.rfind(">",0) == content.length()-1) {
1713 Logger::warning("[apply_chat_template_fallback] Could not find special token string '" + content +
1714 "' in added_tokens_ or vocab. Using default/fallback string: '" + fallback_value + "'");
1715 }
1716 return fallback_value;
1717 };
1718
1719 // Use member versions of bos_token_, etc. which are set up during constructor
1720 std::string bos_s_fallback = this->bos_token_id_ != -1 ? this->bos_token_ : "<s>";
1721 // For Llama3 specific tokens, ensure they are correctly fetched or have sensible defaults
1722 std::string start_header_s_fallback = find_added_token_str_fallback("<|start_header_id|>", "<|start_header_id|>");
1723 std::string end_header_s_fallback = find_added_token_str_fallback("<|end_header_id|>", "<|end_header_id|>");
1724 std::string eot_s_fallback = find_added_token_str_fallback("<|eot_id|>", "<|eot_id|>");
1725 // For role names, they are typically just strings, not special tokens themselves
1726 std::string system_role_name = "system";
1727 std::string user_role_name = "user";
1728 std::string assistant_role_name = "assistant";
1729
1730 std::stringstream ss;
1731 ss << bos_s_fallback;
1732 if (!system_message.empty()) {
1734 }
1737
1738 Logger::info("[apply_chat_template] Applied hardcoded Llama 3 Instruct-like chat template as fallback. Prompt snippet: " + ss.str().substr(0,100));
1739 return ss.str();
1740 }
1741}
static std::string replace_all(std::string str, const std::string &from, const std::string &to)

References added_tokens_, bos_token_, bos_token_id_, Logger::debug(), eos_token_, eos_token_id_, gguf_chat_template_, Logger::info(), j, replace_all(), token_to_id_, and Logger::warning().

◆ bos_token_id()

int Tokenizer::bos_token_id ( ) const
inline

Gets the beginning-of-sequence token ID.

Returns
BOS token ID

Definition at line 163 of file tokenizer.h.

163{ return bos_token_id_; }

References bos_token_id_.

◆ bpe_tokenize()

std::vector< std::string > Tokenizer::bpe_tokenize ( const std::string &  text) const
private

Definition at line 2010 of file tokenizer.cpp.

2010 {
2011 Logger::debug("[Original bpe_tokenize for SentencePiece] Entered. bpe_merges_ size: " + std::to_string(bpe_merges_.size()));
2012 std::vector<std::string> all_final_tokens;
2013 const std::string sp_space_prefix = "\xE2\x96\x81"; // SentencePiece space U+2581
2014
2015 std::vector<std::string> pieces;
2016 std::string current_piece;
2017 bool last_char_was_space = true;
2018
2019 for (char c : text) {
2020 if (std::isspace(static_cast<unsigned char>(c))) {
2021 if (!current_piece.empty()) {
2022 pieces.push_back(current_piece);
2023 current_piece.clear();
2024 }
2025 pieces.push_back(std::string(1, c));
2026 last_char_was_space = true;
2027 } else {
2028 current_piece += c;
2029 last_char_was_space = false;
2030 }
2031 }
2032 if (!current_piece.empty()) {
2033 pieces.push_back(current_piece);
2034 }
2035
2036 Logger::debug("[Original bpe_tokenize for SentencePiece] Split text into " + std::to_string(pieces.size()) + " pieces (words/spaces).");
2037
2038 bool next_word_needs_prefix = true;
2039
2040 for (const std::string& piece : pieces) {
2041 if (piece.empty()) continue;
2042
2043 bool piece_is_whitespace = std::all_of(piece.begin(), piece.end(),
2044 [](char c) { return std::isspace(static_cast<unsigned char>(c)); });
2045
2046 if (piece_is_whitespace) {
2048 Logger::debug("[Original bpe_tokenize for SentencePiece] Piece '" + piece + "' is whitespace. Setting prefix flag.");
2049 continue;
2050 }
2051
2052 std::string word_to_process = piece;
2055 Logger::debug("[Original bpe_tokenize for SentencePiece] Prefixed word: '" + piece + "' -> '" + word_to_process + "'");
2056 next_word_needs_prefix = false;
2057 } else {
2058 Logger::debug("[Original bpe_tokenize for SentencePiece] Processing word without prefix: '" + word_to_process + "'");
2059 }
2060
2061 std::vector<std::string> chars;
2062 for (size_t i = 0; i < word_to_process.size();) {
2064 if (i + bytes <= word_to_process.size()) {
2065 chars.push_back(word_to_process.substr(i, bytes));
2066 } else {
2067 Logger::warning("[Original bpe_tokenize for SentencePiece] Invalid UTF-8 near: '" + word_to_process.substr(i) + "'");
2068 chars.push_back(word_to_process.substr(i, 1));
2069 bytes = 1;
2070 }
2071 i += bytes;
2072 }
2073
2074 if (chars.empty()) {
2075 Logger::warning("[Original bpe_tokenize for SentencePiece] Word '" + word_to_process + "' produced no chars.");
2076 continue;
2077 }
2078
2079 bool changes = true;
2080 while (changes && chars.size() > 1) {
2081 changes = false;
2082 int best_rank = std::numeric_limits<int>::max();
2083 int best_i = -1;
2084
2085 for (size_t i = 0; i < chars.size() - 1; ++i) {
2086 std::string pair = chars[i] + chars[i + 1];
2087 auto it = bpe_merges_.find(pair);
2088 if (it != bpe_merges_.end() && it->second < best_rank) {
2089 best_rank = it->second;
2090 best_i = i;
2091 }
2092 }
2093
2094 if (best_i >= 0) {
2095 std::string merged = chars[best_i] + chars[best_i + 1];
2096 chars[best_i] = merged;
2097 chars.erase(chars.begin() + best_i + 1);
2098 changes = true;
2099 Logger::debug("[Original bpe_tokenize for SentencePiece] Applied merge: '" + merged + "' with rank " +
2100 std::to_string(best_rank));
2101 }
2102 }
2103 all_final_tokens.insert(all_final_tokens.end(), chars.begin(), chars.end());
2104 }
2105
2106 Logger::debug("[Original bpe_tokenize for SentencePiece] Final token count: " + std::to_string(all_final_tokens.size()));
2107 return all_final_tokens;
2108}
std::string text

References bpe_merges_, c, Logger::debug(), j, text, and Logger::warning().

Referenced by encode().

◆ bpe_tokenize_from_scores()

std::vector< std::string > Tokenizer::bpe_tokenize_from_scores ( const std::string &  text) const
private

Definition at line 59 of file tokenizer.cpp.

60 {
61 std::vector<std::string> all_tokens;
62 std::vector<std::string> initial_units; // Pre-tokenized parts (words, symbols, spaces)
63
64 // Llama-like regex for pre-tokenization
65 boost::regex llama_regex(
66 // This pattern is common for SentencePiece-like splitting by words, numbers, symbols, and whitespace.
67 R"([\r\n]+|[[:space:]]+|[^\r\n[:space:][:alnum:]]+|[[:alnum:]]+)");
68 boost::smatch match;
69 std::string text_to_search = text;
70
71 // Pre-tokenize the text using the regex
72 while (boost::regex_search(text_to_search, match, llama_regex)) {
73 if (!match.str(0).empty()) { // Ensure no empty strings are added
74 initial_units.push_back(match.str(0));
75 }
76 text_to_search = match.suffix().str();
77 }
78 if (!text_to_search.empty()) { // Add any trailing part not matched
80 }
81
82 Logger::debug("[BPE_SCORES] Regex pre-tokenization resulted in " + std::to_string(initial_units.size()) + " initial units.");
83
84 const std::string sp_space_prefix = "\xE2\x96\x81"; // SentencePiece space U+2581
85 bool next_word_needs_prefix = true;
86
87 for (const std::string& unit_raw : initial_units) {
88 if (unit_raw.empty()) continue;
89
90 // Check if the unit is purely whitespace
91 bool unit_is_whitespace = true;
92 for (char c : unit_raw) {
93 if (!std::isspace(static_cast<unsigned char>(c))) {
94 unit_is_whitespace = false;
95 break;
96 }
97 }
98
100 // Whitespace signals that the *next* non-whitespace unit needs the prefix.
102 Logger::debug("[BPE_SCORES] Unit '" + unit_raw + "' is whitespace. Setting prefix flag for next word.");
103 continue; // Skip to the next unit
104 }
105
106
107 std::string unit_to_bpe = unit_raw;
110 Logger::debug("[BPE_SCORES] Prefixed unit: '" + unit_raw + "' -> '" + unit_to_bpe + "'");
111 next_word_needs_prefix = false; // Reset flag after applying prefix
112 } else {
113 Logger::debug("[BPE_SCORES] Processing unit without prefix: '" + unit_to_bpe + "'");
114 }
115
116 if (unit_raw == "\n") {
117 Logger::debug("[BPE_SCORES] Raw unit is newline. It will be split into chars. Current unit_to_bpe: '" + unit_to_bpe + "'");
118 // If a newline is a standalone token, it should be found. If it's part of merges, it will be handled.
119 }
120
121 std::vector<std::string> chars; // Characters/sub-units of the current unit_to_bpe
122 // Split unit_to_bpe into UTF-8 characters
123 for (size_t i = 0; i < unit_to_bpe.size();) {
125
126 if (i + bytes <= unit_to_bpe.size()) {
127 chars.push_back(unit_to_bpe.substr(i, bytes));
128 } else {
129 Logger::warning("[BPE_SCORES] Invalid UTF-8 sequence or length error for: '" + unit_to_bpe.substr(i) + "'");
130 chars.push_back(unit_to_bpe.substr(i));
131 break;
132 }
133 i += bytes;
134 }
135
136 if (chars.empty()) {
137 Logger::warning("[BPE_SCORES] Unit '" + unit_to_bpe + "' (original: '" + unit_raw + "') produced no chars for BPE.");
138 continue;
139 }
140
141 // Perform BPE merges based on scores (ranks in bpe_merges_)
142 bool changes = true;
143 while (changes && chars.size() > 1) {
144 changes = false;
145 int best_rank = std::numeric_limits<int>::max(); // For rank-based merges, lower is better
146 int best_i = -1;
147
148 for (size_t i = 0; i < chars.size() - 1; ++i) {
149 std::string pair = chars[i] + chars[i + 1];
150 auto it = bpe_merges_.find(pair);
151 if (it != bpe_merges_.end() && it->second < best_rank) { // Using rank from bpe_merges_
152 best_rank = it->second;
153 best_i = i;
154 }
155 }
156
157 if (best_i >= 0) { // If a merge was found
158 std::string merged = chars[best_i] + chars[best_i + 1];
160 chars.erase(chars.begin() + best_i + 1);
161 changes = true;
162 }
163 }
164
165 all_tokens.insert(all_tokens.end(), chars.begin(), chars.end());
166 }
167
168 Logger::debug("[BPE_SCORES] Final token count after BPE: " + std::to_string(all_tokens.size()));
169 return all_tokens;
170}

References bpe_merges_, c, Logger::debug(), j, text, and Logger::warning().

Referenced by encode().

◆ bpe_tokenize_to_ids()

std::vector< int > Tokenizer::bpe_tokenize_to_ids ( const std::string &  text,
bool  add_bos_token_param,
bool  add_eos_token_param,
bool  ignore_merges_param 
) const
private

Definition at line 2129 of file tokenizer.cpp.

2132 {
2133 Logger::debug(std::string("[bpe_tokenize_to_ids] Starting Tiktoken BPE tokenization for text length: ") + std::to_string(text.length()) +
2134 ", add_bos=" + std::to_string(add_bos_token_param) +
2135 ", add_eos=" + std::to_string(add_eos_token_param) +
2136 ", ignore_merges=" + std::to_string(ignore_merges_param) );
2137
2138 std::vector<int> output_ids;
2139
2140 if (add_bos_token_param) {
2141 if (bos_token_id_ == -1) {
2142 Logger::warning("[bpe_tokenize_to_ids] BOS token requested but bos_token_id_ is -1.");
2143 } else {
2144 output_ids.push_back(bos_token_id_);
2145 Logger::debug(std::string("[bpe_tokenize_to_ids] Added BOS token: ") + std::to_string(bos_token_id_));
2146 }
2147 }
2148
2150
2151 // TikToken regex pattern string
2152 const std::string tiktoken_pattern_str =
2153 R"(<\|[^|]+\||[[:alnum:]]+|\.(?![<|])|[^\s<|]+|\s+)"; // Updated regex
2154
2155 // Compile with boost::xpressive::sregex and icase flag
2156 const boost::xpressive::sregex tiktoken_pattern_ = boost::xpressive::sregex::compile(
2158 boost::xpressive::regex_constants::icase
2159 );
2160
2161 size_t current_idx = 0;
2162 while (current_idx < text.length()) {
2163 bool special_match_found = false;
2164 if (!sorted_special_tokens.empty()) {
2165 for (const auto& special_pair : sorted_special_tokens) {
2166 const std::string& special_text = special_pair.first;
2167 int special_id = special_pair.second;
2168 if (text.compare(current_idx, special_text.length(), special_text) == 0) {
2169 output_ids.push_back(special_id);
2170 Logger::debug("[bpe_tokenize_to_ids] Matched special token: '" + special_text + "' -> ID: " + std::to_string(special_id));
2171 current_idx += special_text.length();
2172 special_match_found = true;
2173 break;
2174 }
2175 }
2176 }
2177
2178 if (special_match_found) {
2179 continue;
2180 }
2181
2182 if (current_idx >= text.length()) break;
2183
2184 std::string remaining_text_view_str = text.substr(current_idx);
2185 boost::xpressive::smatch word_match;
2186
2187 if (!boost::xpressive::regex_search(remaining_text_view_str, word_match, tiktoken_pattern_, boost::xpressive::regex_constants::match_continuous)) {
2188 Logger::debug(std::string("[bpe_tokenize_to_ids] No more regex-matchable words at pos ") + std::to_string(current_idx) + ". Remainder: '" + remaining_text_view_str + "'");
2189 if (!remaining_text_view_str.empty()) {
2190 Logger::warning(std::string("[bpe_tokenize_to_ids] Regex could not process remainder. Processing byte-by-byte: '") + remaining_text_view_str + "'");
2191 for (char c : remaining_text_view_str) {
2192 std::string byte_str(1, c);
2193 auto it = token_to_id_.find(byte_str);
2194 if (it != token_to_id_.end()) {
2195 output_ids.push_back(it->second);
2196 } else {
2197 if (byte_char_to_id_.count(c)) {
2198 output_ids.push_back(byte_char_to_id_.at(c));
2199 } else if (unk_token_id_ != -1) {
2200 output_ids.push_back(unk_token_id_);
2201 Logger::warning(std::string("[bpe_tokenize_to_ids] Unrecognized byte '") + byte_str + std::string("' replaced with UNK."));
2202 } else {
2203 Logger::error(std::string("[bpe_tokenize_to_ids] Unrecognized byte '") + byte_str + std::string("' and no UNK token defined. Skipping."));
2204 }
2205 }
2206 }
2207 }
2208 current_idx = text.length();
2209 break;
2210 }
2211
2212 std::string original_word = word_match.str(0);
2213
2214 if (original_word.empty()){
2215 Logger::warning("[bpe_tokenize_to_ids] Regex search succeeded but matched an empty string. Advancing one char from pos " + std::to_string(current_idx));
2217 if (advance_len == 0) advance_len = 1;
2218
2219 std::string problematic_char_str = text.substr(current_idx, advance_len);
2221 if (it_char != token_to_id_.end()) {
2222 output_ids.push_back(it_char->second);
2223 } else if (advance_len == 1 && byte_char_to_id_.count(problematic_char_str[0])) {
2225 } else if (unk_token_id_ != -1) {
2226 output_ids.push_back(unk_token_id_);
2227 Logger::debug("[bpe_tokenize_to_ids] Added UNK for unmatchable leading char after empty regex match: '" + problematic_char_str + "'");
2228 }
2230 continue;
2231 }
2232
2233 // Check if the entire original_word (matched by regex) is a known token (especially for <|...|> cases)
2235 if (direct_match_it != token_to_id_.end()) {
2236 output_ids.push_back(direct_match_it->second);
2237 Logger::debug("[bpe_tokenize_to_ids] Regex-matched word '" + original_word + "' is a direct token ID: " + std::to_string(direct_match_it->second));
2238 current_idx += original_word.length();
2239 continue;
2240 }
2241
2242 Logger::debug(std::string("[bpe_tokenize_to_ids] Processing regex-derived word for BPE: '") + original_word + "'");
2243
2244 // Convert leading space of original_word to BPE_SPACE_CHAR (Ä ) for Tiktoken-style BPE
2245 // This is crucial if the vocabulary expects space-prefixed tokens like "Ä word".
2246 std::string word_to_process = original_word;
2247 if (!word_to_process.empty() && word_to_process[0] == ' ') {
2248 if (word_to_process.length() > 1) {
2250 } else { // Word is just a single space
2252 }
2253 Logger::debug(std::string("[bpe_tokenize_to_ids] Converted leading space. Word for BPE: '") + word_to_process + "'");
2254 }
2255
2256 if (ignore_merges_param) { // If ignore_merges is true, try direct lookup first
2258 if (it_direct != token_to_id_.end()) {
2259 output_ids.push_back(it_direct->second);
2260 Logger::debug(std::string("[bpe_tokenize_to_ids] Found word directly (ignore_merges): '") + word_to_process + "' -> ID: " + std::to_string(it_direct->second));
2261 current_idx += original_word.length();
2262 continue;
2263 }
2264 Logger::debug(std::string("[bpe_tokenize_to_ids] ignore_merges=true, but word \'") + word_to_process + "\' not in vocab directly. Proceeding with BPE char split (unusual for tiktoken special words).");
2265
2266 }
2267
2268 std::vector<llm_symbol> symbols;
2269 symbols.reserve(word_to_process.length());
2270 size_t offset = 0;
2271 while (offset < word_to_process.length()) {
2272 size_t char_len = unicode_char_len(word_to_process[offset]);
2273 if (offset + char_len > word_to_process.length()) {
2274 Logger::error("[bpe_tokenize_to_ids] Invalid UTF-8 sequence in word: '" + word_to_process + "' at offset " + std::to_string(offset));
2275 symbols.clear();
2276 break;
2277 }
2278 // For Tiktoken, the llm_symbol needs `text_offset` relative to `word_to_process.data()` and `n` (length).
2279 // The `prev` and `next` are for the linked list structure during BPE.
2280 symbols.emplace_back(llm_symbol{-1, -1, word_to_process.data() + offset, char_len});
2281 offset += char_len;
2282 }
2283
2284 if (symbols.empty() && !word_to_process.empty()) {
2285 Logger::warning("[bpe_tokenize_to_ids] Word '" + word_to_process + "' resulted in no symbols. Skipping this word's BPE.");
2286 if (unk_token_id_ != -1 && !original_word.empty()){
2287 output_ids.push_back(unk_token_id_);
2288 }
2289 current_idx += original_word.length();
2290 continue;
2291 }
2292 if (symbols.empty() && word_to_process.empty()){
2293 current_idx += original_word.length();
2294 continue;
2295 }
2296
2297 for (size_t i = 0; i < symbols.size(); ++i) {
2298 symbols[i].prev = (i > 0) ? (i - 1) : -1;
2299 symbols[i].next = (i < symbols.size() - 1) ? (i + 1) : -1;
2300 }
2301
2302 // Use std::priority_queue for merges
2303 std::priority_queue<std::pair<int, int>,
2304 std::vector<std::pair<int, int>>,
2305 std::greater<std::pair<int, int>>> merge_queue;
2306
2307 for (size_t i = 0; i + 1 < symbols.size(); ++i) {
2308 // add_bigram_to_queue expects data pointer, symbols vector, index of first symbol in pair, and queue
2310 }
2311
2312 while (!merge_queue.empty()) {
2313 auto top = merge_queue.top();
2314 merge_queue.pop();
2315
2316 int rank = top.first;
2317 int p1_idx = top.second;
2318
2319 if (symbols[p1_idx].n == 0) continue;
2320 int p2_idx = symbols[p1_idx].next;
2321 if (p2_idx == -1 || symbols[p2_idx].n == 0) continue;
2322
2323
2324 symbols[p1_idx].n += symbols[p2_idx].n;
2325 symbols[p2_idx].n = 0;
2326 symbols[p1_idx].next = symbols[p2_idx].next;
2327 if (symbols[p1_idx].next != -1) {
2328 symbols[symbols[p1_idx].next].prev = p1_idx;
2329 }
2330
2331
2332 // Add new bigrams
2333 if (symbols[p1_idx].prev != -1) {
2335 }
2336 if (symbols[p1_idx].next != -1) {
2338 }
2339 }
2340
2341 std::vector<int> final_word_ids;
2342 if (!symbols.empty()) {
2343 for (int i = 0; i != -1; i = symbols[i].next) {
2344 const llm_symbol & symbol = symbols[i];
2345 if (symbol.n == 0) continue;
2346
2347 std::string s(symbol.text, symbol.n);
2348 std::string lookup_s = s;
2349
2350 const auto token_it = token_to_id_.find(lookup_s);
2351
2352 if (token_it != token_to_id_.end()) {
2353 final_word_ids.push_back(token_it->second);
2354 } else {
2355 Logger::warning(std::string("[bpe_tokenize_to_ids] Symbol not found in vocab: '") + lookup_s + "'. Attempting byte-level tokenization.");
2356 for (char c_char : lookup_s) {
2357 auto byte_map_it = byte_char_to_id_.find(c_char);
2358 if (byte_map_it != byte_char_to_id_.end()){
2359 final_word_ids.push_back(byte_map_it->second);
2360 } else {
2361 if (unk_token_id_ != -1) {
2362 final_word_ids.push_back(unk_token_id_);
2363 } else {
2364 Logger::error(std::string("[bpe_tokenize_to_ids] Unhandled char '") + std::string(1, c_char) + "' and no UNK token ID.");
2365 }
2366 }
2367 }
2368 }
2369 }
2370 } else if (!word_to_process.empty()) {
2371 Logger::warning(std::string("[bpe_tokenize_to_ids] Word '") + word_to_process + std::string("' yielded no final symbols. UNK if available."));
2372 if (unk_token_id_ != -1){ final_word_ids.push_back(unk_token_id_); }
2373 }
2374
2375 if (final_word_ids.empty() && !original_word.empty()) {
2376 Logger::warning(std::string("[bpe_tokenize_to_ids] Word '") + original_word + "' resulted in no tokens. Adding UNK.");
2377 if (unk_token_id_ != -1) { output_ids.push_back(unk_token_id_); }
2378 } else {
2379 output_ids.insert(output_ids.end(), final_word_ids.begin(), final_word_ids.end());
2380 }
2381 current_idx += original_word.length();
2382 }
2383
2384 if (add_eos_token_param) {
2385 if (eos_token_id_ == -1) {
2386 Logger::warning("[bpe_tokenize_to_ids] EOS token requested but eos_token_id_ is -1.");
2387 } else {
2388 output_ids.push_back(eos_token_id_); // Corrected to output_ids
2389 Logger::debug(std::string("[bpe_tokenize_to_ids] Added EOS token: ") + std::to_string(eos_token_id_));
2390 }
2391 }
2392 Logger::debug("[bpe_tokenize_to_ids] Finished Tiktoken BPE tokenization. Total IDs: " + std::to_string(output_ids.size()));
2393 return output_ids;
2394}
void add_bigram_to_queue_refactored(const char *text_data_base, const std::vector< llm_symbol > &symbols, llm_symbol::index first_symbol_idx, std::priority_queue< std::pair< int, int >, std::vector< std::pair< int, int > >, std::greater< std::pair< int, int > > > &work_queue) const
int n
static std::vector< std::pair< std::string, int > > sort_tokens_by_length_desc(const std::unordered_map< std::string, int > &tokens_map)

References add_bigram_to_queue_refactored(), added_tokens_, bos_token_id_, BPE_SPACE_CHAR, byte_char_to_id_, c, Logger::debug(), eos_token_id_, Logger::error(), j, n, sort_tokens_by_length_desc(), text, token_to_id_, unk_token_id_, and Logger::warning().

Referenced by encode().

◆ capitalize_first_letter()

std::string Tokenizer::capitalize_first_letter ( std::string  s) const
private

Definition at line 1980 of file tokenizer.cpp.

1980 { // Added Tokenizer:: scope and const
1981 if (s.empty()) return s;
1982
1983
1984 size_t first_letter_pos = 0;
1985 const std::string sp_space = "\xE2\x96\x81"; // SentencePiece space U+2581
1986
1987 // Check if the string starts with the SentencePiece space
1988 // Using s instead of result
1989 if (s.rfind(sp_space, 0) == 0) {
1990 // If it does, the actual first letter is after the space prefix
1991 if (s.length() > sp_space.length()) {
1992 first_letter_pos = sp_space.length();
1993 } else {
1994 // String is just the space prefix, nothing to capitalize
1995 return s;
1996 }
1997 }
1998
1999 // Capitalize the character at the determined position
2000 // Create result string here to modify
2001 std::string result = s;
2002 if (first_letter_pos < result.length()) {
2004 std::toupper(static_cast<unsigned char>(result[first_letter_pos]));
2005 }
2006
2007 return result;
2008}

References j.

Referenced by tokens_to_ids().

◆ decode()

std::string Tokenizer::decode ( const std::vector< int > &  ids,
bool  skip_special_tokens = true 
) const

Decodes token IDs back to text.

Parameters
idsVector of token IDs to decode
skip_special_tokensWhether to skip special tokens in output
Returns
The decoded text

Definition at line 1412 of file tokenizer.cpp.

1413 {
1414 // Dispatch based on tokenizer family
1416 // transformer_cpp word-level GGUF: ids are whole words; join with
1417 // single spaces, skipping specials (pad/unk/bos/eos) when requested.
1418 std::stringstream wss;
1419 bool first = true;
1420 for (int id : ids) {
1421 if (id < 0 || static_cast<size_t>(id) >= id_to_token_.size()) continue;
1422 if (skip_special_tokens &&
1423 (id == bos_token_id_ || id == eos_token_id_ ||
1424 id == pad_token_id_ || id == unk_token_id_)) continue;
1425 if (!first) wss << " ";
1426 wss << id_to_token_[id];
1427 first = false;
1428 }
1429 return wss.str();
1430 }
1431
1433 // Use the dedicated SentencePiece decoding logic
1435 }
1436
1437 // Default to Llama 3 / Tiktoken BPE decoding logic
1438 Logger::debug("[decode] Decoding using Llama 3 / Tiktoken logic.");
1439 std::stringstream ss;
1440 bool first_token = true;
1441
1442 for (int id : ids) {
1443 // Handle potential invalid IDs first
1444 if (id < 0 || static_cast<size_t>(id) >= id_to_token_.size()) {
1445 if (!skip_special_tokens) { // Only show invalid ID if not skipping specials
1446 ss << "[INVALID_ID:" << id << "]";
1447 Logger::debug("[decode] Invalid token ID: " + std::to_string(id));
1448 first_token = false; // Considered as outputted content
1449 }
1450 continue;
1451 }
1452
1453 // Handle special tokens skip
1454 if (skip_special_tokens) {
1455 if (id == bos_token_id_ || id == eos_token_id_ || id == pad_token_id_ || id == unk_token_id_) {
1456 Logger::debug("[decode] Skipping special token ID: " + std::to_string(id) +
1457 " (BOS/EOS/PAD/UNK)");
1458 continue;
1459 }
1460 if (id_to_added_token_.count(id)) {
1461 Logger::debug("[decode] Skipping added token ID: " + std::to_string(id));
1462 continue;
1463 }
1464 }
1465
1466 std::string token = id_to_token_[id];
1467 std::string token_debug = token;
1468 // Make non-printable characters visible in logs
1469 for (size_t i = 0; i < token_debug.length(); i++) {
1470 if (!std::isprint(static_cast<unsigned char>(token_debug[i]))) {
1471 char hex[5];
1472 snprintf(hex, sizeof(hex), "\\x%02x", static_cast<unsigned char>(token_debug[i]));
1473 token_debug.replace(i, 1, hex);
1474 i += 3; // Skip the added hex chars
1475 }
1476 }
1477 Logger::debug("[decode] Processing token ID " + std::to_string(id) +
1478 ": '" + token_debug + "'");
1479
1480 if (token.empty()) {
1481 if (!skip_special_tokens && unk_token_id_ != -1) {
1482 token = unk_token_;
1483 Logger::debug("[decode] Empty token replaced with UNK token");
1484 } else {
1485 Logger::debug("[decode] Empty token skipped");
1486 continue;
1487 }
1488 }
1489
1490 if (token.size() >= BPE_SPACE_CHAR.size() &&
1491 token.substr(0, BPE_SPACE_CHAR.size()) == BPE_SPACE_CHAR) {
1492 if (!first_token) {
1493 ss << " ";
1494 Logger::debug("[decode] Added space before token with BPE_SPACE_CHAR prefix");
1495 }
1496 ss << token.substr(BPE_SPACE_CHAR.size());
1497 Logger::debug("[decode] Added token content after BPE_SPACE_CHAR: '" +
1498 token.substr(BPE_SPACE_CHAR.size()) + "'");
1499 first_token = false;
1500 } else { // Token does NOT start with Ä 
1501 ss << token; // Append the token itself
1502 Logger::debug("[decode] Added non-BPE_SPACE_CHAR token: '" + token + "'");
1503 first_token = false; // Still set first_token to false as content has been added
1504 }
1505 }
1506 std::string final_text = ss.str();
1507 Logger::debug("[decode] Final decoded text: '" + final_text + "'");
1508 return final_text;
1509}
std::string decode_sentencepiece(const std::vector< int > &ids, bool skip_special_tokens) const

References bos_token_id_, BPE_SPACE_CHAR, Logger::debug(), decode_sentencepiece(), eos_token_id_, id, id_to_added_token_, id_to_token_, j, ModelConfig::LLAMA_SENTENCEPIECE, pad_token_id_, tokenizer_family_, unk_token_, unk_token_id_, and ModelConfig::WORD_LEVEL.

◆ decode_sentencepiece()

std::string Tokenizer::decode_sentencepiece ( const std::vector< int > &  ids,
bool  skip_special_tokens 
) const
private

Definition at line 1511 of file tokenizer.cpp.

1512 {
1513 Logger::debug("[decode_sentencepiece] Decoding using SentencePiece logic.");
1514
1515 std::stringstream ss;
1516 bool first_token = true; // Flag to handle potential leading space correctly
1517 const std::string sp_space_prefix = "\xE2\x96\x81"; // Actual UTF-8 sequence for U+2581
1518 const std::string gpt2_space_prefix = "\xC4\xA0"; // Actual UTF-8 sequence for U+0120 (Ä ) - check just in case
1519
1520 for (int id : ids) {
1521 std::string token_str; // Holds the string representation of the current token
1522 bool is_special_or_invalid = false;
1523
1524 // Handle special token skipping FIRST
1525 if (skip_special_tokens) {
1526 if (id == bos_token_id_ || id == eos_token_id_ || id == pad_token_id_ || id == unk_token_id_) {
1527 is_special_or_invalid = true;
1528 continue; // Skip this token entirely
1529 }
1530 if (id_to_added_token_.count(id)) {
1531 is_special_or_invalid = true;
1532 continue; // Skip added special tokens
1533 }
1534 }
1535
1536 // Get the token string (handling invalid IDs)
1537 if (id >= 0 && static_cast<size_t>(id) < id_to_token_.size()) {
1539 } else {
1540 auto added_it = id_to_added_token_.find(id);
1541 if (added_it != id_to_added_token_.end()) {
1542 token_str = added_it->second; // It's an added token (might be special)
1543 } else { // Truly invalid ID
1544 // Don't output if skipping specials/invalid
1545 if (!skip_special_tokens) {
1546 token_str = "[INVALID_ID:" + std::to_string(id) + "]";
1547 } else {
1548 token_str = ""; // Effectively skip
1549 }
1550 is_special_or_invalid = true; // Treat invalid ID as special for spacing
1551 }
1552 }
1553
1554 // NEW: Check for <0xNN> format and convert if necessary
1555 if (token_str.length() == 6 && token_str.rfind("<0x", 0) == 0 && token_str[5] == '>') {
1556 try {
1557 std::string hex_val_str = token_str.substr(3, 2);
1558 int byte_val = std::stoi(hex_val_str, nullptr, 16);
1559 token_str = std::string(1, static_cast<char>(byte_val));
1560 Logger::debug("[decode_sentencepiece] Converted '<0x" + hex_val_str + ">' to char: " + std::to_string(byte_val));
1561 } catch (const std::exception& e) {
1562 Logger::warning("[decode_sentencepiece] Failed to parse hex from token: '" + token_str + "'. Error: " + e.what());
1563 // Keep original token_str if parsing fails
1564 }
1565 }
1566
1567 if (token_str.empty() && !is_special_or_invalid) {
1568 if (unk_token_id_ != -1) {
1569 // Check if UNK should be skipped
1570 if (!skip_special_tokens || unk_token_id_ != id) { // Check if UNK is the ID causing emptiness if not skipping
1572 } else {
1573 // Skipping specials, and UNK is considered special
1574 is_special_or_invalid = true;
1575 continue; // Skip this empty token
1576 }
1577 } else {
1578 if (!skip_special_tokens){
1579 token_str = "[EMPTY_TOKEN_FOR_ID:" + std::to_string(id) + "]";
1580 } else {
1581 is_special_or_invalid = true;
1582 continue; // Skip
1583 }
1584 }
1585 if (!is_special_or_invalid) { // Only log if we actually output something
1586 Logger::warning("[decode_sentencepiece] Encountered empty token string for valid ID " + std::to_string(id) +
1587 ". Using: '" + token_str + "'");
1588 }
1589 }
1590
1591 // Handle cases where the token IS the space prefix itself
1593 if (first_token) {
1594 // If it's the first token and it's just a space prefix, ignore it and wait for actual content.
1595 // first_token remains true.
1596 Logger::debug("[decode_sentencepiece] Ignored leading standalone space prefix token.");
1597 continue;
1598 }
1599 // If not the first token, and it's a standalone space prefix, ensure one space is added.
1600 std::string current_output_check = ss.str();
1601 if (current_output_check.empty() || current_output_check.back() != ' ') {
1602 ss << " ";
1603 Logger::debug("[decode_sentencepiece] Added space for standalone prefix token mid-sequence.");
1604 }
1605 first_token = false; // A space was effectively output.
1606 continue; // Move to the next token.
1607 }
1608
1609 // Process the token string: handle prefixes and append to result
1610 if (!token_str.empty()) {
1611 bool starts_with_sp_prefix = (token_str.rfind(sp_space_prefix, 0) == 0);
1612 // Check for GPT2 prefix only if SP prefix wasn't found
1614
1616 std::string current_output = ss.str();
1617 if (!first_token && (current_output.empty() || current_output.back() != ' ')) {
1618 ss << " ";
1619 }
1620 std::string content = token_str.substr(sp_space_prefix.length());
1621 // RE-ADD: Trim any leading literal spaces from the content itself
1622 size_t first_non_space = content.find_first_not_of(' ');
1623 if (std::string::npos != first_non_space) {
1624 content = content.substr(first_non_space);
1625 }
1626 ss << content;
1627 first_token = false; // We have outputted something
1628 }
1629 else if (starts_with_gpt2_prefix) { // Handle Ä  prefix if found
1630 std::string current_output = ss.str();
1631 if (!first_token && (current_output.empty() || current_output.back() != ' ')) {
1632 ss << " ";
1633 }
1634 std::string content = token_str.substr(gpt2_space_prefix.length());
1635 // RE-ADD: Trim any leading literal spaces from the content itself
1636 size_t first_non_space = content.find_first_not_of(' ');
1637 if (std::string::npos != first_non_space) {
1638 content = content.substr(first_non_space);
1639 }
1640 ss << content;
1641 first_token = false;
1642 }
1643 else { // Token does not start with a known space prefix
1644 ss << token_str;
1645 first_token = false; // Mark that we've outputted content
1646 }
1647 }
1648 } // End for loop over IDs
1649
1650 return ss.str();
1651}

References bos_token_id_, Logger::debug(), eos_token_id_, id, id_to_added_token_, id_to_token_, j, pad_token_id_, unk_token_, unk_token_id_, and Logger::warning().

Referenced by decode().

◆ detokenize()

std::string Tokenizer::detokenize ( const std::vector< std::string > &  tokens) const

Combines tokens back into text.

Parameters
tokensVector of token strings to combine
Returns
The reconstructed text

Definition at line 1050 of file tokenizer.cpp.

1051 {
1052 std::string result;
1053
1054 bool using_space_prefix = false;
1055 const std::string gpt2_space_prefix = "\xC4\xA0";
1056 const std::string tinyllama_space_prefix = "\xE2\x96\x81";
1057
1058 for (const auto& token : tokens) {
1059 if (!token.empty() &&
1060 ((token.size() >= 2 && token.substr(0, 2) == gpt2_space_prefix) ||
1061 (token.size() >= 3 && token.substr(0, 3) == tinyllama_space_prefix))) {
1062 using_space_prefix = true;
1063 break;
1064 }
1065 }
1066
1067 for (size_t i = 0; i < tokens.size(); ++i) {
1068 std::string token = tokens[i];
1069
1070 if (using_space_prefix) {
1071 if (!token.empty()) {
1072 if (token.size() >= 2 && token.substr(0, 2) == gpt2_space_prefix) {
1073 if (token.size() > 2) {
1074 result += ' ' + token.substr(2);
1075 } else {
1076 result += ' ';
1077 }
1078 }
1079
1080 else if (token.size() >= 3 &&
1081 token.substr(0, 3) == tinyllama_space_prefix) {
1082 if (token.size() > 3) {
1083 result += ' ' + token.substr(3);
1084 } else {
1085 result += ' ';
1086 }
1087 } else {
1088 result += token;
1089 }
1090 }
1091 } else {
1092 if (token.size() >= 4 && token.substr(token.size() - 4) == "</w>") {
1093 result += token.substr(0, token.size() - 4);
1094 result += " ";
1095 continue;
1096 }
1097
1098 if (i > 0) {
1099 result += " ";
1100 }
1101
1102 result += token;
1103 }
1104 }
1105
1106 if (!result.empty() && result[0] == ' ') {
1107 result = result.substr(1);
1108 }
1109
1110 std::string clean_result;
1111 bool prev_space = false;
1112 for (char c : result) {
1113 if (c == ' ') {
1114 if (!prev_space) {
1115 clean_result += c;
1116 }
1117 prev_space = true;
1118 } else {
1119 clean_result += c;
1120 prev_space = false;
1121 }
1122 }
1123
1124 return clean_result;
1125}

References c, and j.

◆ encode()

std::vector< int > Tokenizer::encode ( const std::string &  text,
bool  add_bos = true,
bool  add_eos = false,
PreTokenizeMethod  pre_tok_override = PreTokenizeMethod::DEFAULT 
) const

Encodes text into token IDs with optional special tokens.

Parameters
textText to encode
add_bosWhether to add beginning-of-sequence token
add_eosWhether to add end-of-sequence token
pre_tok_overrideOverride the default pre-tokenization method
Returns
Vector of token IDs

Definition at line 1141 of file tokenizer.cpp.

1143 {
1144 std::vector<int> final_ids; // Initialize the vector to store final token IDs.
1145 std::string family_str_enc = "UNKNOWN"; // String representation for logging.
1146
1147 // Determine the tokenizer family string for logging purposes.
1150
1151 // Log the start of the encoding process with relevant parameters.
1152 std::stringstream log_ss_main;
1153 log_ss_main << "[ENCODE] Encoding text: '" << text << "'"
1154 << " (add_bos=" << add_bos
1155 << ", add_eos=" << add_eos
1156 << ", family=" << family_str_enc
1157 << ", pre_tok_override=" << static_cast<int>(pre_tok_override)
1158 << ")";
1160
1161
1163 // transformer_cpp word-level GGUF: whitespace split -> lowercase ->
1164 // whole-word lookup -> <unk> fallback. BOS/EOS are intentionally NOT
1165 // injected regardless of flags: training streams were raw word sequences
1166 // and low token ids may be ordinary vocabulary words.
1167 Logger::debug("[ENCODE] Using WORD_LEVEL (whole-word lookup) path.");
1168 std::istringstream word_iss(text);
1169 std::string word;
1170 while (word_iss >> word) {
1171 std::transform(word.begin(), word.end(), word.begin(),
1172 [](unsigned char c) { return static_cast<char>(std::tolower(c)); });
1173 auto it = token_to_id_.find(word);
1174 final_ids.push_back(it != token_to_id_.end() ? it->second
1175 : this->unk_token_id_);
1176 }
1177 return final_ids;
1178 }
1179
1181 Logger::debug("[ENCODE] Using LLAMA3_TIKTOKEN (bpe_tokenize_to_ids) path.");
1182
1183 if (add_bos && this->bos_token_id_ != -1) {
1184 // Check if the text already starts with the BOS token string
1185 if (this->bos_token_.empty() || text.rfind(this->bos_token_, 0) != 0) {
1186 final_ids.push_back(this->bos_token_id_);
1187 Logger::debug("[ENCODE Llama 3 Path] Added BOS token: " + std::to_string(this->bos_token_id_) +
1188 " (text did not already start with it).");
1189 } else {
1190 Logger::debug("[ENCODE Llama 3 Path] BOS token flag was true, but text already started with BOS string. Skipping explicit BOS ID addition.");
1191 }
1192 }
1193
1194 std::vector<int> token_ids = this->bpe_tokenize_to_ids(text, false, false, false);
1195 final_ids.insert(final_ids.end(), token_ids.begin(), token_ids.end());
1196
1197 if (add_eos && this->eos_token_id_ != -1) {
1198 final_ids.push_back(this->eos_token_id_);
1199 Logger::debug("[ENCODE Llama 3 Path] Added EOS token: " + std::to_string(this->eos_token_id_));
1200 }
1201
1202
1204 Logger::debug("[ENCODE] Using LLAMA_SENTENCEPIECE (old SentencePiece/BPE logic) path.");
1205
1206 if (!this->initialized_from_gguf_) {
1208 "[ENCODE SPM Path] Using simplified merge-based tokenizer path (calling "
1209 "bpe_tokenize directly).");
1210
1211 std::vector<std::string> bpe_pieces = this->bpe_tokenize(text);
1212 Logger::debug("[ENCODE SPM Path] bpe_tokenize returned " +
1213 std::to_string(bpe_pieces.size()) + " pieces.");
1214
1215 final_ids = this->tokens_to_ids(bpe_pieces);
1216
1217 if (add_bos && this->bos_token_id_ != -1) {
1218 final_ids.insert(final_ids.begin(), this->bos_token_id_);
1219 Logger::debug("[ENCODE SPM Path] Prepended BOS token: " +
1220 std::to_string(this->bos_token_id_));
1221 }
1222 if (add_eos && this->eos_token_id_ != -1) {
1223 final_ids.push_back(this->eos_token_id_);
1224 Logger::debug("[ENCODE SPM Path] Appended EOS token: " +
1225 std::to_string(this->eos_token_id_));
1226 }
1227 Logger::debug("[ENCODE SPM Path] Final IDs (Simplified Merge Path): " +
1228 std::to_string(final_ids.size()) + " tokens.");
1229 } else {
1230 Logger::debug("[ENCODE SPM Path] Using GGUF score-based tokenizer path.");
1231
1232 if (add_bos && this->bos_token_id_ != -1) {
1233 final_ids.push_back(this->bos_token_id_);
1234 Logger::debug("[ENCODE SPM GGUF Path] Added BOS token: " +
1235 std::to_string(this->bos_token_id_));
1236 }
1237
1238 std::vector<std::pair<std::string, bool>> segments;
1239 std::string text_to_process = text;
1241
1243 if (this->pre_tok_type_ == "default") {
1244 method_to_use = PreTokenizeMethod::DEFAULT;
1245 Logger::debug("[ENCODE SPM GGUF Path] Using DEFAULT pre-tokenization (split by special, BPE for non-specials).");
1246 } else if (this->pre_tok_type_ == "llama") {
1247 method_to_use = PreTokenizeMethod::LLAMA_REGEX;
1248 Logger::debug("[ENCODE SPM GGUF Path] Using LLAMA_REGEX pre-tokenization.");
1249 } else {
1250 Logger::warning("[ENCODE SPM GGUF Path] pre_tok_type_ is '" + this->pre_tok_type_ + "' or unset. Defaulting to WHITESPACE pre-tokenization for GGUF/SPM path.");
1251 method_to_use = PreTokenizeMethod::DEFAULT; // Fallback to DEFAULT, whitespace logic handled below
1252 }
1253 } else {
1255 }
1256
1257 std::string method_str_log;
1259 else method_str_log = "DEFAULT (Special Token Split or WHITESPACE Fallback)";
1260 Logger::debug("[ENCODE SPM GGUF Path] Effective pre-tokenization method: " + method_str_log);
1261
1262 if (method_to_use == PreTokenizeMethod::DEFAULT && this->pre_tok_type_ == "default") {
1263 std::unordered_set<std::string> all_special_tokens_set;
1264 for (const auto& pair : this->added_tokens_) {
1265 if (!pair.first.empty()) all_special_tokens_set.insert(pair.first);
1266 }
1267 if (!this->bos_token_.empty()) all_special_tokens_set.insert(this->bos_token_);
1268 if (!this->eos_token_.empty()) all_special_tokens_set.insert(this->eos_token_);
1269 if (!this->unk_token_.empty()) all_special_tokens_set.insert(this->unk_token_);
1270
1271 std::string special_pattern_str = "(";
1272 bool first_special = true;
1273 for (const std::string& st : all_special_tokens_set) {
1275 std::string escaped_st;
1276 for (char c : st) {
1277 if (strchr(".^$*+?()[{\\|", c)) escaped_st += '\\';
1278 escaped_st += c;
1279 }
1281 first_special = false;
1282 }
1283 special_pattern_str += ")";
1284
1285 if (all_special_tokens_set.empty()) {
1286 Logger::debug("[ENCODE SPM GGUF Path] No special tokens defined for DEFAULT pre-tok. Treating whole text as one segment.");
1287 segments.push_back({text_to_process, false});
1288 } else {
1289 Logger::debug("[ENCODE SPM GGUF Path] Splitting by special tokens regex: " + special_pattern_str);
1290 try {
1291 boost::regex special_regex(special_pattern_str);
1292 boost::sregex_iterator it(text_to_process.begin(), text_to_process.end(), special_regex);
1293 boost::sregex_iterator end;
1294 size_t last_pos = 0;
1295 while (it != end) {
1296 boost::smatch match = *it;
1297 if (match.position() > last_pos) {
1298 segments.push_back({text_to_process.substr(last_pos, match.position() - last_pos), false});
1299 }
1300 segments.push_back({match.str(), true});
1301 last_pos = match.position() + match.length();
1302 ++it;
1303 }
1304 if (last_pos < text_to_process.length()) {
1305 segments.push_back({text_to_process.substr(last_pos), false});
1306 }
1307 } catch (const boost::regex_error& e) {
1308 Logger::error("[ENCODE SPM GGUF Path] Regex error splitting by special tokens: " + std::string(e.what()) + ". Treating as single segment.");
1309 segments.clear();
1310 segments.push_back({text_to_process, false});
1311 }
1312 }
1314 boost::regex llama_segment_regex( R"('s|'t|'re|'ve|'m|'ll|'d| ?[[:alpha:]]+| ?[[:digit:]]+| ?[^\\s[:alpha:][:digit:]]+|\\s+(?!\\S)|\\s+)");
1315 Logger::debug("[ENCODE SPM GGUF Path] Using LLAMA_REGEX for pre-tokenization.");
1316 try {
1317 boost::sregex_iterator it(text_to_process.begin(), text_to_process.end(), llama_segment_regex);
1318 boost::sregex_iterator end;
1319 size_t last_pos = 0;
1320 while(it != end) {
1321 boost::smatch match = *it;
1322 if (match.position() > last_pos) {
1323 segments.push_back({text_to_process.substr(last_pos, match.position() - last_pos), false});
1324 }
1325 segments.push_back({match.str(), false});
1326 last_pos = match.position() + match.length();
1327 ++it;
1328 }
1329 if (last_pos < text_to_process.length()) {
1330 segments.push_back({text_to_process.substr(last_pos), false});
1331 }
1332 } catch (const boost::regex_error& e) {
1333 Logger::error("[ENCODE SPM GGUF Path] Regex error during LLAMA_REGEX splitting: " + std::string(e.what()) + ". Treating as single segment.");
1334 segments.clear();
1335 segments.push_back({text_to_process, false});
1336 }
1337 } else { // WHITESPACE or fallback (method_to_use is DEFAULT here if pre_tok_type_ was not "default")
1338 Logger::debug("[ENCODE SPM GGUF Path] Using WHITESPACE pre-tokenization (or fallback).");
1339 std::string current_ws_segment;
1340 for (char c : text_to_process) {
1341 if (std::isspace(static_cast<unsigned char>(c))) {
1342 if (!current_ws_segment.empty()) {
1343 segments.push_back({current_ws_segment, false});
1344 current_ws_segment.clear();
1345 }
1346 segments.push_back({{c}, false});
1347 } else {
1349 }
1350 }
1351 if (!current_ws_segment.empty()) {
1352 segments.push_back({current_ws_segment, false});
1353 }
1354 }
1355
1356 Logger::debug("[ENCODE SPM GGUF Path] Pre-tokenization resulted in " + std::to_string(segments.size()) + " segments.");
1357
1358 std::vector<int> segment_ids;
1359 for (const auto& seg_pair : segments) {
1360 const std::string& segment_str = seg_pair.first;
1361 bool is_special = seg_pair.second;
1362
1363 if (segment_str.empty()) continue;
1364
1365 if (is_special) {
1366 auto it = this->token_to_id_.find(segment_str);
1367 if (it != this->token_to_id_.end()) {
1368 segment_ids.push_back(it->second);
1369 Logger::debug("[ENCODE SPM GGUF Path] Found special segment: '" + segment_str + "' -> ID: " + std::to_string(it->second));
1370 } else {
1371 Logger::warning("[ENCODE SPM GGUF Path] Special segment '" + segment_str +
1372 "' not in vocab. Using UNK ID: " + std::to_string(this->unk_token_id_));
1373 segment_ids.push_back(this->unk_token_id_);
1374 }
1375 } else {
1376 std::vector<std::string> pieces = this->bpe_tokenize_from_scores(segment_str);
1377 std::vector<int> piece_ids = this->tokens_to_ids(pieces);
1378 segment_ids.insert(segment_ids.end(), piece_ids.begin(), piece_ids.end());
1379 Logger::debug("[ENCODE SPM GGUF Path] BPE for non-special segment '" + segment_str + "' -> " + std::to_string(piece_ids.size()) + " IDs.");
1380 }
1381 }
1382 final_ids.insert(final_ids.end(), segment_ids.begin(), segment_ids.end());
1383
1384 if (add_eos && this->eos_token_id_ != -1) {
1385 final_ids.push_back(this->eos_token_id_);
1386 Logger::debug("[ENCODE SPM GGUF Path] Appended EOS token: " +
1387 std::to_string(this->eos_token_id_));
1388 }
1389 Logger::debug("[ENCODE SPM GGUF Path] Final IDs (GGUF Score Path): " + std::to_string(final_ids.size()) + " tokens.");
1390 }
1391 } // This closes the LLAMA_SENTENCEPIECE block
1392 else { // Unknown Tokenizer Family Path
1393 Logger::error("[ENCODE] Unknown or unsupported tokenizer family: " + family_str_enc + ". Cannot encode text.");
1394 if (add_bos && this->bos_token_id_ != -1) {
1395 final_ids.push_back(this->bos_token_id_);
1396 Logger::debug("[ENCODE Unknown Path] Added BOS token: " + std::to_string(this->bos_token_id_));
1397 }
1398 if (add_eos && this->eos_token_id_ != -1) {
1399 final_ids.push_back(this->eos_token_id_);
1400 Logger::debug("[ENCODE Unknown Path] Added EOS token: " + std::to_string(this->eos_token_id_));
1401 }
1402 }
1403
1404 Logger::debug("[ENCODE] Final IDs count (end of function): " + std::to_string(final_ids.size()));
1405 if (final_ids.empty() && !text.empty()) {
1406 Logger::warning("[ENCODE] Tokenization resulted in empty ID list for non-empty text: '" + text + "'");
1407 }
1408
1409 return final_ids;
1410}
PreTokenizeMethod
Enumeration of available pre-tokenization methods.
Definition tokenizer.h:66
std::vector< int > bpe_tokenize_to_ids(const std::string &text, bool add_bos_token_param, bool add_eos_token_param, bool ignore_merges_param) const
std::vector< int > tokens_to_ids(const std::vector< std::string > &tokens) const
std::vector< std::string > bpe_tokenize(const std::string &text) const
std::vector< std::string > bpe_tokenize_from_scores(const std::string &text) const
Definition tokenizer.cpp:59
std::string pre_tok_type_
Definition tokenizer.h:228

References added_tokens_, bos_token_, bos_token_id_, bpe_tokenize(), bpe_tokenize_from_scores(), bpe_tokenize_to_ids(), c, Logger::debug(), DEFAULT, eos_token_, eos_token_id_, Logger::error(), initialized_from_gguf_, j, ModelConfig::LLAMA3_TIKTOKEN, LLAMA_REGEX, ModelConfig::LLAMA_SENTENCEPIECE, pre_tok_type_, text, token_to_id_, tokenizer_family_, tokens_to_ids(), unk_token_, unk_token_id_, Logger::warning(), and ModelConfig::WORD_LEVEL.

Referenced by main().

◆ eos_token_id()

int Tokenizer::eos_token_id ( ) const
inline

Gets the end-of-sequence token ID.

Returns
EOS token ID

Definition at line 169 of file tokenizer.h.

169{ return eos_token_id_; }

References eos_token_id_.

◆ find_bpe_rank()

int Tokenizer::find_bpe_rank ( const std::string &  token_left,
const std::string &  token_right 
) const
private

Definition at line 51 of file tokenizer.cpp.

51 {
52 auto it = bpe_merges_.find(token_left + token_right); // Ensure this uses the correct combined form if prefixes are involved
53 if (it != bpe_merges_.end()) {
54 return it->second; // Return the rank
55 }
56 return -1; // Merge not found
57}

References bpe_merges_, and j.

◆ get_gguf_chat_template()

const std::string & Tokenizer::get_gguf_chat_template ( ) const

Definition at line 2110 of file tokenizer.cpp.

2110 {
2111 return gguf_chat_template_;
2112}

References gguf_chat_template_.

◆ ids_to_tokens()

std::vector< std::string > Tokenizer::ids_to_tokens ( const std::vector< int > &  ids) const

Converts token IDs back to token strings.

Parameters
idsVector of token IDs to convert
Returns
Vector of token strings

Definition at line 258 of file tokenizer.cpp.

259 {
260 std::vector<std::string> tokens;
261 tokens.reserve(ids.size());
262
263 for (int id : ids) {
264 auto added_it = id_to_added_token_.find(id); // Check added tokens first
265 if (added_it != id_to_added_token_.end()) {
266 tokens.push_back(added_it->second);
267 } else if (id >= 0 && static_cast<size_t>(id) < id_to_token_.size()) { // Check base vocabulary
268 if (!id_to_token_[id].empty()) { // Ensure token string is not empty
269 tokens.push_back(id_to_token_[id]);
270 } else {
271 tokens.push_back(unk_token_); // Fallback to UNK string
273 "ID " + std::to_string(id) +
274 " found in base vocab range but has empty string. Using UNK token string: '" + unk_token_ + "'.");
275 }
276 } else { // ID is out of bounds or negative (and not an added token)
277 tokens.push_back(unk_token_); // Fallback to UNK string
278 }
279 }
280
281 return tokens;
282}

References id_to_added_token_, id_to_token_, j, unk_token_, and Logger::warning().

◆ is_added_token()

bool Tokenizer::is_added_token ( int  id) const

Checks if a token ID represents an added token.

Parameters
idToken ID to check
Returns
True if token was added, false otherwise

◆ load_bpe_merges_from_json()

void Tokenizer::load_bpe_merges_from_json ( const std::string &  model_path)
private

Loads BPE merge rules from JSON file.

Definition at line 1895 of file tokenizer.cpp.

1895 {
1896 try {
1897 std::ifstream file(tokenizer_json_path);
1898 if (!file.is_open()) {
1899 throw std::runtime_error("load_bpe_merges_from_json: Failed to open BPE merges file: " + tokenizer_json_path);
1900 }
1901
1903 file >> model_json;
1904
1905 bpe_merges_.clear(); // Ensure merges map is empty before loading
1906
1907 // Check for HuggingFace tokenizer.json structure first
1908 // Merges are typically under model.merges
1909 if (model_json.contains("model") && model_json["model"].is_object()) {
1910 const auto& model_section = model_json["model"];
1911 if (model_section.contains("merges") && model_section["merges"].is_array()) {
1912 Logger::info("load_bpe_merges_from_json: Detected HuggingFace tokenizer.json format with BPE merges from: " + tokenizer_json_path);
1913 const auto& merges = model_section["merges"];
1914 int rank = 0; // Use index as rank for merges from HF JSON
1915 for (const auto& merge_entry_json : merges) {
1916 if (merge_entry_json.is_string()) {
1917 std::string merge_entry = merge_entry_json.get<std::string>();
1918 size_t space_pos = merge_entry.find(' ');
1919
1920 // Expecting format "part1 part2"
1921 if (space_pos != std::string::npos && space_pos > 0 && space_pos < merge_entry.length() - 1) {
1922 std::string first = merge_entry.substr(0, space_pos);
1923 std::string second = merge_entry.substr(space_pos + 1);
1924 // Combine without the space to form the key for the map
1925 std::string pair_key = first + second;
1926 bpe_merges_[pair_key] = rank++;
1927 } else {
1928 Logger::warning("load_bpe_merges_from_json: Skipping malformed merge rule: '" + merge_entry + "' from " + tokenizer_json_path);
1929 }
1930 } else {
1931 Logger::warning("load_bpe_merges_from_json: Merge entry is not a string, skipping. File: " + tokenizer_json_path);
1932 }
1933 }
1934 } else {
1935 // Handle case where tokenizer.json doesn't have expected BPE structure
1936 Logger::warning("load_bpe_merges_from_json: HuggingFace format detected, but no 'model.merges' array found in model section of: " + tokenizer_json_path);
1937 }
1938 }
1939 // Fallback: Check for a simple top-level "merges" array (less common format)
1940 else if (model_json.contains("merges") && model_json["merges"].is_array()) {
1941 Logger::info("load_bpe_merges_from_json: Detected simple top-level 'merges' array format in: " + tokenizer_json_path);
1942 const auto& merges = model_json["merges"];
1943 int rank = 0;
1944 for (const auto& merge_entry_json : merges) {
1945 if (merge_entry_json.is_string()) {
1946 std::string merge_entry = merge_entry_json.get<std::string>();
1947 size_t space_pos = merge_entry.find(' ');
1948 if (space_pos != std::string::npos && space_pos > 0 && space_pos < merge_entry.length() - 1) {
1949 std::string first = merge_entry.substr(0, space_pos);
1950 std::string second = merge_entry.substr(space_pos + 1);
1951 std::string pair_key = first + second;
1952 bpe_merges_[pair_key] = rank++;
1953 } else {
1954 Logger::warning("load_bpe_merges_from_json: Skipping malformed merge rule from top-level array: '" + merge_entry + "' from " + tokenizer_json_path);
1955 }
1956 } else {
1957 Logger::warning("load_bpe_merges_from_json: Merge entry in top-level array is not a string, skipping. File: " + tokenizer_json_path);
1958 }
1959 }
1960 } else {
1961 // If neither format is found
1962 throw std::runtime_error(
1963 "load_bpe_merges_from_json: Unsupported BPE model format: no 'model.merges' or top-level 'merges' array found in '" + tokenizer_json_path + "'");
1964 }
1965
1966 if (bpe_merges_.empty()) {
1967 Logger::warning("load_bpe_merges_from_json: No BPE merges were loaded from the file: " + tokenizer_json_path);
1968 } else {
1969 Logger::info("load_bpe_merges_from_json: Loaded " + std::to_string(bpe_merges_.size()) +
1970 " BPE merges with ranks from " + tokenizer_json_path);
1971 }
1972
1973 } catch (const json::exception& e) {
1974 throw std::runtime_error("Error parsing BPE merges JSON from " + tokenizer_json_path + ": " + e.what());
1975 } catch (const std::exception& e) {
1976 throw std::runtime_error("An unexpected error occurred while loading BPE merges from " + tokenizer_json_path + ": " + std::string(e.what()));
1977 }
1978}
nlohmann::json json
Definition server.cpp:68

References bpe_merges_, Logger::info(), j, and Logger::warning().

Referenced by Tokenizer().

◆ load_sentencepiece_model()

void Tokenizer::load_sentencepiece_model ( const std::string &  model_path)
private

Loads a SentencePiece model.

Definition at line 1890 of file tokenizer.cpp.

1890 {
1891 Logger::warning("load_sentencepiece_model: Loading from SentencePiece model file ('" + model_path + "') is currently not implemented.");
1893}
bool sentencepiece_model_loaded_
Definition tokenizer.h:227

References j, sentencepiece_model_loaded_, and Logger::warning().

Referenced by Tokenizer().

◆ load_vocab_from_json()

void Tokenizer::load_vocab_from_json ( const std::string &  vocab_path,
std::unordered_map< std::string, int > &  token_to_id,
std::vector< std::string > &  id_to_token 
)
private

Loads vocabulary from JSON file.

Definition at line 1743 of file tokenizer.cpp.

1746 {
1747 token_to_id_map.clear();
1748 id_to_token_vec.clear();
1749
1750 try {
1751 std::ifstream file(vocab_path);
1752 if (!file.is_open()) {
1753 throw std::runtime_error("Failed to open vocabulary file: " + vocab_path);
1754 }
1755
1757 file >> vocab_json;
1758
1759 // Try to determine format (HuggingFace tokenizer.json vs. plain vocab)
1760 if (vocab_json.contains("model") && vocab_json["model"].is_object() &&
1761 vocab_json["model"].contains("vocab") && vocab_json["model"]["vocab"].is_object()) {
1762 Logger::info("load_vocab_from_json: Detected HuggingFace tokenizer.json format.");
1763 const auto& vocab = vocab_json["model"]["vocab"];
1764 size_t max_id = 0;
1765
1766 // First pass to determine max_id to size id_to_token_vec appropriately
1767 for (auto it = vocab.begin(); it != vocab.end(); ++it) {
1768 int id = it.value().get<int>();
1769 if (id < 0) {
1770 Logger::warning("load_vocab_from_json: Skipping token with negative ID: " + it.key());
1771 continue;
1772 }
1773 if (static_cast<size_t>(id) > max_id) {
1774 max_id = static_cast<size_t>(id);
1775 }
1776 }
1777 id_to_token_vec.resize(max_id + 1, "<unk>"); // Initialize with unk_token_ or a placeholder
1778
1779 // Second pass to populate maps
1780 for (auto it = vocab.begin(); it != vocab.end(); ++it) {
1781 std::string token = it.key();
1782 int id = it.value().get<int>();
1783 if (id < 0) continue; // Already warned
1784
1786 if (static_cast<size_t>(id) < id_to_token_vec.size()) {
1788 } else {
1789 // This should ideally not happen if resize was correct
1790 Logger::warning("load_vocab_from_json: ID out of bounds during vocab population: " + std::to_string(id));
1791 }
1792 }
1793
1794 // Ensure `added_tokens_` (member) is populated here.
1795 if (vocab_json.contains("added_tokens") &&
1796 vocab_json["added_tokens"].is_array()) {
1797 const auto& added_tokens_json = vocab_json["added_tokens"];
1798 Logger::info("load_vocab_from_json: Processing " + std::to_string(added_tokens_json.size()) + " added_tokens.");
1799 for (const auto& token_obj : added_tokens_json) {
1800 if (token_obj.contains("content") && token_obj.contains("id")) {
1801 std::string token_content = token_obj["content"];
1802 int token_id = token_obj["id"];
1803
1804 if (token_id < 0) {
1805 Logger::warning("load_vocab_from_json: Skipping added_token with negative ID: " + token_content);
1806 continue;
1807 }
1808
1809 // Update maps for added tokens
1810 token_to_id_map[token_content] = token_id; // Also add to the main map for direct lookup
1811 this->added_tokens_[token_content] = token_id; // Populate member variable
1812 this->id_to_added_token_[token_id] = token_content; // Populate member variable
1813
1814 if (static_cast<size_t>(token_id) >= id_to_token_vec.size()) {
1815 id_to_token_vec.resize(token_id + 1, "<unk>"); // Ensure vector is large enough
1816 }
1817 id_to_token_vec[token_id] = token_content; // Ensure id_to_token_vec also has added tokens
1818
1819 if (token_content == this->unk_token_) this->unk_token_id_ = token_id;
1820 else if (token_content == this->bos_token_) this->bos_token_id_ = token_id;
1821 else if (token_content == this->eos_token_) this->eos_token_id_ = token_id;
1822 else if (token_content == this->pad_token_) this->pad_token_id_ = token_id;
1823
1824 Logger::debug("load_vocab_from_json: Processed added_token: '" + token_content + "' with ID " +
1825 std::to_string(token_id));
1826 }
1827 }
1828 }
1829
1830 } else if (vocab_json.is_object()) {
1831 Logger::info("load_vocab_from_json: Detected plain vocabulary format (direct map).");
1832 size_t max_id = 0;
1833 for (auto it = vocab_json.begin(); it != vocab_json.end(); ++it) {
1834 int id = it.value().get<int>();
1835 if (id < 0) continue;
1836 if (static_cast<size_t>(id) > max_id) {
1837 max_id = static_cast<size_t>(id);
1838 }
1839 }
1840 id_to_token_vec.resize(max_id + 1, "<unk>");
1841
1842 for (auto it = vocab_json.begin(); it != vocab_json.end(); ++it) {
1843 std::string token = it.key();
1844 int id = it.value().get<int>();
1845 if (id < 0) {
1846 Logger::warning("load_vocab_from_json: Skipping token with negative ID: " + token);
1847 continue;
1848 }
1850 if (static_cast<size_t>(id) < id_to_token_vec.size()) {
1852 }
1853
1854 if (token == this->unk_token_) this->unk_token_id_ = id;
1855 else if (token == this->bos_token_) this->bos_token_id_ = id;
1856 else if (token == this->eos_token_) this->eos_token_id_ = id;
1857 else if (token == this->pad_token_) this->pad_token_id_ = id;
1858 }
1859 } else {
1860 throw std::runtime_error("load_vocab_from_json: Vocabulary JSON has an unsupported format.");
1861 }
1862
1863 for (size_t i = 0; i < id_to_token_vec.size(); ++i) {
1864 if (id_to_token_vec[i].empty() || id_to_token_vec[i] == "<unk>") {
1865 auto added_it = this->id_to_added_token_.find(static_cast<int>(i));
1866 if (added_it != this->id_to_added_token_.end()) {
1867 id_to_token_vec[i] = added_it->second;
1868 } else if (id_to_token_vec[i].empty()) {
1869 if (id_to_token_vec[i].empty()) id_to_token_vec[i] = "<missing_id_" + std::to_string(i) + ">";
1870 }
1871 }
1872 }
1873
1874 Logger::info("load_vocab_from_json: Loaded vocabulary with " +
1875 std::to_string(token_to_id_map.size()) + " unique token strings and " +
1876 std::to_string(id_to_token_vec.size()) + " ID entries.");
1877 Logger::debug("load_vocab_from_json: Special tokens after JSON load: UNK_ID=" + std::to_string(unk_token_id_) +
1878 " ('" + unk_token_ + "'), BOS_ID=" + std::to_string(bos_token_id_) +
1879 " ('" + bos_token_ + "'), EOS_ID=" + std::to_string(eos_token_id_) +
1880 " ('" + eos_token_ + "'), PAD_ID=" + std::to_string(pad_token_id_) +
1881 " ('" + pad_token_ + "')");
1882
1883 } catch (const json::exception& e) {
1884 throw std::runtime_error("Error parsing vocabulary JSON from " + vocab_path + ": " + e.what());
1885 } catch (const std::exception& e) {
1886 throw std::runtime_error("Error loading vocabulary from " + vocab_path + ": " + std::string(e.what()));
1887 }
1888}

References added_tokens_, bos_token_, bos_token_id_, Logger::debug(), eos_token_, eos_token_id_, id, id_to_added_token_, Logger::info(), j, pad_token_, pad_token_id_, unk_token_, unk_token_id_, and Logger::warning().

Referenced by Tokenizer().

◆ pad_token_id()

int Tokenizer::pad_token_id ( ) const
inline

Gets the padding token ID.

Returns
PAD token ID

Definition at line 175 of file tokenizer.h.

175{ return pad_token_id_; }

References pad_token_id_.

◆ tokenize()

std::vector< std::string > Tokenizer::tokenize ( const std::string &  text) const

Tokenizes input text into token strings.

Parameters
textThe input text to tokenize
Returns
Vector of token strings

◆ tokens_to_ids()

std::vector< int > Tokenizer::tokens_to_ids ( const std::vector< std::string > &  tokens) const
private

Definition at line 171 of file tokenizer.cpp.

172 {
173 std::vector<int> ids;
174 ids.reserve(tokens.size());
175
176 for (const auto& token : tokens) {
177
178 if (token == "\n") {
179 Logger::debug("[TOK_TO_ID_NL_DEBUG] Processing token: '\n' (actual newline char). Length: " + std::to_string(token.length()));
180 bool found_in_added = false;
181 for (const auto& pair : added_tokens_) {
182 if (pair.first == "\n") {
183 Logger::debug("[TOK_TO_ID_NL_DEBUG] Found '\n' key in added_tokens_ map. ID: " + std::to_string(pair.second));
184 found_in_added = true;
185 break;
186 }
187 }
188 if (!found_in_added) {
189 Logger::debug("[TOK_TO_ID_NL_DEBUG] '\n' key NOT found in added_tokens_ map by direct string compare.");
190 // Log all keys in added_tokens_ if newline is not found, to see what IS there
191 std::string keys_in_map = "Keys in added_tokens_: ";
192 for (const auto& pair : added_tokens_) {
193 std::string key_escaped;
194 for (char c_key : pair.first) {
195 if (c_key == '\n') key_escaped += "<NL>";
196 else if (c_key == '\r') key_escaped += "<CR>";
197 else if (c_key == '\t') key_escaped += "<TAB>";
198 else if (std::isprint(static_cast<unsigned char>(c_key))) key_escaped += c_key;
199 else { std::stringstream ss_hex; ss_hex << "<0x" << std::hex << std::setw(2) << std::setfill('0') << static_cast<int>(static_cast<unsigned char>(c_key)) << ">"; key_escaped += ss_hex.str(); }
200 }
201 keys_in_map += "['" + key_escaped + "' (len:" + std::to_string(pair.first.length()) + ")] ";
202 }
204 }
205 }
206
207
208 auto added_it = added_tokens_.find(token);
209 if (added_it != added_tokens_.end()) { // Check added tokens first
210 ids.push_back(added_it->second);
211 Logger::debug("[TOK_TO_ID] Found added token: '" + token +
212 "' -> ID: " + std::to_string(added_it->second));
213 } else { // Not an added token, check base vocabulary
214 auto base_it = token_to_id_.find(token);
215 if (base_it != token_to_id_.end()) {
216 ids.push_back(base_it->second);
217 Logger::debug("[TOK_TO_ID] Found base token: '" + token +
218 "' -> ID: " + std::to_string(base_it->second));
219 } else { // Not in base vocab, try capitalized version
221 if (capitalized_token != token) { // If capitalization changed something
223 if (capitalized_it != token_to_id_.end()) {
224 ids.push_back(capitalized_it->second);
226 "[TOK_TO_ID] FALLBACK: Found capitalized base token: '" +
227 token + "' -> '" + capitalized_token +
228 "' -> ID: " + std::to_string(capitalized_it->second));
229 continue; // Skip further fallbacks for this token
230 }
231 }
232
233 // Fallback for single-byte tokens if not found yet
234 if (token.length() == 1) {
235 char c = token[0];
236 auto byte_it = byte_char_to_id_.find(c);
237 if (byte_it != byte_char_to_id_.end()) {
238 ids.push_back(byte_it->second);
239 Logger::debug("[TOK_TO_ID] FALLBACK: Mapped single-byte token '" +
240 std::string(1, c) + "' to byte token ID " +
241 std::to_string(byte_it->second));
242 continue; // Skip further fallbacks
243 }
244 }
245
246 // If all fallbacks fail, use UNK token
247 Logger::debug("[TOK_TO_ID] UNKNOWN: Token '" + token +
248 "' not found in added, base, capitalized fallback, or "
249 "byte tokens. Using UNK ID: " +
250 std::to_string(unk_token_id_));
251 ids.push_back(unk_token_id_);
252 }
253 }
254 }
255
256 return ids;
257}
std::string capitalize_first_letter(std::string s) const

References added_tokens_, byte_char_to_id_, c, capitalize_first_letter(), Logger::debug(), j, token_to_id_, and unk_token_id_.

Referenced by encode().

◆ unk_token_id()

int Tokenizer::unk_token_id ( ) const
inline

Gets the unknown token ID.

Returns
UNK token ID

Definition at line 181 of file tokenizer.h.

181{ return unk_token_id_; }

References unk_token_id_.

◆ vocab_size()

int Tokenizer::vocab_size ( ) const

Returns the size of the vocabulary.

Returns
Number of tokens in vocabulary

Referenced by Tokenizer().

Member Data Documentation

◆ added_tokens_

std::unordered_map<std::string, int> Tokenizer::added_tokens_
private

◆ bos_token_

std::string Tokenizer::bos_token_
private

Beginning of sequence token string

Definition at line 217 of file tokenizer.h.

Referenced by apply_chat_template(), encode(), load_vocab_from_json(), Tokenizer(), and Tokenizer().

◆ bos_token_id_

int Tokenizer::bos_token_id_ = -1
private

◆ bpe_merges_

std::unordered_map<std::string, int> Tokenizer::bpe_merges_
private

BPE merge rules (rank/order based for SentencePiece/Tiktoken)

Definition at line 207 of file tokenizer.h.

Referenced by add_bigram_to_queue_refactored(), bpe_tokenize(), bpe_tokenize_from_scores(), find_bpe_rank(), load_bpe_merges_from_json(), and Tokenizer().

◆ byte_char_to_id_

std::unordered_map<char, int> Tokenizer::byte_char_to_id_
private

Byte-level character mapping

Definition at line 231 of file tokenizer.h.

Referenced by bpe_tokenize_to_ids(), Tokenizer(), and tokens_to_ids().

◆ chat_template_special_tokens

std::unordered_set<std::string> Tokenizer::chat_template_special_tokens
private

Special tokens for chat

Definition at line 230 of file tokenizer.h.

◆ eos_token_

std::string Tokenizer::eos_token_
private

End of sequence token string

Definition at line 218 of file tokenizer.h.

Referenced by apply_chat_template(), encode(), load_vocab_from_json(), Tokenizer(), and Tokenizer().

◆ eos_token_id_

int Tokenizer::eos_token_id_ = -1
private

◆ gguf_chat_template_

std::string Tokenizer::gguf_chat_template_
private

Chat template string from GGUF metadata

Definition at line 234 of file tokenizer.h.

Referenced by apply_chat_template(), get_gguf_chat_template(), and Tokenizer().

◆ id_to_added_token_

std::unordered_map<int, std::string> Tokenizer::id_to_added_token_
private

Maps IDs to added tokens

Definition at line 229 of file tokenizer.h.

Referenced by decode(), decode_sentencepiece(), ids_to_tokens(), load_vocab_from_json(), Tokenizer(), and Tokenizer().

◆ id_to_token_

std::vector<std::string> Tokenizer::id_to_token_
private

Maps IDs to their tokens

Definition at line 206 of file tokenizer.h.

Referenced by decode(), decode_sentencepiece(), ids_to_tokens(), Tokenizer(), and Tokenizer().

◆ initialized_from_gguf_

bool Tokenizer::initialized_from_gguf_ = false
private

Initialization source flag

Definition at line 212 of file tokenizer.h.

Referenced by encode().

◆ pad_token_

std::string Tokenizer::pad_token_
private

Padding token string

Definition at line 219 of file tokenizer.h.

Referenced by load_vocab_from_json(), Tokenizer(), and Tokenizer().

◆ pad_token_id_

int Tokenizer::pad_token_id_ = -1
private

Padding token ID

Definition at line 225 of file tokenizer.h.

Referenced by decode(), decode_sentencepiece(), load_vocab_from_json(), pad_token_id(), Tokenizer(), and Tokenizer().

◆ pre_tok_type_

std::string Tokenizer::pre_tok_type_ = "unknown"
private

Pre-tokenization type

Definition at line 228 of file tokenizer.h.

Referenced by encode().

◆ sentencepiece_model_loaded_

bool Tokenizer::sentencepiece_model_loaded_ = false
private

SentencePiece model status

Definition at line 227 of file tokenizer.h.

Referenced by load_sentencepiece_model().

◆ tiktoken_merges_list_

std::vector<std::string> Tokenizer::tiktoken_merges_list_
private

Tiktoken BPE merge rules, loaded as ordered list from GGUF

Definition at line 208 of file tokenizer.h.

◆ token_scores_

std::vector<float> Tokenizer::token_scores_
private

Token scores for BPE (primarily for Llama2 GGUF)

Definition at line 209 of file tokenizer.h.

Referenced by Tokenizer().

◆ token_to_id_

std::unordered_map<std::string, int> Tokenizer::token_to_id_
private

Maps tokens to their IDs

Definition at line 205 of file tokenizer.h.

Referenced by apply_chat_template(), bpe_tokenize_to_ids(), encode(), Tokenizer(), Tokenizer(), and tokens_to_ids().

◆ token_types_

std::vector<int32_t> Tokenizer::token_types_
private

Token type information from GGUF

Definition at line 210 of file tokenizer.h.

Referenced by Tokenizer().

◆ tokenizer_family_

Definition at line 211 of file tokenizer.h.

Referenced by decode(), encode(), Tokenizer(), and Tokenizer().

◆ type_

Type Tokenizer::type_ = Type::UNKNOWN
private

Definition at line 233 of file tokenizer.h.

Referenced by Tokenizer().

◆ unk_token_

std::string Tokenizer::unk_token_
private

Unknown token string

Definition at line 216 of file tokenizer.h.

Referenced by decode(), decode_sentencepiece(), encode(), ids_to_tokens(), load_vocab_from_json(), Tokenizer(), and Tokenizer().

◆ unk_token_id_

int Tokenizer::unk_token_id_ = 0
private

The documentation for this class was generated from the following files:
