ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
microtorch::llama3::Tokenizer Class Reference

#include <llama3_tokenizer.h>
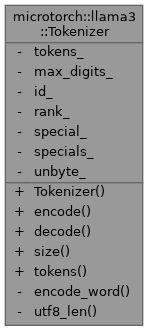
Collaboration diagram for microtorch::llama3::Tokenizer:
Collaboration graph

Classes

struct  Bigram
 
struct  Later
 
struct  Symbol
 

Public Member Functions

 Tokenizer (std::vector< std::string > tokens, const std::vector< std::string > &merges, const std::vector< int32_t > &token_type, size_t max_digits=3)
 
std::vector< int > encode (const std::string &text) const
 
std::string decode (const std::vector< int > &ids) const
 
size_t size () const
 
const std::vector< std::string > & tokens () const
 

Private Member Functions

void encode_word (const std::string &word, std::vector< int > &out) const
 

Static Private Member Functions

static size_t utf8_len (unsigned char c)
 

Private Attributes

std::vector< std::string > tokens_
 
size_t max_digits_ = 3
 
std::unordered_map< std::string, int > id_
 
std::unordered_map< std::string, int > rank_
 
std::vector< bool > special_
 
std::vector< int > specials_
 
std::unordered_map< std::string, unsigned char > unbyte_
 

Detailed Description

Definition at line 262 of file llama3_tokenizer.h.

Constructor & Destructor Documentation

◆ Tokenizer()

microtorch::llama3::Tokenizer::Tokenizer ( std::vector< std::string >  tokens,
const std::vector< std::string > &  merges,
const std::vector< int32_t > &  token_type,
size_t  max_digits = 3 
)
inline

Definition at line 268 of file llama3_tokenizer.h.

270 : tokens_(std::move(tokens)), max_digits_(max_digits) {
271 // A repeated string maps to its last id, as llama.cpp's token_to_id.
272 for (size_t i = 0; i < tokens_.size(); ++i) id_[tokens_[i]] = static_cast<int>(i);
273 for (size_t r = 0; r < merges.size(); ++r) rank_.emplace(merges[r], static_cast<int>(r));
274 special_.assign(tokens_.size(), false);
275 for (size_t i = 0; i < token_type.size() && i < tokens_.size(); ++i) {
276 const int t = token_type[i];
277 if (t == 2 || t == 3 || t == 4) {
278 special_[i] = true;
279 specials_.push_back(static_cast<int>(i));
280 }
281 }
282 // Longest first, as llama.cpp's special-token cache (ties by id).
283 std::stable_sort(specials_.begin(), specials_.end(),
284 [&](int a, int b) { return tokens_[a].size() > tokens_[b].size(); });
285 for (int c = 0; c < 256; ++c) unbyte_.emplace(byte_to_unicode()[c], static_cast<unsigned char>(c));
286 }
std::unordered_map< std::string, unsigned char > unbyte_
std::unordered_map< std::string, int > id_
std::unordered_map< std::string, int > rank_
const std::vector< std::string > & tokens() const
std::vector< std::string > tokens_
float c
std::vector< E > a
size_t j
const std::vector< std::string > & byte_to_unicode()

References a, microtorch::llama3::byte_to_unicode(), c, id_, j, rank_, special_, specials_, tokens_, and unbyte_.

Member Function Documentation

◆ decode()

std::string microtorch::llama3::Tokenizer::decode ( const std::vector< int > &  ids) const
inline

Definition at line 320 of file llama3_tokenizer.h.

320 {
321 std::string s;
322 for (int id : ids) {
323 if (id < 0 || static_cast<size_t>(id) >= tokens_.size()) continue;
324 if (special_[id]) {
325 s += tokens_[id];
326 continue;
327 }
328 const std::string& t = tokens_[id];
329 for (size_t i = 0; i < t.size();) {
330 const size_t len = utf8_len(static_cast<unsigned char>(t[i]));
331 const auto it = unbyte_.find(t.substr(i, len));
332 if (it != unbyte_.end()) s.push_back(static_cast<char>(it->second));
333 i += len;
334 }
335 }
336 return s;
337 }
static size_t utf8_len(unsigned char c)

References id, j, special_, tokens_, unbyte_, and utf8_len().

◆ encode()

std::vector< int > microtorch::llama3::Tokenizer::encode ( const std::string &  text) const
inline

Definition at line 288 of file llama3_tokenizer.h.

288 {
289 std::vector<std::pair<std::string, int>> frags = {{text, -1}};
290 for (int sid : specials_) {
291 const std::string& s = tokens_[sid];
292 if (s.empty()) continue;
293 std::vector<std::pair<std::string, int>> next;
294 for (auto& [t, id] : frags) {
295 if (id >= 0) {
296 next.emplace_back(std::move(t), id);
297 continue;
298 }
299 size_t at = 0;
300 for (size_t m; (m = t.find(s, at)) != std::string::npos; at = m + s.size()) {
301 if (m > at) next.emplace_back(t.substr(at, m - at), -1);
302 next.emplace_back(std::string(), sid);
303 }
304 if (at < t.size()) next.emplace_back(t.substr(at), -1);
305 }
306 frags = std::move(next);
307 }
308 std::vector<int> out;
309 for (const auto& [t, id] : frags) {
310 if (id >= 0) {
311 out.push_back(id);
312 continue;
313 }
314 for (const std::string& w : split_words(t, max_digits_)) encode_word(byte_encode(w), out);
315 }
316 return out;
317 }
void encode_word(const std::string &word, std::vector< int > &out) const
std::string text
node out
std::vector< std::string > split_words(const std::string &text, size_t max_digits=3)
std::string byte_encode(const std::string &word)

References microtorch::llama3::byte_encode(), encode_word(), id, j, max_digits_, out, specials_, microtorch::llama3::split_words(), text, and tokens_.

◆ encode_word()

void microtorch::llama3::Tokenizer::encode_word ( const std::string &  word,
std::vector< int > &  out 
) const
inlineprivate

Definition at line 363 of file llama3_tokenizer.h.

363 {
364 std::vector<Symbol> sym;
365 if (id_.count(word)) { // ignore_merges: a whole-word token wins
366 sym.push_back({-1, -1, 0, word.size()});
367 } else {
368 for (size_t off = 0; off < word.size();) {
369 const size_t len = std::min(word.size() - off, utf8_len(static_cast<unsigned char>(word[off])));
370 const int idx = static_cast<int>(sym.size());
371 sym.push_back({idx - 1, off + len == word.size() ? -1 : idx + 1, off, len});
372 off += len;
373 }
374 }
375 std::priority_queue<Bigram, std::vector<Bigram>, Later> q;
376 const auto text = [&](int i) { return word.substr(sym[i].start, sym[i].n); };
377 const auto push = [&](int l, int r) {
378 if (l < 0 || r < 0) return;
379 const std::string a = text(l), b = text(r);
380 const auto it = rank_.find(a + " " + b);
381 if (it != rank_.end()) q.push({l, r, it->second, a + b});
382 };
383 for (int i = 1; i < static_cast<int>(sym.size()); ++i) push(i - 1, i);
384 while (!q.empty()) {
385 const Bigram bg = q.top();
386 q.pop();
387 Symbol& L = sym[bg.left];
388 Symbol& R = sym[bg.right];
389 if (L.n == 0 || R.n == 0 || text(bg.left) + text(bg.right) != bg.text) continue; // outdated
390 L.n += R.n;
391 R.n = 0;
392 L.next = R.next;
393 if (R.next >= 0) sym[R.next].prev = bg.left;
394 push(L.prev, bg.left);
395 push(bg.left, L.next);
396 }
397 for (const Symbol& s : sym) {
398 if (s.n == 0) continue;
399 const std::string t = word.substr(s.start, s.n);
400 const auto it = id_.find(t);
401 if (it != id_.end()) {
402 out.push_back(it->second);
403 continue;
404 }
405 for (char c : t) { // llama.cpp's fallback: single bytes that are tokens
406 const auto b = id_.find(std::string(1, c));
407 if (b != id_.end()) out.push_back(b->second);
408 }
409 }
410 }
int n

References a, c, id_, j, n, microtorch::llama3::Tokenizer::Symbol::n, off, out, rank_, text, and utf8_len().

Referenced by encode().

◆ size()

size_t microtorch::llama3::Tokenizer::size ( ) const
inline

Definition at line 339 of file llama3_tokenizer.h.

339{ return tokens_.size(); }

References tokens_.

◆ tokens()

const std::vector< std::string > & microtorch::llama3::Tokenizer::tokens ( ) const
inline

Definition at line 340 of file llama3_tokenizer.h.

340{ return tokens_; }

References tokens_.

◆ utf8_len()

static size_t microtorch::llama3::Tokenizer::utf8_len ( unsigned char  c)
inlinestaticprivate

Definition at line 343 of file llama3_tokenizer.h.

343 {
344 static const size_t lookup[] = {1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 2, 2, 3, 4};
345 return lookup[c >> 4];
346 }

References c.

Referenced by decode(), and encode_word().

Member Data Documentation

◆ id_

std::unordered_map<std::string, int> microtorch::llama3::Tokenizer::id_
private

Definition at line 414 of file llama3_tokenizer.h.

Referenced by encode_word(), and Tokenizer().

◆ max_digits_

size_t microtorch::llama3::Tokenizer::max_digits_ = 3
private

Definition at line 413 of file llama3_tokenizer.h.

Referenced by encode().

◆ rank_

std::unordered_map<std::string, int> microtorch::llama3::Tokenizer::rank_
private

Definition at line 414 of file llama3_tokenizer.h.

Referenced by encode_word(), and Tokenizer().

◆ special_

std::vector<bool> microtorch::llama3::Tokenizer::special_
private

Definition at line 415 of file llama3_tokenizer.h.

Referenced by decode(), and Tokenizer().

◆ specials_

std::vector<int> microtorch::llama3::Tokenizer::specials_
private

Definition at line 416 of file llama3_tokenizer.h.

Referenced by encode(), and Tokenizer().

◆ tokens_

std::vector<std::string> microtorch::llama3::Tokenizer::tokens_
private

Definition at line 412 of file llama3_tokenizer.h.

Referenced by decode(), encode(), size(), Tokenizer(), and tokens().

◆ unbyte_

std::unordered_map<std::string, unsigned char> microtorch::llama3::Tokenizer::unbyte_
private

Definition at line 417 of file llama3_tokenizer.h.

Referenced by decode(), and Tokenizer().


The documentation for this class was generated from the following file:
