ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
tinyllama::DistributedCoordinator Class Reference

Distributed coordinator for multi-node LLM inference. More...

#include <distributed_coordinator.h>
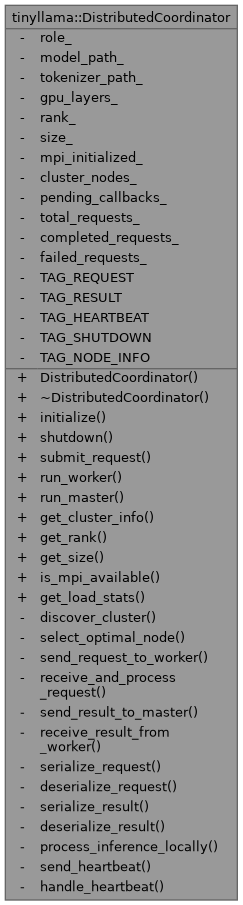
Collaboration diagram for tinyllama::DistributedCoordinator:
Collaboration graph

Classes

struct  InferenceRequest
 
struct  InferenceResult
 
struct  LoadStats
 Get load balancing statistics. More...
 
struct  NodeInfo
 

Public Types

enum class  NodeRole { MASTER , WORKER , HYBRID }
 

Public Member Functions

 DistributedCoordinator (NodeRole role, const std::string &model_path, const std::string &tokenizer_path, int gpu_layers=-1)
 Initialize the distributed coordinator.
 
 ~DistributedCoordinator ()
 
bool initialize ()
 Initialize MPI and discover network topology.
 
void shutdown ()
 Shutdown MPI and cleanup resources.
 
bool submit_request (const InferenceRequest &request, std::function< void(const InferenceResult &)> callback)
 Submit an inference request (master node only)
 
void run_worker ()
 Process requests as a worker node This function blocks and processes incoming requests.
 
void run_master ()
 Run as master node, coordinating requests This function blocks and coordinates the distributed system.
 
std::vector< NodeInfo > get_cluster_info () const
 Get information about all nodes in the cluster.
 
int get_rank () const
 Get the rank of this node.
 
int get_size () const
 Get the total number of nodes.
 
bool is_mpi_available () const
 Check if MPI is available and initialized.
 
LoadStats get_load_stats () const
 

Private Member Functions

void discover_cluster ()
 Discover cluster topology and node capabilities.
 
int select_optimal_node (const InferenceRequest &request)
 Select optimal node for processing request.
 
bool send_request_to_worker (int worker_rank, const InferenceRequest &request)
 Send request to worker node.
 
bool receive_and_process_request ()
 Receive and process request (worker node)
 
bool send_result_to_master (const InferenceResult &result)
 Send result back to master.
 
bool receive_result_from_worker ()
 Receive result from worker (master node)
 
std::vector< char > serialize_request (const InferenceRequest &request)
 Serialize request for MPI transmission.
 
InferenceRequest deserialize_request (const std::vector< char > &data)
 Deserialize request from MPI transmission.
 
std::vector< char > serialize_result (const InferenceResult &result)
 Serialize result for MPI transmission.
 
InferenceResult deserialize_result (const std::vector< char > &data)
 Deserialize result from MPI transmission.
 
InferenceResult process_inference_locally (const InferenceRequest &request)
 Process inference request locally.
 
void send_heartbeat ()
 Send heartbeat to all nodes.
 
void handle_heartbeat (int source_rank)
 Handle heartbeat from other nodes.
 

Private Attributes

NodeRole role_
 
std::string model_path_
 
std::string tokenizer_path_
 
int gpu_layers_
 
int rank_ = -1
 
int size_ = -1
 
bool mpi_initialized_ = false
 
std::vector< NodeInfo > cluster_nodes_
 
std::map< std::string, std::function< void(const InferenceResult &)> > pending_callbacks_
 
std::atomic< int > total_requests_ {0}
 
std::atomic< int > completed_requests_ {0}
 
std::atomic< int > failed_requests_ {0}
 

Static Private Attributes

static constexpr int TAG_REQUEST = 1
 
static constexpr int TAG_RESULT = 2
 
static constexpr int TAG_HEARTBEAT = 3
 
static constexpr int TAG_SHUTDOWN = 4
 
static constexpr int TAG_NODE_INFO = 5
 

Detailed Description

Distributed coordinator for multi-node LLM inference.

This class manages distributed inference across multiple nodes using MPI. It handles model sharding, request routing, and result aggregation.

Definition at line 22 of file distributed_coordinator.h.

Member Enumeration Documentation

◆ NodeRole

Enumerator
MASTER 
WORKER 
HYBRID 

Definition at line 24 of file distributed_coordinator.h.

24 {
25 MASTER, // Coordinates requests and aggregates results
26 WORKER, // Processes inference requests
27 HYBRID // Can act as both master and worker
28 };

Constructor & Destructor Documentation

◆ DistributedCoordinator()

tinyllama::DistributedCoordinator::DistributedCoordinator ( NodeRole  role,
const std::string &  model_path,
const std::string &  tokenizer_path,
int  gpu_layers = -1 
)

Initialize the distributed coordinator.

Parameters
roleThe role of this node
model_pathPath to the model file
tokenizer_pathPath to the tokenizer file
gpu_layersNumber of GPU layers for this node

Definition at line 16 of file distributed_coordinator.cpp.

◆ ~DistributedCoordinator()

tinyllama::DistributedCoordinator::~DistributedCoordinator ( )

Definition at line 26 of file distributed_coordinator.cpp.

26 {
27 shutdown();
28}
void shutdown()
Shutdown MPI and cleanup resources.

References shutdown().

Member Function Documentation

◆ deserialize_request()

DistributedCoordinator::InferenceRequest tinyllama::DistributedCoordinator::deserialize_request ( const std::vector< char > &  data)
private

Deserialize request from MPI transmission.

Definition at line 466 of file distributed_coordinator.cpp.

466 {
467 std::string str(data.begin(), data.end());
468 std::istringstream iss(str);
469
470 InferenceRequest request;
471 std::string temp;
472
473 if (std::getline(iss, request.request_id, '|') &&
474 std::getline(iss, request.prompt, '|') &&
475 std::getline(iss, temp, '|')) {
476 request.max_tokens = std::stoi(temp);
477 }
478 if (std::getline(iss, temp, '|')) {
479 request.temperature = std::stof(temp);
480 }
481 if (std::getline(iss, temp, '|')) {
482 request.top_k = std::stoi(temp);
483 }
484 if (std::getline(iss, temp, '|')) {
485 request.top_p = std::stof(temp);
486 }
487 if (std::getline(iss, request.system_prompt, '|') &&
488 std::getline(iss, temp)) {
489 request.target_node = std::stoi(temp);
490 }
491
492 return request;
493}
std::string str
Definition ir_digest.cpp:66

References j, tinyllama::DistributedCoordinator::InferenceRequest::max_tokens, and str.

Referenced by receive_and_process_request().

◆ deserialize_result()

DistributedCoordinator::InferenceResult tinyllama::DistributedCoordinator::deserialize_result ( const std::vector< char > &  data)
private

Deserialize result from MPI transmission.

Definition at line 509 of file distributed_coordinator.cpp.

509 {
510 std::string str(data.begin(), data.end());
511 std::istringstream iss(str);
512
513 InferenceResult result;
514 std::string temp;
515
516 if (std::getline(iss, result.request_id, '|') &&
517 std::getline(iss, result.generated_text, '|') &&
518 std::getline(iss, temp, '|')) {
519 result.tokens_generated = std::stoi(temp);
520 }
521 if (std::getline(iss, temp, '|')) {
522 result.inference_time_ms = std::stof(temp);
523 }
524 if (std::getline(iss, temp, '|')) {
525 result.processing_node = std::stoi(temp);
526 }
527 if (std::getline(iss, temp, '|')) {
528 result.success = (std::stoi(temp) == 1);
529 }
530 if (std::getline(iss, result.error_message)) {
531 // Got error message
532 }
533
534 return result;
535}

References j, str, and tinyllama::DistributedCoordinator::InferenceResult::tokens_generated.

Referenced by receive_result_from_worker().

◆ discover_cluster()

void tinyllama::DistributedCoordinator::discover_cluster ( )
private

Discover cluster topology and node capabilities.

Definition at line 87 of file distributed_coordinator.cpp.

87 {
88#ifdef HAS_MPI
89 if (!mpi_initialized_) return;
90
91 cluster_nodes_.clear();
92 cluster_nodes_.resize(size_);
93
94 // Get hostname
95 char hostname[MPI_MAX_PROCESSOR_NAME];
96 int name_len;
98
99 // Create node info for this node
100 NodeInfo local_info;
101 local_info.rank = rank_;
102 local_info.hostname = std::string(hostname, name_len);
103 local_info.role = role_;
104 local_info.has_gpu = true; // Assume GPU available - could be detected
105 local_info.gpu_memory_mb = 8192; // Default - could be detected
106 local_info.gpu_layers = gpu_layers_;
107
108 // Serialize local node info
109 std::string serialized_info = local_info.hostname + "|" +
110 std::to_string(static_cast<int>(local_info.role)) + "|" +
111 std::to_string(local_info.has_gpu ? 1 : 0) + "|" +
112 std::to_string(local_info.gpu_memory_mb) + "|" +
113 std::to_string(local_info.gpu_layers);
114
115 // Gather all node info at rank 0
116 std::vector<char> send_buffer(serialized_info.begin(), serialized_info.end());
117 send_buffer.resize(256, '\0'); // Fixed size buffer
118
119 std::vector<char> recv_buffer;
120 if (rank_ == 0) {
121 recv_buffer.resize(256 * size_);
122 }
123
124 MPI_Gather(send_buffer.data(), 256, MPI_CHAR,
125 recv_buffer.data(), 256, MPI_CHAR, 0, MPI_COMM_WORLD);
126
127 // Parse and distribute node info
128 if (rank_ == 0) {
129 for (int i = 0; i < size_; ++i) {
130 std::string node_data(recv_buffer.data() + i * 256);
131 // Remove null terminators
132 node_data = node_data.substr(0, node_data.find('\0'));
133
134 std::istringstream ss(node_data);
135 std::string hostname, role_str, has_gpu_str, memory_str, layers_str;
136
137 if (std::getline(ss, hostname, '|') &&
138 std::getline(ss, role_str, '|') &&
139 std::getline(ss, has_gpu_str, '|') &&
140 std::getline(ss, memory_str, '|') &&
141 std::getline(ss, layers_str)) {
142
143 cluster_nodes_[i].rank = i;
144 cluster_nodes_[i].hostname = hostname;
145 cluster_nodes_[i].role = static_cast<NodeRole>(std::stoi(role_str));
146 cluster_nodes_[i].has_gpu = (std::stoi(has_gpu_str) == 1);
147 cluster_nodes_[i].gpu_memory_mb = std::stoul(memory_str);
148 cluster_nodes_[i].gpu_layers = std::stoi(layers_str);
149 }
150 }
151 }
152
153 // Broadcast cluster info to all nodes
154 if (rank_ == 0) {
155 for (int i = 1; i < size_; ++i) {
157 }
158 } else {
159 recv_buffer.resize(256 * size_);
162
163 // Parse received cluster info
164 for (int i = 0; i < size_; ++i) {
165 std::string node_data(recv_buffer.data() + i * 256);
166 node_data = node_data.substr(0, node_data.find('\0'));
167
168 std::istringstream ss(node_data);
169 std::string hostname, role_str, has_gpu_str, memory_str, layers_str;
170
171 if (std::getline(ss, hostname, '|') &&
172 std::getline(ss, role_str, '|') &&
173 std::getline(ss, has_gpu_str, '|') &&
174 std::getline(ss, memory_str, '|') &&
175 std::getline(ss, layers_str)) {
176
177 cluster_nodes_[i].rank = i;
178 cluster_nodes_[i].hostname = hostname;
179 cluster_nodes_[i].role = static_cast<NodeRole>(std::stoi(role_str));
180 cluster_nodes_[i].has_gpu = (std::stoi(has_gpu_str) == 1);
181 cluster_nodes_[i].gpu_memory_mb = std::stoul(memory_str);
182 cluster_nodes_[i].gpu_layers = std::stoi(layers_str);
183 }
184 }
185 }
186
187 Logger::log("Discovered " + std::to_string(cluster_nodes_.size()) + " nodes in cluster", Logger::INFO);
188 for (const auto& node : cluster_nodes_) {
189 Logger::log("Node " + std::to_string(node.rank) + ": " + node.hostname +
190 " (GPU: " + (node.has_gpu ? "yes" : "no") +
191 ", Layers: " + std::to_string(node.gpu_layers) + ")", Logger::INFO);
192 }
193#endif
194}
Static logging class for application-wide logging.
Definition logger.h:52

References cluster_nodes_, gpu_layers_, Logger::INFO, j, mpi_initialized_, tinyllama::DistributedCoordinator::NodeInfo::rank, rank_, role_, size_, and TAG_NODE_INFO.

Referenced by initialize().

◆ get_cluster_info()

std::vector< DistributedCoordinator::NodeInfo > tinyllama::DistributedCoordinator::get_cluster_info ( ) const

Get information about all nodes in the cluster.

Definition at line 586 of file distributed_coordinator.cpp.

586 {
587 return cluster_nodes_;
588}

References cluster_nodes_.

◆ get_load_stats()

DistributedCoordinator::LoadStats tinyllama::DistributedCoordinator::get_load_stats ( ) const

Definition at line 590 of file distributed_coordinator.cpp.

590 {
591 LoadStats stats;
592 stats.total_requests = total_requests_.load();
593 stats.completed_requests = completed_requests_.load();
594 stats.failed_requests = failed_requests_.load();
595
596 if (stats.completed_requests > 0) {
597 stats.average_response_time_ms = 0.0f; // Would need to track this
598 }
599
600 for (const auto& node : cluster_nodes_) {
601 stats.requests_per_node[node.rank] = node.active_requests.load();
602 }
603
604 return stats;
605}

References cluster_nodes_, completed_requests_, failed_requests_, j, tinyllama::DistributedCoordinator::LoadStats::total_requests, and total_requests_.

◆ get_rank()

int tinyllama::DistributedCoordinator::get_rank ( ) const
inline

Get the rank of this node.

Definition at line 116 of file distributed_coordinator.h.

116{ return rank_; }

References rank_.

◆ get_size()

int tinyllama::DistributedCoordinator::get_size ( ) const
inline

Get the total number of nodes.

Definition at line 121 of file distributed_coordinator.h.

121{ return size_; }

References size_.

◆ handle_heartbeat()

void tinyllama::DistributedCoordinator::handle_heartbeat ( int  source_rank)
private

Handle heartbeat from other nodes.

Definition at line 579 of file distributed_coordinator.cpp.

579 {
580 // Update last seen time for the node
581 if (source_rank >= 0 && source_rank < static_cast<int>(cluster_nodes_.size())) {
582 // Could update a last_seen timestamp here
583 }
584}

References cluster_nodes_, and j.

◆ initialize()

bool tinyllama::DistributedCoordinator::initialize ( )

Initialize MPI and discover network topology.

Returns
true if initialization successful

Definition at line 30 of file distributed_coordinator.cpp.

30 {
31#ifdef HAS_MPI
32 int provided;
33 int result = MPI_Init_thread(nullptr, nullptr, MPI_THREAD_MULTIPLE, &provided);
34 if (result != MPI_SUCCESS) {
35 Logger::log("Failed to initialize MPI", Logger::ERROR);
36 return false;
37 }
38
40 Logger::log("MPI does not support multithreading", Logger::WARNING);
41 }
42
45
46 mpi_initialized_ = true;
47
48 Logger::log("MPI initialized - Rank: " + std::to_string(rank_) +
49 ", Size: " + std::to_string(size_), Logger::INFO);
50
51 // Discover cluster topology
53
54 return true;
55#else
56 Logger::log("MPI support not compiled in", Logger::ERROR);
57 return false;
58#endif
59}
void discover_cluster()
Discover cluster topology and node capabilities.

References discover_cluster(), Logger::ERROR, Logger::INFO, j, mpi_initialized_, rank_, size_, and Logger::WARNING.

◆ is_mpi_available()

bool tinyllama::DistributedCoordinator::is_mpi_available ( ) const

Check if MPI is available and initialized.

Definition at line 79 of file distributed_coordinator.cpp.

79 {
80#ifdef HAS_MPI
81 return mpi_initialized_;
82#else
83 return false;
84#endif
85}

References mpi_initialized_.

◆ process_inference_locally()

DistributedCoordinator::InferenceResult tinyllama::DistributedCoordinator::process_inference_locally ( const InferenceRequest &  request)
private

Process inference request locally.

Definition at line 537 of file distributed_coordinator.cpp.

537 {
538 InferenceResult result;
539 result.request_id = request.request_id;
540 result.processing_node = rank_;
541
542 auto start_time = std::chrono::high_resolution_clock::now();
543
544 try {
545 // Use the existing TinyLlama API for local inference
546 // This is a simplified version - you would integrate with your actual API
547
548 // For now, create a mock result
549 result.generated_text = "Generated response for: " + request.prompt;
550 result.tokens_generated = request.max_tokens;
551 result.success = true;
552
553 // TODO: Replace with actual inference call
554 // std::string response = tinyllama_generate(request.prompt, request.max_tokens,
555 // request.temperature, request.top_k, request.top_p);
556 // result.generated_text = response;
557
558 } catch (const std::exception& e) {
559 result.success = false;
560 result.error_message = e.what();
561 }
562
563 auto end_time = std::chrono::high_resolution_clock::now();
564 auto duration = std::chrono::duration_cast<std::chrono::milliseconds>(end_time - start_time);
565 result.inference_time_ms = static_cast<float>(duration.count());
566
567 return result;
568}

References j, rank_, and tinyllama::DistributedCoordinator::InferenceResult::request_id.

Referenced by receive_and_process_request(), and submit_request().

◆ receive_and_process_request()

bool tinyllama::DistributedCoordinator::receive_and_process_request ( )
private

Receive and process request (worker node)

Definition at line 346 of file distributed_coordinator.cpp.

346 {
347#ifdef HAS_MPI
348 int flag;
350
351 // Check if there's a request available
353 if (!flag) {
354 return false;
355 }
356
357 // Receive size first
358 int size;
360
361 // Receive data
362 std::vector<char> buffer(size);
364
365 // Deserialize request
366 InferenceRequest request = deserialize_request(buffer);
367
368 // Update active request count
369 if (rank_ < static_cast<int>(cluster_nodes_.size())) {
370 cluster_nodes_[rank_].active_requests++;
371 }
372
373 // Process request locally
374 InferenceResult result = process_inference_locally(request);
375 result.processing_node = rank_;
376
377 // Send result back to master
379
380 // Update active request count
381 if (rank_ < static_cast<int>(cluster_nodes_.size())) {
382 cluster_nodes_[rank_].active_requests--;
383 }
384
385 return true;
386#else
387 return false;
388#endif
389}
InferenceResult process_inference_locally(const InferenceRequest &request)
Process inference request locally.
bool send_result_to_master(const InferenceResult &result)
Send result back to master.
InferenceRequest deserialize_request(const std::vector< char > &data)
Deserialize request from MPI transmission.

References cluster_nodes_, deserialize_request(), j, process_inference_locally(), rank_, send_result_to_master(), and TAG_REQUEST.

Referenced by run_worker().

◆ receive_result_from_worker()

bool tinyllama::DistributedCoordinator::receive_result_from_worker ( )
private

Receive result from worker (master node)

Definition at line 391 of file distributed_coordinator.cpp.

391 {
392#ifdef HAS_MPI
393 int flag;
395
396 // Check if there's a result available from any worker
398 if (!flag) {
399 return false;
400 }
401
402 // Receive size first
403 int size;
404 MPI_Recv(&size, 1, MPI_INT, status.MPI_SOURCE, TAG_RESULT, MPI_COMM_WORLD, &status);
405
406 // Receive data
407 std::vector<char> buffer(size);
408 MPI_Recv(buffer.data(), size, MPI_CHAR, status.MPI_SOURCE, TAG_RESULT, MPI_COMM_WORLD, &status);
409
410 // Deserialize result
411 InferenceResult result = deserialize_result(buffer);
412
413 // Find and call the callback
414 auto callback_it = pending_callbacks_.find(result.request_id);
415 if (callback_it != pending_callbacks_.end()) {
416 callback_it->second(result);
418
419 if (result.success) {
421 } else {
423 }
424 }
425
426 return true;
427#else
428 return false;
429#endif
430}
std::map< std::string, std::function< void(const InferenceResult &)> > pending_callbacks_
InferenceResult deserialize_result(const std::vector< char > &data)
Deserialize result from MPI transmission.

References completed_requests_, deserialize_result(), failed_requests_, j, pending_callbacks_, and TAG_RESULT.

Referenced by run_master().

◆ run_master()

void tinyllama::DistributedCoordinator::run_master ( )

Run as master node, coordinating requests This function blocks and coordinates the distributed system.

Definition at line 317 of file distributed_coordinator.cpp.

317 {
318#ifdef HAS_MPI
319 if (!mpi_initialized_ || rank_ != 0) {
320 Logger::log("Only rank 0 can run as master", Logger::ERROR);
321 return;
322 }
323
324 Logger::log("Starting master node", Logger::INFO);
325
326 while (true) {
327 // Receive results from workers
329 // Result processed successfully
330 } else {
331 // No result available, sleep briefly
332 std::this_thread::sleep_for(std::chrono::milliseconds(10));
333 }
334
335 // Send periodic heartbeats
336 static auto last_heartbeat = std::chrono::steady_clock::now();
337 auto now = std::chrono::steady_clock::now();
338 if (now - last_heartbeat > std::chrono::seconds(5)) {
341 }
342 }
343#endif
344}
bool receive_result_from_worker()
Receive result from worker (master node)
void send_heartbeat()
Send heartbeat to all nodes.

References Logger::ERROR, Logger::INFO, j, mpi_initialized_, rank_, receive_result_from_worker(), and send_heartbeat().

◆ run_worker()

void tinyllama::DistributedCoordinator::run_worker ( )

Process requests as a worker node This function blocks and processes incoming requests.

Definition at line 283 of file distributed_coordinator.cpp.

283 {
284#ifdef HAS_MPI
285 if (!mpi_initialized_) {
286 Logger::log("MPI not initialized", Logger::ERROR);
287 return;
288 }
289
290 Logger::log("Starting worker node (rank " + std::to_string(rank_) + ")", Logger::INFO);
291
292 while (true) {
293 // Check for shutdown signal
294 int flag;
297 if (flag) {
298 int shutdown_signal;
300 Logger::log("Received shutdown signal", Logger::INFO);
301 break;
302 }
303
304 // Check for incoming requests
306 // Request processed successfully
307 } else {
308 // No request available, sleep briefly
309 std::this_thread::sleep_for(std::chrono::milliseconds(10));
310 }
311 }
312
313 Logger::log("Worker node shutting down", Logger::INFO);
314#endif
315}
bool receive_and_process_request()
Receive and process request (worker node)

References Logger::ERROR, Logger::INFO, j, mpi_initialized_, rank_, receive_and_process_request(), and TAG_SHUTDOWN.

◆ select_optimal_node()

int tinyllama::DistributedCoordinator::select_optimal_node ( const InferenceRequest &  request)
private

Select optimal node for processing request.

Definition at line 241 of file distributed_coordinator.cpp.

241 {
242 if (request.target_node != -1 && request.target_node < size_) {
243 return request.target_node;
244 }
245
246 // Simple load balancing - select node with least active requests
247 int best_node = -1;
248 int min_load = INT_MAX;
249
250 for (const auto& node : cluster_nodes_) {
251 if (node.rank == 0) continue; // Skip master node
252 if (node.role == NodeRole::WORKER || node.role == NodeRole::HYBRID) {
253 int current_load = node.active_requests.load();
254 if (current_load < min_load) {
256 best_node = node.rank;
257 }
258 }
259 }
260
261 return best_node;
262}

References cluster_nodes_, HYBRID, j, size_, and WORKER.

Referenced by submit_request().

◆ send_heartbeat()

void tinyllama::DistributedCoordinator::send_heartbeat ( )
private

Send heartbeat to all nodes.

Definition at line 570 of file distributed_coordinator.cpp.

570 {
571#ifdef HAS_MPI
572 for (int i = 1; i < size_; ++i) {
573 int heartbeat = 1;
575 }
576#endif
577}

References j, size_, and TAG_HEARTBEAT.

Referenced by run_master().

◆ send_request_to_worker()

bool tinyllama::DistributedCoordinator::send_request_to_worker ( int  worker_rank,
const InferenceRequest &  request 
)
private

Send request to worker node.

Definition at line 264 of file distributed_coordinator.cpp.

264 {
265#ifdef HAS_MPI
266 std::vector<char> serialized = serialize_request(request);
267
268 // Send size first
269 int size = static_cast<int>(serialized.size());
271 if (result != MPI_SUCCESS) {
272 return false;
273 }
274
275 // Send data
277 return result == MPI_SUCCESS;
278#else
279 return false;
280#endif
281}
std::vector< char > serialize_request(const InferenceRequest &request)
Serialize request for MPI transmission.

References j, serialize_request(), and TAG_REQUEST.

Referenced by submit_request().

◆ send_result_to_master()

bool tinyllama::DistributedCoordinator::send_result_to_master ( const InferenceResult &  result)
private

Send result back to master.

Definition at line 432 of file distributed_coordinator.cpp.

432 {
433#ifdef HAS_MPI
434 std::vector<char> serialized = serialize_result(result);
435
436 // Send size first
437 int size = static_cast<int>(serialized.size());
439 if (mpi_result != MPI_SUCCESS) {
440 return false;
441 }
442
443 // Send data
445 return mpi_result == MPI_SUCCESS;
446#else
447 return false;
448#endif
449}
std::vector< char > serialize_result(const InferenceResult &result)
Serialize result for MPI transmission.

References j, serialize_result(), and TAG_RESULT.

Referenced by receive_and_process_request().

◆ serialize_request()

std::vector< char > tinyllama::DistributedCoordinator::serialize_request ( const InferenceRequest &  request)
private

Serialize request for MPI transmission.

Definition at line 451 of file distributed_coordinator.cpp.

451 {
452 std::ostringstream oss;
453 oss << request.request_id << "|"
454 << request.prompt << "|"
455 << request.max_tokens << "|"
456 << request.temperature << "|"
457 << request.top_k << "|"
458 << request.top_p << "|"
459 << request.system_prompt << "|"
460 << request.target_node;
461
462 std::string str = oss.str();
463 return std::vector<char>(str.begin(), str.end());
464}

References j, and str.

Referenced by send_request_to_worker().

◆ serialize_result()

std::vector< char > tinyllama::DistributedCoordinator::serialize_result ( const InferenceResult &  result)
private

Serialize result for MPI transmission.

Definition at line 495 of file distributed_coordinator.cpp.

495 {
496 std::ostringstream oss;
497 oss << result.request_id << "|"
498 << result.generated_text << "|"
499 << result.tokens_generated << "|"
500 << result.inference_time_ms << "|"
501 << result.processing_node << "|"
502 << (result.success ? 1 : 0) << "|"
503 << result.error_message;
504
505 std::string str = oss.str();
506 return std::vector<char>(str.begin(), str.end());
507}

References j, and str.

Referenced by send_result_to_master().

◆ shutdown()

void tinyllama::DistributedCoordinator::shutdown ( )

Shutdown MPI and cleanup resources.

Definition at line 61 of file distributed_coordinator.cpp.

61 {
62#ifdef HAS_MPI
63 if (mpi_initialized_) {
64 // Send shutdown signal to all nodes
65 if (rank_ == 0) {
66 for (int i = 1; i < size_; ++i) {
67 int shutdown_signal = 1;
69 }
70 }
71
73 mpi_initialized_ = false;
74 Logger::log("MPI finalized", Logger::INFO);
75 }
76#endif
77}

References Logger::INFO, j, mpi_initialized_, rank_, size_, and TAG_SHUTDOWN.

Referenced by ~DistributedCoordinator().

◆ submit_request()

bool tinyllama::DistributedCoordinator::submit_request ( const InferenceRequest &  request,
std::function< void(const InferenceResult &)>  callback 
)

Submit an inference request (master node only)

Parameters
requestThe inference request
callbackCallback function for result
Returns
true if request was submitted successfully

Definition at line 196 of file distributed_coordinator.cpp.

197 {
198#ifdef HAS_MPI
199 if (!mpi_initialized_ || rank_ != 0) {
200 Logger::log("Only master node (rank 0) can submit requests", Logger::ERROR);
201 return false;
202 }
203
204 // Store callback for later
205 pending_callbacks_[request.request_id] = callback;
206
207 // Select optimal worker node
208 int target_node = select_optimal_node(request);
209 if (target_node == -1) {
210 Logger::log("No available worker nodes", Logger::ERROR);
211 InferenceResult error_result;
212 error_result.request_id = request.request_id;
213 error_result.success = false;
214 error_result.error_message = "No available worker nodes";
216 return false;
217 }
218
219 // Send request to worker
220 bool sent = send_request_to_worker(target_node, request);
221 if (!sent) {
222 Logger::log("Failed to send request to worker node " + std::to_string(target_node), Logger::ERROR);
223 InferenceResult error_result;
224 error_result.request_id = request.request_id;
225 error_result.success = false;
226 error_result.error_message = "Failed to send request to worker";
228 return false;
229 }
230
232 return true;
233#else
234 // Fallback to local processing if MPI not available
235 InferenceResult result = process_inference_locally(request);
237 return result.success;
238#endif
239}
bool send_request_to_worker(int worker_rank, const InferenceRequest &request)
Send request to worker node.
int select_optimal_node(const InferenceRequest &request)
Select optimal node for processing request.

References Logger::ERROR, j, mpi_initialized_, pending_callbacks_, process_inference_locally(), rank_, tinyllama::DistributedCoordinator::InferenceResult::request_id, select_optimal_node(), send_request_to_worker(), and total_requests_.

Member Data Documentation

◆ cluster_nodes_

std::vector<NodeInfo> tinyllama::DistributedCoordinator::cluster_nodes_
private

◆ completed_requests_

std::atomic<int> tinyllama::DistributedCoordinator::completed_requests_ {0}
private

Definition at line 155 of file distributed_coordinator.h.

155{0};

Referenced by get_load_stats(), and receive_result_from_worker().

◆ failed_requests_

std::atomic<int> tinyllama::DistributedCoordinator::failed_requests_ {0}
private

Definition at line 156 of file distributed_coordinator.h.

156{0};

Referenced by get_load_stats(), and receive_result_from_worker().

◆ gpu_layers_

int tinyllama::DistributedCoordinator::gpu_layers_
private

Definition at line 144 of file distributed_coordinator.h.

Referenced by discover_cluster().

◆ model_path_

std::string tinyllama::DistributedCoordinator::model_path_
private

Definition at line 142 of file distributed_coordinator.h.

◆ mpi_initialized_

bool tinyllama::DistributedCoordinator::mpi_initialized_ = false
private

◆ pending_callbacks_

std::map<std::string, std::function<void(const InferenceResult&)> > tinyllama::DistributedCoordinator::pending_callbacks_
private

Definition at line 151 of file distributed_coordinator.h.

Referenced by receive_result_from_worker(), and submit_request().

◆ rank_

int tinyllama::DistributedCoordinator::rank_ = -1
private

◆ role_

NodeRole tinyllama::DistributedCoordinator::role_
private

Definition at line 141 of file distributed_coordinator.h.

Referenced by discover_cluster().

◆ size_

int tinyllama::DistributedCoordinator::size_ = -1
private

◆ TAG_HEARTBEAT

constexpr int tinyllama::DistributedCoordinator::TAG_HEARTBEAT = 3
staticconstexprprivate

Definition at line 161 of file distributed_coordinator.h.

Referenced by send_heartbeat().

◆ TAG_NODE_INFO

constexpr int tinyllama::DistributedCoordinator::TAG_NODE_INFO = 5
staticconstexprprivate

Definition at line 163 of file distributed_coordinator.h.

Referenced by discover_cluster().

◆ TAG_REQUEST

constexpr int tinyllama::DistributedCoordinator::TAG_REQUEST = 1
staticconstexprprivate

◆ TAG_RESULT

constexpr int tinyllama::DistributedCoordinator::TAG_RESULT = 2
staticconstexprprivate

Definition at line 160 of file distributed_coordinator.h.

Referenced by receive_result_from_worker(), and send_result_to_master().

◆ TAG_SHUTDOWN

constexpr int tinyllama::DistributedCoordinator::TAG_SHUTDOWN = 4
staticconstexprprivate

Definition at line 162 of file distributed_coordinator.h.

Referenced by run_worker(), and shutdown().

◆ tokenizer_path_

std::string tinyllama::DistributedCoordinator::tokenizer_path_
private

Definition at line 143 of file distributed_coordinator.h.

◆ total_requests_

std::atomic<int> tinyllama::DistributedCoordinator::total_requests_ {0}
private

Definition at line 154 of file distributed_coordinator.h.

154{0};

Referenced by get_load_stats(), and submit_request().


The documentation for this class was generated from the following files:
