ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
cuda_kernels.cu File Reference

CUDA kernel implementations for TinyLlama GPU operations. More...

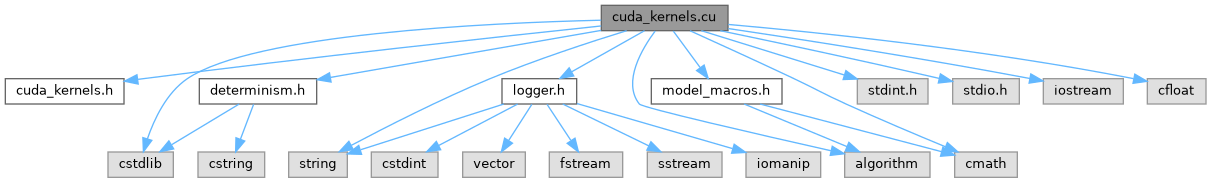
#include "cuda_kernels.h"
#include "determinism.h"
#include "logger.h"
#include "model_macros.h"
#include <stdint.h>
#include <stdio.h>
#include <algorithm>
#include <cmath>
#include <iostream>
#include <cfloat>
#include <cstdlib>
#include <string>
Include dependency graph for cuda_kernels.cu:

Go to the source code of this file.

Functions

static bool kernel_debug_copies ()
 
__device__ float atomicMaxFloat (float *address, float val)
 
__device__ float atomicAddFloat (float *address, float val)
 
__device__ float bf16_to_float32_device (uint16_t bf16_raw)
 Converts BF16 to FP32 on the device.
 
__device__ uint16_t float32_to_bf16_device (float fp32_val)
 
__global__ void rmsnorm_sum_squares_kernel (const float *x, float *partial_sums, int n)
 Kernel for computing sum of squares in RMS normalization.
 
__global__ void rmsnorm_apply_kernel (const float *x, const float *weight, float *out, int n, float inv_norm_factor)
 Kernel for applying RMS normalization.
 
__global__ void reduce_partial_sums_kernel (const float *partial_sums, float *total_sum_sq_out, int num_partial_sums)
 
void rmsnorm_vector_cuda (const float *x_dev, const float *weight_dev, float *out_dev, int n, float eps, cudaStream_t stream)
 Implementation of RMS normalization with device pointers.
 
void rmsnorm_vector_cuda (const std::vector< float > &x_in_host, const std::vector< float > &weight_host, std::vector< float > &out_host, int n, float eps)
 
void matvec_f32_f32_cuda (cublasHandle_t handle, const float *mat_f32_dev, const float *vec_f32_dev, float *out_f32_dev, int rows, int cols, cudaStream_t stream)
 Implementation of matrix-vector multiplication with FP32.
 
void matvec_bf16_f32_cuda (cublasHandle_t handle, const uint16_t *mat_bf16_dev, const float *vec_f32_dev, float *out_f32_dev, int rows, int cols, bool use_tensor_cores, cudaStream_t stream)
 Matrix-vector multiplication with BF16 matrix and FP32 vector/output on GPU.
 
void matvec_f32_f32_cuda (cublasHandle_t handle, const std::vector< float > &mat_f32_host, const std::vector< float > &vec_f32_host, std::vector< float > &out_f32_host, int rows, int cols)
 
__global__ void silu_kernel (const float *x, float *out, int n)
 
void silu_cuda (const std::vector< float > &x_host, std::vector< float > &out_host, int n)
 
__global__ void softmax_find_max_kernel (const float *x, float *partial_max, int n)
 
__global__ void softmax_exp_sum_kernel (const float *x, float *partial_sums, int n, float max_val)
 
__global__ void softmax_normalize_kernel (const float *x, float *out, int n, float max_val, float inv_sum)
 
void softmax_vector_cuda (const std::vector< float > &x_host, std::vector< float > &out_host, int n)
 
__global__ void swiglu_kernel (const float *gate, const float *up, float *out, int n)
 
void swiglu_cuda (const float *gate_dev, const float *up_dev, float *out_dev, int n, cudaStream_t stream)
 
__global__ void swiglu_batch_cuda_kernel (float *d_out_batch, const float *d_gate_act_batch, const float *d_up_act_batch, int num_tokens, int intermediate_size)
 
void swiglu_batch_cuda (float *d_out_batch, const float *d_gate_act_batch, const float *d_up_act_batch, int num_tokens, int intermediate_size, cudaStream_t stream)
 
__global__ void rope_kernel (float *x, int num_heads, int head_dim, const float *all_freqs_cis_base, int pos, bool use_adjacent_pairing)
 
void rope_cuda (float *x_dev, int num_heads, int head_dim, const float *all_freqs_cis_dev_base, int pos, bool use_adjacent_pairing, cudaStream_t stream)
 
__global__ void rope_batch_kernel_cuda (float *x_batch_tensor, int num_tokens, int num_heads_in_tensor, int head_dim, const float *d_all_freqs_cis_base, int start_pos_offset, bool use_adjacent_pairing)
 
void rope_batch_cuda (float *d_q_batch, float *d_k_batch, const float *d_all_freqs_cis_base, int num_tokens, int num_q_heads, int num_kv_heads, int head_dim, int start_pos_in_kv_cache, bool use_adjacent_pairing, cudaStream_t stream)
 
__global__ void attention_kernel (const float *Q_current, const float *K_layer_cache_base, const float *V_layer_cache_base, float *out, int current_seq_len, int head_dim, float scale, int cache_num_kv_heads, int num_q_heads)
 
void attention_cuda (const float *Q_current_dev, const float *K_layer_cache_base, const float *V_layer_cache_base, float *out_dev, int num_heads, int current_seq_len, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads, cudaStream_t stream)
 
__global__ void attention_selective_dequant_kernel (const float *__restrict__ Q_current_dev, const int8_t *__restrict__ K_quantized_cache_base, const int8_t *__restrict__ V_quantized_cache_base, const float *__restrict__ K_scales_cache_base, const float *__restrict__ V_scales_cache_base, float *__restrict__ selective_k_dequant_buffer, float *__restrict__ selective_v_dequant_buffer, float *__restrict__ out_dev, int num_heads, int current_seq_len, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads)
 
void attention_cuda_selective_dequant (const float *Q_current_dev, const int8_t *K_quantized_cache_base, const int8_t *V_quantized_cache_base, const float *K_scales_cache_base, const float *V_scales_cache_base, float *selective_k_dequant_buffer, float *selective_v_dequant_buffer, float *out_dev, int num_heads, int current_seq_len, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads, cudaStream_t stream)
 
__global__ void add_vectors_kernel (const float *a, const float *b, float *result, int n)
 
void add_vectors_cuda (const float *a_dev, const float *b_dev, float *result_dev, int n, cudaStream_t stream)
 
__global__ void add_residual_kernel (const float *matvec_out, const float *residual, float *result, int n)
 
void add_residual_cuda (const float *matvec_out_dev, const float *residual_dev, float *result_dev, int n, cudaStream_t stream)
 
__global__ void add_residual_batch_cuda_kernel (float *d_output_batch, const float *d_input_a_batch, const float *d_input_b_batch, int num_tokens, int hidden_size)
 
void add_residual_batch_cuda (float *d_output_batch, const float *d_input_a_batch, const float *d_input_b_batch, int num_tokens, int hidden_size, cudaStream_t stream)
 
__global__ void update_kv_cache_kernel (float *cache_base_ptr, const float *current_kv_vector, int pos, int kv_head_idx, int max_seq_len, int num_kv_heads, int head_dim)
 
void update_kv_cache_cuda (float *cache_base_ptr, const float *current_kv_head_vector, int pos, int kv_head_idx, int max_seq_len, int num_kv_heads, int head_dim, cudaStream_t stream)
 
__global__ void rope_and_update_kv_cache_kernel (float *cache_base_ptr, const float *kv_vector_head, const float *all_freqs_cis_base, int pos, int kv_head_idx, int max_seq_len, int num_kv_heads, int head_dim)
 
void rope_and_update_kv_cache_cuda (float *cache_base_ptr, const float *kv_vector_head, const float *all_freqs_cis_base, int pos, int kv_head_idx, int max_seq_len, int num_kv_heads, int head_dim, cudaStream_t stream)
 
__global__ void lookup_embedding_kernel (const void *__restrict__ table_dev, float *__restrict__ output_dev, int token_id, int hidden_size, int vocab_size, bool is_bf16)
 
void lookup_embedding_cuda (const void *table_dev, float *output_dev, int token_id, int hidden_size, int vocab_size, bool is_bf16, cudaStream_t stream)
 
__global__ void convert_bf16_to_fp32_kernel (const uint16_t *__restrict__ bf16_in, float *__restrict__ fp32_out, size_t n_elements)
 
__global__ void rmsnorm_optimized_kernel (const float *__restrict__ x, const float *__restrict__ weight, float *__restrict__ out, int n, float eps)
 Optimized RMS normalization using simple warp primitives and shared memory.
 
__global__ void softmax_optimized_kernel (const float *__restrict__ x, float *__restrict__ out, int n)
 Optimized softmax using shared memory and warp primitives.
 
__global__ void attention_optimized_kernel (const float *__restrict__ Q_current, const float *__restrict__ K_layer_cache_base, const float *__restrict__ V_layer_cache_base, float *__restrict__ out, int current_seq_len, int head_dim, float scale, int cache_num_kv_heads, int num_q_heads, const int *step_dev)
 Corrected and optimized attention kernel.
 
__global__ void rmsnorm_optimized_det_kernel (const float *__restrict__ x, const float *__restrict__ weight, float *__restrict__ out, int n, float eps)
 
__global__ void attention_optimized_det_kernel (const float *__restrict__ Q_current, const float *__restrict__ K_layer_cache_base, const float *__restrict__ V_layer_cache_base, float *__restrict__ out, int current_seq_len, int head_dim, float scale, int cache_num_kv_heads, int num_q_heads, const int *step_dev)
 
void rmsnorm_vector_cuda_optimized (const float *x_dev, const float *weight_dev, float *out_dev, int n, float eps, cudaStream_t stream)
 Optimized wrappers using the new high-performance kernels.
 
void softmax_vector_cuda_optimized (const float *x_dev, float *out_dev, int n, cudaStream_t stream)
 
int decode_attention_kind ()
 
void decode_attention_tiles (int *min_chunk, int *max_chunks)
 
void attention_cuda_optimized (const float *Q_current_dev, const float *K_layer_cache_base, const float *V_layer_cache_base, float *out_dev, int num_heads, int current_seq_len, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads, cudaStream_t stream)
 
__global__ void convert_fp32_to_bf16_kernel (const float *__restrict__ fp32_in, uint16_t *__restrict__ bf16_out, size_t n_elements)
 
void convert_fp32_to_bf16_cuda (const float *fp32_in_dev, uint16_t *bf16_out_dev, size_t n_elements, cudaStream_t stream)
 
void gemm_bf16_bf16_cuda (cublasHandle_t handle, bool transa_user, bool transb_user, int m_user, int n_user, int k_user, const float *alpha_user, const uint16_t *A_bf16_user, int lda_user, const uint16_t *B_bf16_user, int ldb_user, const float *beta_user, uint16_t *C_bf16_user, int ldc_user, cudaStream_t stream)
 
void gemm_f32_to_bf16_f32_cuda (cublasHandle_t handle, bool transa_user, bool transb_user, int m_user, int n_user, int k_user, const float *alpha_user, const float *A_f32_user, int lda_user, const uint16_t *B_bf16_user, int ldb_user, const float *beta_user, float *C_f32_user, int ldc_user, cudaStream_t stream)
 
void convert_bf16_to_fp32_cuda (const uint16_t *bf16_in_dev, float *fp32_out_dev, size_t n_elements, cudaStream_t stream)
 
__global__ void decode_embed_kernel (const float *__restrict__ table, float *__restrict__ out, const int *__restrict__ step_dev, int hidden_size, int vocab_size)
 
void decode_embed_cuda (const float *table_dev, float *out_dev, const int *step_dev, int hidden_size, int vocab_size, cudaStream_t stream)
 
__global__ void rope_devpos_kernel (float *x, int num_heads, int head_dim, const float *all_freqs_cis_base, const int *step_dev, bool use_adjacent_pairing)
 
void rope_devpos_cuda (float *x_dev, int num_heads, int head_dim, const float *all_freqs_cis_dev_base, const int *step_dev, bool use_adjacent_pairing, cudaStream_t stream)
 
__global__ void kv_write_devpos_kernel (float *k_cache, float *v_cache, const float *__restrict__ k, const float *__restrict__ v, const int *step_dev, int row)
 
void kv_write_devpos_cuda (float *k_cache_dev, float *v_cache_dev, const float *k_dev, const float *v_dev, const int *step_dev, int row, cudaStream_t stream)
 
void attention_decode_at_cuda (const float *Q_current_dev, const float *K_layer_cache_base, const float *V_layer_cache_base, float *out_dev, int num_heads, int seq_len, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads, cudaStream_t stream)
 
void attention_devpos_cuda (const float *Q_current_dev, const float *K_layer_cache_base, const float *V_layer_cache_base, float *out_dev, int num_heads, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads, const int *step_dev, cudaStream_t stream)
 
void gemm_rm_f32_cuda (cublasHandle_t handle, const float *X, const float *W, float *Y, int T, int O, int I, cudaStream_t stream)
 
size_t moe_ffn_scratch_floats (int T, int d, int d_ff, int E, int k)
 
void moe_ffn_cuda (cublasHandle_t handle, const float *x, int T, int d, int d_ff, int E, int k, bool renorm, const float *router, const float *gate_exps, const float *up_exps, const float *down_exps, float *scratch, float *out, cudaStream_t stream)
 

Detailed Description

CUDA kernel implementations for TinyLlama GPU operations.

This file contains the actual CUDA kernel implementations for the GPU-accelerated operations declared in cuda_kernels.h. The implementations are optimized for NVIDIA GPUs and use CUDA-specific features for maximum performance.

Key implementation details:

  • Uses shared memory for efficient reduction operations
  • Implements parallel reduction patterns for normalization
  • Leverages cuBLAS for matrix operations
  • Supports both FP32 and BF16 formats
  • Includes error checking and memory management

Definition in file cuda_kernels.cu.

Function Documentation

◆ add_residual_batch_cuda()

void add_residual_batch_cuda ( float *  d_output_batch,
const float *  d_input_a_batch,
const float *  d_input_b_batch,
int  num_tokens,
int  hidden_size,
cudaStream_t  stream 
)

Definition at line 1274 of file cuda_kernels.cu.

1280 {
1281
1282
1283 if (num_tokens == 0 || hidden_size == 0) {
1284 Logger::info("[ADD_RESIDUAL_BATCH_CUDA_SKIP] num_tokens or hidden_size is 0. Nothing to do.");
1285 Logger::info("[ADD_RESIDUAL_BATCH_CUDA_EXIT] Skipped operation.");
1286 return; // Nothing to do
1287 }
1288
1289 // Log initial input values (first token, first few elements)
1290 int log_count_elements = std::min(3, hidden_size);
1291 if (num_tokens > 0 && hidden_size > 0) {
1292 if (d_input_a_batch) {
1293 std::vector<float> h_input_a_sample(log_count_elements);
1294 // Input A is [num_tokens, hidden_size]. Offset for T0 is 0.
1296 }
1297 if (d_input_b_batch) {
1298 std::vector<float> h_input_b_sample(log_count_elements);
1299 // Input B is [num_tokens, hidden_size]. Offset for T0 is 0.
1301 }
1302 }
1303
1304 const int threads_per_block = 256;
1307
1312 num_tokens,
1313 hidden_size
1314 );
1316
1317 // Log output values
1318 if (num_tokens > 0 && hidden_size > 0 && d_output_batch) {
1319 std::vector<float> h_output_sample(log_count_elements);
1320 // Output is [num_tokens, hidden_size]. Offset for T0 is 0.
1322 }
1323}
static void info(const std::string &message)
Definition logger.cpp:135
static bool kernel_debug_copies()
size_t j

References Logger::info(), j, and kernel_debug_copies().

◆ add_residual_batch_cuda_kernel()

__global__ void add_residual_batch_cuda_kernel ( float *  d_output_batch,
const float *  d_input_a_batch,
const float *  d_input_b_batch,
int  num_tokens,
int  hidden_size 
)

Definition at line 1250 of file cuda_kernels.cu.

1255 {
1256
1257 int token_idx = blockIdx.x;
1258 if (token_idx >= num_tokens) {
1259 return;
1260 }
1261
1262 // Base pointers for the current token
1263 const float* current_token_input_a_ptr = d_input_a_batch + (size_t)token_idx * hidden_size;
1264 const float* current_token_input_b_ptr = d_input_b_batch + (size_t)token_idx * hidden_size;
1265 float* current_token_output_ptr = d_output_batch + (size_t)token_idx * hidden_size;
1266
1267 // Threads in the block parallelize over hidden_size
1268 for (int i = threadIdx.x; i < hidden_size; i += blockDim.x) {
1270 }
1271}

References j.

◆ add_residual_cuda()

void add_residual_cuda ( const float *  matvec_out_dev,
const float *  residual_dev,
float *  result_dev,
int  n,
cudaStream_t  stream 
)

Definition at line 1239 of file cuda_kernels.cu.

References j, and n.

◆ add_residual_kernel()

__global__ void add_residual_kernel ( const float *  matvec_out,
const float *  residual,
float *  result,
int  n 
)

Definition at line 1230 of file cuda_kernels.cu.

1232 {
1233 int i = blockIdx.x * blockDim.x + threadIdx.x;
1234 if (i < n) {
1235 result[i] = matvec_out[i] + residual[i];
1236 }
1237}

References j, and n.

◆ add_vectors_cuda()

void add_vectors_cuda ( const float *  a_dev,
const float *  b_dev,
float *  result_dev,
int  n,
cudaStream_t  stream 
)

Definition at line 1220 of file cuda_kernels.cu.

References j, and n.

◆ add_vectors_kernel()

__global__ void add_vectors_kernel ( const float *  a,
const float *  b,
float *  result,
int  n 
)

Definition at line 1212 of file cuda_kernels.cu.

1213 {
1214 int i = blockIdx.x * blockDim.x + threadIdx.x;
1215 if (i < n) {
1216 result[i] = a[i] + b[i];
1217 }
1218}
std::vector< E > a

References a, j, and n.

◆ atomicAddFloat()

__device__ float atomicAddFloat ( float *  address,
float  val 
)

Definition at line 81 of file cuda_kernels.cu.

81 {
82 int* address_as_int = (int*)address;
84 do {
85 assumed = old;
88 } while (assumed != old);
89 return __int_as_float(old);
90}

References j.

Referenced by attention_optimized_kernel(), and softmax_optimized_kernel().

◆ atomicMaxFloat()

__device__ float atomicMaxFloat ( float *  address,
float  val 
)

Definition at line 70 of file cuda_kernels.cu.

70 {
71 int* address_as_int = (int*)address;
73 do {
74 assumed = old;
77 } while (assumed != old);
78 return __int_as_float(old);
79}

References j.

Referenced by attention_optimized_kernel(), and softmax_optimized_kernel().

◆ attention_cuda()

void attention_cuda ( const float *  Q_current_dev,
const float *  K_layer_cache_base,
const float *  V_layer_cache_base,
float *  out_dev,
int  num_heads,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_max_seq_len,
int  cache_num_kv_heads,
cudaStream_t  stream 
)

Definition at line 1093 of file cuda_kernels.cu.

1097 {
1098 // Grid: num_heads blocks, each block handles one attention head
1099 // Block: head_dim threads, each thread handles one output dimension
1102 // scores[current_seq_len] + dot_product_terms[head_dim] (the kernel's extern shared layout)
1103 const size_t shm = (size_t)(current_seq_len + head_dim) * sizeof(float);
1104
1109}
node scale

References j, and scale.

◆ attention_cuda_optimized()

void attention_cuda_optimized ( const float *  Q_current_dev,
const float *  K_layer_cache_base,
const float *  V_layer_cache_base,
float *  out_dev,
int  num_heads,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_max_seq_len,
int  cache_num_kv_heads,
cudaStream_t  stream 
)

◆ attention_cuda_selective_dequant()

void attention_cuda_selective_dequant ( const float *  Q_current_dev,
const int8_t *  K_quantized_cache_base,
const int8_t *  V_quantized_cache_base,
const float *  K_scales_cache_base,
const float *  V_scales_cache_base,
float *  selective_k_dequant_buffer,
float *  selective_v_dequant_buffer,
float *  out_dev,
int  num_heads,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_max_seq_len,
int  cache_num_kv_heads,
cudaStream_t  stream 
)

Definition at line 1178 of file cuda_kernels.cu.

1188 {
1189
1190 if (num_heads == 0 || current_seq_len == 0 || head_dim == 0) {
1191 Logger::warning("[ATTENTION_SELECTIVE_DEQUANT] Invalid parameters: num_heads=" +
1192 std::to_string(num_heads) + ", current_seq_len=" + std::to_string(current_seq_len) +
1193 ", head_dim=" + std::to_string(head_dim));
1194 return;
1195 }
1196
1197 // Grid: num_heads blocks, each block handles one attention head
1198 // Block: head_dim threads, each thread handles one output dimension
1201
1208
1210}
static void warning(const std::string &message)
Definition logger.cpp:139

References j, scale, and Logger::warning().

◆ attention_decode_at_cuda()

void attention_decode_at_cuda ( const float *  Q_current_dev,
const float *  K_layer_cache_base,
const float *  V_layer_cache_base,
float *  out_dev,
int  num_heads,
int  seq_len,
int  head_dim,
float  scale,
int  cache_max_seq_len,
int  cache_num_kv_heads,
cudaStream_t  stream 
)

Definition at line 3600 of file cuda_kernels.cu.

3603 {
3608}
void attention_cuda_optimized(const float *Q_current_dev, const float *K_layer_cache_base, const float *V_layer_cache_base, float *out_dev, int num_heads, int current_seq_len, int head_dim, float scale, int cache_max_seq_len, int cache_num_kv_heads, cudaStream_t stream)

References attention_cuda_optimized(), j, and scale.

◆ attention_devpos_cuda()

void attention_devpos_cuda ( const float *  Q_current_dev,
const float *  K_layer_cache_base,
const float *  V_layer_cache_base,
float *  out_dev,
int  num_heads,
int  head_dim,
float  scale,
int  cache_max_seq_len,
int  cache_num_kv_heads,
const int *  step_dev,
cudaStream_t  stream 
)

◆ attention_kernel()

__global__ void attention_kernel ( const float *  Q_current,
const float *  K_layer_cache_base,
const float *  V_layer_cache_base,
float *  out,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_num_kv_heads,
int  num_q_heads 
)

Definition at line 981 of file cuda_kernels.cu.

985 {
986
987
988 int q_head_idx = blockIdx.x;
989 int d_idx = threadIdx.x; // dimension index for this thread
990
991 if (q_head_idx >= num_q_heads) return; // Should not happen with correct launch
992
993 // Determine the corresponding KV head for this Q head (for GQA/MQA)
996
997 // Shared memory for scores (one score per k_pos) and for dot product reduction
998 extern __shared__ float shared_data[];
999 float* scores = shared_data; // First part of shared_data: size current_seq_len
1000 float* dot_product_terms = &shared_data[current_seq_len]; // Second part: size head_dim (blockDim.x)
1001
1002 // Pointer to the current query head's data
1003 const float* q_head_ptr = Q_current + q_head_idx * head_dim;
1004
1005 for (int k_pos = 0; k_pos < current_seq_len; ++k_pos) {
1006 // Pointer to the k_pos-th key vector for the relevant kv_head
1008 (size_t)kv_head_idx * head_dim;
1009 const float* k_vec_ptr = K_layer_cache_base + k_vec_offset;
1010
1012 __syncthreads(); // Ensure all terms are written before reduction
1013
1014 // Reduction in shared memory (e.g., by thread 0 or tree-based)
1015 if (d_idx == 0) {
1016 float current_dot = 0.0f;
1017 for (int r = 0; r < head_dim; ++r) {
1019 }
1020 scores[k_pos] = current_dot * scale;
1021 }
1022 __syncthreads();
1023 }
1024
1025 float thread_max_score = -INFINITY;
1026 for (int i = d_idx; i < current_seq_len; i += blockDim.x) { // blockDim.x is head_dim
1027 if (scores[i] > thread_max_score) {
1028 thread_max_score = scores[i];
1029 }
1030 }
1031 dot_product_terms[d_idx] = thread_max_score; // Repurpose dot_product_terms shared memory
1032 __syncthreads();
1033
1034 float block_max_score = -INFINITY;
1035 if (d_idx == 0) {
1036 for (int r = 0; r < head_dim; ++r) { // head_dim might be > current_seq_len for first few tokens
1037 if (dot_product_terms[r] > block_max_score) { // Check if dot_product_terms[r] was validly written
1039 }
1040 }
1041 }
1042 __syncthreads();
1043 if(d_idx == 0) dot_product_terms[0] = block_max_score; // Store it.
1044 __syncthreads();
1045 block_max_score = dot_product_terms[0]; // All threads read it.
1046
1047
1048 // Calculate exp scores and sum
1049 float thread_exp_sum = 0.0f;
1050 for (int i = d_idx; i < current_seq_len; i += blockDim.x) {
1051 float prob = expf(scores[i] - block_max_score);
1052 scores[i] = prob; // Update scores in-place with exp(val - max)
1054 }
1055 // Reduce thread_exp_sum across the block
1056 dot_product_terms[d_idx] = thread_exp_sum; // Repurpose again
1057 __syncthreads();
1058
1059 float block_exp_sum = 0.0f;
1060 if (d_idx == 0) {
1061 for (int r = 0; r < head_dim; ++r) { // Similar concern as max_score reduction range
1063 }
1064 }
1065 __syncthreads();
1066 // Store and reload block_exp_sum for all threads
1068 __syncthreads();
1070
1071
1072 float inv_sum = 1.0f / (block_exp_sum + 1e-9f); // Add epsilon for stability
1073
1074 // Normalize scores in shared memory
1075 for (int i = d_idx; i < current_seq_len; i += blockDim.x) {
1076 scores[i] *= inv_sum;
1077 }
1078 __syncthreads(); // Ensure all scores are normalized before weighted sum
1079
1080 double weighted_val_d = 0.0; // Use double for accumulation
1081 for (int k_pos = 0; k_pos < current_seq_len; ++k_pos) {
1083 (size_t)kv_head_idx * head_dim;
1084 const float* v_vec_ptr = V_layer_cache_base + v_vec_offset;
1085
1086 weighted_val_d += static_cast<double>(scores[k_pos]) * static_cast<double>(v_vec_ptr[d_idx]);
1087 }
1088
1089 // Write the final result for this thread's dimension d_idx
1090 out[q_head_idx * head_dim + d_idx] = static_cast<float>(weighted_val_d);
1091}
node out

References j, out, and scale.

◆ attention_optimized_det_kernel()

__global__ void attention_optimized_det_kernel ( const float *__restrict__  Q_current,
const float *__restrict__  K_layer_cache_base,
const float *__restrict__  V_layer_cache_base,
float *__restrict__  out,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_num_kv_heads,
int  num_q_heads,
const int *  step_dev 
)

Definition at line 2987 of file cuda_kernels.cu.

2993 {
2994 if (step_dev) current_seq_len = step_dev[1] + 1;
2995
2996 const int head_idx = blockIdx.x;
2997 const int tid_in_block = threadIdx.x;
2998 const int block_dim_x = blockDim.x;
2999
3000 if (head_idx >= num_q_heads) return;
3001
3003 const int kv_head_idx = head_idx / heads_per_kv;
3004
3005 extern __shared__ float s_data[];
3006 float* s_scores = s_data; // [current_seq_len]
3007 __shared__ float s_warp_val[32]; // one partial per warp
3008 __shared__ float s_block_val; // the block-wide max, then sum
3009 const int num_warps = (block_dim_x + warpSize - 1) / warpSize;
3010
3011 const float* q_vec = Q_current + head_idx * head_dim;
3012
3013 // --- 1. Q.K^T scores ---
3016 float score = 0.0f;
3017 for (int d = 0; d < head_dim; ++d) {
3018 score += q_vec[d] * k_vec[d];
3019 }
3020 s_scores[k_idx] = score * scale;
3021 }
3022 __syncthreads();
3023
3024 // --- 2a. max score: warp maxima, then in warp order ---
3025 float thread_max_score = -INFINITY;
3028 }
3029 for (int offset = warpSize / 2; offset > 0; offset >>= 1) thread_max_score = fmaxf(thread_max_score, __shfl_down_sync(0xFFFFFFFF, thread_max_score, offset));
3031 __syncthreads();
3032 if (tid_in_block == 0) {
3033 float m = -INFINITY;
3034 for (int w = 0; w < num_warps; ++w) m = fmaxf(s_warp_val[w], m);
3035 s_block_val = m;
3036 }
3037 __syncthreads();
3038 float max_score = s_block_val;
3039 __syncthreads(); // every thread has read the max before the slots are reused
3040
3041 // --- 2b. exp and their sum: warp sums, then added in warp order ---
3042 float thread_sum_exp = 0.0f;
3044 float val = expf(s_scores[k_idx] - max_score);
3045 s_scores[k_idx] = val;
3047 }
3048 for (int offset = warpSize / 2; offset > 0; offset >>= 1) thread_sum_exp += __shfl_down_sync(0xFFFFFFFF, thread_sum_exp, offset);
3050 __syncthreads();
3051 if (tid_in_block == 0) {
3052 float s = 0.0f;
3053 for (int w = 0; w < num_warps; ++w) s = s_warp_val[w] + s;
3054 s_block_val = s;
3055 }
3056 __syncthreads();
3057 float sum_exp = s_block_val;
3058 float inv_sum_exp = (sum_exp == 0.0f || sum_exp < 1e-9f) ? 0.0f : 1.0f / sum_exp;
3059
3060 // --- 2c. normalise ---
3063 }
3064 __syncthreads();
3065
3066 // --- 3. P V ---
3068 for (int d_out = tid_in_block; d_out < head_dim; d_out += block_dim_x) {
3069 float weighted_val = 0.0f;
3070 for (int k_idx = 0; k_idx < current_seq_len; ++k_idx) {
3073 }
3075 }
3076}

References j, out, and scale.

◆ attention_optimized_kernel()

__global__ void attention_optimized_kernel ( const float *__restrict__  Q_current,
const float *__restrict__  K_layer_cache_base,
const float *__restrict__  V_layer_cache_base,
float *__restrict__  out,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_num_kv_heads,
int  num_q_heads,
const int *  step_dev 
)

Corrected and optimized attention kernel.

Uses shared memory for scores and performs a full softmax operation correctly. Each block computes attention for one head.

Definition at line 2839 of file cuda_kernels.cu.

2845 {
2846 // Graph decode: the length comes from device memory (step_dev[1] = pos).
2847 if (step_dev) current_seq_len = step_dev[1] + 1;
2848
2849 const int head_idx = blockIdx.x; // Current Q head index this block is working on
2850 const int tid_in_block = threadIdx.x;
2851 const int block_dim_x = blockDim.x; // Threads per block (e.g., 256)
2852
2853 if (head_idx >= num_q_heads) return;
2854
2855 // Map current Q head to its corresponding KV cache head index (for GQA/MQA)
2857 const int kv_head_idx = head_idx / heads_per_kv;
2858
2859 // Dynamic shared memory. Layout:
2860 // s_scores[current_seq_len]: to store Q.K^T results
2861 // s_reduction_val[1]: for block-wide max and sum_exp
2862 extern __shared__ float s_data[];
2863 float* s_scores = s_data;
2864 float* s_reduction_val = &s_data[current_seq_len]; // Single float for block-wide reduction
2865
2866 // Pointer to the current Q vector for this specific head
2867 // Assuming Q_current is already offset for the specific token if in batch generation.
2868 // Here, Q_current is expected to be just [head_idx * head_dim] for the current token's Q vector.
2869 const float* q_vec = Q_current + head_idx * head_dim;
2870
2871 // --- 1. Compute Q.K^T scores and store in s_scores ---
2873 // Pointer to the k_idx-th K vector in the cache for the relevant kv_head
2875 float score = 0.0f;
2876 for (int d = 0; d < head_dim; ++d) {
2877 score += q_vec[d] * k_vec[d];
2878 }
2879 s_scores[k_idx] = score * scale;
2880 }
2881 __syncthreads(); // Ensure all scores are computed and stored in s_scores
2882
2883 // --- 2. Softmax calculation on s_scores ---
2884 // a. Find max score in s_scores (block-wide reduction)
2886 __syncthreads();
2887
2888 float thread_max_score = -INFINITY;
2891 }
2892 for (int offset = warpSize / 2; offset > 0; offset >>= 1) thread_max_score = fmaxf(thread_max_score, __shfl_down_sync(0xFFFFFFFF, thread_max_score, offset));
2894 __syncthreads();
2895 float max_score = *s_reduction_val;
2896 __syncthreads(); // every thread has read the max before thread 0 reuses the slot
2897
2898 // b. Subtract max, compute exp, and sum exp (block-wide reduction for sum)
2899 if (tid_in_block == 0) *s_reduction_val = 0.0f;
2900 __syncthreads();
2901
2902 float thread_sum_exp = 0.0f;
2904 float val = expf(s_scores[k_idx] - max_score);
2905 s_scores[k_idx] = val; // Store exp(score - max)
2907 }
2908 for (int offset = warpSize / 2; offset > 0; offset >>= 1) thread_sum_exp += __shfl_down_sync(0xFFFFFFFF, thread_sum_exp, offset);
2910 __syncthreads();
2911 float sum_exp = *s_reduction_val;
2912 float inv_sum_exp = (sum_exp == 0.0f || sum_exp < 1e-9f) ? 0.0f : 1.0f / sum_exp; // add small epsilon for stability
2913
2914 // c. Normalize s_scores (they now contain softmax probabilities)
2917 }
2918 __syncthreads();
2919
2920 // --- 3. Multiply by V and accumulate to output ---
2921 // Output for this head: out_for_this_head[d_out]
2923
2924 for (int d_out = tid_in_block; d_out < head_dim; d_out += block_dim_x) {
2925 float weighted_val = 0.0f;
2926 for (int k_idx = 0; k_idx < current_seq_len; ++k_idx) { // All threads iterate full k_idx to sum contributions
2929 }
2930 out_for_this_head[d_out] = weighted_val; // Each thread writes to its assigned output dimension part
2931 }
2932}
__device__ float atomicAddFloat(float *address, float val)
__device__ float atomicMaxFloat(float *address, float val)

References atomicAddFloat(), atomicMaxFloat(), j, out, and scale.

◆ attention_selective_dequant_kernel()

__global__ void attention_selective_dequant_kernel ( const float *__restrict__  Q_current_dev,
const int8_t *__restrict__  K_quantized_cache_base,
const int8_t *__restrict__  V_quantized_cache_base,
const float *__restrict__  K_scales_cache_base,
const float *__restrict__  V_scales_cache_base,
float *__restrict__  selective_k_dequant_buffer,
float *__restrict__  selective_v_dequant_buffer,
float *__restrict__  out_dev,
int  num_heads,
int  current_seq_len,
int  head_dim,
float  scale,
int  cache_max_seq_len,
int  cache_num_kv_heads 
)

Definition at line 1112 of file cuda_kernels.cu.

1122 {
1123
1124 int head_idx = blockIdx.x;
1125 int dim_idx = threadIdx.x;
1126
1127 if (head_idx >= num_heads || dim_idx >= head_dim) return;
1128
1129 // Map query head to corresponding KV head (for GQA/MQA)
1132
1133 // Get current query vector for this head and dimension
1135
1136 float attn_out = 0.0f;
1137
1138 // Selective dequantization and attention computation
1139 for (int t = 0; t < current_seq_len; ++t) {
1140 // Calculate offset for this token and KV head in the quantized cache
1143
1144 // Dequantize only the specific elements we need for this head/dimension
1145 if (dim_idx == 0) {
1146 // Only thread 0 in each block dequantizes the entire head for this token
1149
1150 for (int d = 0; d < head_dim; ++d) {
1151 // Dequantize K values for this token/head
1154
1155 // Dequantize V values for this token/head
1158 }
1159 }
1160
1161 __syncthreads(); // Ensure dequantization is complete before using values
1162
1163 // Compute attention score for this token
1165 float score = q_val * k_val * scale;
1166
1167 // Apply attention score to value
1169 attn_out += score * v_val;
1170
1171 __syncthreads(); // Ensure all threads are done before next iteration
1172 }
1173
1174 // Write output
1176}

References j, and scale.

◆ bf16_to_float32_device()

__device__ float bf16_to_float32_device ( uint16_t  bf16_raw)
inline

Converts BF16 to FP32 on the device.

This device function converts Brain Floating Point (BF16) values to FP32. It uses CUDA's native BF16 support on architectures >= 800, and falls back to a manual conversion on older architectures.

Parameters
bf16_rawRaw BF16 value as uint16_t
Returns
Converted FP32 value

Definition at line 102 of file cuda_kernels.cu.

102 {
103#if __CUDA_ARCH__ >= 800
105
106 memcpy(&bf16_val, &bf16_raw, sizeof(uint16_t));
108#else
109
110 unsigned int bits = ((unsigned int)bf16_raw) << 16;
111 float result;
112 memcpy(&result, &bits, sizeof(float));
113 return result;
114#endif
115}

References j.

Referenced by convert_bf16_to_fp32_kernel(), and lookup_embedding_kernel().

◆ convert_bf16_to_fp32_cuda()

void convert_bf16_to_fp32_cuda ( const uint16_t *  bf16_in_dev,
float *  fp32_out_dev,
size_t  n_elements,
cudaStream_t  stream 
)

Definition at line 3515 of file cuda_kernels.cu.

3516 {
3517 if (n_elements == 0) return;
3518
3519 const int threads = 256;
3520 const int blocks = (n_elements + threads - 1) / threads;
3521
3524}

References j.

Referenced by gemm_f32_to_bf16_f32_cuda().

◆ convert_bf16_to_fp32_kernel()

__global__ void convert_bf16_to_fp32_kernel ( const uint16_t *__restrict__  bf16_in,
float *__restrict__  fp32_out,
size_t  n_elements 
)

Definition at line 1498 of file cuda_kernels.cu.

1500 {
1501 size_t idx = blockIdx.x * blockDim.x + threadIdx.x;
1502 if (idx < n_elements) {
1504 }
1505}
__device__ float bf16_to_float32_device(uint16_t bf16_raw)
Converts BF16 to FP32 on the device.

References bf16_to_float32_device(), and j.

◆ convert_fp32_to_bf16_cuda()

void convert_fp32_to_bf16_cuda ( const float *  fp32_in_dev,
uint16_t *  bf16_out_dev,
size_t  n_elements,
cudaStream_t  stream 
)

Definition at line 3357 of file cuda_kernels.cu.

3358 {
3359 if (n_elements == 0) return;
3360
3361 const int threads = 256;
3362 const int blocks = (n_elements + threads - 1) / threads;
3363
3366}

References j.

Referenced by gemm_f32_to_bf16_f32_cuda().

◆ convert_fp32_to_bf16_kernel()

__global__ void convert_fp32_to_bf16_kernel ( const float *__restrict__  fp32_in,
uint16_t *__restrict__  bf16_out,
size_t  n_elements 
)

Definition at line 3347 of file cuda_kernels.cu.

3349 {
3350 size_t idx = blockIdx.x * blockDim.x + threadIdx.x;
3351 if (idx < n_elements) {
3353 }
3354}
__device__ uint16_t float32_to_bf16_device(float fp32_val)

References float32_to_bf16_device(), and j.

◆ decode_attention_kind()

int decode_attention_kind ( )

Definition at line 3297 of file cuda_kernels.cu.

3297 {
3298 static const int kind = [] {
3299 const char* e = std::getenv("EMBER_DECODE_ATTN");
3300 const std::string s = e ? e : "";
3301 return s == "legacy" ? 2 : s == "split" ? 1 : 0;
3302 }();
3303 return kind;
3304}
Kind kind

References j, and kind.

◆ decode_attention_tiles()

void decode_attention_tiles ( int *  min_chunk,
int *  max_chunks 
)

Definition at line 3306 of file cuda_kernels.cu.

3306 {
3307 static const std::pair<int, int> t = [] {
3309 const char* e = std::getenv("EMBER_DECODE_ATTN_TILE");
3310 int a = 0, b = 0;
3311 if (e && std::sscanf(e, "%d,%d", &a, &b) == 2 && a >= 1 && b >= 1 && b <= ember_tiled::kTiledMaxChunks)
3312 d = {a, b};
3313 return d;
3314 }();
3315 *min_chunk = t.first;
3316 *max_chunks = t.second;
3317}
constexpr int kTiledMaxChunks
constexpr int kTiledMinChunk

References a, j, ember_tiled::kTiledMaxChunks, and ember_tiled::kTiledMinChunk.

◆ decode_embed_cuda()

void decode_embed_cuda ( const float *  table_dev,
float *  out_dev,
const int *  step_dev,
int  hidden_size,
int  vocab_size,
cudaStream_t  stream 
)

Definition at line 3541 of file cuda_kernels.cu.

3542 {
3543 decode_embed_kernel<<<(hidden_size + 255) / 256, 256, 0, stream>>>(table_dev, out_dev, step_dev, hidden_size,
3544 vocab_size);
3546}
__global__ void decode_embed_kernel(const float *__restrict__ table, float *__restrict__ out, const int *__restrict__ step_dev, int hidden_size, int vocab_size)

References decode_embed_kernel(), and j.

◆ decode_embed_kernel()

__global__ void decode_embed_kernel ( const float *__restrict__  table,
float *__restrict__  out,
const int *__restrict__  step_dev,
int  hidden_size,
int  vocab_size 
)

Definition at line 3533 of file cuda_kernels.cu.

3534 {
3535 const int i = blockIdx.x * blockDim.x + threadIdx.x;
3536 if (i >= hidden_size) return;
3537 const int tok = step_dev[0];
3538 out[i] = (tok >= 0 && tok < vocab_size) ? table[(size_t)tok * hidden_size + i] : 0.0f;
3539}
Tok tok

References j, out, and tok.

Referenced by decode_embed_cuda().

◆ float32_to_bf16_device()

__device__ uint16_t float32_to_bf16_device ( float  fp32_val)
inline

Definition at line 118 of file cuda_kernels.cu.

118 {
119#if __CUDA_ARCH__ >= 800
122 memcpy(&bf16_raw, &bf16_val, sizeof(uint16_t));
123 return bf16_raw;
124#else
125 // Manual conversion for older architectures
126 unsigned int bits;
127 memcpy(&bits, &fp32_val, sizeof(float));
128 // Extract upper 16 bits for BF16
129 return (uint16_t)(bits >> 16);
130#endif
131}

References j.

Referenced by convert_fp32_to_bf16_kernel().

◆ gemm_bf16_bf16_cuda()

void gemm_bf16_bf16_cuda ( cublasHandle_t  handle,
bool  transa_user,
bool  transb_user,
int  m_user,
int  n_user,
int  k_user,
const float *  alpha_user,
const uint16_t *  A_bf16_user,
int  lda_user,
const uint16_t *  B_bf16_user,
int  ldb_user,
const float *  beta_user,
uint16_t *  C_bf16_user,
int  ldc_user,
cudaStream_t  stream 
)

Definition at line 3369 of file cuda_kernels.cu.

3377 {
3378
3381 Logger::error("cublasSetStream failed in gemm_bf16_bf16_cuda with error: " + std::to_string(status));
3382 throw std::runtime_error("cublasSetStream failed");
3383 }
3384
3385 // Log parameters for debugging
3386 Logger::info("[GEMM_BF16_BF16] M=" + std::to_string(m_user) + ", N=" + std::to_string(n_user) +
3387 ", K=" + std::to_string(k_user) + ", LDA=" + std::to_string(lda_user) +
3388 ", LDB=" + std::to_string(ldb_user) + ", LDC=" + std::to_string(ldc_user));
3389
3394
3395 // Apply the same column-major transformation as gemm_f32_f32_cuda
3396 M_cublas = n_user;
3397 N_cublas = m_user;
3398 K_cublas = k_user;
3399
3400 A_cublas_ptr = B_bf16_user; // B_user data is the first matrix for cuBLAS call
3402
3403 B_cublas_ptr = A_bf16_user; // A_user data is the second matrix for cuBLAS call
3405
3406 // Determine cuBLAS operations
3407 if (!transa_user && !transb_user) {
3408 opA_cublas = CUBLAS_OP_N; // for B_user
3409 opB_cublas = CUBLAS_OP_N; // for A_user
3410 } else if (transa_user && !transb_user) {
3411 opA_cublas = CUBLAS_OP_N; // for B_user
3412 opB_cublas = CUBLAS_OP_T; // for A_user (A^T)
3413 } else if (!transa_user && transb_user) {
3414 opA_cublas = CUBLAS_OP_T; // for B_user (B^T)
3415 opB_cublas = CUBLAS_OP_N; // for A_user
3416 } else { // transa_user && transb_user
3417 opA_cublas = CUBLAS_OP_T; // for B_user (B^T)
3418 opB_cublas = CUBLAS_OP_T; // for A_user (A^T)
3419 }
3420
3421 int LDC_cublas = ldc_user;
3422
3423 // Use cublasGemmEx with BF16 Tensor Cores
3427 alpha_user,
3430 beta_user,
3432 CUBLAS_COMPUTE_32F, // Use FP32 for accumulation for stability
3433 CUBLAS_GEMM_DEFAULT_TENSOR_OP); // Enable Tensor Cores
3434
3436 Logger::error("cublasGemmEx BF16 failed in gemm_bf16_bf16_cuda with error: " + std::to_string(status));
3437 Logger::error("GEMM params: transa=" + std::to_string(transa_user) + " transb=" + std::to_string(transb_user) +
3438 " m=" + std::to_string(m_user) + " n=" + std::to_string(n_user) + " k=" + std::to_string(k_user));
3439 throw std::runtime_error("cublasGemmEx BF16 failed");
3440 }
3441
3442 Logger::info("[GEMM_BF16_BF16] SUCCESS with Tensor Cores");
3443}
static void error(const std::string &message)
Definition logger.cpp:143

References Logger::error(), Logger::info(), and j.

◆ gemm_f32_to_bf16_f32_cuda()

void gemm_f32_to_bf16_f32_cuda ( cublasHandle_t  handle,
bool  transa_user,
bool  transb_user,
int  m_user,
int  n_user,
int  k_user,
const float *  alpha_user,
const float *  A_f32_user,
int  lda_user,
const uint16_t *  B_bf16_user,
int  ldb_user,
const float *  beta_user,
float *  C_f32_user,
int  ldc_user,
cudaStream_t  stream 
)

Definition at line 3446 of file cuda_kernels.cu.

3454 {
3455
3458 Logger::error("cublasSetStream failed in gemm_f32_to_bf16_f32_cuda with error: " + std::to_string(stream_status));
3459 throw std::runtime_error("cublasSetStream failed");
3460 }
3461
3462 // Convert FP32 input A to BF16
3463 size_t A_size = (size_t)m_user * k_user;
3467
3468 // Allocate BF16 output buffer
3469 size_t C_size = (size_t)m_user * n_user;
3472
3473 // Convert alpha and beta to BF16 for host-side pointers
3476
3477 // DIRECT parameter mapping for cublasGemmEx
3480
3481 // A is A_bf16_temp (converted from A_f32_user)
3482 // B is B_bf16_user (already BF16)
3483 // C is C_bf16_temp (will be converted back to C_f32_user)
3485 opA, opB,
3486 m_user, n_user, k_user,
3487 &alpha_bf16_host, // Pointer to BF16 host alpha
3490 &beta_bf16_host, // Pointer to BF16 host beta
3492 CUBLAS_COMPUTE_16F, // Compute in BF16 (A_16*B_16 -> C_16)
3494 );
3495
3497 Logger::error("cublasGemmEx BF16 (A_bf16*B_bf16->C_bf16) failed in gemm_f32_to_bf16_f32_cuda with error: " + std::to_string(status));
3498 Logger::error("GEMM params: transA=" + std::to_string(opA) + " transB=" + std::to_string(opB) +
3499 " m=" + std::to_string(m_user) + " n=" + std::to_string(n_user) + " k=" + std::to_string(k_user) +
3500 " lda=" + std::to_string(lda_user) + " ldb=" + std::to_string(ldb_user) + " ldc=" + std::to_string(ldc_user));
3503 throw std::runtime_error("BF16 Tensor Core GEMM failed");
3504 }
3505
3506 // Convert BF16 result back to FP32
3508
3509 // Cleanup temporary buffers
3512}
void convert_fp32_to_bf16_cuda(const float *fp32_in_dev, uint16_t *bf16_out_dev, size_t n_elements, cudaStream_t stream)
void convert_bf16_to_fp32_cuda(const uint16_t *bf16_in_dev, float *fp32_out_dev, size_t n_elements, cudaStream_t stream)

References convert_bf16_to_fp32_cuda(), convert_fp32_to_bf16_cuda(), Logger::error(), and j.

◆ gemm_rm_f32_cuda()

void gemm_rm_f32_cuda ( cublasHandle_t  handle,
const float *  X,
const float *  W,
float *  Y,
int  T,
int  O,
int  I,
cudaStream_t  stream 
)

Definition at line 3759 of file cuda_kernels.cu.

3760 {
3762 moe_gemm_rm(handle, X, W, Y, T, O, I);
3763}

References j.

◆ kernel_debug_copies()

static bool kernel_debug_copies ( )
static

Definition at line 64 of file cuda_kernels.cu.

64 {
65 static const bool on = std::getenv("EMBER_KERNEL_DEBUG") != nullptr;
66 return on;
67}

References j.

Referenced by add_residual_batch_cuda(), rope_batch_cuda(), and swiglu_batch_cuda().

◆ kv_write_devpos_cuda()

void kv_write_devpos_cuda ( float *  k_cache_dev,
float *  v_cache_dev,
const float *  k_dev,
const float *  v_dev,
const int *  step_dev,
int  row,
cudaStream_t  stream 
)

Definition at line 3593 of file cuda_kernels.cu.

3594 {
3596 row);
3598}
__global__ void kv_write_devpos_kernel(float *k_cache, float *v_cache, const float *__restrict__ k, const float *__restrict__ v, const int *step_dev, int row)

References j, and kv_write_devpos_kernel().

◆ kv_write_devpos_kernel()

__global__ void kv_write_devpos_kernel ( float *  k_cache,
float *  v_cache,
const float *__restrict__  k,
const float *__restrict__  v,
const int *  step_dev,
int  row 
)

Definition at line 3584 of file cuda_kernels.cu.

3585 {
3586 const int i = blockIdx.x * blockDim.x + threadIdx.x;
3587 if (i >= row) return;
3588 const size_t off = (size_t)step_dev[1] * row + i;
3589 k_cache[off] = k[i];
3590 v_cache[off] = v[i];
3591}
std::vector< float > v

References j, k, off, and v.

Referenced by kv_write_devpos_cuda().

◆ lookup_embedding_cuda()

void lookup_embedding_cuda ( const void *  table_dev,
float *  output_dev,
int  token_id,
int  hidden_size,
int  vocab_size,
bool  is_bf16,
cudaStream_t  stream 
)

Definition at line 1474 of file cuda_kernels.cu.

1476 {
1477 if (!table_dev || !output_dev) {
1478 Logger::error("lookup_embedding_cuda: Received null device pointer(s).");
1479
1480 return;
1481 }
1482 if (hidden_size <= 0 || vocab_size <= 0) {
1483 Logger::error("lookup_embedding_cuda: Invalid hidden_size or vocab_size.");
1484 return;
1485 }
1486
1487 int threads_per_block = 256;
1488
1489 int blocks_per_grid =
1490 (hidden_size + threads_per_block - 1) / threads_per_block;
1491
1493 table_dev, output_dev, token_id, hidden_size, vocab_size, is_bf16);
1494
1496}
int token_id(const std::vector< std::string > &tokens, const std::string &text)

References Logger::error(), and j.

◆ lookup_embedding_kernel()

__global__ void lookup_embedding_kernel ( const void *__restrict__  table_dev,
float *__restrict__  output_dev,
int  token_id,
int  hidden_size,
int  vocab_size,
bool  is_bf16 
)

Definition at line 1445 of file cuda_kernels.cu.

1448 {
1449 int idx = blockIdx.x * blockDim.x + threadIdx.x;
1450
1451 if (idx >= hidden_size) {
1452 return;
1453 }
1454
1455 if (token_id < 0 || token_id >= vocab_size) {
1456 output_dev[idx] = 0.0f;
1457 return;
1458 }
1459 size_t offset = (size_t)token_id * hidden_size + idx;
1460
1461 if (is_bf16) {
1462 const uint16_t* table_bf16 = static_cast<const uint16_t*>(table_dev);
1463
1464 uint16_t val_bf16 = table_bf16[offset];
1465
1467 } else {
1468 const float* table_f32 = static_cast<const float*>(table_dev);
1469
1470 output_dev[idx] = table_f32[offset];
1471 }
1472}

References bf16_to_float32_device(), and j.

◆ matvec_bf16_f32_cuda()

void matvec_bf16_f32_cuda ( cublasHandle_t  handle,
const uint16_t *  mat_bf16_dev,
const float *  vec_f32_dev,
float *  out_f32_dev,
int  rows,
int  cols,
bool  use_tensor_cores,
cudaStream_t  stream 
)

Matrix-vector multiplication with BF16 matrix and FP32 vector/output on GPU.

This function performs matrix-vector multiplication (mat * vec = out) where the matrix is in BF16 format, and the vector and output are in FP32 format. It can use BF16 Tensor Cores via cublasGemmEx if supported and enabled. Otherwise, it falls back to converting the BF16 matrix to FP32 and then using cublasSgemm.

Matrix 'mat_bf16_dev' is assumed to be in row-major format with 'rows' rows and 'cols' columns. Vector 'vec_f32_dev' is assumed to have 'cols' elements. Output 'out_f32_dev' will have 'rows' elements.

Parameters
handlecuBLAS handle
mat_bf16_devBF16 matrix (device pointer, row-major, rows x cols)
vec_f32_devFP32 vector (device pointer, cols elements)
out_f32_devFP32 output vector (device pointer, rows elements)
rowsNumber of matrix rows
colsNumber of matrix columns
use_tensor_coresWhether to attempt using BF16 Tensor Cores with cublasGemmEx
streamCUDA stream (optional)

Definition at line 353 of file cuda_kernels.cu.

358 {
360 const float alpha = 1.0f;
361 const float beta = 0.0f;
362
363 // For C = A * B (row-major view) where A is mat_bf16_dev (rows x cols) and B is vec_f32_dev (cols x 1)
364 // cuBLAS expects column-major. We use A^T for op(A) to simulate row-major A.
365 // M_blas = rows (rows of C, rows of op(A))
366 // N_blas = 1 (cols of C, cols of op(B))
367 // K_blas = cols (cols of op(A), rows of op(B))
368 //
369 // If op(A) is CUBLAS_OP_T, then A is passed as K_blas x M_blas (cols x rows) column-major. LDA = K_blas = cols.
370 // If op(B) is CUBLAS_OP_N, then B is passed as K_blas x N_blas (cols x 1) column-major. LDB = K_blas = cols.
371 // C is M_blas x N_blas (rows x 1) column-major. LDC = M_blas = rows.
372
373 // Disable Tensor Cores for matrix-vector operations (N=1) as they are not supported
374 // by cublasGemmEx with mixed precision BF16->FP32 (confirmed by standalone test)
375 if (use_tensor_cores) {
376 Logger::info("[CUDA_KERNEL] matvec_bf16_f32_cuda: Tensor Cores requested, but disabling for matrix-vector (N=1) operation. Mixed precision BF16->FP32 with N=1 returns CUBLAS_STATUS_NOT_SUPPORTED in cublasGemmEx.");
377 use_tensor_cores = false;
378 }
379
380 if (use_tensor_cores) {
381 // Set the cuBLAS stream explicitly
384 Logger::warning("[CUDA_KERNEL] cublasSetStream failed with status: " + std::to_string(stream_status) + ". Falling back to FP32 Sgemm.");
385 use_tensor_cores = false;
386 } else {
387 // Logger::debug("[CUDA_KERNEL] matvec_bf16_f32_cuda attempting cublasGemmEx with Tensor Cores.");
388 // Log all parameters for debugging
389 Logger::info("[CUDA_KERNEL] cublasGemmEx parameters: M=" + std::to_string(rows) +
390 ", N=1, K=" + std::to_string(cols) +
391 ", LDA=" + std::to_string(cols) +
392 ", LDB=" + std::to_string(cols) +
393 ", LDC=" + std::to_string(rows) +
394 ", mat_ptr=" + std::to_string(reinterpret_cast<uintptr_t>(mat_bf16_dev)) +
395 ", vec_ptr=" + std::to_string(reinterpret_cast<uintptr_t>(vec_f32_dev)) +
396 ", out_ptr=" + std::to_string(reinterpret_cast<uintptr_t>(out_f32_dev)));
397
398 // A is mat_bf16_dev (CUDA_R_16BF)
399 // B is vec_f32_dev (CUDA_R_32F)
400 // C is out_f32_dev (CUDA_R_32F)
401 // Computation type CUDA_R_32F
403 CUBLAS_OP_T, // Transpose A (mat_bf16_dev)
404 CUBLAS_OP_N, // No transpose B (vec_f32_dev)
405 rows, // M
406 1, // N
407 cols, // K
408 &alpha, // Alpha
409 mat_bf16_dev, // A
410 CUDA_R_16BF, // Atype
411 cols, // LDA (K_blas for A^T)
412 vec_f32_dev, // B
413 CUDA_R_32F, // Btype
414 cols, // LDB (K_blas for B_NoTrans)
415 &beta, // Beta
416 out_f32_dev, // C
417 CUDA_R_32F, // Ctype
418 rows, // LDC (M_blas)
419 CUBLAS_COMPUTE_32F, // Compute type (use FP32 for accumulation for stability with BF16 inputs)
420 // For pure BF16 compute (if B was also BF16), could use CUBLAS_COMPUTE_32F_FAST_16BF
421 // Or CUBLAS_GEMM_DEFAULT_TENSOR_OP for algo to let cuBLAS pick
422 CUBLAS_GEMM_DEFAULT_TENSOR_OP); // Algorithm
423 }
425 Logger::warning("[CUDA_KERNEL] cublasGemmEx with Tensor Cores failed for matvec_bf16_f32_cuda: " + std::to_string(status) + ". Falling back to FP32 Sgemm.");
426 // Fallback to FP32 path
427 use_tensor_cores = false; // Ensure fallback path is taken
428 } else {
429 // Logger::debug("[CUDA_KERNEL] cublasGemmEx with Tensor Cores SUCCEEDED for matvec_bf16_f32_cuda.");
431 return; // Success with Tensor Cores
432 }
433 }
434
435 // Fallback path: Convert BF16 matrix to FP32 and use cublasSgemm
436 if (!use_tensor_cores) {
437 // Logger::debug("[CUDA_KERNEL] matvec_bf16_f32_cuda using fallback: BF16->FP32 conversion then Sgemm.");
438 // Set the cuBLAS stream for fallback path too
441 throw std::runtime_error("cublasSetStream failed in matvec_bf16_f32_cuda fallback: " + std::to_string(stream_status));
442 }
443
444 float* mat_fp32_dev = nullptr;
445 size_t mat_size_elements = static_cast<size_t>(rows) * cols;
447
448 const int threads = 256;
449 const int blocks = (mat_size_elements + threads - 1) / threads;
452 // No explicit sync needed here if stream is managed correctly by caller or if Sgemm uses the same stream.
453
455 rows, 1, cols,
456 &alpha,
457 mat_fp32_dev, cols, // A (mat_fp32_dev), LDA = K_blas = cols
458 vec_f32_dev, cols, // B (vec_f32_dev), LDB = K_blas = cols
459 &beta,
460 out_f32_dev, rows); // C (out_f32_dev), LDC = M_blas = rows
461
464 throw std::runtime_error("cuBLAS Sgemm failed in matvec_bf16_f32_cuda fallback: " + std::to_string(status));
465 }
467 }
468}

References Logger::info(), j, and Logger::warning().

◆ matvec_f32_f32_cuda() [1/2]

void matvec_f32_f32_cuda ( cublasHandle_t  handle,
const float *  mat_f32_dev,
const float *  vec_f32_dev,
float *  out_f32_dev,
int  rows,
int  cols,
cudaStream_t  stream 
)

Implementation of matrix-vector multiplication with FP32.

This function performs matrix-vector multiplication using cuBLAS, optimized for FP32 precision. It handles the cuBLAS setup and error checking.

Parameters
handlecuBLAS handle
mat_f32_devMatrix in row-major format (device pointer)
vec_f32_devVector to multiply (device pointer)
out_f32_devOutput vector (device pointer)
rowsNumber of matrix rows
colsNumber of matrix columns
streamCUDA stream for asynchronous execution

Definition at line 306 of file cuda_kernels.cu.

308 {
309 // Existing implementation of matvec_f32_f32_cuda
310 // C = A^T * B where A is mat_f32_dev (passed as KxM) and B is vec_f32_dev (KxN)
311 // M_blas = rows, N_blas = 1, K_blas = cols
312 // A is mat_f32_dev, LDA = cols (K_blas)
313 // B is vec_f32_dev, LDB = cols (K_blas)
314 // C is out_f32_dev, LDC = rows (M_blas)
315 const float alpha = 1.0f;
316 const float beta = 0.0f;
318 rows, 1, cols,
319 &alpha,
322 &beta,
325 throw std::runtime_error("cuBLAS Sgemm failed in matvec_f32_f32_cuda: " +
326 std::to_string(status));
327 }
329}

References j.

Referenced by matvec_f32_f32_cuda().

◆ matvec_f32_f32_cuda() [2/2]

void matvec_f32_f32_cuda ( cublasHandle_t  handle,
const std::vector< float > &  mat_f32_host,
const std::vector< float > &  vec_f32_host,
std::vector< float > &  out_f32_host,
int  rows,
int  cols 
)

Definition at line 470 of file cuda_kernels.cu.

473 {
474 if (mat_f32_host.size() != (size_t)rows * cols) {
475 throw std::runtime_error(
476 "matvec_f32_f32_cuda (host/host/host): mat size mismatch.");
477 }
478 if (vec_f32_host.size() != (size_t)cols) {
479 throw std::runtime_error(
480 "matvec_f32_f32_cuda (host/host/host): vec size mismatch.");
481 }
482 out_f32_host.resize(rows);
483
484 float* mat_f32_dev = nullptr;
485 float* vec_f32_dev = nullptr;
486 float* out_f32_dev = nullptr;
487
488 gpuErrchk(cudaMalloc(&mat_f32_dev, mat_f32_host.size() * sizeof(float)));
489 gpuErrchk(cudaMalloc(&vec_f32_dev, vec_f32_host.size() * sizeof(float)));
490 gpuErrchk(cudaMalloc(&out_f32_dev, out_f32_host.size() * sizeof(float)));
491
493 mat_f32_host.size() * sizeof(float),
496 vec_f32_host.size() * sizeof(float),
498
500 0);
501
503
505 out_f32_host.size() * sizeof(float),
507
511}
void matvec_f32_f32_cuda(cublasHandle_t handle, const float *mat_f32_dev, const float *vec_f32_dev, float *out_f32_dev, int rows, int cols, cudaStream_t stream)
Implementation of matrix-vector multiplication with FP32.

References j, and matvec_f32_f32_cuda().

◆ moe_ffn_cuda()

void moe_ffn_cuda ( cublasHandle_t  handle,
const float *  x,
int  T,
int  d,
int  d_ff,
int  E,
int  k,
bool  renorm,
const float *  router,
const float *  gate_exps,
const float *  up_exps,
const float *  down_exps,
float *  scratch,
float *  out,
cudaStream_t  stream 
)

Definition at line 3770 of file cuda_kernels.cu.

3772 {
3773 if (moe_use_routed(T, k) && E <= 256 && k <= 64) {
3774 const int tk = T * k;
3775 const float** Ag = reinterpret_cast<const float**>(scratch);
3776 const float** Au = Ag + tk;
3777 const float** Ad = Au + tk;
3778 const float** Bx = Ad + tk;
3779 const float** Bg = Bx + tk;
3780 float** Cg = reinterpret_cast<float**>(scratch) + 5 * (size_t)tk;
3781 float** Cu = Cg + tk;
3782 float** Cy = Cu + tk;
3783 float* logits = reinterpret_cast<float*>(Cy + tk);
3784 float* gsel = logits + (size_t)T * E;
3785 float* g = gsel + tk;
3786 float* u = g + (size_t)tk * d_ff;
3787 float* y = u + (size_t)tk * d_ff;
3789 moe_gemm_rm(handle, x, router, logits, T, E, d);
3791 down_exps, gsel, g, u, y, Ag, Au, Ad, Bx, Bg, Cg, Cu, Cy);
3792 const float one = 1.0f, zero = 0.0f;
3793 // Each item: row-major [rows][cols] weight times a column vector (see moe_gemm_rm).
3794 if (cublasSgemmBatched(handle, CUBLAS_OP_T, CUBLAS_OP_N, d_ff, 1, d, &one, Ag, d, Bx, d, &zero, Cg, d_ff, tk) !=
3798 throw std::runtime_error("moe_ffn_cuda: cublasSgemmBatched failed");
3799 const size_t n = (size_t)tk * d_ff;
3800 moe_swiglu_kernel<<<(unsigned)((n + 255) / 256), 256, 0, stream>>>(g, u, n);
3803 throw std::runtime_error("moe_ffn_cuda: cublasSgemmBatched failed");
3806 return;
3807 }
3808 float* logits = scratch;
3809 float* gates = logits + (size_t)T * E;
3810 float* sel = gates + (size_t)T * E;
3811 float* g = sel + (size_t)T * E;
3812 float* u = g + (size_t)T * d_ff;
3813 float* y = u + (size_t)T * d_ff;
3815 moe_gemm_rm(handle, x, router, logits, T, E, d);
3817 const size_t n = (size_t)T * d_ff;
3818 for (int e = 0; e < E; ++e) {
3819 moe_gemm_rm(handle, x, gate_exps + (size_t)e * d_ff * d, g, T, d_ff, d);
3820 moe_gemm_rm(handle, x, up_exps + (size_t)e * d_ff * d, u, T, d_ff, d);
3821 moe_swiglu_kernel<<<(unsigned)((n + 255) / 256), 256, 0, stream>>>(g, u, n);
3822 moe_gemm_rm(handle, g, down_exps + (size_t)e * d * d_ff, y + (size_t)e * T * d, T, d, d_ff);
3823 }
3826}

References j, k, n, and out.

◆ moe_ffn_scratch_floats()

size_t moe_ffn_scratch_floats ( int  T,
int  d,
int  d_ff,
int  E,
int  k 
)

Definition at line 3765 of file cuda_kernels.cu.

3765 {
3766 const size_t dense = (size_t)T * E * 3 + (size_t)T * d_ff * 2 + (size_t)E * T * d;
3767 return std::max(dense, moe_routed_floats(T, d, d_ff, E, k));
3768}

References j, and k.

◆ reduce_partial_sums_kernel()

__global__ void reduce_partial_sums_kernel ( const float *  partial_sums,
float *  total_sum_sq_out,
int  num_partial_sums 
)

Definition at line 185 of file cuda_kernels.cu.

185 {
186 extern __shared__ float sdata[];
187 unsigned int tid = threadIdx.x;
188
189 float my_sum = 0.0f;
190 for (unsigned int i = tid; i < num_partial_sums; i += blockDim.x) {
192 }
193 sdata[tid] = my_sum;
195
196 // Standard parallel reduction in shared memory
197 for (unsigned int s = blockDim.x / 2; s > 0; s >>= 1) {
198 if (tid < s) {
199 sdata[tid] += sdata[tid + s];
200 }
202 }
203
204 if (tid == 0) {
205 total_sum_sq_out[0] = sdata[0];
206 }
207}

References j.

Referenced by rmsnorm_vector_cuda().

◆ rmsnorm_apply_kernel()

__global__ void rmsnorm_apply_kernel ( const float *  x,
const float *  weight,
float *  out,
int  n,
float  inv_norm_factor 
)

Kernel for applying RMS normalization.

This kernel applies the normalization weights and scaling factor to the input tensor. It's the second step in RMS normalization.

Parameters
xInput tensor
weightNormalization weights
outOutput tensor
nSize of tensors
inv_norm_factorInverse of the normalization factor

Definition at line 177 of file cuda_kernels.cu.

178 {
179 int i = blockIdx.x * blockDim.x + threadIdx.x;
180 if (i < n) {
181 out[i] = x[i] * inv_norm_factor * weight[i];
182 }
183}

References j, n, and out.

◆ rmsnorm_optimized_det_kernel()

__global__ void rmsnorm_optimized_det_kernel ( const float *__restrict__  x,
const float *__restrict__  weight,
float *__restrict__  out,
int  n,
float  eps 
)

Definition at line 2945 of file cuda_kernels.cu.

2948 {
2949 const int tid_global = threadIdx.x + blockIdx.x * blockDim.x;
2950 const int tid_block = threadIdx.x;
2951
2952 __shared__ float s_warp_sum_sq[32];
2954
2955 float thread_partial_sum_sq = 0.0f;
2956 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2957 float val = x[i];
2959 }
2960
2961 // Reduce within warp
2962 for (int offset = warpSize / 2; offset > 0; offset >>= 1) {
2964 }
2965
2966 // Warp leaders store their sums; thread 0 adds them in warp order
2967 if ((tid_block % warpSize) == 0) {
2969 }
2970 __syncthreads();
2971 if (tid_block == 0) {
2972 const int num_warps = (blockDim.x + warpSize - 1) / warpSize;
2973 float total = 0.0f;
2974 for (int w = 0; w < num_warps; ++w) total += s_warp_sum_sq[w];
2976 }
2977 __syncthreads();
2978
2980 float rms_scale = rsqrtf(total_sum_sq / n + eps);
2981
2982 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2983 out[i] = x[i] * weight[i] * rms_scale;
2984 }
2985}

References j, n, and out.

◆ rmsnorm_optimized_kernel()

__global__ void rmsnorm_optimized_kernel ( const float *__restrict__  x,
const float *__restrict__  weight,
float *__restrict__  out,
int  n,
float  eps 
)

Optimized RMS normalization using simple warp primitives and shared memory.

This kernel uses warp-level reductions and a shared memory variable for block-wide sum.

Definition at line 2738 of file cuda_kernels.cu.

2741 {
2742 const int tid_global = threadIdx.x + blockIdx.x * blockDim.x;
2743 const int tid_block = threadIdx.x;
2744
2746
2747 if (tid_block == 0) {
2748 s_block_sum_sq = 0.0f;
2749 }
2750 __syncthreads();
2751
2752 float thread_partial_sum_sq = 0.0f;
2753 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2754 float val = x[i];
2756 }
2757
2758 // Reduce within warp
2759 for (int offset = warpSize / 2; offset > 0; offset >>= 1) {
2761 }
2762
2763 // Warp leaders add to shared memory sum
2764 if ((tid_block % warpSize) == 0) {
2766 }
2767 __syncthreads(); // Ensure all warps have added their sums
2768
2770 float rms_scale = rsqrtf(total_sum_sq / n + eps);
2771
2772 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2773 out[i] = x[i] * weight[i] * rms_scale;
2774 }
2775}

References j, n, and out.

Referenced by rmsnorm_vector_cuda_optimized().

◆ rmsnorm_sum_squares_kernel()

__global__ void rmsnorm_sum_squares_kernel ( const float *  x,
float *  partial_sums,
int  n 
)

Kernel for computing sum of squares in RMS normalization.

This kernel computes the sum of squares of input elements using parallel reduction with shared memory. It's the first step in RMS normalization.

Parameters
xInput tensor
partial_sumsOutput array for partial sums
nSize of input tensor

Definition at line 143 of file cuda_kernels.cu.

144 {
145 extern __shared__ float sdata[];
146
147 unsigned int tid = threadIdx.x;
148 unsigned int i = blockIdx.x * blockDim.x + threadIdx.x;
149
150 sdata[tid] = (i < n) ? x[i] * x[i] : 0.0f;
152
153 for (unsigned int s = blockDim.x / 2; s > 0; s >>= 1) {
154 if (tid < s) {
155 sdata[tid] += sdata[tid + s];
156 }
158 }
159
160 if (tid == 0) {
162 }
163}

References j, and n.

Referenced by rmsnorm_vector_cuda().

◆ rmsnorm_vector_cuda() [1/2]

void rmsnorm_vector_cuda ( const float *  x_dev,
const float *  weight_dev,
float *  out_dev,
int  n,
float  eps,
cudaStream_t  stream 
)

Implementation of RMS normalization with device pointers.

This function implements the complete RMS normalization process:

  1. Computes sum of squares using parallel reduction
  2. Calculates normalization factor
  3. Applies normalization with weights
Parameters
x_devInput tensor (device pointer)
weight_devNormalization weights (device pointer)
out_devOutput tensor (device pointer)
nSize of tensors
epsEpsilon for numerical stability
streamCUDA stream for asynchronous execution

Definition at line 224 of file cuda_kernels.cu.

226 {
227 const int threads_per_block = 256; // General purpose threads per block
230
231 float* partial_sums_dev = nullptr;
233
238
239 float* total_sum_sq_dev = nullptr;
240 gpuErrchk(cudaMalloc(&total_sum_sq_dev, sizeof(float)));
241
242 const int threads_for_final_reduction = (num_blocks_reduce_pass1 <= 256) ? 256 :
243 (num_blocks_reduce_pass1 <= 512) ? 512 : 1024;
244 // Cap at 1024, ensure kernel handles num_partial_sums correctly if it's less than blockDim.x
246
247 // Launch a single block for the final reduction of partial_sums_dev
252 gpuErrchk(cudaFree(partial_sums_dev)); // Free intermediate partial sums
253
254 float h_total_ssq = 0.0f;
257 gpuErrchk(cudaStreamSynchronize(stream)); // Ensure h_total_ssq is ready
259
260 double total_ssq_double = static_cast<double>(h_total_ssq);
262 float inv_norm_factor = 1.0f / SAFE_SQRT(static_cast<float>(total_ssq_double) + eps);
263
268}
#define SAFE_SQRT(x)
__global__ void rmsnorm_sum_squares_kernel(const float *x, float *partial_sums, int n)
Kernel for computing sum of squares in RMS normalization.
__global__ void reduce_partial_sums_kernel(const float *partial_sums, float *total_sum_sq_out, int num_partial_sums)

References j, n, reduce_partial_sums_kernel(), rmsnorm_sum_squares_kernel(), and SAFE_SQRT.

Referenced by rmsnorm_vector_cuda().

◆ rmsnorm_vector_cuda() [2/2]

void rmsnorm_vector_cuda ( const std::vector< float > &  x_in_host,
const std::vector< float > &  weight_host,
std::vector< float > &  out_host,
int  n,
float  eps 
)

Definition at line 270 of file cuda_kernels.cu.

272 {
273 out_host.resize(n);
274 float *x_dev = nullptr, *weight_dev = nullptr, *out_dev = nullptr;
275 gpuErrchk(cudaMalloc(&x_dev, n * sizeof(float)));
276 gpuErrchk(cudaMalloc(&weight_dev, n * sizeof(float)));
277 gpuErrchk(cudaMalloc(&out_dev, n * sizeof(float)));
278 gpuErrchk(cudaMemcpy(x_dev, x_in_host.data(), n * sizeof(float),
280 gpuErrchk(cudaMemcpy(weight_dev, weight_host.data(), n * sizeof(float),
284 gpuErrchk(cudaMemcpy(out_host.data(), out_dev, n * sizeof(float),
289}
void rmsnorm_vector_cuda(const float *x_dev, const float *weight_dev, float *out_dev, int n, float eps, cudaStream_t stream)
Implementation of RMS normalization with device pointers.

References j, n, and rmsnorm_vector_cuda().

◆ rmsnorm_vector_cuda_optimized()

void rmsnorm_vector_cuda_optimized ( const float *  x_dev,
const float *  weight_dev,
float *  out_dev,
int  n,
float  eps,
cudaStream_t  stream 
)

Optimized wrappers using the new high-performance kernels.

Definition at line 3082 of file cuda_kernels.cu.

3084 {
3085 if (n <= 0) return;
3086 const int block_size = 256;
3087 // Ensure grid_size is 1 as the kernel is designed for block-wide reduction.
3088 const int grid_size = 1;
3089 if (ember::deterministic()) {
3092 return;
3093 }
3097}
__global__ void rmsnorm_optimized_kernel(const float *__restrict__ x, const float *__restrict__ weight, float *__restrict__ out, int n, float eps)
Optimized RMS normalization using simple warp primitives and shared memory.

References ember::deterministic(), j, n, and rmsnorm_optimized_kernel().

◆ rope_and_update_kv_cache_cuda()

void rope_and_update_kv_cache_cuda ( float *  cache_base_ptr,
const float *  kv_vector_head,
const float *  all_freqs_cis_base,
int  pos,
int  kv_head_idx,
int  max_seq_len,
int  num_kv_heads,
int  head_dim,
cudaStream_t  stream 
)

Definition at line 1412 of file cuda_kernels.cu.

1417 {
1418 if (head_dim % 2 != 0) {
1419 Logger::error("rope_and_update_kv_cache_cuda: head_dim must be even.");
1420 return;
1421 }
1423 Logger::error("rope_and_update_kv_cache_cuda: pos out of bounds.");
1424 return;
1425 }
1427 Logger::error("rope_and_update_kv_cache_cuda: kv_head_idx out of bounds.");
1428 return;
1429 }
1432 "rope_and_update_kv_cache_cuda: Received null device pointer(s).");
1433 return;
1434 }
1435
1436 int threads_per_block = 128;
1438
1443}

References Logger::error(), j, and pos.

◆ rope_and_update_kv_cache_kernel()

__global__ void rope_and_update_kv_cache_kernel ( float *  cache_base_ptr,
const float *  kv_vector_head,
const float *  all_freqs_cis_base,
int  pos,
int  kv_head_idx,
int  max_seq_len,
int  num_kv_heads,
int  head_dim 
)

Definition at line 1376 of file cuda_kernels.cu.

1380 {
1381 int pair_idx = blockIdx.x * blockDim.x + threadIdx.x;
1382 int dim_half = head_dim / 2;
1383
1384 if (pair_idx >= dim_half) return;
1385
1386 int idx0 = pair_idx;
1387 int idx1 = pair_idx + dim_half;
1388 float kv0 = kv_vector_head[idx0];
1389 float kv1 = kv_vector_head[idx1];
1390
1391 size_t freq_base_offset = (size_t)pos * head_dim + (size_t)pair_idx * 2;
1394
1395 float kv0_rotated = kv0 * cos_val - kv1 * sin_val;
1396 float kv1_rotated = kv0 * sin_val + kv1 * cos_val;
1397
1399 (size_t)kv_head_idx * head_dim + idx0;
1401
1405 return;
1406 }
1407
1410}

References j, and pos.

◆ rope_batch_cuda()

void rope_batch_cuda ( float *  d_q_batch,
float *  d_k_batch,
const float *  d_all_freqs_cis_base,
int  num_tokens,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
int  start_pos_in_kv_cache,
bool  use_adjacent_pairing,
cudaStream_t  stream 
)

Definition at line 872 of file cuda_kernels.cu.

877 {
878
879
880 if (head_dim == 0) {
881 Logger::warning("[ROPE_BATCH_CUDA_SKIP] head_dim is 0. Skipping RoPE application.");
882 return;
883 }
884 if (head_dim % 2 != 0) {
885 Logger::error("rope_batch_cuda: head_dim must be even. Got " + std::to_string(head_dim));
886 Logger::info("[ROPE_BATCH_CUDA_EXIT] Error: head_dim not even.");
887 return;
888 }
889 if (num_tokens == 0) {
890 Logger::info("[ROPE_BATCH_CUDA_EXIT] num_tokens is 0. Nothing to process.");
891 return; // Nothing to process
892 }
893
894 int log_count_elements = std::min(3, head_dim);
895
896 // Log initial Q values
897 if (d_q_batch && num_q_heads > 0 && head_dim > 0) {
898 for (int token_to_log_idx = 0; token_to_log_idx < std::min(num_tokens, 2); ++token_to_log_idx) {
899 std::vector<float> h_q_sample_before(log_count_elements);
901
904 log_count_elements * sizeof(float),
906 }
907 }
908
909 // Log initial K values
910 if (d_k_batch && num_kv_heads > 0 && head_dim > 0) {
911 for (int token_to_log_idx = 0; token_to_log_idx < std::min(num_tokens, 2); ++token_to_log_idx) {
912 std::vector<float> h_k_sample_before(log_count_elements);
914
917 log_count_elements * sizeof(float),
919 }
920 }
921
923
924 // Apply RoPE to Q batch
925 if (d_q_batch && num_q_heads > 0) {
928 d_q_batch,
931 head_dim,
935 );
937 }
938
939 // Apply RoPE to K batch
940 if (d_k_batch && num_kv_heads > 0) {
943 d_k_batch,
946 head_dim,
950 );
952 }
953
954 // Log Q values after RoPE
955 if (d_q_batch && num_q_heads > 0 && head_dim > 0) {
956 for (int token_to_log_idx = 0; token_to_log_idx < std::min(num_tokens, 2); ++token_to_log_idx) {
957 std::vector<float> h_q_sample_after(log_count_elements);
959
962 log_count_elements * sizeof(float),
964 }
965 }
966
967 // Log K values after RoPE
968 if (d_k_batch && num_kv_heads > 0 && head_dim > 0) {
969 for (int token_to_log_idx = 0; token_to_log_idx < std::min(num_tokens, 2); ++token_to_log_idx) {
970 std::vector<float> h_k_sample_after(log_count_elements);
972
975 log_count_elements * sizeof(float),
977 }
978 }
979}

References Logger::error(), Logger::info(), j, kernel_debug_copies(), and Logger::warning().

◆ rope_batch_kernel_cuda()

__global__ void rope_batch_kernel_cuda ( float *  x_batch_tensor,
int  num_tokens,
int  num_heads_in_tensor,
int  head_dim,
const float *  d_all_freqs_cis_base,
int  start_pos_offset,
bool  use_adjacent_pairing 
)

Definition at line 812 of file cuda_kernels.cu.

819 {
820
821 // Grid: dim3 grid_dim(num_tokens, num_heads_in_tensor);
822 // Block: dim3 block_dim(head_dim / 2);
823 int pair_within_head_idx = threadIdx.x; // Thread index within the block (0 to head_dim/2 - 1)
824 int head_idx = blockIdx.y; // Block index in Y dimension maps to head index
825 int token_idx = blockIdx.x; // Block index in X dimension maps to token index within the batch
826
827 // Boundary checks
828 if (pair_within_head_idx >= (head_dim / 2) ||
831 return;
832 }
833
834 // Determine the actual sequence position for RoPE for the current token
836
837 // Fetch cos and sin values from the precomputed table
838 // d_all_freqs_cis_base is effectively [max_seq_len][head_dim/2][2]
839 // Access: (pos * (head_dim/2) + pair_idx_in_head) * 2 for cos, and +1 for sin
843
844 // Calculate base pointer to the current token's data in x_batch_tensor
845 // x_batch_tensor is [num_tokens][num_heads_in_tensor][head_dim]
847 // Pointer to the start of the current head's data for this token
849
852 // Adjacent pairing: (x_0, x_1), (x_2, x_3), ... for a head
853 // pair_within_head_idx = 0 maps to (x_0, x_1), pair_within_head_idx = 1 maps to (x_2, x_3)
856 } else {
857 // Split-half pairing: (x_0, x_{D/2}), (x_1, x_{D/2+1}), ... for a head
858 // pair_within_head_idx = 0 maps to (x_0, x_{D/2}), pair_within_head_idx = 1 maps to (x_1, x_{D/2+1})
861 }
862
865
866
869}

References j.

◆ rope_cuda()

void rope_cuda ( float *  x_dev,
int  num_heads,
int  head_dim,
const float *  all_freqs_cis_dev_base,
int  pos,
bool  use_adjacent_pairing,
cudaStream_t  stream 
)

◆ rope_devpos_cuda()

void rope_devpos_cuda ( float *  x_dev,
int  num_heads,
int  head_dim,
const float *  all_freqs_cis_dev_base,
const int *  step_dev,
bool  use_adjacent_pairing,
cudaStream_t  stream 
)

Definition at line 3573 of file cuda_kernels.cu.

3574 {
3575 const int total_pairs = num_heads * (head_dim / 2);
3576 rope_devpos_kernel<<<(total_pairs + 255) / 256, 256, 0, stream>>>(x_dev, num_heads, head_dim,
3580}
__global__ void rope_devpos_kernel(float *x, int num_heads, int head_dim, const float *all_freqs_cis_base, const int *step_dev, bool use_adjacent_pairing)

References j, and rope_devpos_kernel().

◆ rope_devpos_kernel()

__global__ void rope_devpos_kernel ( float *  x,
int  num_heads,
int  head_dim,
const float *  all_freqs_cis_base,
const int *  step_dev,
bool  use_adjacent_pairing 
)

Definition at line 3548 of file cuda_kernels.cu.

3549 {
3550 const int idx = blockIdx.x * blockDim.x + threadIdx.x;
3551 const int total_pairs = num_heads * (head_dim / 2);
3552 if (idx >= total_pairs) return;
3553 const int pos = step_dev[1];
3554 const int head_idx = idx / (head_dim / 2);
3555 const int dim_pair_idx = idx % (head_dim / 2);
3556 const size_t freq_base_offset = ((size_t)pos * (head_dim / 2) + dim_pair_idx) * 2;
3557 int base_x0, base_x1;
3560 base_x1 = head_idx * head_dim + (dim_pair_idx * 2 + 1);
3561 } else {
3564 }
3565 const float x0 = x[base_x0];
3566 const float x1 = x[base_x1];
3568 const float sin_val = all_freqs_cis_base[freq_base_offset + 1];
3569 x[base_x0] = x0 * cos_val - x1 * sin_val;
3570 x[base_x1] = x0 * sin_val + x1 * cos_val;
3571}

References j, and pos.

Referenced by rope_devpos_cuda().

◆ rope_kernel()

__global__ void rope_kernel ( float *  x,
int  num_heads,
int  head_dim,
const float *  all_freqs_cis_base,
int  pos,
bool  use_adjacent_pairing 
)

Definition at line 767 of file cuda_kernels.cu.

768 {
769 int idx = blockIdx.x * blockDim.x + threadIdx.x; // Global thread index for pairs
770 int total_pairs = num_heads * (head_dim / 2); // Total (dim_i, dim_{i+1}) or (dim_i, dim_{i+D/2}) pairs across all heads
771 if (idx >= total_pairs) return;
772
773 int head_idx = idx / (head_dim / 2); // The specific head this thread works on
774 int dim_pair_idx = idx % (head_dim / 2); // The index of the pair within this head (0 to head_dim/2 - 1)
775
778
779 int base_x0, base_x1;
781 // Adjacent pairing: Rotate x[h*HD + 2*j] with x[h*HD + 2*j + 1]
783 base_x1 = head_idx * head_dim + (dim_pair_idx * 2 + 1);
784 } else {
785 // Split-half pairing: Rotate x[h*HD + j] with x[h*HD + j + head_dim/2]
788 }
789
790 float x0 = x[base_x0];
791 float x1 = x[base_x1];
792
795
796 x[base_x0] = x0 * cos_val - x1 * sin_val;
797 x[base_x1] = x0 * sin_val + x1 * cos_val;
798}

References j, and pos.

◆ silu_cuda()

void silu_cuda ( const std::vector< float > &  x_host,
std::vector< float > &  out_host,
int  n 
)

Definition at line 521 of file cuda_kernels.cu.

522 {
523 if (x_host.size() != n) {
524 throw std::runtime_error("SiLU CUDA: Input vector size mismatch.");
525 }
526 out_host.resize(n);
527
528 float* x_dev = nullptr;
529 float* out_dev = nullptr;
530 gpuErrchk(cudaMalloc(&x_dev, n * sizeof(float)));
531 gpuErrchk(cudaMalloc(&out_dev, n * sizeof(float)));
532
533 gpuErrchk(cudaMemcpy(x_dev, x_host.data(), n * sizeof(float),
535
536 const int threads_per_block = 256;
540
541 gpuErrchk(cudaMemcpy(out_host.data(), out_dev, n * sizeof(float),
544
547}

References j, and n.

◆ silu_kernel()

__global__ void silu_kernel ( const float *  x,
float *  out,
int  n 
)

Definition at line 513 of file cuda_kernels.cu.

513 {
514 int i = blockIdx.x * blockDim.x + threadIdx.x;
515 if (i < n) {
516 float x_val = x[i];
517 out[i] = x_val / (1.0f + expf(-x_val));
518 }
519}

References j, n, and out.

Referenced by ember_ir::ir_silu_cuda().

◆ softmax_exp_sum_kernel()

__global__ void softmax_exp_sum_kernel ( const float *  x,
float *  partial_sums,
int  n,
float  max_val 
)

Definition at line 570 of file cuda_kernels.cu.

571 {
572 extern __shared__ float sdata[];
573 unsigned int tid = threadIdx.x;
574 unsigned int i = blockIdx.x * blockDim.x + threadIdx.x;
575
576 sdata[tid] = (i < n) ? expf(x[i] - max_val) : 0.0f;
578
579 for (unsigned int s = blockDim.x / 2; s > 0; s >>= 1) {
580 if (tid < s) {
581 sdata[tid] += sdata[tid + s];
582 }
584 }
585
586 if (tid == 0) {
588 }
589}

References j, and n.

◆ softmax_find_max_kernel()

__global__ void softmax_find_max_kernel ( const float *  x,
float *  partial_max,
int  n 
)

Definition at line 549 of file cuda_kernels.cu.

550 {
551 extern __shared__ float sdata[];
552 unsigned int tid = threadIdx.x;
553 unsigned int i = blockIdx.x * blockDim.x + threadIdx.x;
554
555 sdata[tid] = (i < n) ? x[i] : -INFINITY;
557
558 for (unsigned int s = blockDim.x / 2; s > 0; s >>= 1) {
559 if (tid < s) {
560 sdata[tid] = fmaxf(sdata[tid], sdata[tid + s]);
561 }
563 }
564
565 if (tid == 0) {
566 partial_max[blockIdx.x] = sdata[0];
567 }
568}

References j, and n.

◆ softmax_normalize_kernel()

__global__ void softmax_normalize_kernel ( const float *  x,
float *  out,
int  n,
float  max_val,
float  inv_sum 
)

Definition at line 591 of file cuda_kernels.cu.

592 {
593 int i = blockIdx.x * blockDim.x + threadIdx.x;
594 if (i < n) {
595 out[i] = expf(x[i] - max_val) * inv_sum;
596 }
597}

References j, n, and out.

◆ softmax_optimized_kernel()

__global__ void softmax_optimized_kernel ( const float *__restrict__  x,
float *__restrict__  out,
int  n 
)

Optimized softmax using shared memory and warp primitives.

Correctly finds max and sum of exponentials at block level for accurate softmax.

Definition at line 2782 of file cuda_kernels.cu.

2784 {
2785 const int tid_global = threadIdx.x + blockIdx.x * blockDim.x;
2786 const int tid_block = threadIdx.x;
2787
2790
2791 // Initialize shared variables by the first thread of the block
2792 if (tid_block == 0) {
2794 s_block_sum_exp = 0.0f;
2795 }
2796 __syncthreads();
2797
2798 // Phase 1: Find max
2799 float thread_max_val = -INFINITY;
2800 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2802 }
2803 for (int offset = warpSize / 2; offset > 0; offset >>= 1) {
2805 }
2806 if ((tid_block % warpSize) == 0) { // Warp leaders
2808 }
2809 __syncthreads();
2811
2812 // Phase 2: Compute sum of exp
2813 float thread_sum_exp = 0.0f;
2814 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2816 }
2817 for (int offset = warpSize / 2; offset > 0; offset >>= 1) {
2818 thread_sum_exp += __shfl_down_sync(0xFFFFFFFF, thread_sum_exp, offset);
2819 }
2820 if ((tid_block % warpSize) == 0) { // Warp leaders
2822 }
2823 __syncthreads();
2825
2826 // Phase 3: Apply softmax
2827 float inv_sum = (global_sum_exp == 0.0f) ? 0.0f : 1.0f / global_sum_exp;
2828 for (int i = tid_global; i < n; i += gridDim.x * blockDim.x) {
2829 out[i] = expf(x[i] - global_max) * inv_sum;
2830 }
2831}

References atomicAddFloat(), atomicMaxFloat(), j, n, and out.

Referenced by softmax_vector_cuda_optimized().

◆ softmax_vector_cuda()

void softmax_vector_cuda ( const std::vector< float > &  x_host,
std::vector< float > &  out_host,
int  n 
)

Definition at line 599 of file cuda_kernels.cu.

600 {
601 if (x_host.size() != n) {
602 throw std::runtime_error("Softmax CUDA: Input vector size mismatch.");
603 }
604 if (n == 0) {
605 out_host.clear();
606 return;
607 }
608 out_host.resize(n);
609
610 float* x_dev = nullptr;
611 float* out_dev = nullptr;
612 float* partial_max_dev = nullptr;
613 float* partial_sum_dev = nullptr;
614
615 const int threads_per_block = 256;
617 size_t shared_mem_size = threads_per_block * sizeof(float);
618
619 float* partial_max_host = new float[num_blocks];
620 float* partial_sum_host = new float[num_blocks];
621
622 gpuErrchk(cudaMalloc(&x_dev, n * sizeof(float)));
623 gpuErrchk(cudaMalloc(&out_dev, n * sizeof(float)));
626
627 gpuErrchk(cudaMemcpy(x_dev, x_host.data(), n * sizeof(float),
629
634 num_blocks * sizeof(float), cudaMemcpyDeviceToHost));
635
636 float max_val = -INFINITY;
637 for (int i = 0; i < num_blocks; ++i) {
638 if (partial_max_host[i] > max_val) {
640 }
641 }
642
647 num_blocks * sizeof(float), cudaMemcpyDeviceToHost));
648
649 double exp_sum = 0.0;
650 for (int i = 0; i < num_blocks; ++i) {
652 }
653 float inv_sum = 1.0f / static_cast<float>(exp_sum);
654
658
659 gpuErrchk(cudaMemcpy(out_host.data(), out_dev, n * sizeof(float),
661
662 delete[] partial_max_host;
663 delete[] partial_sum_host;
668}

References j, and n.

◆ softmax_vector_cuda_optimized()

void softmax_vector_cuda_optimized ( const float *  x_dev,
float *  out_dev,
int  n,
cudaStream_t  stream 
)

Definition at line 3099 of file cuda_kernels.cu.

3100 {
3101 if (n <= 0) return;
3102 const int block_size = 256;
3103 // Ensure grid_size is 1 as the kernel is designed for block-wide reduction.
3104 const int grid_size = 1;
3105 // Shared memory: 2 floats (max_val, sum_exp)
3107 x_dev, out_dev, n);
3109}
__global__ void softmax_optimized_kernel(const float *__restrict__ x, float *__restrict__ out, int n)
Optimized softmax using shared memory and warp primitives.

References j, n, and softmax_optimized_kernel().

◆ swiglu_batch_cuda()

void swiglu_batch_cuda ( float *  d_out_batch,
const float *  d_gate_act_batch,
const float *  d_up_act_batch,
int  num_tokens,
int  intermediate_size,
cudaStream_t  stream 
)

Definition at line 717 of file cuda_kernels.cu.

723 {
724
725
726 if (num_tokens == 0 || intermediate_size == 0) {
727 Logger::info("[SWIGLU_BATCH_CUDA_SKIP] num_tokens or intermediate_size is 0. Nothing to do.");
728 Logger::info("[SWIGLU_BATCH_CUDA_EXIT] Skipped operation.");
729 return; // Nothing to do
730 }
731
732 // Log initial input values (first token, first few elements)
733 int log_count_elements = std::min(3, intermediate_size);
734 if (num_tokens > 0 && intermediate_size > 0) {
735 if (d_gate_act_batch) {
736 std::vector<float> h_gate_sample(log_count_elements);
737 // Gate is [num_tokens, intermediate_size]. Offset for T0 is 0.
739 }
740 if (d_up_act_batch) {
741 std::vector<float> h_up_sample(log_count_elements);
742 // Up is [num_tokens, intermediate_size]. Offset for T0 is 0.
744 }
745 }
746
747 const int threads_per_block = 256;
750
756 intermediate_size
757 );
759
760 // Log output values
761 if (num_tokens > 0 && intermediate_size > 0 && d_out_batch) {
762 std::vector<float> h_out_sample(log_count_elements);
763 // Out is [num_tokens, intermediate_size]. Offset for T0 is 0.
765 }
766}

References Logger::info(), j, and kernel_debug_copies().

◆ swiglu_batch_cuda_kernel()

__global__ void swiglu_batch_cuda_kernel ( float *  d_out_batch,
const float *  d_gate_act_batch,
const float *  d_up_act_batch,
int  num_tokens,
int  intermediate_size 
)

Definition at line 690 of file cuda_kernels.cu.

695 {
696
697 int token_idx = blockIdx.x;
698 if (token_idx >= num_tokens) {
699 return;
700 }
701
702 // Base pointers for the current token
703 const float* current_token_gate_ptr = d_gate_act_batch + (size_t)token_idx * intermediate_size;
704 const float* current_token_up_ptr = d_up_act_batch + (size_t)token_idx * intermediate_size;
705 float* current_token_out_ptr = d_out_batch + (size_t)token_idx * intermediate_size;
706
707 // Threads in the block parallelize over intermediate_size
708 for (int i = threadIdx.x; i < intermediate_size; i += blockDim.x) {
710 float silu_gate = gate_val / (1.0f + expf(-gate_val)); // SiLU(x) = x * sigmoid(x)
713 }
714}

References j.

◆ swiglu_cuda()

void swiglu_cuda ( const float *  gate_dev,
const float *  up_dev,
float *  out_dev,
int  n,
cudaStream_t  stream 
)

Definition at line 680 of file cuda_kernels.cu.

References j, and n.

◆ swiglu_kernel()

__global__ void swiglu_kernel ( const float *  gate,
const float *  up,
float *  out,
int  n 
)

Definition at line 670 of file cuda_kernels.cu.

671 {
672 int i = blockIdx.x * blockDim.x + threadIdx.x;
673 if (i < n) {
674 float gate_val = gate[i];
675 float silu_gate = gate_val / (1.0f + expf(-gate_val));
676 out[i] = silu_gate * up[i];
677 }
678}

References j, n, and out.

◆ update_kv_cache_cuda()

void update_kv_cache_cuda ( float *  cache_base_ptr,
const float *  current_kv_head_vector,
int  pos,
int  kv_head_idx,
int  max_seq_len,
int  num_kv_heads,
int  head_dim,
cudaStream_t  stream 
)

Definition at line 1344 of file cuda_kernels.cu.

1348 {
1350 dim3 gridDim(1);
1351
1353 Logger::error("update_kv_cache_cuda: pos out of bounds (" +
1354 std::to_string(pos) + " >= " + std::to_string(max_seq_len) +
1355 ")");
1356 return;
1357 }
1358
1360 Logger::error("update_kv_cache_cuda: kv_head_idx out of bounds (" +
1361 std::to_string(kv_head_idx) +
1362 " >= " + std::to_string(num_kv_heads) + ")");
1363 return;
1364 }
1366 Logger::error("update_kv_cache_cuda: Input K/V vector pointer is null.");
1367 return;
1368 }
1369
1374}

References Logger::error(), j, and pos.

◆ update_kv_cache_kernel()

__global__ void update_kv_cache_kernel ( float *  cache_base_ptr,
const float *  current_kv_vector,
int  pos,
int  kv_head_idx,
int  max_seq_len,
int  num_kv_heads,
int  head_dim 
)

Definition at line 1324 of file cuda_kernels.cu.

1327 {
1328 int d = threadIdx.x;
1329 if (d >= head_dim) return;
1330
1332 (size_t)kv_head_idx * head_dim + d;
1333
1334 size_t source_offset = d;
1335
1338 return;
1339 }
1340
1342}

References j, and pos.