Parser for GGUF (GPT-Generated Unified Format) files. More...
#include <cstddef>#include <fstream>#include <map>#include <string>#include <vector>#include "gguf_structs.h"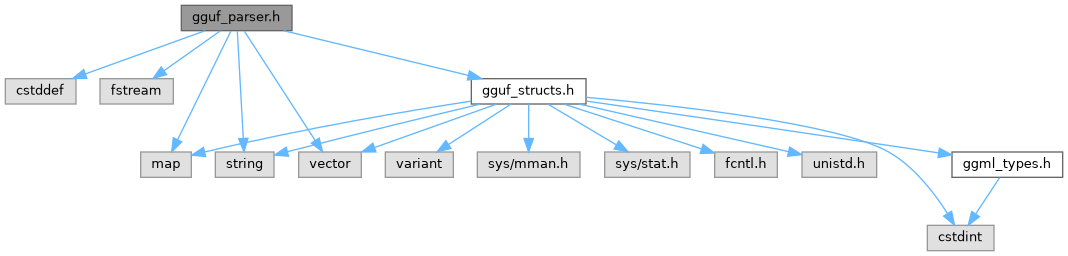
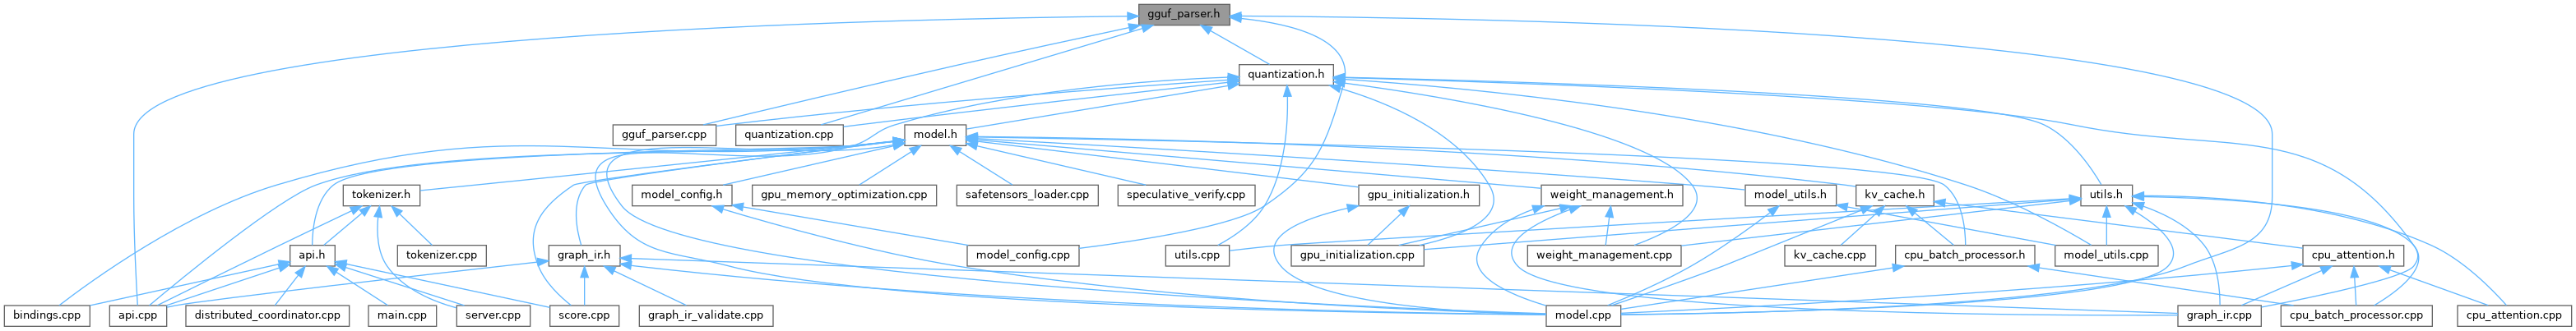
Go to the source code of this file.
Functions | |
| template<typename T > | |
| void | read_raw (std::ifstream &file, T &dest) |
| Reads raw binary data from a file stream. | |
| std::string | read_gguf_string (std::ifstream &file) |
| Reads a string from a GGUF format file. | |
| GGUFData | load_gguf_meta (const std::string &filename, bool use_mmap) |
| Loads GGUF metadata and optionally memory-maps tensor data. | |
Variables | |
| constexpr uint32_t | GGUF_MAGIC = 0x46554747 |
| GGUF magic number that identifies the file format Spells "GGUF" in ASCII (0x47475546) | |
| constexpr uint64_t | GGUF_DEFAULT_ALIGNMENT = 32 |
| Constants for GGUF file parsing and validation. | |
| constexpr uint32_t | GGUF_MAX_TENSOR_DIMS = 4 |
| constexpr uint64_t | GGUF_STRING_MAX_LENGTH = 1ull << 30 |
| constexpr float | GGUF_EPSILON = 1e-10f |
| Constants for numeric stability in calculations. | |
| constexpr float | GGUF_SMALL_VAL = 1e-6f |
| constexpr size_t | GGML_QK_K = 256 |
| Block size constants for different quantization formats. | |
| constexpr size_t | GGML_QK8_0 = 32 |
| constexpr size_t | GGML_Q4K_BLOCK_SIZE = 32 |
| constexpr size_t | GGML_Q6K_BLOCK_SIZE = 256 |
| constexpr float | TENSOR_SCALE_MAX = 1000.0f |
| Constants for tensor value validation. | |
| constexpr float | TENSOR_SCALE_MIN = -1000.0f |
| constexpr float | Q4K_SCALE_FACTOR = 15.0f |
| Scale factors for different quantization methods. | |
| constexpr float | Q6K_SCALE_FACTOR = 31.0f |
| constexpr float | Q8K_SCALE_FACTOR = 127.0f |
| constexpr int8_t | Q4K_OFFSET = 8 |
| Offset values for quantization methods. | |
| constexpr int8_t | Q6K_OFFSET = 32 |
Detailed Description
Parser for GGUF (GPT-Generated Unified Format) files.
This file contains constants and functions for parsing GGUF format files, which are used to store language models and their associated metadata. The format supports various quantization methods and tensor storage options.
Definition in file gguf_parser.h.
Function Documentation
◆ load_gguf_meta()
| GGUFData load_gguf_meta | ( | const std::string & | filename, |
| bool | use_mmap | ||
| ) |
Loads GGUF metadata and optionally memory-maps tensor data.
Parses the header, metadata, and tensor information from a GGUF file. If mmap is enabled, it will also memory-map the tensor data region. If mmap is disabled, tensor data pointers will be null and fd will be -1.
- Parameters
-
filename Path to the GGUF file. use_mmap Whether to memory-map the tensor data block.
- Returns
- GGUFData structure containing loaded information.
- Exceptions
-
std::runtime_error on file I/O or format errors.
Definition at line 123 of file gguf_parser.cpp.
References ARRAY, BOOL, Logger::error(), FLOAT32, FLOAT64, ggml_type_block_size(), ggml_type_name(), ggml_type_size(), GGUF_DEFAULT_ALIGNMENT, GGUF_MAGIC, GGUF_MAX_TENSOR_DIMS, gguf_value_type_size(), Logger::info(), INT16, INT32, INT64, INT8, j, k, GGUFData::MMapFailure, GGUFTensorInfo::name, GGUFTensorInfo::num_elements, GGUFTensorInfo::offset, read_gguf_string(), read_raw(), GGUFTensorInfo::shape, GGUFTensorInfo::size_in_bytes, STRING, GGUFArray::type, GGUFTensorInfo::type, UINT16, UINT32, UINT64, UINT8, and Logger::warning().
Referenced by TinyLlamaModel::TinyLlamaModel().
◆ read_gguf_string()
| std::string read_gguf_string | ( | std::ifstream & | file | ) |
Reads a string from a GGUF format file.
- Parameters
-
file Input file stream positioned at the start of a string
- Returns
- The string read from the file
- Exceptions
-
std::runtime_error if string length exceeds GGUF_STRING_MAX_LENGTH
Definition at line 82 of file gguf_parser.cpp.
References GGUF_STRING_MAX_LENGTH, j, and read_raw().
Referenced by load_gguf_meta().
◆ read_raw()
| void read_raw | ( | std::ifstream & | file, |
| T & | dest | ||
| ) |
Reads raw binary data from a file stream.
- Template Parameters
-
T The type of data to read
- Parameters
-
file Input file stream dest Destination variable to store the read data
Definition at line 62 of file gguf_parser.cpp.
References j.
Referenced by load_gguf_meta(), and read_gguf_string().
Variable Documentation
◆ GGML_Q4K_BLOCK_SIZE
Block size for Q4_K format
Definition at line 44 of file gguf_parser.h.
◆ GGML_Q6K_BLOCK_SIZE
Block size for Q6_K format
Definition at line 45 of file gguf_parser.h.
◆ GGML_QK8_0
Block size for Q8_0 format
Definition at line 43 of file gguf_parser.h.
Referenced by dequant_span_to_f32(), TinyLlamaModel::dequantize_all_if_small(), dequantize_q8_0_block(), dequantize_vector_q8_0_to_f32(), TinyLlamaModel::initialize_gpu_and_rope(), TinyLlamaModel::lookup_embedding(), and matvec_q8_0_f32_vector_cpu().
◆ GGML_QK_K
Block size constants for different quantization formats.
Block size for K-quantized formats
Definition at line 42 of file gguf_parser.h.
Referenced by ember_ir::Interpreter::bind_tensor(), dequant_legacy_to_f32(), dequant_span_to_f32(), dequantize_q2_k(), dequantize_q3_k(), dequantize_q4_k_m(), dequantize_q5_k(), dequantize_q6_k(), dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), ggml_type_block_size(), TinyLlamaModel::initialize_gpu_and_rope(), TinyLlamaModel::lookup_embedding(), matmul_q8k_f32_batch_cpu(), matvec_q4k_f32_vector_cpu(), matvec_q4k_q8k_cpu(), matvec_q6k_f32_vector_cpu(), matvec_q6k_q8k_cpu(), matvec_q8k_f32_vector_cpu(), quantize_fp32_to_q8_K(), quantize_q4_k_m(), quantize_q6_k(), vec_dot_q4_k_q8_k_cpu(), and vec_dot_q6_k_q8_k_cpu().
◆ GGUF_DEFAULT_ALIGNMENT
Constants for GGUF file parsing and validation.
Default alignment for tensor data
Definition at line 29 of file gguf_parser.h.
Referenced by load_gguf_meta().
◆ GGUF_EPSILON
Constants for numeric stability in calculations.
Minimum value for numeric stability
Definition at line 36 of file gguf_parser.h.
Referenced by quantize_q4_k_m(), and quantize_q6_k().
◆ GGUF_MAGIC
GGUF magic number that identifies the file format Spells "GGUF" in ASCII (0x47475546)
Definition at line 24 of file gguf_parser.h.
Referenced by load_gguf_meta().
◆ GGUF_MAX_TENSOR_DIMS
Maximum number of dimensions for tensors
Definition at line 30 of file gguf_parser.h.
Referenced by load_gguf_meta().
◆ GGUF_SMALL_VAL
Small value for near-zero comparisons
Definition at line 37 of file gguf_parser.h.
Referenced by quantize_q4_k_m().
◆ GGUF_STRING_MAX_LENGTH
Maximum length for strings (1GB)
Definition at line 31 of file gguf_parser.h.
Referenced by read_gguf_string().
◆ Q4K_OFFSET
Offset values for quantization methods.
Offset for Q4_K quantization
Definition at line 63 of file gguf_parser.h.
Referenced by quantize_q4_k_m().
◆ Q4K_SCALE_FACTOR
Scale factors for different quantization methods.
Scale factor for Q4_K quantization
Definition at line 56 of file gguf_parser.h.
Referenced by quantize_q4_k_m().
◆ Q6K_OFFSET
Offset for Q6_K quantization
Definition at line 64 of file gguf_parser.h.
Referenced by quantize_q6_k().
◆ Q6K_SCALE_FACTOR
Scale factor for Q6_K quantization
Definition at line 57 of file gguf_parser.h.
Referenced by quantize_q6_k().
◆ Q8K_SCALE_FACTOR
Scale factor for Q8_K quantization
Definition at line 58 of file gguf_parser.h.
Referenced by quantize_fp32_to_q8_K().
◆ TENSOR_SCALE_MAX
Constants for tensor value validation.
Maximum allowed scale value
Definition at line 50 of file gguf_parser.h.
Referenced by dequantize_q2_k().
◆ TENSOR_SCALE_MIN
Minimum allowed scale value
Definition at line 51 of file gguf_parser.h.
Referenced by dequantize_q2_k().
