ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
model_config.cpp File Reference
#include "model_config.h"
#include "logger.h"
#include "gguf_parser.h"
#include <algorithm>
#include <cmath>
#include <cstring>
#include <fstream>
#include <iomanip>
#include <limits>
#include <memory>
#include <sstream>
#include <stdexcept>
#include <cassert>
#include <cstdint>
#include <iostream>
#include <numeric>
#include <variant>
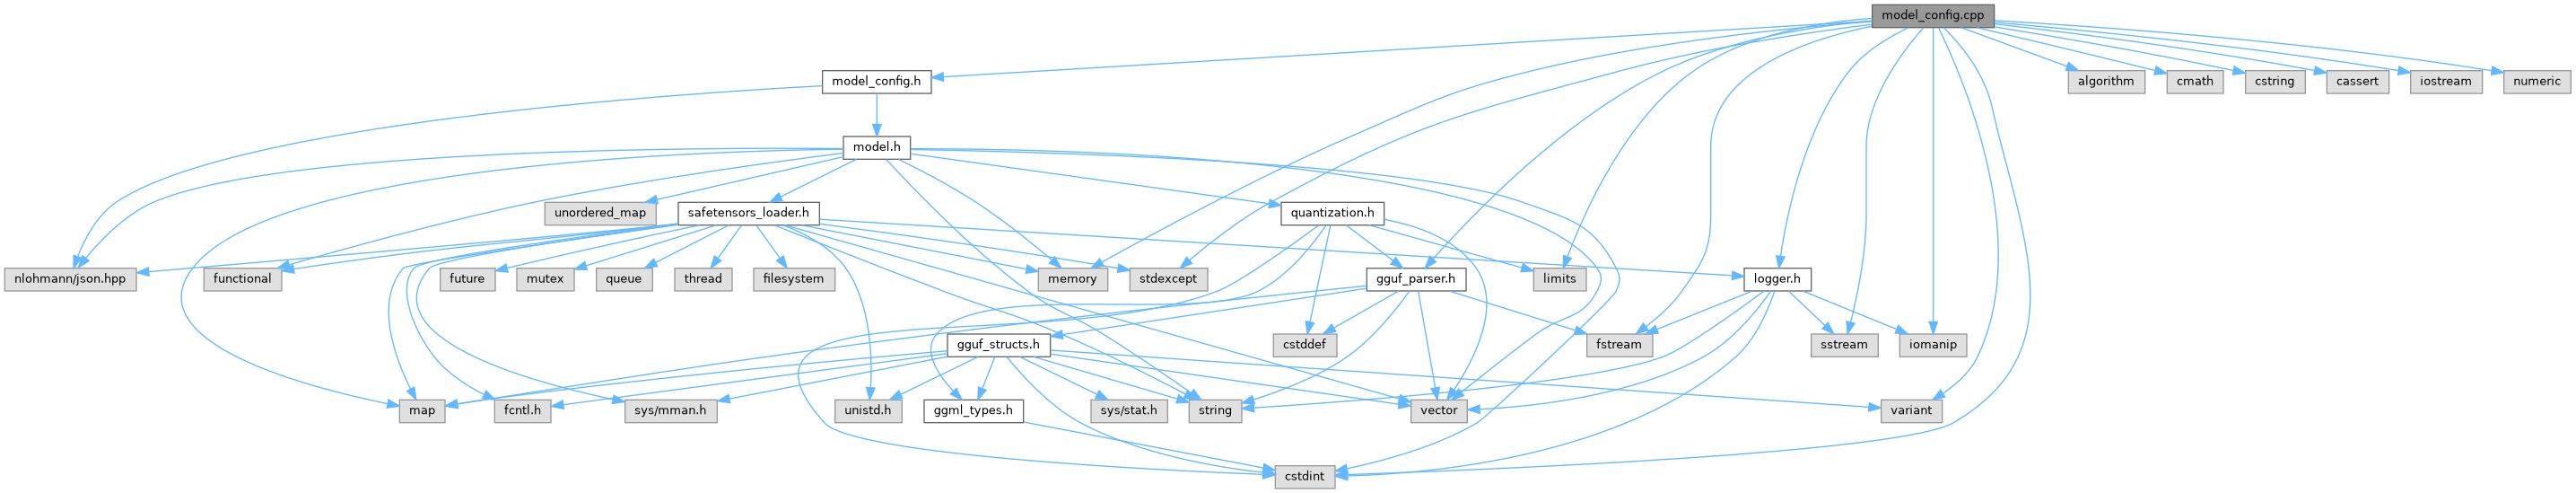
Include dependency graph for model_config.cpp:
Go to the source code of this file.

Functions

ModelConfig parse_model_config (const nlohmann::json &json)
 
ModelConfig parse_model_config_from_gguf (const GGUFData &gguf)
 

Function Documentation

◆ parse_model_config()

ModelConfig parse_model_config ( const nlohmann::json &  json)

Definition at line 20 of file model_config.cpp.

20 {
22 cfg.hidden_size = json.value("hidden_size", 0);
23 cfg.intermediate_size = json.value("intermediate_size", 0);
24 cfg.num_attention_heads = json.value("num_attention_heads", 0);
25 cfg.num_key_value_heads = json.value("num_key_value_heads", 0);
26 cfg.num_hidden_layers = json.value("num_hidden_layers", 0);
27 cfg.vocab_size = json.value("vocab_size", 0);
28 cfg.max_position_embeddings = json.value("max_position_embeddings", 0);
29 cfg.rms_norm_eps = json.value("rms_norm_eps", 1e-5f);
30 cfg.rope_theta = json.value("rope_theta", 10000.0f);
31 cfg.hidden_act = json.value("hidden_act", "silu");
32 cfg.torch_dtype = json.value("torch_dtype", "bfloat16");
33 cfg.bos_token_id = json.value("bos_token_id", 1);
34 cfg.eos_token_id = json.value("eos_token_id", 2);
35 cfg.unk_token_id = json.value("unk_token_id", -1);
36 cfg.pad_token_id = json.value("pad_token_id", -1);
37
38 // Infer Architecture if available
39 if (json.contains("architectures") && json["architectures"].is_array() && !json["architectures"].empty()) {
40 // Take the first architecture string if multiple are listed
41 cfg.architecture = json["architectures"][0].get<std::string>();
42 } else {
43 cfg.architecture = "unknown";
44 }
45 cfg.model_name = json.value("model_type", cfg.architecture); // Use model_type or fallback to architecture
46
47
48 Logger::info("[parse_json_config] Inferring tokenizer family for SafeTensors. Arch: '" + cfg.architecture + "', Vocab: " + std::to_string(cfg.vocab_size));
49 bool is_llama3_vocab_size_json = (cfg.vocab_size == 128256);
50 bool is_llama3_arch_hint_json = (cfg.architecture.find("LlamaForCausalLM") != std::string::npos && // Llama 3 often uses this
51 cfg.architecture.find("Llama2") == std::string::npos); // Exclude Llama 2 explicitly if needed
52
55 Logger::info("[parse_json_config] Result: Identified LLAMA3_TIKTOKEN (vocab size + arch hint).");
56 if (cfg.rope_theta == 10000.0f) {
57 float llama3_rope_candidate = json.value("rope_theta", 500000.0f); // Check rope_theta in config.json
58 if (llama3_rope_candidate > 10000.0f) {
59 cfg.rope_theta = llama3_rope_candidate;
60 Logger::info("[parse_json_config] Adjusted rope_theta to " + std::to_string(cfg.rope_theta) + " for Llama 3 model (was 10000.0).");
61 }
62 }
63 } else if (cfg.vocab_size == 32000 || cfg.architecture.find("Llama") != std::string::npos) { // Common for Llama 1/2/TinyLlama
65 Logger::info("[parse_json_config] Result: Identified LLAMA_SENTENCEPIECE (vocab size or arch hint).");
66 } else {
68 Logger::warning("[parse_json_config] Result: UNKNOWN tokenizer family.");
69 }
70
71
72 return cfg;
73}
static void warning(const std::string &message)
Definition logger.cpp:139
static void info(const std::string &message)
Definition logger.cpp:135
size_t j
nlohmann::json json
Definition server.cpp:68
Model configuration structure holding architecture and hyperparameters.
Definition model.h:82
int hidden_size
Definition model.h:83

References ModelConfig::hidden_size, Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, ModelConfig::LLAMA_SENTENCEPIECE, ModelConfig::UNKNOWN, and Logger::warning().

◆ parse_model_config_from_gguf()

ModelConfig parse_model_config_from_gguf ( const GGUFData &  gguf)

Definition at line 75 of file model_config.cpp.

75 {
77 Logger::info("[parse_gguf_config] Entered function.");
78
79 auto get_meta_string = [&](const std::string& key,
80 const std::string& default_val) -> std::string {
81 auto it = gguf.metadata.find(key);
82 if (it != gguf.metadata.end() &&
83 std::holds_alternative<std::string>(it->second)) {
84 return std::get<std::string>(it->second);
85 }
86 return default_val;
87 };
88
89 auto get_meta_value = [&](const std::string& key, auto default_value) {
90 using TargetType = typename std::decay<decltype(default_value)>::type;
91 auto it = gguf.metadata.find(key);
92 if (it != gguf.metadata.end()) {
93 return std::visit(
94 [&](const auto& val) -> TargetType {
95 using T = std::decay_t<decltype(val)>;
96
97 if constexpr (std::is_integral_v<TargetType>) {
98 if constexpr (std::is_integral_v<T> && !std::is_same_v<T, bool>) {
99 if constexpr (std::is_unsigned_v<T> &&
100 std::is_signed_v<TargetType>) {
101 if (val > static_cast<std::make_unsigned_t<TargetType>>(
102 std::numeric_limits<TargetType>::max())) {
103 Logger::warning("Metadata key '" + key + "' value " +
104 std::to_string(val) +
105 " overflows TargetType. Using default.");
106 return default_value;
107 }
108 }
109
110 else if constexpr (std::is_signed_v<T> &&
111 std::is_signed_v<TargetType> &&
112 sizeof(T) > sizeof(TargetType)) {
113 if (val > static_cast<T>(
114 std::numeric_limits<TargetType>::max()) ||
115 val < static_cast<T>(
116 std::numeric_limits<TargetType>::lowest())) {
117 Logger::warning("Metadata key '" + key + "' value " +
118 std::to_string(val) +
119 " overflows TargetType. Using default.");
120 return default_value;
121 }
122 }
123 return static_cast<TargetType>(val);
124 }
125 } else if constexpr (std::is_floating_point_v<TargetType>) {
126 if constexpr (std::is_floating_point_v<T>) {
127 return static_cast<TargetType>(val);
128 }
129 } else if constexpr (std::is_same_v<TargetType, bool>) {
130 if constexpr (std::is_same_v<T, bool>) {
131 return val;
132 }
133 } else if constexpr (std::is_same_v<TargetType, std::string>) {
134 if constexpr (std::is_same_v<T, std::string>) {
135 return val;
136 }
137 }
138 Logger::warning("Metadata key '" + key +
139 "' has stored type incompatible with requested "
140 "TargetType. Using default.");
141 return default_value;
142 },
143 it->second);
144 } else {
145 return default_value;
146 }
147 };
148
149 config.vocab_size = get_meta_value("tokenizer.ggml.vocab_size",
150 get_meta_value("llama.vocab_size", 32000));
151 // Model dimensions with fallbacks for different architectures (llama.*, phi.*, mistral.*)
152 config.hidden_size = get_meta_value("llama.embedding_length",
153 get_meta_value("phi.embedding_length",
154 get_meta_value("mistral.embedding_length", 4096)));
155 config.intermediate_size = get_meta_value("llama.feed_forward_length",
156 get_meta_value("phi.feed_forward_length",
157 get_meta_value("mistral.feed_forward_length", 11008)));
158 config.num_attention_heads = get_meta_value("llama.attention.head_count",
159 get_meta_value("phi.attention.head_count",
160 get_meta_value("mistral.attention.head_count", 32)));
161 config.num_experts = get_meta_value("llama.expert_count", 0);
162 config.num_experts_used = get_meta_value("llama.expert_used_count", 0);
163 config.num_hidden_layers = get_meta_value("llama.block_count",
164 get_meta_value("phi.block_count",
165 get_meta_value("mistral.block_count", 32)));
166 config.num_key_value_heads = get_meta_value("llama.attention.head_count_kv",
167 get_meta_value("phi.attention.head_count_kv",
168 get_meta_value("mistral.attention.head_count_kv",
169 config.num_attention_heads)));
170 config.max_position_embeddings = get_meta_value("llama.context_length",
171 get_meta_value("phi.context_length",
172 get_meta_value("mistral.context_length", 4096)));
173 if (config.max_position_embeddings == 0 ||
174 config.max_position_embeddings > 8192) {
175 Logger::warning("max_position_embeddings from GGUF is " +
176 std::to_string(config.max_position_embeddings) +
177 ", overriding to sensible default (2048)");
178 config.max_position_embeddings = 2048;
179 }
180 config.rms_norm_eps =
181 get_meta_value("llama.attention.layer_norm_rms_epsilon",
182 get_meta_value("phi.attention.layer_norm_rms_epsilon",
183 get_meta_value("mistral.attention.layer_norm_rms_epsilon", 1e-5f)));
184 config.rope_theta = get_meta_value("llama.rope.freq_base",
185 get_meta_value("phi.rope.freq_base",
186 get_meta_value("mistral.rope.freq_base", 10000.0f)));
187
188 // Read hidden_act from metadata, with architecture-based defaults
189 std::string arch = get_meta_string("general.architecture", "llama");
190 config.hidden_act = get_meta_string("llama.hidden_act",
191 get_meta_string("phi.hidden_act",
192 get_meta_string("mistral.hidden_act", "")));
193 if (config.hidden_act.empty()) {
194 // Architecture-based defaults: Phi uses gelu_new, Llama/Mistral use silu
195 if (arch.find("phi") != std::string::npos || arch.find("Phi") != std::string::npos) {
196 config.hidden_act = "gelu_new";
197 Logger::info("[parse_gguf_config] Phi architecture detected, defaulting hidden_act to 'gelu_new'");
198 } else {
199 config.hidden_act = "silu";
200 }
201 }
202 Logger::info("[parse_gguf_config] hidden_act = '" + config.hidden_act + "'");
203 config.bos_token_id = get_meta_value("tokenizer.ggml.bos_token_id", -1);
204 config.eos_token_id = get_meta_value("tokenizer.ggml.eos_token_id", -1);
205 config.unk_token_id = get_meta_value("tokenizer.ggml.unk_token_id", -1);
206 config.pad_token_id = get_meta_value("tokenizer.ggml.padding_token_id", -1);
207
208 config.architecture = get_meta_string("general.architecture", "unknown");
209 config.model_name = get_meta_string("general.name", "unknown");
210 bool has_pre_key = gguf.metadata.count("tokenizer.ggml.pre");
211 bool has_merges = !gguf.tokenizer_merges.empty();
212
213 Logger::info("[parse_gguf_config] Architecture: " + config.architecture +
214 ", Vocab Size: " + std::to_string(config.vocab_size) +
215 ", Has Merges: " + (has_merges ? "Yes" : "No"));
216
217
218 Logger::info("[parse_gguf_config] Identifying tokenizer family...");
219 bool is_llama3_arch_hint = (config.architecture.find("llama3") != std::string::npos ||
220 config.architecture.find("Llama-3") != std::string::npos ||
221 config.architecture.find("Meta-Llama-3") != std::string::npos);
222 bool is_llama3_vocab_size = (config.vocab_size == 128256);
223 std::string ggml_tokenizer_model = get_meta_string("tokenizer.ggml.model", "");
225
226 Logger::info("[parse_gguf_config] L3 Hints: arch_hint=" + std::string(is_llama3_arch_hint ? "Y":"N") +
227 ", vocab_size_match=" + std::string(is_llama3_vocab_size ? "Y":"N") +
228 ", has_merges=" + std::string(has_merges ? "Y":"N") +
229 ", ggml_tokenizer_model_key='" + ggml_tokenizer_model + "' (is_tiktoken_style: " + std::string(is_tiktoken_style_tokenizer_model ? "Y":"N") + ")" );
230
231 if (ggml_tokenizer_model == "word") {
232 // transformer_cpp export: word-level vocabulary (whitespace split,
233 // lowercased whole-word lookup). Must be checked before the
234 // architecture-based branches — these GGUFs also declare arch "llama".
236 Logger::info("[parse_gguf_config] Result: Identified WORD_LEVEL tokenizer "
237 "(tokenizer.ggml.model='word'; transformer_cpp export).");
240 Logger::info("[parse_gguf_config] Result: Identified LLAMA3_TIKTOKEN (merges + vocab_size + ggml_tokenizer_model='gpt2'). Architecture string was: '" + config.architecture + "'");
241 if (!is_llama3_arch_hint && config.architecture == "llama") {
242 Logger::info("[parse_gguf_config] Note: Classified as Llama 3 based on tokenizer/vocab, but arch string was 'llama'.");
243 }
244 if (config.rope_theta == 10000.0f) {
245 float llama3_rope_candidate = get_meta_value("llama.rope.freq_base", 500000.0f);
246 if (llama3_rope_candidate > 10000.0f) {
247 config.rope_theta = llama3_rope_candidate;
248 Logger::info("[parse_gguf_config] Adjusted rope_theta to " + std::to_string(config.rope_theta) + " for Llama 3 model (was 10000.0).");
249 }
250 }
251 } else if (config.architecture == "llama" || config.architecture.find("Llama-2") != std::string::npos || config.architecture.find("TinyLlama") != std::string::npos) {
253 Logger::info("[parse_gguf_config] Result: Identified LLAMA_SENTENCEPIECE based on architecture: '" + config.architecture + "'");
254 } else {
256 Logger::info("[parse_gguf_config] Result: UNKNOWN tokenizer family for architecture: '" + config.architecture + "'");
257 }
258
259 // Existing chat_template_type and pre_tokenizer_type logic based on architecture and pre_key
260 if (config.model_name.find("TinyLlama") != std::string::npos ||
261 (config.architecture == "llama" && has_pre_key)) {
262 config.chat_template_type = "tinyllama";
263 } else if (config.architecture == "llama" && !has_pre_key) {
264 config.chat_template_type = "llama2";
265 } else {
266 config.chat_template_type = "unknown";
267 Logger::warning("Could not determine chat template type for arch='" +
268 config.architecture + "', name='" + config.model_name +
269 "'.");
270 }
271
272 if (has_pre_key) {
273 config.pre_tokenizer_type =
274 get_meta_string("tokenizer.ggml.pre", "unknown");
275 } else if (config.architecture == "llama") {
276 config.pre_tokenizer_type = "llama";
277 } else {
278 config.pre_tokenizer_type = "unknown";
279 }
280 Logger::info("Determined config: architecture='" + config.architecture +
281 "', model_name='" + config.model_name + "', chat_template='" +
282 config.chat_template_type + "', pre_tokenizer='" +
283 config.pre_tokenizer_type + "'");
284
285 if (config.model_name == "llama" && config.pre_tokenizer_type != "llama") {
286 config.chat_template_type = "llama2";
288 "Inferred chat_template_type='llama2' based on model_type and "
289 "missing/different pre_tokenizer_type.");
290 }
291
292 auto template_it = gguf.metadata.find("tokenizer.chat_template");
293 if (template_it != gguf.metadata.end() &&
294 std::holds_alternative<std::string>(template_it->second)) {
295 config.chat_template_string = std::get<std::string>(template_it->second);
296 Logger::info("Found tokenizer.chat_template in metadata.");
297
298 } else {
300 "tokenizer.chat_template not found or not a string in metadata. Will "
301 "use fallback logic.");
302 config.chat_template_string = "";
303 }
304 if (config.chat_template_type == "unknown") {
305 if (config.model_name == "llama" && config.pre_tokenizer_type != "llama") {
306 config.chat_template_type = "llama2";
308 "Inferred chat_template_type='llama2' based on model name and "
309 "missing/different pre_tokenizer_type.");
310 } else if (config.tokenizer_family == ModelConfig::TokenizerFamily::LLAMA3_TIKTOKEN) {
311 Logger::info("Llama 3 model identified. Chat template will primarily rely on 'tokenizer.chat_template' from GGUF if present.");
312 // Set a generic type for now, actual application will use the string.
313 if (gguf.metadata.count("tokenizer.chat_template")) {
314 config.chat_template_type = "llama3_gguf_direct";
315 } else {
316 config.chat_template_type = "llama3_fallback"; // Or some other indicator
317 Logger::warning("Llama 3 model detected, but 'tokenizer.chat_template' not found in GGUF metadata.");
318 }
319 }
320 }
321
322 Logger::info(std::string("[parse_gguf_config] Finished parsing. Returning config. Family: ") +
323 (config.tokenizer_family == ModelConfig::TokenizerFamily::LLAMA3_TIKTOKEN ? "L3_TIKTOKEN" :
324 (config.tokenizer_family == ModelConfig::TokenizerFamily::LLAMA_SENTENCEPIECE ? "L2_SPM" : "UNKNOWN")));
325 return config;
326}
enum ember_ir::@44::Value::Type type

References Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, ModelConfig::LLAMA_SENTENCEPIECE, type, ModelConfig::UNKNOWN, Logger::warning(), and ModelConfig::WORD_LEVEL.

Referenced by TinyLlamaModel::TinyLlamaModel(), and ember_ir::tuned_llama_match().
