ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
KVCache Struct Reference

Complete Key-Value cache for all transformer layers. More...

#include <model.h>
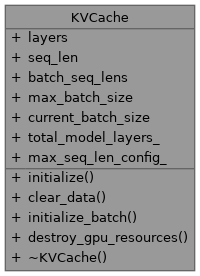
Collaboration diagram for KVCache:
Collaboration graph

Public Member Functions

void initialize (const ModelConfig &config, int total_num_model_layers, int num_gpu_layers_to_allocate, int max_seq_len_arg, int num_kv_heads, int head_dim, int max_batch_size_arg=1)
 Initializes the KV cache with given dimensions.
 
void clear_data ()
 
void initialize_batch (int batch_size)
 Initialize batch mode with specified number of sequences.
 
void destroy_gpu_resources ()
 
 ~KVCache ()
 

Public Attributes

std::vector< KVCacheLayer > layers
 
int seq_len = 0
 
std::vector< int > batch_seq_lens
 
int max_batch_size = 1
 
int current_batch_size = 0
 
int total_model_layers_ = 0
 
int max_seq_len_config_ = 0
 

Detailed Description

Complete Key-Value cache for all transformer layers.

Manages the KV cache across all layers of the transformer model, including memory management for both CPU and GPU implementations. Supports both single-sequence and multi-sequence batch processing.

Definition at line 157 of file model.h.

Constructor & Destructor Documentation

◆ ~KVCache()

KVCache::~KVCache ( )
inline

Definition at line 239 of file model.h.

239 {
241 }
void destroy_gpu_resources()
Definition kv_cache.cpp:217

References destroy_gpu_resources().

Member Function Documentation

◆ clear_data()

void KVCache::clear_data ( )
inline

Definition at line 186 of file model.h.

186 {
187 // Single-sequence mode (legacy compatibility)
188 seq_len = 0;
189
190 // Multi-sequence mode
192 batch_seq_lens.clear();
193
194 // For batch processing, we MUST clear the actual KV data to prevent cross-sequence contamination.
195 // Only layers that run on the CPU read these host vectors. The GPU
196 // layers (the top allocated_num_layers) keep their KV on the device,
197 // where prefill writes positions 0..n-1 before attention reads them.
198 // Zero-filling their unused host copies cost a constant 26 ms per
199 // request on the TTFT timing model (docs/TTFT.md).
200 size_t host_layers = layers.size();
201#ifdef HAS_CUDA
202 host_layers -= std::min(host_layers, static_cast<size_t>(std::max(allocated_num_layers, 0)));
203#endif
204 for (size_t i = 0; i < host_layers; ++i) {
205 std::fill(layers[i].k.begin(), layers[i].k.end(), 0.0f);
206 std::fill(layers[i].v.begin(), layers[i].v.end(), 0.0f);
207 }
208
209 // Logger::debug("[KVCache] clear_data() called. seq_len reset to 0. K/V vectors cleared for batch processing.");
210 }
std::vector< float > v
size_t j
std::vector< KVCacheLayer > layers
Definition model.h:158
int seq_len
Definition model.h:161
std::vector< int > batch_seq_lens
Definition model.h:164
int current_batch_size
Definition model.h:166

References batch_seq_lens, current_batch_size, j, k, layers, seq_len, and v.

Referenced by tinyllama::TinyLlamaSession::generate(), tinyllama::TinyLlamaSession::generate_batch(), and tinyllama::TinyLlamaSession::score_rows().

◆ destroy_gpu_resources()

void KVCache::destroy_gpu_resources ( )

Definition at line 217 of file kv_cache.cpp.

217 {
218 // No-op for CPU-only builds
219}

Referenced by ~KVCache().

◆ initialize()

void KVCache::initialize ( const ModelConfig &  config,
int  total_num_model_layers,
int  num_gpu_layers_to_allocate,
int  max_seq_len_arg,
int  num_kv_heads,
int  head_dim,
int  max_batch_size_arg = 1 
)

Initializes the KV cache with given dimensions.

Parameters
configThe model configuration, used to determine if KVCache quantization is enabled.
total_num_model_layersTotal number of layers in the model (for sizing CPU cache vectors)
num_gpu_layers_to_allocateNumber of layers for which to allocate GPU device memory. Can be 0.
max_seq_len_argMaximum sequence length to cache
num_kv_headsNumber of key/value heads
head_dimDimension of each attention head
max_batch_size_argMaximum number of sequences for batch processing (default: 1 for single-sequence)

Definition at line 10 of file kv_cache.cpp.

13 {
17 this->current_batch_size = 0;
18 this->batch_seq_lens.clear();
19 this->batch_seq_lens.resize(max_batch_size_arg, 0);
21 seq_len = 0;
22 Logger::info("Allocating KVCache host vectors...");
23 size_t cache_size_per_layer = static_cast<size_t>(max_seq_len_arg) *
24 static_cast<size_t>(max_batch_size_arg) *
25 static_cast<size_t>(num_kv_heads) *
26 static_cast<size_t>(head_dim);
27 if (cache_size_per_layer == 0 && max_seq_len_arg > 0 && total_num_model_layers > 0) {
28 throw std::runtime_error(
29 "KVCache (CPU): Calculated cache size is zero for non-empty model. Check parameters.");
30 }
31
32 for (int l = 0; l < total_num_model_layers; ++l) {
33 try {
34 layers[l].k.assign(cache_size_per_layer, 0.0f);
35 layers[l].v.assign(cache_size_per_layer, 0.0f);
36 } catch (const std::bad_alloc& e) {
37 Logger::error("Failed to allocate CPU KVCache for layer " +
38 std::to_string(l) + ": " + e.what());
39 throw;
40 }
41 }
42 Logger::info("KVCache (CPU) vectors allocated for " +
43 std::to_string(total_num_model_layers) + " layers.");
44
45#ifdef HAS_CUDA
50
52 if (num_gpu_layers_to_allocate > total_num_model_layers) {
53 Logger::warning("KVCache::initialize: num_gpu_layers_to_allocate (" + std::to_string(num_gpu_layers_to_allocate) +
54 ") > total_num_model_layers (" + std::to_string(total_num_model_layers) +
55 "). Clamping to total_num_model_layers.");
58 }
59
60 size_t cache_elems_per_layer_gpu = static_cast<size_t>(max_seq_len_arg) *
61 static_cast<size_t>(num_kv_heads) *
62 static_cast<size_t>(head_dim);
63
64 size_t fp32_cache_bytes_per_layer_gpu = cache_elems_per_layer_gpu * sizeof(float);
66 size_t num_scales_per_layer_gpu = static_cast<size_t>(max_seq_len_arg) * static_cast<size_t>(num_kv_heads);
68
69 if (cache_elems_per_layer_gpu == 0 && config.use_kvcache_quantization) {
70 throw std::runtime_error(
71 "KVCache (CUDA INT8): Calculated cache elements per layer is zero. Check parameters.");
72 } else if (cache_elems_per_layer_gpu == 0) {
73 throw std::runtime_error(
74 "KVCache (CUDA FP32): Calculated cache elements per layer is zero. Check parameters.");
75 }
76
77 if (config.use_kvcache_quantization) {
78 Logger::info("Allocating INT8 KVCache + FP32 Scales on GPU for " + std::to_string(num_gpu_layers_to_allocate) +
79 " layers. Data size per layer: " +
80 std::to_string(int8_cache_bytes_per_layer_gpu / (1024.0 * 1024.0)) +
81 " MB. Scales size per layer: " +
82 std::to_string(scales_bytes_per_layer_gpu / (1024.0 * 1024.0)) + " MB");
83 } else {
84 Logger::info("Allocating FP32 KVCache on GPU for " + std::to_string(num_gpu_layers_to_allocate) +
85 " layers, size per layer: " +
86 std::to_string(fp32_cache_bytes_per_layer_gpu / (1024.0 * 1024.0)) +
87 " MB");
88 }
89
91 Logger::info("KVCache GPU allocation will target model layers from index " + std::to_string(gpu_layer_start_model_idx) +
92 " to " + std::to_string(gpu_layer_start_model_idx + num_gpu_layers_to_allocate - 1));
93
94 for (int i = 0; i < num_gpu_layers_to_allocate; ++i) {
96
97 if (current_model_idx_for_gpu < 0 || static_cast<size_t>(current_model_idx_for_gpu) >= layers.size()) {
98 Logger::error("KVCache::initialize: Calculated current_model_idx_for_gpu (" + std::to_string(current_model_idx_for_gpu) + ") is out of bounds for layers vector (size " + std::to_string(layers.size()) + "). Skipping this layer.");
99 continue;
100 }
101
104 "KVCache::initialize: Re-initializing KVCache layer " + std::to_string(current_model_idx_for_gpu) + " K dev fp32 pointer without proper destruction?");
106 layers[current_model_idx_for_gpu].k_dev_fp32 = nullptr;
107 }
110 "KVCache::initialize: Re-initializing KVCache layer " + std::to_string(current_model_idx_for_gpu) + " V dev fp32 pointer without proper destruction?");
112 layers[current_model_idx_for_gpu].v_dev_fp32 = nullptr;
113 }
116 "KVCache::initialize: Re-initializing KVCache layer " + std::to_string(current_model_idx_for_gpu) + " K dev quantized pointer without proper destruction?");
118 layers[current_model_idx_for_gpu].k_dev_quantized = nullptr;
119 }
122 "KVCache::initialize: Re-initializing KVCache layer " + std::to_string(current_model_idx_for_gpu) + " V dev quantized pointer without proper destruction?");
124 layers[current_model_idx_for_gpu].v_dev_quantized = nullptr;
125 }
128 "KVCache::initialize: Re-initializing KVCache layer " + std::to_string(current_model_idx_for_gpu) + " K dev scales pointer without proper destruction?");
130 layers[current_model_idx_for_gpu].k_dev_scales = nullptr;
131 }
134 "KVCache::initialize: Re-initializing KVCache layer " + std::to_string(current_model_idx_for_gpu) + " V dev scales pointer without proper destruction?");
136 layers[current_model_idx_for_gpu].v_dev_scales = nullptr;
137 }
138
139 if (config.use_kvcache_quantization) {
144
149 } else {
154 }
155 }
156 Logger::info("KVCache GPU allocation and zeroing complete for " + std::to_string(num_gpu_layers_to_allocate) + " layers.");
157 } else {
158 Logger::info("KVCache: No GPU layers requested for allocation (num_gpu_layers_to_allocate is 0). Skipping GPU KVCache allocation.");
159 this->allocated_num_layers = 0;
160 }
161
162#else
163 Logger::info("KVCache (CPU-only build) initialized with dimensions for " +
164 std::to_string(total_num_model_layers) + " layers, " +
165 std::to_string(max_seq_len_arg) + " seq len, " +
166 std::to_string(num_kv_heads) + " KV heads, " +
167 std::to_string(head_dim) + " head dim");
168#endif
169}
static void warning(const std::string &message)
Definition logger.cpp:139
static void info(const std::string &message)
Definition logger.cpp:135
static void error(const std::string &message)
Definition logger.cpp:143
int max_batch_size
Definition model.h:165
int max_seq_len_config_
Definition model.h:169
int total_model_layers_
Definition model.h:168

References batch_seq_lens, current_batch_size, Logger::error(), Logger::info(), j, layers, max_batch_size, max_seq_len_config_, seq_len, total_model_layers_, and Logger::warning().

Referenced by tinyllama::TinyLlamaSession::TinyLlamaSession().

◆ initialize_batch()

void KVCache::initialize_batch ( int  batch_size)
inline

Initialize batch mode with specified number of sequences.

Parameters
batch_sizeNumber of sequences to process in batch

Definition at line 216 of file model.h.

216 {
218 Logger::warning("Requested batch size " + std::to_string(batch_size) +
219 " exceeds max batch size " + std::to_string(max_batch_size) +
220 ". Using max batch size.");
222 }
224 batch_seq_lens.resize(batch_size, 0);
225 }

References batch_seq_lens, current_batch_size, j, max_batch_size, and Logger::warning().

Referenced by tinyllama::TinyLlamaSession::generate_batch().

Member Data Documentation

◆ batch_seq_lens

std::vector<int> KVCache::batch_seq_lens

Sequence lengths for each sequence in batch

Definition at line 164 of file model.h.

Referenced by clear_data(), initialize(), and initialize_batch().

◆ current_batch_size

int KVCache::current_batch_size = 0

Current number of active sequences

Definition at line 166 of file model.h.

Referenced by clear_data(), initialize(), and initialize_batch().

◆ layers

std::vector<KVCacheLayer> KVCache::layers

KV cache for each layer

Definition at line 158 of file model.h.

Referenced by clear_data(), and initialize().

◆ max_batch_size

int KVCache::max_batch_size = 1

Maximum number of sequences that can be cached

Definition at line 165 of file model.h.

Referenced by initialize(), and initialize_batch().

◆ max_seq_len_config_

int KVCache::max_seq_len_config_ = 0

Store the original max_seq_len

Definition at line 169 of file model.h.

Referenced by initialize().

◆ seq_len

int KVCache::seq_len = 0

Current sequence length (single-sequence mode)

Definition at line 161 of file model.h.

Referenced by clear_data(), tinyllama::TinyLlamaSession::generate(), tinyllama::TinyLlamaSession::generate_batch(), initialize(), and tinyllama::TinyLlamaSession::score_rows().

◆ total_model_layers_

int KVCache::total_model_layers_ = 0

Total number of layers in the model

Definition at line 168 of file model.h.

Referenced by initialize().


The documentation for this struct was generated from the following files:
