ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
distributed_main.cpp File Reference

Distributed inference main program for TinyLlama. More...

#include <iostream>
#include <string>
#include <thread>
#include <chrono>
#include <signal.h>
#include <atomic>
#include "distributed_coordinator.h"
#include "logger.h"
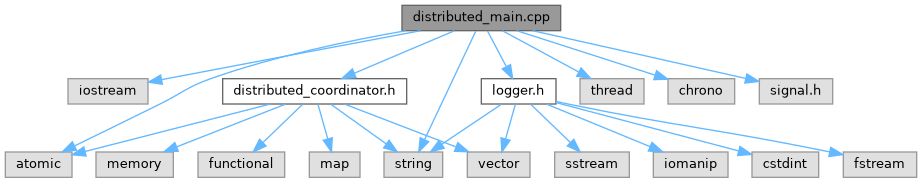
Include dependency graph for distributed_main.cpp:

Go to the source code of this file.

Functions

void signal_handler (int signal)
 
void print_usage (const char *program_name)
 
DistributedCoordinator::NodeRole parse_role (const std::string &role_str)
 
void run_interactive_master (DistributedCoordinator &coordinator)
 
int main (int argc, char *argv[])
 

Variables

std::atomic< bool > shutdown_requested {false}
 

Detailed Description

Distributed inference main program for TinyLlama.

This program provides distributed inference capabilities using MPI. It can run as either a master node (coordinating requests) or worker nodes (processing inference requests).

Usage:

*   mpirun -np 4 ./tinyllama_distributed <model_path> <tokenizer_path> <role> [gpu_layers]
* 

Arguments: model_path: Path to the model file (.gguf) or directory (SafeTensors). tokenizer_path: Path to the tokenizer file. role: Node role - "master", "worker", or "hybrid" gpu_layers: (Optional) Number of layers to offload to GPU. Default: -1 (all layers)

Examples:

Run with 4 nodes (1 master, 3 workers)

mpirun -np 4 ./tinyllama_distributed ./models/model.gguf ./models/tokenizer.model worker -1

Run with hybrid nodes (all can be master or worker)

mpirun -np 4 ./tinyllama_distributed ./models/model.gguf ./models/tokenizer.model hybrid -1

Environment Variables: TINYLLAMA_LOG_LEVEL: Set logging level (DEBUG, INFO, WARNING, ERROR)

Definition in file distributed_main.cpp.

Function Documentation

◆ main()

int main ( int  argc,
char *  argv[] 
)

Definition at line 173 of file distributed_main.cpp.

173 {
174 // Set up signal handlers
177
178 // Parse command line arguments
179 if (argc < 4) {
180 print_usage(argv[0]);
181 return 1;
182 }
183
184 std::string model_path = argv[1];
185 std::string tokenizer_path = argv[2];
186 std::string role_str = argv[3];
187 int gpu_layers = (argc > 4) ? std::stoi(argv[4]) : -1;
188
189 // Set up logging
190 const char* log_level_env = std::getenv("TINYLLAMA_LOG_LEVEL");
191 if (log_level_env) {
192 std::string log_level(log_level_env);
193 if (log_level == "DEBUG") {
195 } else if (log_level == "INFO") {
197 } else if (log_level == "WARNING") {
199 } else if (log_level == "ERROR") {
201 }
202 }
203
204 try {
205 // Parse role
207
208 // Create distributed coordinator
210
211 // Initialize MPI and discover cluster
212 if (!coordinator.initialize()) {
213 std::cerr << "Failed to initialize distributed coordinator" << std::endl;
214 return 1;
215 }
216
217 int rank = coordinator.get_rank();
218 int size = coordinator.get_size();
219
220 Logger::log("Node " + std::to_string(rank) + "/" + std::to_string(size) +
221 " initialized with role: " + role_str, Logger::INFO);
222
223 // Run based on role and rank
224 if (role == DistributedCoordinator::NodeRole::MASTER ||
225 (role == DistributedCoordinator::NodeRole::HYBRID && rank == 0)) {
226
227 // Master node - handle interactive input and coordinate requests
228 std::thread master_thread([&coordinator]() {
229 coordinator.run_master();
230 });
231
232 // Run interactive interface on main thread
234
235 // Signal shutdown and wait for master thread
236 shutdown_requested = true;
237 master_thread.join();
238
239 } else if (role == DistributedCoordinator::NodeRole::WORKER ||
240 role == DistributedCoordinator::NodeRole::HYBRID) {
241
242 // Worker node - process incoming requests
243 Logger::log("Starting worker mode", Logger::INFO);
244 coordinator.run_worker();
245 }
246
247 // Cleanup
248 coordinator.shutdown();
249 Logger::log("Node shutdown complete", Logger::INFO);
250
251 } catch (const std::exception& e) {
252 std::cerr << "Error: " << e.what() << std::endl;
253 return 1;
254 }
255
256 return 0;
257}
static void set_level(Level new_level)
Definition logger.cpp:34
Distributed coordinator for multi-node LLM inference.
std::atomic< bool > shutdown_requested
void run_interactive_master(DistributedCoordinator &coordinator)
void signal_handler(int signal)
void print_usage(const char *program_name)
DistributedCoordinator::NodeRole parse_role(const std::string &role_str)
size_t j

References Logger::DEBUG, Logger::ERROR, Logger::INFO, j, parse_role(), print_usage(), run_interactive_master(), Logger::set_level(), shutdown_requested, signal_handler(), and Logger::WARNING.

◆ parse_role()

Definition at line 68 of file distributed_main.cpp.

68 {
69 if (role_str == "master") {
70 return DistributedCoordinator::NodeRole::MASTER;
71 } else if (role_str == "worker") {
72 return DistributedCoordinator::NodeRole::WORKER;
73 } else if (role_str == "hybrid") {
74 return DistributedCoordinator::NodeRole::HYBRID;
75 } else {
76 throw std::invalid_argument("Invalid role: " + role_str + ". Must be 'master', 'worker', or 'hybrid'");
77 }
78}

References j.

Referenced by main().

◆ print_usage()

void print_usage ( const char *  program_name)

Definition at line 53 of file distributed_main.cpp.

53 {
54 std::cout << "Usage: " << program_name << " <model_path> <tokenizer_path> <role> [gpu_layers]\n"
55 << "\n"
56 << "Arguments:\n"
57 << " model_path Path to the model file (.gguf) or directory (SafeTensors)\n"
58 << " tokenizer_path Path to the tokenizer file\n"
59 << " role Node role: 'master', 'worker', or 'hybrid'\n"
60 << " gpu_layers (Optional) Number of GPU layers (-1 for all, 0 for none). Default: -1\n"
61 << "\n"
62 << "Examples:\n"
63 << " mpirun -np 4 " << program_name << " ./model.gguf ./tokenizer.model worker -1\n"
64 << " mpirun -np 4 " << program_name << " ./model.gguf ./tokenizer.model hybrid 32\n"
65 << std::endl;
66}

References j.

Referenced by main().

◆ run_interactive_master()

void run_interactive_master ( DistributedCoordinator &  coordinator)

Definition at line 80 of file distributed_main.cpp.

80 {
81 std::cout << "\n=== TinyLlama Distributed Inference (Master Node) ===" << std::endl;
82 std::cout << "Type 'quit' to exit, 'status' for cluster status, or enter prompts for inference." << std::endl;
83 std::cout << "Cluster info:" << std::endl;
84
85 auto cluster_info = coordinator.get_cluster_info();
86 for (const auto& node : cluster_info) {
87 std::cout << " Node " << node.rank << " (" << node.hostname << "): ";
88 switch (node.role) {
89 case DistributedCoordinator::NodeRole::MASTER:
90 std::cout << "MASTER";
91 break;
92 case DistributedCoordinator::NodeRole::WORKER:
93 std::cout << "WORKER";
94 break;
95 case DistributedCoordinator::NodeRole::HYBRID:
96 std::cout << "HYBRID";
97 break;
98 }
99 std::cout << ", GPU: " << (node.has_gpu ? "yes" : "no")
100 << ", Layers: " << node.gpu_layers << std::endl;
101 }
102 std::cout << std::endl;
103
104 std::string input;
105 int request_counter = 0;
106
107 while (!shutdown_requested) {
108 std::cout << "tinyllama> ";
109 std::getline(std::cin, input);
110
111 if (input.empty()) continue;
112
113 if (input == "quit" || input == "exit") {
114 break;
115 }
116
117 if (input == "status") {
118 auto stats = coordinator.get_load_stats();
119 std::cout << "Cluster Status:" << std::endl;
120 std::cout << " Total requests: " << stats.total_requests << std::endl;
121 std::cout << " Completed: " << stats.completed_requests << std::endl;
122 std::cout << " Failed: " << stats.failed_requests << std::endl;
123 std::cout << " Active requests per node:" << std::endl;
124 for (const auto& pair : stats.requests_per_node) {
125 std::cout << " Node " << pair.first << ": " << pair.second << std::endl;
126 }
127 continue;
128 }
129
130 // Create inference request
132 request.request_id = "req_" + std::to_string(++request_counter);
133 request.prompt = input;
134 request.max_tokens = 256;
135 request.temperature = 0.1f;
136 request.top_k = 40;
137 request.top_p = 0.9f;
138 request.system_prompt = "";
139
140 std::cout << "Processing request..." << std::endl;
141 auto start_time = std::chrono::high_resolution_clock::now();
142
143 // Submit request
144 bool submitted = coordinator.submit_request(request,
146 auto end_time = std::chrono::high_resolution_clock::now();
147 auto total_time = std::chrono::duration_cast<std::chrono::milliseconds>(end_time - start_time);
148
149 std::cout << "\n--- Response ---" << std::endl;
150 if (result.success) {
151 std::cout << result.generated_text << std::endl;
152 std::cout << "\nStats:" << std::endl;
153 std::cout << " Tokens: " << result.tokens_generated << std::endl;
154 std::cout << " Inference time: " << result.inference_time_ms << "ms" << std::endl;
155 std::cout << " Total time: " << total_time.count() << "ms" << std::endl;
156 std::cout << " Processed by node: " << result.processing_node << std::endl;
157 } else {
158 std::cout << "Error: " << result.error_message << std::endl;
159 }
160 std::cout << "tinyllama> ";
161 std::cout.flush();
162 });
163
164 if (!submitted) {
165 std::cout << "Failed to submit request!" << std::endl;
166 }
167
168 // Give some time for the request to be processed
169 std::this_thread::sleep_for(std::chrono::milliseconds(100));
170 }
171}

References j, tinyllama::DistributedCoordinator::InferenceRequest::request_id, and shutdown_requested.

Referenced by main().

◆ signal_handler()

void signal_handler ( int  signal)

Definition at line 46 of file distributed_main.cpp.

46 {
47 if (signal == SIGINT || signal == SIGTERM) {
48 std::cout << "\nShutdown requested..." << std::endl;
49 shutdown_requested = true;
50 }
51}

References j, and shutdown_requested.

Referenced by main().

Variable Documentation

◆ shutdown_requested

std::atomic<bool> shutdown_requested {false}

Definition at line 44 of file distributed_main.cpp.

44{false};

Referenced by main(), run_interactive_master(), and signal_handler().