ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
main.cpp File Reference

Command-line interface for TinyLlama text generation. More...

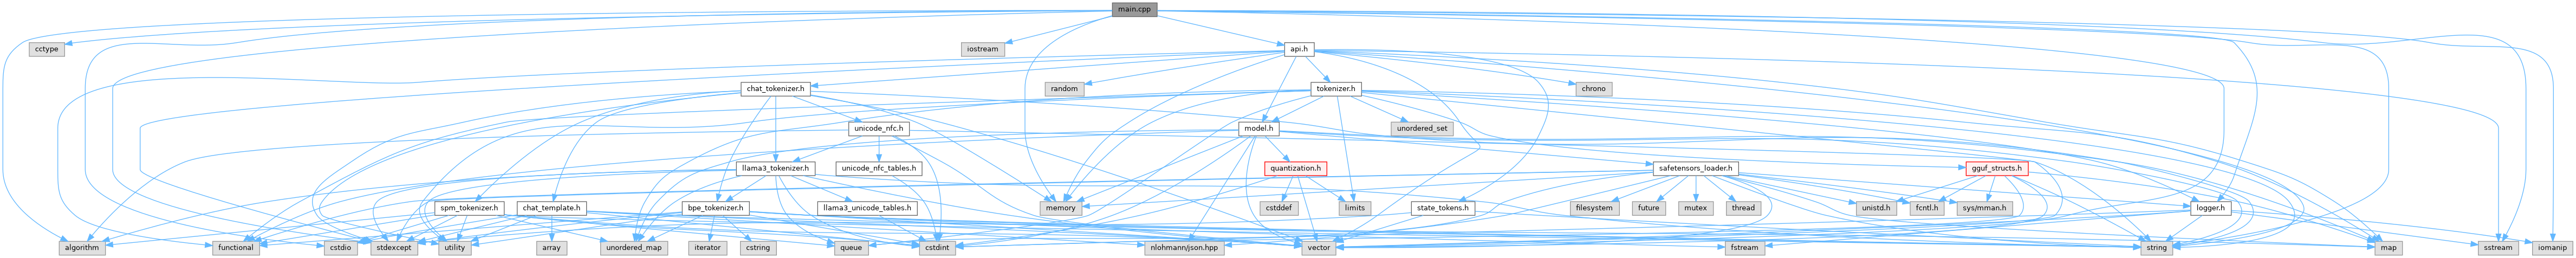
#include <algorithm>
#include <cctype>
#include <cstdio>
#include <iomanip>
#include <iostream>
#include <memory>
#include <sstream>
#include <stdexcept>
#include <string>
#include <vector>
#include "api.h"
#include "logger.h"
Include dependency graph for main.cpp:

Go to the source code of this file.

Functions

std::string trim_whitespace (const std::string &s)
 
void print_usage (const char *program_name)
 
int main (int argc, char **argv)
 

Detailed Description

Command-line interface for TinyLlama text generation.

This program provides a command-line interface for generating text using TinyLlama models. It supports both GGUF and SafeTensors model formats. The program automatically applies Q:A formatting to prompts, which is required for proper model responses in both formats.

Usage:

*   tinyllama <model_path> <tokenizer_path> <num_threads> <prompt|chat|batch> [--system-prompt <system_prompt_string>] [initial_user_prompt] [max_tokens] [n_gpu_layers] [use_mmap] [temperature] [top_k] [top_p] [use_kv_quant] [use_batch_generation] [--batch-prompts "prompt1" "prompt2" ...] [--max-batch-size N]
* 

Arguments: model_path: Path to the model file (.gguf) or directory (SafeTensors). tokenizer_path: Path to the tokenizer file. num_threads: Number of threads to use for generation. prompt|chat|batch: 'prompt' for single prompt generation, 'chat' for interactive chat mode, 'batch' for batch processing. –system-prompt: (Optional) System prompt to guide the model. Default: empty. initial_user_prompt: (Optional) Initial user prompt string. Default: "Hello, world!" max_tokens: (Optional) Maximum number of tokens to generate. Default: 256 n_gpu_layers: (Optional) Number of layers to offload to GPU (-1 for all, 0 for none). Default: -1 (all layers on GPU if available) use_mmap: (Optional) Use mmap for GGUF files ('true' or 'false'). Default: true temperature: (Optional) Sampling temperature (e.g., 0.1). Lower is more deterministic. Default: 0.1 top_k: (Optional) Top-K sampling parameter (0 to disable). Default: 40 top_p: (Optional) Top-P/nucleus sampling parameter (0.0-1.0). Default: 0.9 use_kv_quant: (Optional) Use INT8 KVCache quantization on GPU ('true' or 'false'). Default: false use_batch_generation: (Optional) Use GPU batch generation for tokens ('true' or 'false'). Default: false –batch-prompts: (For batch mode) Multiple prompts in quotes, e.g., "prompt1" "prompt2" ... –max-batch-size: (For batch mode) Maximum batch size. Default: 8

Example: ./tinyllama ./models/model.gguf ./models/tokenizer.model 4 prompt –system-prompt "You are a helpful assistant." "What is the capital of France?" 128 0 true 0.1 40 0.9 true

Note: The program may automatically apply Q:A formatting to prompts (e.g., "Q: [prompt]\nA:") depending on the model type, as this can be required for proper responses.

Definition in file main.cpp.

Function Documentation

◆ main()

int main ( int  argc,
char **  argv 
)

Definition at line 89 of file main.cpp.

89 {
90 if (argc > 1 && (std::string(argv[1]) == "-h" || std::string(argv[1]) == "--help")) {
91 print_usage(argv[0]);
92 return 0;
93 }
94
95 if (argc < 5) { // Minimum required: model_path, tokenizer_path, num_threads, mode
96 std::cerr << "ERROR: Missing required arguments." << std::endl;
97 print_usage(argv[0]);
98 return 1;
99 }
100
101 std::string model_path_or_dir = argv[1];
102 std::string tokenizer_path = argv[2];
103 int num_threads = 4; // Default, will be overwritten if provided by argv[3]
104 try {
105 if (argc > 3) { // Ensure argv[3] (number of threads) exists
106 num_threads = std::stoi(argv[3]);
107 } else {
108 Logger::warning("Number of threads not provided, using default: " + std::to_string(num_threads));
109 }
110 } catch (const std::exception& e) {
111 Logger::warning("Could not parse num_threads from argv[3]: '" + (argc > 3 ? std::string(argv[3]) : "<not provided>") + "'. Using default: " + std::to_string(num_threads));
112 }
113
114 if (argc < 5) { // Check after attempting to parse num_threads
115 std::cerr << "ERROR: Missing mode argument (prompt|chat|batch) after num_threads." << std::endl;
116 print_usage(argv[0]);
117 return 1;
118 }
119 std::string mode_str = argv[4]; // Mode (prompt|chat|batch) is argv[4]
120
121 std::string system_prompt_str = ""; // Default empty system prompt
122 std::string user_prompt_str = "Hello, world!"; // Default user prompt
123 int max_tokens = 256; // Default for steps
124 int n_gpu_layers = -1; // Default: all layers on GPU
125 bool use_mmap = true; // Default: use mmap
126 bool use_kv_quant = false; // Default: do not use KVCache quantization
127 bool use_batch_generation = false; // Default: do not use batch generation
128
129 // Batch processing specific variables
130 std::vector<std::string> batch_prompts;
131 int max_batch_size = 8; // Default max batch size
132
133 // Default sampling params for generate
134 float temperature = 0.1f; // Default temperature
135 int top_k = 40; // Default top-k sampling parameter
136 float top_p = 0.9f; // Default top-p/nucleus sampling parameter
137 float rep_penalty = -1.0f; // <=0: keep the engine default (1.3); 1.0 disables
138 bool raw_prompt = false; // --raw-prompt: no internal Q&A wrap (see below)
139
140 int current_arg_idx = 5;
141 while(current_arg_idx < argc) {
142 std::string arg = argv[current_arg_idx];
143 if (arg == "--system-prompt" || arg == "-sp") {
144 if (current_arg_idx + 1 < argc) {
146 current_arg_idx += 2;
147 } else {
148 std::cerr << "ERROR: --system-prompt requires a value." << std::endl;
149 print_usage(argv[0]);
150 return 1;
151 }
152 } else if (arg == "--max-tokens" || arg == "-mt") {
153 if (current_arg_idx + 1 < argc) {
154 try { max_tokens = std::stoi(argv[current_arg_idx+1]); }
155 catch (const std::exception& e) { Logger::error("Invalid max_tokens: " + std::string(argv[current_arg_idx+1])); }
156 current_arg_idx += 2;
157 } else { std::cerr << "ERROR: --max-tokens requires a value." << std::endl; return 1;}
158 } else if (arg == "--n-gpu-layers" || arg == "-ngl") {
159 if (current_arg_idx + 1 < argc) {
160 try { n_gpu_layers = std::stoi(argv[current_arg_idx+1]); }
161 catch (const std::exception& e) { Logger::error("Invalid n_gpu_layers: " + std::string(argv[current_arg_idx+1])); }
162 current_arg_idx += 2;
163 } else { std::cerr << "ERROR: --n-gpu-layers requires a value." << std::endl; return 1;}
164 } else if (arg == "--use-mmap") {
165 if (current_arg_idx + 1 < argc) {
166 std::string mmap_str_val = argv[current_arg_idx+1];
167 std::transform(mmap_str_val.begin(), mmap_str_val.end(), mmap_str_val.begin(), ::tolower);
168 if (mmap_str_val == "false" || mmap_str_val == "0") use_mmap = false;
169 else if (mmap_str_val == "true" || mmap_str_val == "1") use_mmap = true;
170 else { std::cerr << "ERROR: Invalid use_mmap value." << std::endl; return 1; }
171 current_arg_idx += 2;
172 } else { std::cerr << "ERROR: --use-mmap requires a value." << std::endl; return 1;}
173 } else if (arg == "--temperature" || arg == "-t") {
174 if (current_arg_idx + 1 < argc) {
175 try { temperature = std::stof(argv[current_arg_idx+1]); }
176 catch (const std::exception& e) { Logger::error("Invalid temperature: " + std::string(argv[current_arg_idx+1]));}
177 current_arg_idx += 2;
178 } else { std::cerr << "ERROR: --temperature requires a value." << std::endl; return 1;}
179 } else if (arg == "--top-k" || arg == "-k") {
180 if (current_arg_idx + 1 < argc) {
181 try { top_k = std::stoi(argv[current_arg_idx+1]); }
182 catch (const std::exception& e) { Logger::error("Invalid top_k: " + std::string(argv[current_arg_idx+1])); }
183 current_arg_idx += 2;
184 } else { std::cerr << "ERROR: --top-k requires a value." << std::endl; return 1;}
185 } else if (arg == "--top-p" || arg == "-p") {
186 if (current_arg_idx + 1 < argc) {
187 try { top_p = std::stof(argv[current_arg_idx+1]); }
188 catch (const std::exception& e) { Logger::error("Invalid top_p: " + std::string(argv[current_arg_idx+1])); }
189 current_arg_idx += 2;
190 } else { std::cerr << "ERROR: --top-p requires a value." << std::endl; return 1;}
191 } else if (arg == "--raw-prompt") {
192 raw_prompt = true;
193 current_arg_idx += 1;
194 } else if (arg == "--rep-penalty" || arg == "-rp") {
195 if (current_arg_idx + 1 < argc) {
196 try { rep_penalty = std::stof(argv[current_arg_idx+1]); }
197 catch (const std::exception& e) { Logger::error("Invalid rep_penalty: " + std::string(argv[current_arg_idx+1])); }
198 current_arg_idx += 2;
199 } else { std::cerr << "ERROR: --rep-penalty requires a value." << std::endl; return 1;}
200 } else if (arg == "--use-kv-quant" || arg == "-kvq") {
201 if (current_arg_idx + 1 < argc) {
202 std::string kvq_str_val = argv[current_arg_idx+1];
203 std::transform(kvq_str_val.begin(), kvq_str_val.end(), kvq_str_val.begin(), ::tolower);
204 if (kvq_str_val == "false" || kvq_str_val == "0") use_kv_quant = false;
205 else if (kvq_str_val == "true" || kvq_str_val == "1") use_kv_quant = true;
206 else { std::cerr << "ERROR: Invalid use_kv_quant value: " << argv[current_arg_idx+1] << std::endl; return 1; }
207 current_arg_idx += 2;
208 } else { std::cerr << "ERROR: --use-kv-quant requires a value." << std::endl; return 1;}
209 } else if (arg == "--use-batch-generation" || arg == "-ubg") {
210 if (current_arg_idx + 1 < argc) {
211 std::string ubg_str_val = argv[current_arg_idx+1];
212 std::transform(ubg_str_val.begin(), ubg_str_val.end(), ubg_str_val.begin(), ::tolower);
213 if (ubg_str_val == "false" || ubg_str_val == "0") use_batch_generation = false;
214 else if (ubg_str_val == "true" || ubg_str_val == "1") use_batch_generation = true;
215 else { std::cerr << "ERROR: Invalid use_batch_generation value: " << argv[current_arg_idx+1] << std::endl; return 1; }
216 current_arg_idx += 2;
217 } else { std::cerr << "ERROR: --use-batch-generation requires a value." << std::endl; return 1;}
218 } else if (arg == "--batch-prompts" || arg == "-bp") {
219 current_arg_idx++; // Move past the --batch-prompts argument
220 while (current_arg_idx < argc && argv[current_arg_idx][0] != '-') {
221 batch_prompts.push_back(std::string(argv[current_arg_idx]));
223 }
224 if (batch_prompts.empty()) {
225 std::cerr << "ERROR: --batch-prompts requires at least one prompt." << std::endl;
226 return 1;
227 }
228 } else if (arg == "--max-batch-size" || arg == "-mbs") {
229 if (current_arg_idx + 1 < argc) {
230 try { max_batch_size = std::stoi(argv[current_arg_idx+1]); }
231 catch (const std::exception& e) { Logger::error("Invalid max_batch_size: " + std::string(argv[current_arg_idx+1])); }
232 current_arg_idx += 2;
233 } else { std::cerr << "ERROR: --max-batch-size requires a value." << std::endl; return 1;}
234 } else {
235 if (user_prompt_str == "Hello, world!") {
237 } else if (argv[current_arg_idx][0] != '-') {
238 std::cerr << "ERROR: Unexpected positional argument: " << argv[current_arg_idx] << std::endl;
239 print_usage(argv[0]);
240 return 1;
241 } else {
242 std::cerr << "ERROR: Unknown option: " << argv[current_arg_idx] << std::endl;
243 print_usage(argv[0]);
244 return 1;
245 }
247 }
248 }
249
250 Logger::info("Using model path/directory: " + model_path_or_dir);
251 Logger::info("Tokenizer path: " + tokenizer_path);
252 Logger::info("Num threads: " + std::to_string(num_threads));
253 Logger::info("Mode: " + mode_str);
254 Logger::info("System Prompt: \"" + system_prompt_str + "\"");
255 Logger::info("Default User Prompt: \"" + user_prompt_str + "\"");
256 Logger::info("Max tokens: " + std::to_string(max_tokens));
257 Logger::info("N GPU Layers: " + std::to_string(n_gpu_layers));
258 Logger::info(std::string("Use mmap: ") + (use_mmap ? "true" : "false"));
259 Logger::info("Temperature: " + std::to_string(temperature));
260 Logger::info("Top-K: " + std::to_string(top_k));
261 Logger::info("Top-P: " + std::to_string(top_p));
262 Logger::info(std::string("Use KVCache Quantization: ") + (use_kv_quant ? "true" : "false"));
263 Logger::info(std::string("Use Batch Generation: ") + (use_batch_generation ? "true" : "false"));
264
265 try {
266 // For batch mode, we need to determine max_batch_size before creating session
267 int session_max_batch_size = (mode_str == "batch") ? max_batch_size : 1;
269
271 Logger::info("TinyLlamaSession initialized successfully.");
272 if (rep_penalty > 0.0f) {
273 session.set_repetition_penalty(rep_penalty);
274 Logger::info("Repetition penalty overridden to " + std::to_string(rep_penalty));
275 }
276
277 const ModelConfig& config = session.get_config();
278 bool apply_qa_formatting_decision; // This will be true if no advanced template is used
279
280 if (config.tokenizer_family == ModelConfig::TokenizerFamily::LLAMA3_TIKTOKEN || \
281 (session.get_tokenizer() && !session.get_tokenizer()->get_gguf_chat_template().empty())) { // Use getter
282 apply_qa_formatting_decision = false; // Llama 3 or GGUF template handles formatting
283 Logger::info("[Main.cpp] Llama 3 model or GGUF chat template detected. Internal Q&A prompt formatting will be DISABLED.");
284 } else {
285 apply_qa_formatting_decision = true; // Default for other models without GGUF template
286 Logger::info("[Main.cpp] Non-Llama 3 model and no GGUF chat template. Internal Q&A prompt formatting will be ENABLED.");
287 }
288 if (raw_prompt) {
289 // The legacy "Q: ... \nA:" wrap injects UNKs at the answer boundary on
290 // word-level models whose vocab lacks "Q:"/"A:" (found 2026-07-21:
291 // TinyChat evals conditioned on garbage exactly where the reply
292 // starts). --raw-prompt sends the prompt verbatim.
294 Logger::info("[Main.cpp] --raw-prompt: internal Q&A formatting DISABLED.");
295 }
296
297 Logger::info("[Main.cpp] Mode: '" + mode_str + "'. Final decision for apply_qa_formatting_decision: " + std::string(apply_qa_formatting_decision ? "true" : "false"));
298
299 if (mode_str == "prompt") {
300 std::string generated_text =
301 session.generate(user_prompt_str, max_tokens, temperature, top_k, top_p, system_prompt_str, apply_qa_formatting_decision);
302 std::cout << generated_text << std::endl;
303 } else if (mode_str == "chat") {
304 std::cout << "Entering chat mode. System Prompt: \"" << system_prompt_str << "\". Type 'exit', 'quit' to end." << std::endl;
305 std::string current_user_message;
306
307 if (!user_prompt_str.empty() && (user_prompt_str != "Hello, world!" || !system_prompt_str.empty() )) {
309 std::cout << "You: " << current_user_message << std::endl;
310 std::string ai_response = session.generate(current_user_message, max_tokens, temperature, top_k, top_p, system_prompt_str, apply_qa_formatting_decision);
311 std::cout << "AI: " << ai_response << std::endl;
312 }
313
314 while (true) {
315 std::cout << "You: ";
316 std::getline(std::cin, current_user_message);
317 if (current_user_message == "exit" || current_user_message == "quit") {
318 break;
319 }
320 if (current_user_message.empty()) {
321 continue;
322 }
323 std::string ai_response = session.generate(current_user_message, max_tokens, temperature, top_k, top_p, system_prompt_str, apply_qa_formatting_decision);
324 std::cout << "AI: " << ai_response << std::endl;
325 }
326 } else if (mode_str == "batch") {
327 // Batch processing logic
328 if (batch_prompts.empty()) {
329 std::cerr << "ERROR: Batch mode requires prompts. Use --batch-prompts \"prompt1\" \"prompt2\" ..." << std::endl;
330 print_usage(argv[0]);
331 return 1;
332 }
333
334 if (batch_prompts.size() > static_cast<size_t>(max_batch_size)) {
335 std::cerr << "ERROR: Number of prompts (" << batch_prompts.size()
336 << ") exceeds max batch size (" << max_batch_size << ")" << std::endl;
337 return 1;
338 }
339
340 Logger::info("[Batch Mode] Processing " + std::to_string(batch_prompts.size()) + " prompts in batch...");
341
342 try {
343 std::vector<std::string> results = session.generate_batch(
344 batch_prompts, max_tokens, temperature, top_k, top_p,
346 );
347
348 std::cout << "\n" << std::string(80, '=') << std::endl;
349 std::cout << "BATCH PROCESSING RESULTS" << std::endl;
350 std::cout << std::string(80, '=') << std::endl;
351
352 for (size_t i = 0; i < batch_prompts.size(); ++i) {
353 std::cout << "\n--- Prompt " << (i + 1) << " ---" << std::endl;
354 std::cout << "Input: " << batch_prompts[i] << std::endl;
355 std::cout << "Output: " << results[i] << std::endl;
356 }
357
358 } catch (const std::exception& e) {
359 Logger::error("[Batch Mode] Error during batch processing: " + std::string(e.what()));
360 return 1;
361 }
362 } else {
363 std::cerr << "ERROR: Invalid mode '" << mode_str << "'. Expected 'prompt', 'chat', or 'batch'." << std::endl;
364 print_usage(argv[0]);
365 return 1;
366 }
367
368 } catch (const std::exception& e) {
369 Logger::error("Error: " + std::string(e.what()));
370 return 1;
371 }
372
373 return 0;
374}
static void warning(const std::string &message)
Definition logger.cpp:139
static void info(const std::string &message)
Definition logger.cpp:135
static void error(const std::string &message)
Definition logger.cpp:143
Represents an active TinyLlama session holding the loaded model and tokenizer.
Definition api.h:85
size_t j
std::string trim_whitespace(const std::string &s)
Definition main.cpp:55
void print_usage(const char *program_name)
Definition main.cpp:64
Model configuration structure holding architecture and hyperparameters.
Definition model.h:82

References Logger::error(), Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, print_usage(), trim_whitespace(), and Logger::warning().

◆ print_usage()

void print_usage ( const char *  program_name)

Definition at line 64 of file main.cpp.

64 {
65 std::cout << "Usage: " << program_name
66 << " <model_path> <tokenizer_path> <num_threads> <prompt|chat|batch> "
67 "[--system-prompt <system_prompt_string>] [initial_user_prompt] [max_tokens] [n_gpu_layers] [use_mmap] [temperature] [top_k] [top_p] [use_kv_quant] [use_batch_generation] [--batch-prompts \"prompt1\" \"prompt2\" ...] [--max-batch-size N]"
68 << std::endl;
69 std::cout << "\nArguments:\n"
70 " model_path : Path to the model file (.gguf) or directory (SafeTensors).\n"
71 " tokenizer_path : Path to the tokenizer file.\n"
72 " num_threads : Number of threads to use for generation.\n"
73 " prompt|chat|batch : 'prompt' for single prompt, 'chat' for chat mode, 'batch' for batch processing.\n"
74 " --system-prompt : (Optional) System prompt to guide the model. Default: empty.\n"
75 " initial_user_prompt : (Optional) Initial user prompt string. Default: \"Hello, world!\".\n"
76 " max_tokens : (Optional) Maximum number of tokens to generate. Default: 256.\n"
77 " n_gpu_layers : (Optional) Number of layers to offload to GPU (-1 for all, 0 for none). Default: -1.\n"
78 " use_mmap : (Optional) Use mmap for GGUF files ('true' or 'false'). Default: true.\n"
79 " temperature : (Optional) Sampling temperature. Default: 0.1.\n"
80 " top_k : (Optional) Top-K sampling parameter (0 to disable). Default: 40.\n"
81 " top_p : (Optional) Top-P/nucleus sampling parameter (0.0-1.0). Default: 0.9.\n"
82 " use_kv_quant : (Optional) Use INT8 KVCache quantization on GPU ('true' or 'false'). Default: false.\n"
83 " use_batch_generation: (Optional) Use GPU batch generation for tokens ('true' or 'false'). Default: false.\n"
84 " --batch-prompts : (For batch mode) Multiple prompts in quotes, e.g., \"prompt1\" \"prompt2\" ...\n"
85 " --max-batch-size : (For batch mode) Maximum batch size. Default: 8.\n"
86 << std::endl;
87}

References j.

Referenced by main().

◆ trim_whitespace()

std::string trim_whitespace ( const std::string &  s)

Definition at line 55 of file main.cpp.

55 {
56 auto start = std::find_if_not(
57 s.begin(), s.end(), [](unsigned char c) { return std::isspace(c); });
58 auto end = std::find_if_not(s.rbegin(), s.rend(), [](unsigned char c) {
59 return std::isspace(c);
60 }).base();
61 return (start < end ? std::string(start, end) : std::string());
62}
float c

References c, and j.

Referenced by main().