ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
utils.cpp File Reference
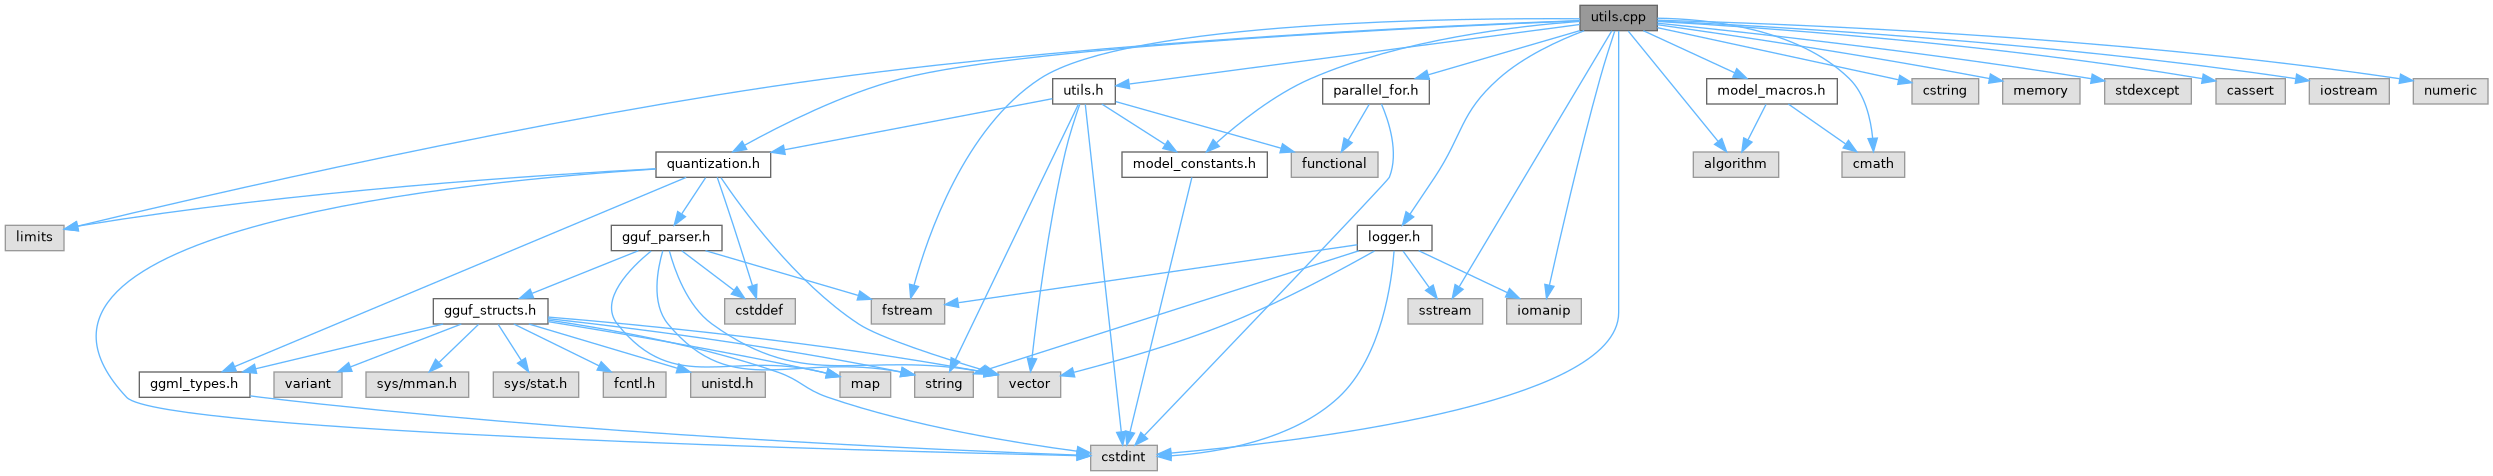
#include "utils.h"
#include "parallel_for.h"
#include "logger.h"
#include "quantization.h"
#include "model_constants.h"
#include "model_macros.h"
#include <algorithm>
#include <cmath>
#include <cstring>
#include <fstream>
#include <iomanip>
#include <limits>
#include <memory>
#include <sstream>
#include <stdexcept>
#include <cassert>
#include <cstdint>
#include <iostream>
#include <numeric>
Include dependency graph for utils.cpp:

Go to the source code of this file.

Functions

float simd_dot_product (const float *a, const float *b, int n)
 
void simd_scaled_add (float *dst, const float *src, float scale, int n)
 
uint16_t float32_to_bfloat16 (float val)
 
float bfloat16_to_float32 (uint16_t bf16)
 
std::vector< float > bfloat16_vector_to_float32 (const std::vector< uint16_t > &bf16_vec)
 
std::vector< uint16_t > uint8_vector_to_uint16_vector (const std::vector< uint8_t > &bytes, size_t numel)
 
int argmax (const std::vector< float > &v)
 
std::vector< float > bf16vec_to_float_vec (const std::vector< uint16_t > &v_bf16)
 
void log_vector_summary (const std::string &name, const std::vector< float > &v, int head_count)
 
void log_vector_summary_with_tail (const std::string &name, const std::vector< float > &v, int head_count, int tail_count)
 
void matvec_q8_0_f32_vector_cpu (const std::vector< block_q8_0 > &mat_q8_0, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
 
static double dot_f32_as_f64 (const float *a, const float *b, int n)
 
void matvec_f32_f32_vector_cpu (const std::vector< float > &mat_f32, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols)
 
void matvec_q8k_f32_vector_cpu (const std::vector< block_q8_K > &mat_q8k, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
 
void apply_rope_vector (std::vector< float > &x, int num_heads, int head_dim, int current_token_pos, const std::vector< std::pair< float, float > > &all_freqs_cis, int max_pos_embeddings, bool use_adjacent_pairing)
 
void apply_rope_batch_cpu (std::vector< float > &q_batch, std::vector< float > &k_batch, int num_tokens, int num_q_heads, int num_kv_heads, int head_dim, int start_pos_in_sequence, const std::vector< std::pair< float, float > > &all_freqs_cis, int max_pos_embeddings, bool use_adjacent_pairing)
 
void rmsnorm_batch_cpu (const std::vector< float > &x_batch, const std::vector< float > &weight, std::vector< float > &out_batch, int num_tokens, int hidden_size, float eps)
 
void rmsnorm_vector_cpu (const std::vector< float > &x, const std::vector< float > &weight, std::vector< float > &out, float eps)
 
void softmax_vector_cpu (const std::vector< float > &x, std::vector< float > &out)
 
void moe_ffn_f32_cpu (const float *x, int d, int d_ff, int E, int k, const float *router, const float *gate_exps, const float *up_exps, const float *down_exps, float *out, bool renorm)
 
void moe_ffn_routed_f32_cpu (const float *x, int d, int d_ff, int E, int k, const float *router, const float *gate_exps, const float *up_exps, const float *down_exps, float *out, bool renorm, bool sigmoid, const float *bias, int groups_n, int groups_top)
 
void silu_cpu (const std::vector< float > &x, std::vector< float > &out)
 
void gelu_cpu (const std::vector< float > &x, std::vector< float > &out)
 
void gelu_new_cpu (const std::vector< float > &x, std::vector< float > &out)
 
void matmul_f32_f32_batch_cpu (const std::vector< float > &mat_weights, const std::vector< float > &batch_input_activations, std::vector< float > &batch_output_activations, int num_tokens, int output_dim, int input_dim)
 
void matmul_rows_f32_batch_cpu (const std::function< void(int64_t, float *)> &row_fn, const float *batch_input_activations, float *batch_output_activations, int num_tokens, int output_dim, int input_dim)
 
void matvec_q6k_f32_vector_cpu (const std::vector< block_q6_K > &mat_q6k, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
 
void matvec_q4k_f32_vector_cpu (const std::vector< block_q4_K > &mat_q4k, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
 
void matmul_q8_0_f32_batch_cpu (const std::vector< block_q8_0 > &mat_q8_0, const std::vector< float > &batch_input_activations, std::vector< float > &batch_output_activations, int num_tokens, int output_dim, int input_dim)
 
void matmul_q8k_f32_batch_cpu (const std::vector< block_q8_K > &mat_q8k, const std::vector< float > &batch_input_activations, std::vector< float > &batch_output_activations, int num_tokens, int output_dim, int input_dim)
 
void matmul_q6k_f32_batch_cpu (const std::vector< block_q6_K > &mat_q6k, const std::vector< float > &batch_input_activations, std::vector< float > &batch_output_activations, int num_tokens, int output_dim, int input_dim)
 
void matmul_q4k_f32_batch_cpu (const std::vector< block_q4_K > &mat_q4k, const std::vector< float > &batch_input_activations, std::vector< float > &batch_output_activations, int num_tokens, int output_dim, int input_dim)
 
void matvec_bf16_f32_vector_cpu (const std::vector< uint16_t > &mat_bf16, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols)
 
void weighted_sum_probs_v (const std::vector< float > &probs, const std::vector< float > &V, std::vector< float > &out, int seq_len, int head_dim)
 
void calculate_attention_scores (const std::vector< float > &Q, const std::vector< float > &K, std::vector< float > &scores, int seq_len, int head_dim, float scale)
 
void log_vec_stats (const std::string &name, const std::vector< float > &v)
 
bool write_vector_to_file (const std::string &filename, const std::vector< float > &vec)
 
std::vector< std::vector< float > > load_rmsnorm_bin (const std::string &filename, int num_tokens, int hidden_size)
 
void log_raw_float_pointer (const std::string &name, const float *ptr, size_t count)
 
void log_vector_summary_detailed (const std::string &name, const std::vector< float > &v, int current_pos, int current_layer, int N)
 

Function Documentation

◆ apply_rope_batch_cpu()

void apply_rope_batch_cpu ( std::vector< float > &  q_batch,
std::vector< float > &  k_batch,
int  num_tokens,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
int  start_pos_in_sequence,
const std::vector< std::pair< float, float > > &  all_freqs_cis,
int  max_pos_embeddings,
bool  use_adjacent_pairing 
)

Definition at line 491 of file utils.cpp.

502 {
503 if (q_batch.size() != (size_t)num_tokens * num_q_heads * head_dim) {
504 Logger::error("apply_rope_batch_cpu: q_batch size mismatch. Expected " +
505 std::to_string((size_t)num_tokens * num_q_heads * head_dim) + ", got " + std::to_string(q_batch.size()));
506 return;
507 }
508 if (k_batch.size() != (size_t)num_tokens * num_kv_heads * head_dim) {
509 Logger::error("apply_rope_batch_cpu: k_batch size mismatch. Expected " +
510 std::to_string((size_t)num_tokens * num_kv_heads * head_dim) + ", got " + std::to_string(k_batch.size()));
511 return;
512 }
513 if (head_dim % 2 != 0) {
514 Logger::error("apply_rope_batch_cpu: head_dim must be even for RoPE.");
515 return;
516 }
517
518 for (int t = 0; t < num_tokens; ++t) {
520
522 Logger::warning("[ROPE_BATCH_CPU] Token " + std::to_string(t) + " (actual_pos: " + std::to_string(current_token_pos) +
523 ") is out of range [0, " + std::to_string(max_pos_embeddings -1) + "]. Skipping RoPE for this token.");
524 continue;
525 }
526
527 for (int h = 0; h < num_q_heads; ++h) {
529
530 for (int i = 0; i < head_dim / 2; ++i) {
531 size_t freq_idx = (size_t)current_token_pos * (head_dim / 2) + i;
532
533 if (freq_idx >= all_freqs_cis.size()) {
534 Logger::warning("[ROPE_BATCH_CPU] Q - Token " + std::to_string(t) + ", Head " + std::to_string(h) +
535 ", DimPair " + std::to_string(i) + ": freq_idx (" + std::to_string(freq_idx) +
536 ") out of bounds for all_freqs_cis.size (" + std::to_string(all_freqs_cis.size()) + "). Skipping pair.");
537 continue;
538 }
539
540 float freq_cis_real = all_freqs_cis[freq_idx].first;
541 float freq_cis_imag = all_freqs_cis[freq_idx].second;
542
543 float val0, val1;
544 size_t idx0, idx1;
545
549 } else {
552 }
553
554 if (idx0 >= q_batch.size() || idx1 >= q_batch.size()) {
555 Logger::warning("[ROPE_BATCH_CPU] Q - Token " + std::to_string(t) + ", Head " + std::to_string(h) +
556 ", DimPair " + std::to_string(i) + ": q_batch index out of bounds. q_batch.size(): " + std::to_string(q_batch.size()) +
557 ", idx0: " + std::to_string(idx0) + ", idx1: " + std::to_string(idx1) + ". Skipping pair.");
558 continue;
559 }
560
561 val0 = q_batch[idx0];
562 val1 = q_batch[idx1];
563
566 }
567 }
568
569 for (int h = 0; h < num_kv_heads; ++h) {
571
572 for (int i = 0; i < head_dim / 2; ++i) {
573 size_t freq_idx = (size_t)current_token_pos * (head_dim / 2) + i;
574
575 if (freq_idx >= all_freqs_cis.size()) {
576 Logger::warning("[ROPE_BATCH_CPU] K - Token " + std::to_string(t) + ", Head " + std::to_string(h) +
577 ", DimPair " + std::to_string(i) + ": freq_idx (" + std::to_string(freq_idx) +
578 ") out of bounds for all_freqs_cis.size (" + std::to_string(all_freqs_cis.size()) + "). Skipping pair.");
579 continue;
580 }
581
582 float freq_cis_real = all_freqs_cis[freq_idx].first;
583 float freq_cis_imag = all_freqs_cis[freq_idx].second;
584
585 float val0, val1;
586 size_t idx0, idx1;
587
591 } else {
594 }
595
596 if (idx0 >= k_batch.size() || idx1 >= k_batch.size()) {
597 Logger::warning("[ROPE_BATCH_CPU] K - Token " + std::to_string(t) + ", Head " + std::to_string(h) +
598 ", DimPair " + std::to_string(i) + ": k_batch index out of bounds. k_batch.size(): " + std::to_string(k_batch.size()) +
599 ", idx0: " + std::to_string(idx0) + ", idx1: " + std::to_string(idx1) + ". Skipping pair.");
600 continue;
601 }
602
603 val0 = k_batch[idx0];
604 val1 = k_batch[idx1];
605
608 }
609 }
610 }
611}
static void warning(const std::string &message)
Definition logger.cpp:139
static void error(const std::string &message)
Definition logger.cpp:143
size_t j

References Logger::error(), j, and Logger::warning().

Referenced by CPUBatchProcessor::forward_cpu_batch(), and ember_ir::Interpreter::run_nodes().

◆ apply_rope_vector()

void apply_rope_vector ( std::vector< float > &  x,
int  num_heads,
int  head_dim,
int  current_token_pos,
const std::vector< std::pair< float, float > > &  all_freqs_cis,
int  max_pos_embeddings,
bool  use_adjacent_pairing 
)

Definition at line 428 of file utils.cpp.

436 {
438 return;
439 }
440 if (head_dim % 2 != 0) {
441 Logger::error("RoPE apply_rope_vector: head_dim must be even. head_dim: " + std::to_string(head_dim));
442 return;
443 }
444
445 const int dim_half = head_dim / 2;
446 size_t pos_offset = static_cast<size_t>(current_token_pos) * static_cast<size_t>(dim_half);
447
448 for (int h = 0; h < num_heads; ++h) {
449 size_t head_offset = static_cast<size_t>(h) * head_dim;
450
451 for (int i = 0; i < dim_half; ++i) {
452 size_t freq_idx = pos_offset + static_cast<size_t>(i);
453
454 if (freq_idx >= all_freqs_cis.size()) {
455 Logger::warning("RoPE apply_rope_vector: freq_idx out of bounds. pos: " +
456 std::to_string(current_token_pos) + ", head_dim/2: " + std::to_string(dim_half) +
457 ", i: " + std::to_string(i) + ", calculated freq_idx: " + std::to_string(freq_idx) +
458 ", all_freqs_cis.size(): " + std::to_string(all_freqs_cis.size()));
459 continue;
460 }
461
462 float cos_theta = all_freqs_cis[freq_idx].first;
463 float sin_theta = all_freqs_cis[freq_idx].second;
464
465 float x0_val, x1_val;
466 size_t x0_idx, x1_idx;
467
469 x0_idx = head_offset + (2 * i);
470 x1_idx = head_offset + (2 * i + 1);
471 } else {
472 x0_idx = head_offset + i;
474 }
475
476 if (x0_idx >= x.size() || x1_idx >= x.size()) {
477 Logger::warning("RoPE apply_rope_vector: x index out of bounds. x.size(): " + std::to_string(x.size()) +
478 ", x0_idx: " + std::to_string(x0_idx) + ", x1_idx: " + std::to_string(x1_idx));
479 continue;
480 }
481
482 x0_val = x[x0_idx];
483 x1_val = x[x1_idx];
484
487 }
488 }
489}

References Logger::error(), j, and Logger::warning().

Referenced by TinyLlamaModel::forward(), CPUBatchProcessor::forward_cpu_batch(), and TinyLlamaModel::forward_cpu_batch_generation().

◆ argmax()

int argmax ( const std::vector< float > &  v)

Definition at line 186 of file utils.cpp.

186 {
187 if (v.empty()) {
188 Logger::error("Cannot perform argmax on empty vector");
189 return -1;
190 }
191 auto max_it = std::max_element(v.begin(), v.end());
192 float max_val = *max_it;
193 int max_idx = std::distance(v.begin(), max_it);
194 Logger::debug("[ARGMAX HELPER] Max value found: " + std::to_string(max_val) +
195 " at index: " + std::to_string(max_idx));
196 return max_idx;
197}
static void debug(const std::string &message)
Definition logger.cpp:131
std::vector< float > v

References Logger::debug(), Logger::error(), j, and v.

◆ bf16vec_to_float_vec()

◆ bfloat16_to_float32()

float bfloat16_to_float32 ( uint16_t  bf16)

Definition at line 145 of file utils.cpp.

145 {
146 if (bf16 == bfloat16::ZERO) return 0.0f;
147 if (bf16 == bfloat16::NEG_ZERO) return -0.0f;
148
150 ((bf16 & bfloat16::MANTISSA_MASK) != 0);
151 if (is_nan) return std::numeric_limits<float>::quiet_NaN();
152
154 (bf16 & bfloat16::MANTISSA_MASK) == 0) {
155 return (bf16 & bfloat16::SIGN_BIT) ? -std::numeric_limits<float>::infinity()
156 : std::numeric_limits<float>::infinity();
157 }
158
160 float result;
161 std::memcpy(&result, &bits, sizeof(float));
162
163 return result;
164}
constexpr uint16_t ZERO
constexpr uint16_t SIGN_BIT
constexpr uint16_t NEG_ZERO
constexpr uint16_t EXPONENT_MASK
constexpr uint16_t MANTISSA_MASK
constexpr int SHIFT_BITS

References bfloat16::EXPONENT_MASK, j, bfloat16::MANTISSA_MASK, bfloat16::NEG_ZERO, bfloat16::SHIFT_BITS, bfloat16::SIGN_BIT, and bfloat16::ZERO.

Referenced by bf16vec_to_float_vec(), bfloat16_vector_to_float32(), and matvec_bf16_f32_vector_cpu().

◆ bfloat16_vector_to_float32()

std::vector< float > bfloat16_vector_to_float32 ( const std::vector< uint16_t > &  bf16_vec)

Definition at line 166 of file utils.cpp.

166 {
167 std::vector<float> f32_vec(bf16_vec.size());
168
169#pragma omp parallel for
170 for (int64_t i = 0; i < static_cast<int64_t>(bf16_vec.size()); ++i) {
172 }
173
174 return f32_vec;
175}

References bfloat16_to_float32(), and j.

◆ calculate_attention_scores()

void calculate_attention_scores ( const std::vector< float > &  Q,
const std::vector< float > &  K,
std::vector< float > &  scores,
int  seq_len,
int  head_dim,
float  scale 
)

Definition at line 1258 of file utils.cpp.

1261 {
1262 if (Q.empty() || K.empty()) return;
1263 scores.resize(seq_len);
1264
1267
1268#pragma omp parallel for collapse(1)
1269 for (int64_t i = 0; i < static_cast<int64_t>(seq_len); ++i) {
1270 double dot_product = 0.0;
1271 double c_kahan = 0.0;
1272 size_t k_offset = static_cast<size_t>(i) * head_dim;
1273
1274 for (int j = 0; j < head_dim; ++j) {
1275 double term = static_cast<double>(Q[j]) * static_cast<double>(K[k_offset + j]);
1276 double y = term - c_kahan;
1277 double t_sum = dot_product + y;
1278 c_kahan = (t_sum - dot_product) - y;
1280 }
1281
1282 scores[i] = static_cast<float>(dot_product * effective_scale);
1283 }
1284}
node scale
constexpr float MIN_SCALE
constexpr float ATTENTION_SCALE_BASE
constexpr float MAX_SCALE

References attention::ATTENTION_SCALE_BASE, j, attention::MAX_SCALE, attention::MIN_SCALE, and scale.

◆ dot_f32_as_f64()

static double dot_f32_as_f64 ( const float *  a,
const float *  b,
int  n 
)
inlinestatic

Definition at line 355 of file utils.cpp.

355 {
356 double acc[8] = {0, 0, 0, 0, 0, 0, 0, 0};
357 int i = 0;
358 for (; i + 8 <= n; i += 8)
359 for (int k = 0; k < 8; ++k) acc[k] += static_cast<double>(a[i + k]) * static_cast<double>(b[i + k]);
360 double tail = 0.0;
361 for (; i < n; ++i) tail += static_cast<double>(a[i]) * static_cast<double>(b[i]);
362 return ((acc[0] + acc[1]) + (acc[2] + acc[3])) + ((acc[4] + acc[5]) + (acc[6] + acc[7])) + tail;
363}
int n
std::vector< E > a

References a, j, k, and n.

Referenced by matmul_f32_f32_batch_cpu(), matmul_rows_f32_batch_cpu(), matvec_f32_f32_vector_cpu(), moe_ffn_f32_cpu(), and moe_ffn_routed_f32_cpu().

◆ float32_to_bfloat16()

uint16_t float32_to_bfloat16 ( float  val)

Definition at line 137 of file utils.cpp.

137 {
139 std::memcpy(&bits, &val, sizeof(float));
140
141 bits += 0x7FFF + ((bits >> 16) & 1);
142 return static_cast<uint16_t>(bits >> 16);
143}

References j.

Referenced by TinyLlamaModel::initialize_gpu_and_rope().

◆ gelu_cpu()

void gelu_cpu ( const std::vector< float > &  x,
std::vector< float > &  out 
)

Definition at line 851 of file utils.cpp.

851 {
852 if (x.size() != out.size()) out.resize(x.size());
853 const float sqrt_2_inv = 0.7071067811865476f; // 1/sqrt(2)
854#pragma omp parallel for
855 for (int64_t i = 0; i < static_cast<int64_t>(x.size()); ++i) {
856 out[i] = x[i] * 0.5f * (1.0f + std::erf(x[i] * sqrt_2_inv));
857 }
858}
node out

References j, and out.

◆ gelu_new_cpu()

void gelu_new_cpu ( const std::vector< float > &  x,
std::vector< float > &  out 
)

Definition at line 860 of file utils.cpp.

860 {
861 if (x.size() != out.size()) out.resize(x.size());
862 const float sqrt_2_pi = 0.7978845608028654f; // sqrt(2/pi)
863 const float coeff = 0.044715f;
864#pragma omp parallel for
865 for (int64_t i = 0; i < static_cast<int64_t>(x.size()); ++i) {
866 float x_val = x[i];
867 float x_cubed = x_val * x_val * x_val;
868 out[i] = x_val * 0.5f * (1.0f + std::tanh(sqrt_2_pi * (x_val + coeff * x_cubed)));
869 }
870}

References j, and out.

Referenced by TinyLlamaModel::forward().

◆ load_rmsnorm_bin()

std::vector< std::vector< float > > load_rmsnorm_bin ( const std::string &  filename,
int  num_tokens,
int  hidden_size 
)

Definition at line 1324 of file utils.cpp.

1324 {
1325 std::ifstream infile(filename, std::ios::binary);
1326 if (!infile) throw std::runtime_error("Failed to open " + filename);
1327 std::vector<float> flat(num_tokens * hidden_size);
1328 infile.read(reinterpret_cast<char*>(flat.data()),
1329 flat.size() * sizeof(float));
1330 if (!infile)
1331 throw std::runtime_error("Failed to read all data from " + filename);
1332 std::vector<std::vector<float>> result(num_tokens,
1333 std::vector<float>(hidden_size));
1334 for (int t = 0; t < num_tokens; ++t) {
1335 for (int h = 0; h < hidden_size; ++h) {
1336 result[t][h] = flat[t * hidden_size + h];
1337 }
1338 }
1339 return result;
1340}

References j.

◆ log_raw_float_pointer()

void log_raw_float_pointer ( const std::string &  name,
const float *  ptr,
size_t  count 
)

Definition at line 1342 of file utils.cpp.

1342 {
1343 if (!ptr) {
1344 Logger::info(name + ": NULL POINTER");
1345 return;
1346 }
1347 std::stringstream ss;
1348 ss << name << ": [";
1349 for (size_t i = 0; i < count; ++i) {
1350 if (i > 0) ss << ", ";
1351 ss << std::fixed << std::setprecision(6) << ptr[i];
1352 }
1353 ss << "]";
1354 Logger::info(ss.str());
1355}
static void info(const std::string &message)
Definition logger.cpp:135
const char * name

References Logger::info(), j, and name.

◆ log_vec_stats()

void log_vec_stats ( const std::string &  name,
const std::vector< float > &  v 
)

Definition at line 1286 of file utils.cpp.

1286 {
1287 if (v.empty()) {
1288 Logger::info(name + ": EMPTY VECTOR");
1289 return;
1290 }
1291 float minv = *std::min_element(v.begin(), v.end());
1292 float maxv = *std::max_element(v.begin(), v.end());
1293 float mean = std::accumulate(v.begin(), v.end(), 0.0f) / v.size();
1294 bool all_finite =
1295 std::all_of(v.begin(), v.end(), [](float x) { return std::isfinite(x); });
1296 Logger::info(name + ": min=" + std::to_string(minv) + ", max=" +
1297 std::to_string(maxv) + ", mean=" + std::to_string(mean) +
1298 ", all_finite=" + (all_finite ? "yes" : "no"));
1299}

References Logger::info(), j, name, and v.

◆ log_vector_summary()

void log_vector_summary ( const std::string &  name,
const std::vector< float > &  v,
int  head_count 
)

Definition at line 208 of file utils.cpp.

208 {
209 if (v.empty()) {
210 Logger::info(name + ": EMPTY");
211 return;
212 }
213 std::stringstream ss;
214 size_t actual_head_count = SAFE_MIN(static_cast<size_t>(head_count), v.size());
215
216 ss << name << ": size=" << v.size();
217
218 if (actual_head_count > 0) {
219 ss << ", first " << actual_head_count << ": [";
220 for (size_t i = 0; i < actual_head_count; ++i) {
221 ss << (i > 0 ? " " : "") << std::fixed << std::setprecision(4) << v[i];
222 }
223 ss << "]";
224 }
225 float minv = *std::min_element(v.begin(), v.end());
226 float maxv = *std::max_element(v.begin(), v.end());
227 double sum = std::accumulate(v.begin(), v.end(), 0.0);
228 float mean = sum / v.size();
229 bool all_finite = std::all_of(v.begin(), v.end(), [](float x) { return std::isfinite(x); });
230 ss << ", min=" << minv << ", max=" << maxv << ", mean=" << mean
231 << ", finite=" << (all_finite ? "yes" : "NO");
232 Logger::info(ss.str());
233}
#define SAFE_MIN(a, b)

References Logger::info(), j, name, SAFE_MIN, and v.

Referenced by TinyLlamaModel::forward().

◆ log_vector_summary_detailed()

void log_vector_summary_detailed ( const std::string &  name,
const std::vector< float > &  v,
int  current_pos,
int  current_layer,
int  N 
)

Definition at line 1357 of file utils.cpp.

1359 {
1360 if (v.empty()) {
1361 Logger::info(name + ": EMPTY");
1362 return;
1363 }
1364
1365 std::stringstream ss;
1366 ss << "[POS=" << current_pos << " LAYER=" << current_layer << "] " << name;
1367 ss << ": size=" << v.size();
1368
1369 size_t actual_N = SAFE_MIN(static_cast<size_t>(N), v.size());
1370 if (actual_N > 0) {
1371 ss << ", first " << actual_N << ": [";
1372 for (size_t i = 0; i < actual_N; ++i) {
1373 ss << (i > 0 ? " " : "") << std::fixed << std::setprecision(6) << v[i];
1374 }
1375 ss << "]";
1376 }
1377
1378 float minv = *std::min_element(v.begin(), v.end());
1379 float maxv = *std::max_element(v.begin(), v.end());
1380 double sum = std::accumulate(v.begin(), v.end(), 0.0);
1381 float mean = sum / v.size();
1382 bool all_finite = std::all_of(v.begin(), v.end(), [](float x) { return std::isfinite(x); });
1383
1384 ss << ", min=" << minv << ", max=" << maxv << ", mean=" << mean
1385 << ", finite=" << (all_finite ? "yes" : "NO");
1386 Logger::info(ss.str());
1387}

References Logger::info(), j, name, SAFE_MIN, and v.

◆ log_vector_summary_with_tail()

void log_vector_summary_with_tail ( const std::string &  name,
const std::vector< float > &  v,
int  head_count,
int  tail_count 
)

Definition at line 235 of file utils.cpp.

236 {
237 if (v.empty()) {
238 Logger::info(name + ": EMPTY");
239 return;
240 }
241 std::stringstream ss;
242
243 size_t actual_head_count = SAFE_MIN(static_cast<size_t>(head_count), v.size());
244 size_t actual_tail_count = SAFE_MIN(static_cast<size_t>(tail_count), v.size());
246 bool overlap = total_shown > v.size();
247 if (overlap) {
249 if (actual_tail_count > SAFE_MIN(static_cast<size_t>(tail_count), v.size())) {
250 actual_tail_count = SAFE_MIN(static_cast<size_t>(tail_count), v.size());
251 }
252 if (tail_count > 0 && actual_head_count == v.size()) {
254 }
255 }
256 size_t tail_start_index = v.size() - actual_tail_count;
257
258 ss << name << ": size=" << v.size();
259
260 if (actual_head_count > 0) {
261 ss << ", first " << actual_head_count << ": [";
262 for (size_t i = 0; i < actual_head_count; ++i) {
263 ss << (i > 0 ? " " : "") << std::fixed << std::setprecision(4) << v[i];
264 }
265 ss << "]";
266 }
267
269 ss << ", last " << actual_tail_count << ": [";
270 for (size_t i = 0; i < actual_tail_count; ++i) {
271 ss << (i > 0 ? " " : "") << std::fixed << std::setprecision(4)
272 << v[tail_start_index + i];
273 }
274 ss << "]";
275 } else if (overlap && tail_count > 0 && actual_head_count < v.size()) {
276 ss << " (... tail overlaps head ...)";
277 }
278
279 float minv = *std::min_element(v.begin(), v.end());
280 float maxv = *std::max_element(v.begin(), v.end());
281 double sum = std::accumulate(v.begin(), v.end(), 0.0);
282 float mean = sum / v.size();
283 bool all_finite = std::all_of(v.begin(), v.end(), [](float x) { return std::isfinite(x); });
284 ss << ", min=" << minv << ", max=" << maxv << ", mean=" << mean
285 << ", finite=" << (all_finite ? "yes" : "NO");
286 Logger::info(ss.str());
287}

References Logger::info(), j, name, SAFE_MIN, and v.

◆ matmul_f32_f32_batch_cpu()

void matmul_f32_f32_batch_cpu ( const std::vector< float > &  mat_weights,
const std::vector< float > &  batch_input_activations,
std::vector< float > &  batch_output_activations,
int  num_tokens,
int  output_dim,
int  input_dim 
)

Definition at line 872 of file utils.cpp.

879 {
880 if (mat_weights.empty() || batch_input_activations.empty()) {
881 Logger::error("[MATMUL_F32_BATCH_CPU] Input matrix or batch_input_activations is empty.");
882 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
883 return;
884 }
885 if (mat_weights.size() != (size_t)output_dim * input_dim) {
886 Logger::error("[MATMUL_F32_BATCH_CPU] Matrix dimensions mismatch. Expected " +
887 std::to_string((size_t)output_dim * input_dim) + ", got " +
888 std::to_string(mat_weights.size()));
889 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
890 return;
891 }
892 if (batch_input_activations.size() != (size_t)num_tokens * input_dim) {
894 "[MATMUL_F32_BATCH_CPU] Batch input activations dimension mismatch. Expected " +
895 std::to_string((size_t)num_tokens * input_dim) + ", got " +
896 std::to_string(batch_input_activations.size()));
897 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
898 return;
899 }
900
902
903 // Weight rows outermost: each row (input_dim floats, a few KB) stays in L1
904 // while every token uses it, so the weights stream from memory once per
905 // call instead of once per token. The same dot products as token-major
906 // order, so the same results.
908 const float* w_row = mat_weights.data() + (size_t)o * input_dim;
909 for (int t = 0; t < num_tokens; ++t) {
910 batch_output_activations[(size_t)t * output_dim + o] = static_cast<float>(
912 }
913 });
914}
void parallel_for(int64_t n, F &&fn)
static double dot_f32_as_f64(const float *a, const float *b, int n)
Definition utils.cpp:355

References dot_f32_as_f64(), Logger::error(), j, and ember::parallel_for().

Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), TinyLlamaModel::forward_cpu_logits_batch(), ember_ir::Interpreter::mor_step(), and ember_ir::Interpreter::run_nodes().

◆ matmul_q4k_f32_batch_cpu()

void matmul_q4k_f32_batch_cpu ( const std::vector< block_q4_K > &  mat_q4k,
const std::vector< float > &  batch_input_activations,
std::vector< float > &  batch_output_activations,
int  num_tokens,
int  output_dim,
int  input_dim 
)

Definition at line 1155 of file utils.cpp.

1162 {
1163 if (mat_q4k.empty() || batch_input_activations.empty()) {
1164 Logger::error("[MATMUL_Q4K_BATCH_CPU] Input matrix or batch_input_activations is empty.");
1165 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
1166 return;
1167 }
1168 if (batch_input_activations.size() != (size_t)num_tokens * input_dim) {
1169 Logger::error("[MATMUL_Q4K_BATCH_CPU] batch_input_activations size mismatch. Expected " +
1170 std::to_string((size_t)num_tokens * input_dim) + ", got " +
1171 std::to_string(batch_input_activations.size()));
1172 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
1173 return;
1174 }
1175
1177
1178#pragma omp parallel for
1179 for (int token_idx = 0; token_idx < num_tokens; ++token_idx) {
1180 std::vector<float> current_token_input(input_dim);
1183
1184 std::vector<float> current_token_output(output_dim);
1186
1189 }
1190}
void matvec_q4k_f32_vector_cpu(const std::vector< block_q4_K > &mat_q4k, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
Definition utils.cpp:983

References Logger::error(), j, and matvec_q4k_f32_vector_cpu().

Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), and TinyLlamaModel::forward_cpu_logits_batch().

◆ matmul_q6k_f32_batch_cpu()

void matmul_q6k_f32_batch_cpu ( const std::vector< block_q6_K > &  mat_q6k,
const std::vector< float > &  batch_input_activations,
std::vector< float > &  batch_output_activations,
int  num_tokens,
int  output_dim,
int  input_dim 
)

Definition at line 1117 of file utils.cpp.

1124 {
1125 if (mat_q6k.empty() || batch_input_activations.empty()) {
1126 Logger::error("[MATMUL_Q6K_BATCH_CPU] Input matrix or batch_input_activations is empty.");
1127 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
1128 return;
1129 }
1130
1131 if (batch_input_activations.size() != (size_t)num_tokens * input_dim) {
1132 Logger::error("[MATMUL_Q6K_BATCH_CPU] batch_input_activations size mismatch. Expected " +
1133 std::to_string((size_t)num_tokens * input_dim) + ", got " +
1134 std::to_string(batch_input_activations.size()));
1135 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
1136 return;
1137 }
1138
1140
1141#pragma omp parallel for
1142 for (int token_idx = 0; token_idx < num_tokens; ++token_idx) {
1143 std::vector<float> current_token_input(input_dim);
1146
1147 std::vector<float> current_token_output(output_dim);
1149
1152 }
1153}
void matvec_q6k_f32_vector_cpu(const std::vector< block_q6_K > &mat_q6k, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
Definition utils.cpp:930

References Logger::error(), j, and matvec_q6k_f32_vector_cpu().

Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), and TinyLlamaModel::forward_cpu_logits_batch().

◆ matmul_q8_0_f32_batch_cpu()

void matmul_q8_0_f32_batch_cpu ( const std::vector< block_q8_0 > &  mat_q8_0,
const std::vector< float > &  batch_input_activations,
std::vector< float > &  batch_output_activations,
int  num_tokens,
int  output_dim,
int  input_dim 
)

Definition at line 1036 of file utils.cpp.

1043 {
1044 if (mat_q8_0.empty() || batch_input_activations.empty()) {
1045 Logger::error("[MATMUL_Q8_0_BATCH_CPU] Input matrix or batch_input_activations is empty.");
1046 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
1047 return;
1048 }
1049
1050 if (batch_input_activations.size() != (size_t)num_tokens * input_dim) {
1051 Logger::error("[MATMUL_Q8_0_BATCH_CPU] batch_input_activations size mismatch. Expected " +
1052 std::to_string((size_t)num_tokens * input_dim) + ", got " +
1053 std::to_string(batch_input_activations.size()));
1054 batch_output_activations.assign((size_t)num_tokens * output_dim, 0.0f);
1055 return;
1056 }
1057
1059
1060#pragma omp parallel for
1061 for (int token_idx = 0; token_idx < num_tokens; ++token_idx) {
1062 std::vector<float> current_token_input(input_dim);
1065
1066 std::vector<float> current_token_output(output_dim);
1068
1071 }
1072}
void matvec_q8_0_f32_vector_cpu(const std::vector< block_q8_0 > &mat_q8_0, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
Definition utils.cpp:294

References Logger::error(), j, and matvec_q8_0_f32_vector_cpu().

Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), and TinyLlamaModel::forward_cpu_logits_batch().

◆ matmul_q8k_f32_batch_cpu()

void matmul_q8k_f32_batch_cpu ( const std::vector< block_q8_K > &  mat_q8k,
const std::vector< float > &  batch_input_activations,
std::vector< float > &  batch_output_activations,
int  num_tokens,
int  output_dim,
int  input_dim 
)

Definition at line 1074 of file utils.cpp.

1081 {
1082 if (input_dim % GGML_QK_K != 0) {
1083 throw std::runtime_error("matmul_q8k_f32_batch_cpu: input_dim (" + std::to_string(input_dim) +
1084 ") must be divisible by GGML_QK_K (" + std::to_string(GGML_QK_K) + ")");
1085 }
1086
1089 throw std::runtime_error("matmul_q8k_f32_batch_cpu: batch_input_activations size mismatch. Expected " +
1090 std::to_string(expected_input_size) + ", got " + std::to_string(batch_input_activations.size()));
1091 }
1092
1095 if (mat_q8k.size() != total_blocks_expected) {
1096 throw std::runtime_error("matmul_q8k_f32_batch_cpu: mat_q8k size mismatch. Expected " +
1097 std::to_string(total_blocks_expected) + " blocks, got " + std::to_string(mat_q8k.size()));
1098 }
1099
1101
1102 for (int t = 0; t < num_tokens; ++t) {
1103 std::vector<float> current_token_input(input_dim);
1104 for (int i = 0; i < input_dim; ++i) {
1106 }
1107
1108 std::vector<float> current_token_output(output_dim);
1110
1111 for (int i = 0; i < output_dim; ++i) {
1113 }
1114 }
1115}
constexpr size_t GGML_QK_K
Block size constants for different quantization formats.
Definition gguf_parser.h:42
void matvec_q8k_f32_vector_cpu(const std::vector< block_q8_K > &mat_q8k, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols, bool log_first_block)
Definition utils.cpp:399

References GGML_QK_K, j, and matvec_q8k_f32_vector_cpu().

◆ matmul_rows_f32_batch_cpu()

void matmul_rows_f32_batch_cpu ( const std::function< void(int64_t, float *)> &  row_fn,
const float *  batch_input_activations,
float *  batch_output_activations,
int  num_tokens,
int  output_dim,
int  input_dim 
)

Definition at line 916 of file utils.cpp.

918 {
920 thread_local std::vector<float> w_row;
921 if (w_row.size() < static_cast<size_t>(input_dim)) w_row.resize(input_dim);
922 row_fn(o, w_row.data());
923 for (int t = 0; t < num_tokens; ++t) {
924 batch_output_activations[(size_t)t * output_dim + o] = static_cast<float>(
926 }
927 });
928}

References dot_f32_as_f64(), j, and ember::parallel_for().

Referenced by ember_ir::Interpreter::run_nodes().

◆ matvec_bf16_f32_vector_cpu()

void matvec_bf16_f32_vector_cpu ( const std::vector< uint16_t > &  mat_bf16,
const std::vector< float > &  vec_f32,
std::vector< float > &  out_f32,
int  rows,
int  cols 
)

Definition at line 1192 of file utils.cpp.

1194 {
1195 if (mat_bf16.size() != (size_t)rows * cols ||
1196 vec_f32.size() != (size_t)cols) {
1197 Logger::error("matvec_bf16_f32_vector_cpu: Size mismatch. Mat: " +
1198 std::to_string(mat_bf16.size()) + " (Expected " +
1199 std::to_string(rows * cols) +
1200 "), Vec: " + std::to_string(vec_f32.size()) + " (Expected " +
1201 std::to_string(cols) + ")");
1202 out_f32.assign(rows, 0.0f);
1203 return;
1204 }
1205 out_f32.resize(rows);
1206
1207#pragma omp parallel for
1208 for (int64_t r = 0; r < static_cast<int64_t>(rows); ++r) {
1209 double sum = 0.0;
1210 double c = 0.0;
1211 size_t row_offset = r * cols;
1212
1213 for (int c_idx = 0; c_idx < cols; ++c_idx) {
1214 float weight = bfloat16_to_float32(mat_bf16[row_offset + c_idx]);
1215 double term =
1216 static_cast<double>(weight) * static_cast<double>(vec_f32[c_idx]);
1217
1218 double y = term - c;
1219 double t = sum + y;
1220 c = (t - sum) - y;
1221 sum = t;
1222 }
1223 out_f32[r] = static_cast<float>(sum);
1224 }
1225}
float c

References bfloat16_to_float32(), c, Logger::error(), and j.

Referenced by TinyLlamaModel::forward().

◆ matvec_f32_f32_vector_cpu()

void matvec_f32_f32_vector_cpu ( const std::vector< float > &  mat_f32,
const std::vector< float > &  vec_f32,
std::vector< float > &  out_f32,
int  rows,
int  cols 
)

Definition at line 365 of file utils.cpp.

368 {
369 if (mat_f32.empty() || vec_f32.empty()) {
371 "matvec_f32_f32_vector_cpu: Input matrix or vector is empty.");
372 out_f32.assign(rows, 0.0f);
373 return;
374 }
375 if (mat_f32.size() != (size_t)rows * cols) {
377 "matvec_f32_f32_vector_cpu: Matrix dimensions mismatch. Expected " +
378 std::to_string((size_t)rows * cols) + ", got " +
379 std::to_string(mat_f32.size()));
380 out_f32.assign(rows, 0.0f);
381 return;
382 }
383 if (vec_f32.size() != (size_t)cols) {
385 "matvec_f32_f32_vector_cpu: Vector dimension mismatch. Expected " +
386 std::to_string(cols) + ", got " + std::to_string(vec_f32.size()));
387 out_f32.assign(rows, 0.0f);
388 return;
389 }
390
391 out_f32.resize(rows);
392
394 const float* mat_row_ptr = mat_f32.data() + static_cast<size_t>(r) * cols;
395 out_f32[r] = static_cast<float>(dot_f32_as_f64(mat_row_ptr, vec_f32.data(), cols));
396 });
397}

References dot_f32_as_f64(), Logger::error(), j, and ember::parallel_for().

Referenced by TinyLlamaModel::forward(), and matvec_q8k_f32_vector_cpu().

◆ matvec_q4k_f32_vector_cpu()

void matvec_q4k_f32_vector_cpu ( const std::vector< block_q4_K > &  mat_q4k,
const std::vector< float > &  vec_f32,
std::vector< float > &  out_f32,
int  rows,
int  cols,
bool  log_first_block 
)

Definition at line 983 of file utils.cpp.

986 {
987 if (cols % GGML_QK_K != 0) {
988 throw std::runtime_error(
989 "matvec_q4k_f32_vector_cpu: cols (" + std::to_string(cols) +
990 ") must be divisible by GGML_QK_K (" + std::to_string(GGML_QK_K) + ")");
991 }
992 if (vec_f32.size() != cols) {
993 throw std::runtime_error(
994 "matvec_q4k_f32_vector_cpu: vec_f32 size mismatch. Expected " +
995 std::to_string(cols) + ", got " + std::to_string(vec_f32.size()));
996 }
999 if (mat_q4k.size() != total_blocks_expected) {
1000 throw std::runtime_error(
1001 "matvec_q4k_f32_vector_cpu: mat_q4k size mismatch. Expected " +
1002 std::to_string(total_blocks_expected) + " blocks, got " +
1003 std::to_string(mat_q4k.size()));
1004 }
1005
1006 out_f32.resize(rows);
1008
1009#pragma omp parallel for private(dequantized_block)
1010 for (int64_t r = 0; r < static_cast<int64_t>(rows); ++r) {
1011 double row_sum = 0.0;
1012 double kahan_c = 0.0;
1013
1015
1018 bool enable_dequant_log = log_first_block && (r == 0 && block_col_idx == 0);
1020
1022 for (int i = 0; i < GGML_QK_K; ++i) {
1023 double term = static_cast<double>(dequantized_block[i]) *
1024 static_cast<double>(vec_f32[vec_offset + i]);
1025
1026 double y = term - kahan_c;
1027 double t = row_sum + y;
1028 kahan_c = (t - row_sum) - y;
1029 row_sum = t;
1030 }
1031 }
1032 out_f32[r] = static_cast<float>(row_sum);
1033 }
1034}
void dequantize_q4_k_m(const block_q4_K *qblock, float *output, int num_weights_in_block, bool log_this_block)
4-bit K-quantized block structure

References dequantize_q4_k_m(), GGML_QK_K, and j.

Referenced by TinyLlamaModel::forward(), and matmul_q4k_f32_batch_cpu().

◆ matvec_q6k_f32_vector_cpu()

void matvec_q6k_f32_vector_cpu ( const std::vector< block_q6_K > &  mat_q6k,
const std::vector< float > &  vec_f32,
std::vector< float > &  out_f32,
int  rows,
int  cols,
bool  log_first_block 
)

Definition at line 930 of file utils.cpp.

933 {
934 if (cols % GGML_QK_K != 0) {
935 throw std::runtime_error(
936 "matvec_q6k_f32_vector_cpu: cols (" + std::to_string(cols) +
937 ") must be divisible by GGML_QK_K (" + std::to_string(GGML_QK_K) + ")");
938 }
939 if (vec_f32.size() != cols) {
940 throw std::runtime_error(
941 "matvec_q6k_f32_vector_cpu: vec_f32 size mismatch. Expected " +
942 std::to_string(cols) + ", got " + std::to_string(vec_f32.size()));
943 }
946 if (mat_q6k.size() != total_blocks_expected) {
947 throw std::runtime_error(
948 "matvec_q6k_f32_vector_cpu: mat_q6k size mismatch. Expected " +
949 std::to_string(total_blocks_expected) + " blocks, got " +
950 std::to_string(mat_q6k.size()));
951 }
952
953 out_f32.resize(rows);
955
956#pragma omp parallel for private(dequantized_block)
957 for (int64_t r = 0; r < static_cast<int64_t>(rows); ++r) {
958 double row_sum = 0.0;
959 double kahan_c = 0.0;
960
962
965 bool enable_dequant_log = log_first_block && (r == 0 && block_col_idx == 0);
967
969 for (int i = 0; i < GGML_QK_K; ++i) {
970 double term = static_cast<double>(dequantized_block[i]) *
971 static_cast<double>(vec_f32[vec_offset + i]);
972
973 double y = term - kahan_c;
974 double t = row_sum + y;
975 kahan_c = (t - row_sum) - y;
976 row_sum = t;
977 }
978 }
979 out_f32[r] = static_cast<float>(row_sum);
980 }
981}
void dequantize_q6_k(const block_q6_K *qblock, float *output, int num_weights_in_block, bool log_this_block)
6-bit K-quantized block structure

References dequantize_q6_k(), GGML_QK_K, and j.

Referenced by TinyLlamaModel::forward(), and matmul_q6k_f32_batch_cpu().

◆ matvec_q8_0_f32_vector_cpu()

void matvec_q8_0_f32_vector_cpu ( const std::vector< block_q8_0 > &  mat_q8_0,
const std::vector< float > &  vec_f32,
std::vector< float > &  out_f32,
int  rows,
int  cols,
bool  log_first_block 
)

Definition at line 294 of file utils.cpp.

297 {
298 if (cols % GGML_QK8_0 != 0) {
299 throw std::runtime_error(
300 "matvec_q8_0_f32_vector_cpu: cols (" + std::to_string(cols) +
301 ") must be divisible by GGML_QK8_0 (" + std::to_string(GGML_QK8_0) + ")");
302 }
303 if (vec_f32.size() != static_cast<size_t>(cols)) {
304 throw std::runtime_error(
305 "matvec_q8_0_f32_vector_cpu: vec_f32 size mismatch. Expected " +
306 std::to_string(cols) + ", got " + std::to_string(vec_f32.size()));
307 }
309 size_t total_blocks_expected = static_cast<size_t>(rows) * num_blocks_per_row;
310 if (mat_q8_0.size() != total_blocks_expected) {
311 throw std::runtime_error(
312 "matvec_q8_0_f32_vector_cpu: mat_q8_0 size mismatch. Expected " +
313 std::to_string(total_blocks_expected) + " blocks, got " +
314 std::to_string(mat_q8_0.size()));
315 }
316
317 out_f32.resize(rows);
319
320
321#pragma omp parallel for private(dequantized_block)
322 for (int64_t r = 0; r < static_cast<int64_t>(rows); ++r) {
323 double row_sum = 0.0;
324 double kahan_c = 0.0;
325
326 size_t block_row_offset = static_cast<size_t>(r) * num_blocks_per_row;
327
331
333
334
335 for (int i = 0; i < GGML_QK8_0; ++i) {
336 double term = static_cast<double>(dequantized_block[i]) *
337 static_cast<double>(vec_f32[vec_offset + i]);
338
339 double y = term - kahan_c;
340 double t = row_sum + y;
341 kahan_c = (t - row_sum) - y;
342 row_sum = t;
343 }
344 }
345 out_f32[r] = static_cast<float>(row_sum);
346
347 }
348}
constexpr size_t GGML_QK8_0
Definition gguf_parser.h:43
void dequantize_q8_0_block(const block_q8_0 *qblock, float *output)
Dequantizes a Q8_0 block to float32.
Simple 8-bit quantized block structure.

References dequantize_q8_0_block(), GGML_QK8_0, and j.

Referenced by TinyLlamaModel::forward(), and matmul_q8_0_f32_batch_cpu().

◆ matvec_q8k_f32_vector_cpu()

void matvec_q8k_f32_vector_cpu ( const std::vector< block_q8_K > &  mat_q8k,
const std::vector< float > &  vec_f32,
std::vector< float > &  out_f32,
int  rows,
int  cols,
bool  log_first_block 
)

Definition at line 399 of file utils.cpp.

402 {
403 if (cols % GGML_QK_K != 0) {
404 throw std::runtime_error("matvec_q8k_f32_vector_cpu: cols must be divisible by GGML_QK_K");
405 }
406
409 if (mat_q8k.size() != total_blocks_expected) {
410 throw std::runtime_error("matvec_q8k_f32_vector_cpu: mat_q8k size mismatch");
411 }
412 if (vec_f32.size() != (size_t)cols) {
413 throw std::runtime_error("matvec_q8k_f32_vector_cpu: vec_f32 size mismatch");
414 }
415
416 out_f32.resize(rows);
417
418 std::vector<float> mat_f32;
420
422
423 if (log_first_block && rows > 0) {
424 Logger::info("[Q8K_MATVEC_DEBUG] First output: " + std::to_string(out_f32[0]));
425 }
426}
void dequantize_q8_k(const std::vector< block_q8_K > &q_data, std::vector< float > &x, int n, bool log_this_block)
void matvec_f32_f32_vector_cpu(const std::vector< float > &mat_f32, const std::vector< float > &vec_f32, std::vector< float > &out_f32, int rows, int cols)
Definition utils.cpp:365

References dequantize_q8_k(), GGML_QK_K, Logger::info(), j, and matvec_f32_f32_vector_cpu().

Referenced by TinyLlamaModel::forward(), and matmul_q8k_f32_batch_cpu().

◆ moe_ffn_f32_cpu()

void moe_ffn_f32_cpu ( const float *  x,
int  d,
int  d_ff,
int  E,
int  k,
const float *  router,
const float *  gate_exps,
const float *  up_exps,
const float *  down_exps,
float *  out,
bool  renorm 
)

Definition at line 709 of file utils.cpp.

710 {
711 std::vector<float> r(E);
712 for (int e = 0; e < E; ++e) r[e] = static_cast<float>(dot_f32_as_f64(router + static_cast<size_t>(e) * d, x, d));
713 std::vector<int> sel;
714 std::vector<char> taken(E, 0);
715 for (int j = 0; j < k && j < E; ++j) {
716 int best = -1;
717 for (int e = 0; e < E; ++e)
718 if (!taken[e] && (best < 0 || r[e] > r[best])) best = e; // strict >: ties keep the lower index
719 taken[best] = 1;
720 sel.push_back(best);
721 }
722 std::sort(sel.begin(), sel.end()); // accumulate in ascending expert index
723 std::vector<float> gate(E, 0.0f);
724 {
725 float mx = -std::numeric_limits<float>::infinity();
726 if (renorm) {
727 for (int e : sel) mx = std::max(mx, r[e]);
728 double z = 0.0;
729 for (int e : sel) z += std::exp(static_cast<double>(r[e] - mx));
730 for (int e : sel) gate[e] = static_cast<float>(std::exp(static_cast<double>(r[e] - mx)) / z);
731 } else {
732 for (int e = 0; e < E; ++e) mx = std::max(mx, r[e]);
733 double z = 0.0;
735 for (int e : sel) gate[e] = static_cast<float>(std::exp(static_cast<double>(r[e] - mx)) / z);
736 }
737 }
738 std::fill(out, out + d, 0.0f);
739 std::vector<float> h(d_ff);
740 for (int e : sel) {
741 const float w = gate[e];
742 const float* g = gate_exps + static_cast<size_t>(e) * d_ff * d;
743 const float* u = up_exps + static_cast<size_t>(e) * d_ff * d;
744 const float* dn = down_exps + static_cast<size_t>(e) * d * d_ff;
745 for (int i = 0; i < d_ff; ++i) {
746 const float gv = static_cast<float>(dot_f32_as_f64(g + static_cast<size_t>(i) * d, x, d));
747 const float uv = static_cast<float>(dot_f32_as_f64(u + static_cast<size_t>(i) * d, x, d));
748 h[i] = gv * (1.0f / (1.0f + std::exp(-gv))) * uv;
749 }
750 for (int o = 0; o < d; ++o)
751 out[o] += w * static_cast<float>(dot_f32_as_f64(dn + static_cast<size_t>(o) * d_ff, h.data(), d_ff));
752 }
753}

References dot_f32_as_f64(), j, k, and out.

Referenced by TinyLlamaModel::forward(), CPUBatchProcessor::forward_cpu_batch(), and moe_ffn_routed_f32_cpu().

◆ moe_ffn_routed_f32_cpu()

void moe_ffn_routed_f32_cpu ( const float *  x,
int  d,
int  d_ff,
int  E,
int  k,
const float *  router,
const float *  gate_exps,
const float *  up_exps,
const float *  down_exps,
float *  out,
bool  renorm,
bool  sigmoid,
const float *  bias,
int  groups_n,
int  groups_top 
)

Definition at line 763 of file utils.cpp.

765 {
766 if (!sigmoid && !bias && groups_n <= 1) {
768 return;
769 }
770 std::vector<float> r(E), sc(E), c(E);
771 for (int e = 0; e < E; ++e) r[e] = static_cast<float>(dot_f32_as_f64(router + static_cast<size_t>(e) * d, x, d));
772 if (sigmoid) {
773 for (int e = 0; e < E; ++e) sc[e] = 1.0f / (1.0f + std::exp(-r[e]));
774 } else {
775 float mx = -std::numeric_limits<float>::infinity();
776 for (int e = 0; e < E; ++e) mx = std::max(mx, r[e]);
777 float z = 0.0f;
778 for (int e = 0; e < E; ++e) {
779 sc[e] = std::exp(r[e] - mx);
780 z += sc[e];
781 }
782 for (int e = 0; e < E; ++e) sc[e] = sc[e] / z;
783 }
784 for (int e = 0; e < E; ++e) c[e] = bias ? sc[e] + bias[e] : sc[e];
785 std::vector<char> cand(E, 1);
786 if (groups_n > 1) {
787 const int per = E / groups_n;
788 std::vector<float> gs(groups_n);
789 for (int g = 0; g < groups_n; ++g) {
790 float a = -std::numeric_limits<float>::infinity(), b = -std::numeric_limits<float>::infinity();
791 for (int e = g * per; e < (g + 1) * per; ++e) {
792 if (c[e] > a) {
793 b = a;
794 a = c[e];
795 } else if (c[e] > b) {
796 b = c[e];
797 }
798 }
799 gs[g] = per == 1 ? a : a + b;
800 }
801 std::vector<char> keep(groups_n, 0);
802 for (int j = 0; j < groups_top && j < groups_n; ++j) {
803 int best = -1;
804 for (int g = 0; g < groups_n; ++g)
805 if (!keep[g] && (best < 0 || gs[g] > gs[best])) best = g; // strict >: ties keep the lower group
806 keep[best] = 1;
807 }
808 for (int e = 0; e < E; ++e) cand[e] = keep[e / per];
809 }
810 std::vector<int> sel;
811 std::vector<char> taken(E, 0);
812 for (int j = 0; j < k; ++j) {
813 int best = -1;
814 for (int e = 0; e < E; ++e)
815 if (cand[e] && !taken[e] && (best < 0 || c[e] > c[best])) best = e; // strict >: ties keep the lower index
816 if (best < 0) break;
817 taken[best] = 1;
818 sel.push_back(best);
819 }
820 std::sort(sel.begin(), sel.end()); // accumulate in ascending expert index
821 std::vector<float> gate(E, 0.0f);
822 float z = 0.0f;
823 for (int e : sel) z += sc[e];
824 for (int e : sel) gate[e] = renorm ? sc[e] / z : sc[e];
825 std::fill(out, out + d, 0.0f);
826 std::vector<float> h(d_ff);
827 for (int e : sel) {
828 const float w = gate[e];
829 const float* g = gate_exps + static_cast<size_t>(e) * d_ff * d;
830 const float* u = up_exps + static_cast<size_t>(e) * d_ff * d;
831 const float* dn = down_exps + static_cast<size_t>(e) * d * d_ff;
832 for (int i = 0; i < d_ff; ++i) {
833 const float gv = static_cast<float>(dot_f32_as_f64(g + static_cast<size_t>(i) * d, x, d));
834 const float uv = static_cast<float>(dot_f32_as_f64(u + static_cast<size_t>(i) * d, x, d));
835 h[i] = gv * (1.0f / (1.0f + std::exp(-gv))) * uv;
836 }
837 for (int o = 0; o < d; ++o)
838 out[o] += w * static_cast<float>(dot_f32_as_f64(dn + static_cast<size_t>(o) * d_ff, h.data(), d_ff));
839 }
840}
node sigmoid
void moe_ffn_f32_cpu(const float *x, int d, int d_ff, int E, int k, const float *router, const float *gate_exps, const float *up_exps, const float *down_exps, float *out, bool renorm)
Definition utils.cpp:709

References a, c, dot_f32_as_f64(), j, k, moe_ffn_f32_cpu(), out, and sigmoid.

Referenced by ember_ir::Interpreter::run_nodes().

◆ rmsnorm_batch_cpu()

void rmsnorm_batch_cpu ( const std::vector< float > &  x_batch,
const std::vector< float > &  weight,
std::vector< float > &  out_batch,
int  num_tokens,
int  hidden_size,
float  eps 
)

Definition at line 613 of file utils.cpp.

618 {
619 if (x_batch.empty() || x_batch.size() != (size_t)num_tokens * hidden_size || weight.size() != (size_t)hidden_size) {
620 Logger::error("[RMSNORM_BATCH_CPU] RMSNorm batch size mismatch or empty input. x_batch.size(): " + std::to_string(x_batch.size()) +
621 ", expected x_batch: " + std::to_string((size_t)num_tokens * hidden_size) +
622 ", weight.size(): " + std::to_string(weight.size()) +
623 ", expected weight: " + std::to_string((size_t)hidden_size));
624 out_batch.assign((size_t)num_tokens * hidden_size, 0.0f);
625 return;
626 }
627 out_batch.resize((size_t)num_tokens * hidden_size);
628
629#pragma omp parallel for
630 for (int t = 0; t < num_tokens; ++t) {
631 double ssq = 0.0;
632 size_t token_offset = (size_t)t * hidden_size;
633
634 for (int i = 0; i < hidden_size; ++i) {
635 ssq += static_cast<double>(x_batch[token_offset + i]) * static_cast<double>(x_batch[token_offset + i]);
636 }
637
638 double ssq_mean = ssq / hidden_size;
639 float norm_factor_input_sqrt = static_cast<float>(ssq_mean);
641
642 for (int i = 0; i < hidden_size; ++i) {
644 }
645 }
646}
#define SAFE_SQRT(x)

References Logger::error(), j, and SAFE_SQRT.

Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), TinyLlamaModel::forward_cpu_logits_batch(), and ember_ir::Interpreter::run_nodes().

◆ rmsnorm_vector_cpu()

void rmsnorm_vector_cpu ( const std::vector< float > &  x,
const std::vector< float > &  weight,
std::vector< float > &  out,
float  eps 
)

Definition at line 648 of file utils.cpp.

650 {
651 if (x.empty() || x.size() != weight.size()) {
652 Logger::error("RMSNorm vector size mismatch or empty input.");
653 out.assign(x.size(), 0.0f);
654 return;
655 }
656 out.resize(x.size());
657 size_t n = x.size();
658
659 double ssq = 0.0;
660#pragma omp parallel for reduction(+ : ssq)
661 for (int64_t i = 0; i < static_cast<int64_t>(n); ++i) {
662 ssq += static_cast<double>(x[i]) * static_cast<double>(x[i]);
663 }
664 ssq /= n;
665
666 float norm_factor = 1.0f / SAFE_SQRT(static_cast<float>(ssq) +
668
669#pragma omp parallel for
670 for (int64_t i = 0; i < static_cast<int64_t>(n); ++i) {
671 out[i] = x[i] * norm_factor * weight[i];
672 }
673}
#define SAFE_MAX(a, b)
constexpr float MIN_NORM_EPS

References Logger::error(), j, numeric::MIN_NORM_EPS, n, out, SAFE_MAX, and SAFE_SQRT.

Referenced by TinyLlamaModel::forward().

◆ silu_cpu()

void silu_cpu ( const std::vector< float > &  x,
std::vector< float > &  out 
)

Definition at line 842 of file utils.cpp.

842 {
843 if (x.size() != out.size()) out.resize(x.size());
844#pragma omp parallel for
845 for (int64_t i = 0; i < static_cast<int64_t>(x.size()); ++i) {
846 float sigmoid_x = 1.0f / (1.0f + std::exp(-x[i]));
847 out[i] = x[i] * sigmoid_x;
848 }
849}

References j, and out.

Referenced by TinyLlamaModel::forward(), and ember_ir::Interpreter::run_nodes().

◆ simd_dot_product()

float simd_dot_product ( const float *  a,
const float *  b,
int  n 
)

Definition at line 36 of file utils.cpp.

36 {
37#if defined(__AVX2__)
39 int i = 0;
40 for (; i <= n - 8; i += 8) {
44 }
45 float result[8];
47 float final_sum = result[0] + result[1] + result[2] + result[3] +
48 result[4] + result[5] + result[6] + result[7];
49 for (; i < n; ++i) {
50 final_sum += a[i] * b[i];
51 }
52 return final_sum;
53#elif defined(__SSE2__)
55 int i = 0;
56 for (; i <= n - 4; i += 4) {
60 }
61 float result[4];
63 float final_sum = result[0] + result[1] + result[2] + result[3];
64 for (; i < n; ++i) {
65 final_sum += a[i] * b[i];
66 }
67 return final_sum;
68#elif defined(__ARM_NEON)
70 int i = 0;
71 for (; i <= n - 4; i += 4) {
74 sum = vmlaq_f32(sum, va, vb);
75 }
76 float result[4];
78 float final_sum = result[0] + result[1] + result[2] + result[3];
79 for (; i < n; ++i) {
80 final_sum += a[i] * b[i];
81 }
82 return final_sum;
83#else
84 float sum = 0.0f;
85 for (int i = 0; i < n; ++i) {
86 sum += a[i] * b[i];
87 }
88 return sum;
89#endif
90}

References a, j, and n.

Referenced by TinyLlamaModel::forward_cpu_batch_generation().

◆ simd_scaled_add()

void simd_scaled_add ( float *  dst,
const float *  src,
float  scale,
int  n 
)

Definition at line 93 of file utils.cpp.

93 {
94#if defined(__AVX2__)
96 int i = 0;
97 for (; i <= n - 8; i += 8) {
102 }
103 for (; i < n; ++i) {
104 dst[i] += src[i] * scale;
105 }
106#elif defined(__SSE2__)
108 int i = 0;
109 for (; i <= n - 4; i += 4) {
114 }
115 for (; i < n; ++i) {
116 dst[i] += src[i] * scale;
117 }
118#elif defined(__ARM_NEON)
120 int i = 0;
121 for (; i <= n - 4; i += 4) {
125 vst1q_f32(&dst[i], result);
126 }
127 for (; i < n; ++i) {
128 dst[i] += src[i] * scale;
129 }
130#else
131 for (int i = 0; i < n; ++i) {
132 dst[i] += src[i] * scale;
133 }
134#endif
135}

References j, n, and scale.

Referenced by TinyLlamaModel::forward_cpu_batch_generation().

◆ softmax_vector_cpu()

void softmax_vector_cpu ( const std::vector< float > &  x,
std::vector< float > &  out 
)

Definition at line 675 of file utils.cpp.

676 {
677 if (x.empty()) return;
678 out.resize(x.size());
679 size_t n = x.size();
680
681 float max_val = x[0];
682 for (size_t i = 1; i < n; ++i) {
683 if (x[i] > max_val) max_val = x[i];
684 }
685
686 float exp_sum = 0.0f;
687 for (size_t i = 0; i < n; ++i) {
688 out[i] = std::exp(x[i] - max_val);
689 exp_sum += out[i];
690 }
691
692 float inv_sum = 1.0f / (exp_sum + 1e-9f);
693
694#pragma omp parallel for
695 for (int64_t i = 0; i < static_cast<int64_t>(n); ++i) {
696 out[i] *= inv_sum;
697 }
698}

References j, n, and out.

Referenced by attention_batch_cpu(), attention_batch_cpu_sequence_aware(), attention_bias_batch_cpu(), attention_relkv_batch_cpu(), attention_rows_batch_cpu(), attention_window_batch_cpu(), TinyLlamaModel::forward(), and TinyLlamaModel::forward_cpu_batch_generation().

◆ uint8_vector_to_uint16_vector()

std::vector< uint16_t > uint8_vector_to_uint16_vector ( const std::vector< uint8_t > &  bytes,
size_t  numel 
)

Definition at line 177 of file utils.cpp.

177 {
178 if (bytes.size() != numel * 2) {
179 throw std::runtime_error("Byte vector size mismatch for uint16_t conversion");
180 }
181 std::vector<uint16_t> out(numel);
182 std::memcpy(out.data(), bytes.data(), bytes.size());
183 return out;
184}
size_t numel

References j, numel, and out.

◆ weighted_sum_probs_v()

void weighted_sum_probs_v ( const std::vector< float > &  probs,
const std::vector< float > &  V,
std::vector< float > &  out,
int  seq_len,
int  head_dim 
)

Definition at line 1227 of file utils.cpp.

1229 {
1230 if (probs.size() != seq_len || V.size() != (size_t)seq_len * head_dim) {
1231 Logger::error("weighted_sum_probs_v: Size mismatch. Probs: " +
1232 std::to_string(probs.size()) + " (Expected " +
1233 std::to_string(seq_len) +
1234 "), V: " + std::to_string(V.size()) + " (Expected " +
1235 std::to_string(seq_len * head_dim) + ")");
1236 out.assign(head_dim, 0.0f);
1237 return;
1238 }
1239 out.resize(head_dim);
1240
1241#pragma omp parallel for
1243 double sum = 0.0;
1244 double c_kahan = 0.0;
1245 for (int i = 0; i < seq_len; ++i) {
1246 double term = static_cast<double>(probs[i]) *
1247 static_cast<double>(V[i * head_dim + j]);
1248
1249 double y = term - c_kahan;
1250 double t = sum + y;
1251 c_kahan = (t - sum) - y;
1252 sum = t;
1253 }
1254 out[j] = static_cast<float>(sum);
1255 }
1256}

References Logger::error(), j, and out.

◆ write_vector_to_file()

bool write_vector_to_file ( const std::string &  filename,
const std::vector< float > &  vec 
)

Definition at line 1301 of file utils.cpp.

1301 {
1302 std::string vec_writer_vals;
1303 int N_log_writer = (std::min)(10, (int)vec.size());
1304 for (int i = 0; i < N_log_writer; ++i)
1305 vec_writer_vals += (i ? " " : "") + std::to_string(vec[i]);
1306 Logger::info("write_vector_to_file Enter: Address of vec.data() on entry: " +
1307 std::to_string(reinterpret_cast<uintptr_t>(vec.data())));
1308
1309 std::ofstream outfile(filename, std::ios::binary);
1310 if (!outfile) {
1311 Logger::error("Failed to open file for writing: " + filename);
1312 return false;
1313 }
1314 outfile.write(reinterpret_cast<const char*>(vec.data()),
1315 vec.size() * sizeof(float));
1316 if (!outfile) {
1317 Logger::error("Failed to write data to file: " + filename);
1318 return false;
1319 }
1320 Logger::info("Successfully wrote vector to " + filename);
1321 return true;
1322}

References Logger::error(), Logger::info(), and j.