ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
cpu_attention.h File Reference
#include <vector>
#include <cmath>
#include "kv_cache.h"
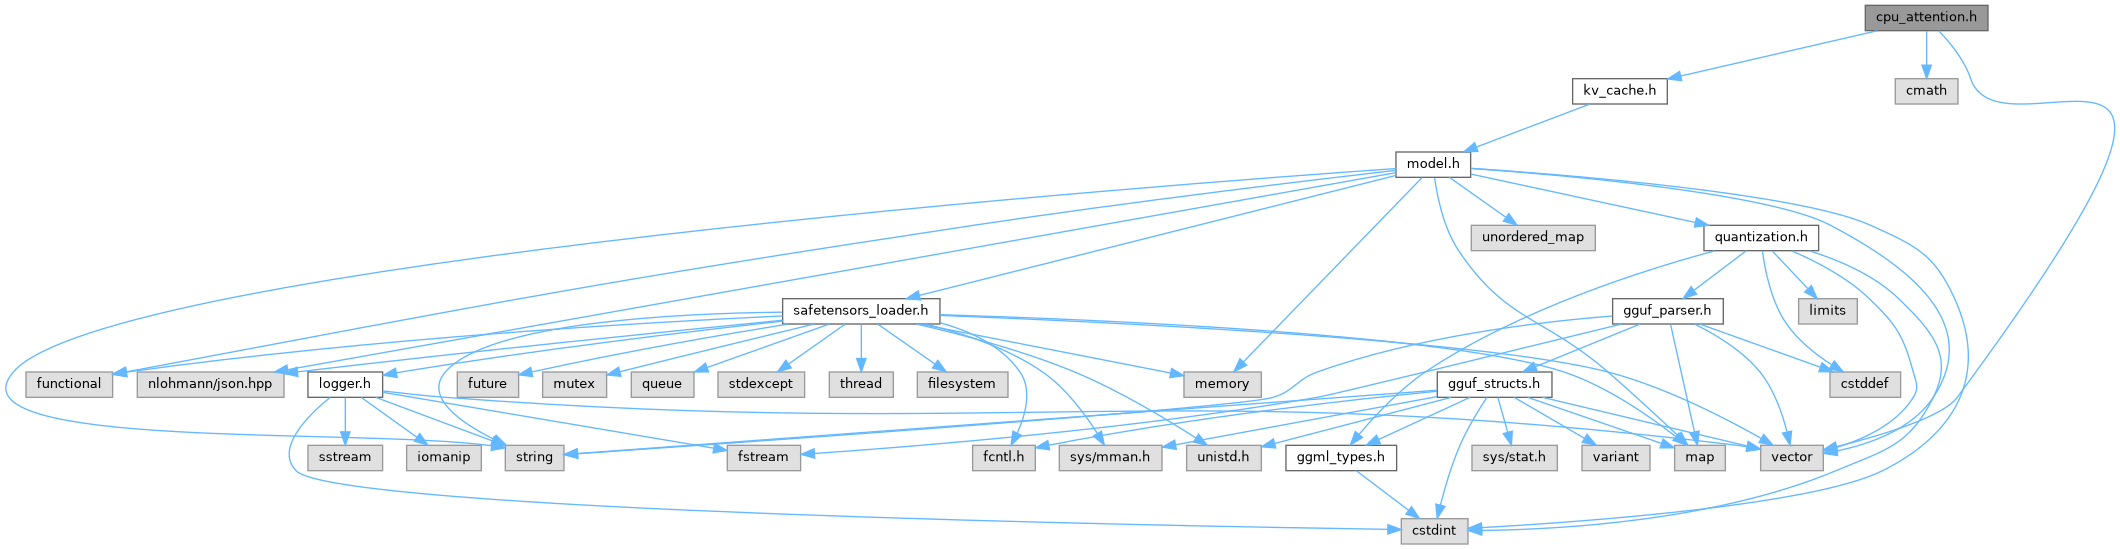
Include dependency graph for cpu_attention.h:
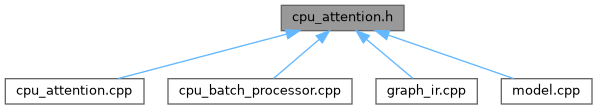
This graph shows which files directly or indirectly include this file:

Go to the source code of this file.

Functions

float softcap_score (float s, float c)
 
void update_kv_cache_batch_cpu (KVCache *kv_cache, int layer_idx, const std::vector< float > &k_batch_for_layer, const std::vector< float > &v_batch_for_layer, int num_tokens_in_batch, int start_pos_in_sequence, int num_kv_heads, int head_dim)
 
void attention_batch_cpu (const std::vector< float > &q_batch_roped, KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, int start_pos_in_sequence, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, float softcap=0.0f)
 
void swa_visible_ranges (int pos, int window, int sinks, int &sink_hi, int &win_lo)
 
void attention_window_batch_cpu (const std::vector< float > &q_batch_roped, KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, int start_pos_in_sequence, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, int window, int sinks, float softcap=0.0f)
 
void attention_rows_batch_cpu (const std::vector< float > &q_batch_roped, const KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, const std::vector< std::vector< int > > &rows, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, float softcap=0.0f)
 
std::vector< std::vector< int > > attention_visible_rows (int num_tokens_in_batch, int start_pos_in_sequence, int window, int sinks)
 
void attention_bias_batch_cpu (const std::vector< float > &q_batch_roped, const KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, const std::vector< std::vector< int > > &rows, const std::vector< int > *key_pos, const std::vector< int > &query_pos, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, const float *bias, const std::vector< int > &buckets, float softcap=0.0f)
 
void attention_relkv_batch_cpu (const std::vector< float > &q_batch_roped, const KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, const std::vector< std::vector< int > > &rows, const std::vector< int > *key_pos, const std::vector< int > &query_pos, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, const float *rk, int rk_width, const float *rv, int rv_width, int max_distance, float softcap=0.0f)
 
void update_kv_cache_batch_cpu_sequence_aware (KVCache *kv_cache, int layer_idx, const std::vector< float > &k_batch_for_layer, const std::vector< float > &v_batch_for_layer, int num_tokens_in_batch, const std::vector< int > &sequence_indices, const std::vector< int > &position_in_sequence, int num_kv_heads, int head_dim)
 
void attention_batch_cpu_sequence_aware (const std::vector< float > &q_batch_roped, KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, const std::vector< int > &sequence_indices, const std::vector< int > &position_in_sequence, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, int max_seq_len_per_sequence)
 

Function Documentation

◆ attention_batch_cpu()

void attention_batch_cpu ( const std::vector< float > &  q_batch_roped,
KVCacheLayer &  current_layer_kv_cache,
std::vector< float > &  batch_attn_output,
int  num_tokens_in_batch,
int  start_pos_in_sequence,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
float  attention_scale,
float  softcap = 0.0f 
)

Definition at line 92 of file cpu_attention.cpp.

103 {
105 if (q_batch_roped.size() != expected_q_size) {
106 Logger::error("[ATTN_BATCH_CPU] q_batch_roped size mismatch. Expected: " + std::to_string(expected_q_size) +
107 ", Got: " + std::to_string(q_batch_roped.size()));
108 std::fill(batch_attn_output.begin(), batch_attn_output.end(), 0.0f);
109 return;
110 }
111 Logger::info("[ATTENTION_BATCH_CPU_ENTRY] Called with num_tokens=" + std::to_string(num_tokens_in_batch));
114
115 // Tokens are independent (each writes its own output rows; scores are
116 // per-iteration), so they run in parallel with unchanged arithmetic.
117#if defined(__EMSCRIPTEN_PTHREADS__)
119#else
120#pragma omp parallel for schedule(dynamic)
122#endif
126
127 for (int h_q = 0; h_q < num_q_heads; ++h_q) {
128 const float* q_head_for_token_ptr = q_batch_roped.data() + q_token_offset + (h_q * head_dim);
130
131 bool log_details_for_this_head = (token_idx == 0 && h_q == 0);
132
133
135 if (history_len <= 0) {
136 Logger::warning("[ATTN_BATCH_CPU] Token_idx " + std::to_string(token_idx) + ", Q_Head " + std::to_string(h_q) +
137 ": history_len is " + std::to_string(history_len) + ". Skipping score calculation for this head.");
138 continue;
139 }
140 std::vector<float> scores(history_len);
141
142 for (int t_hist = 0; t_hist < history_len; ++t_hist) {
144 if (token_idx == 0 && h_q == 0 && t_hist < 3) {
145 Logger::info("[CPU_ATTN_MEM] T" + std::to_string(token_idx) + "_H" + std::to_string(h_q) +
146 " accessing K_cache[pos=" + std::to_string(t_hist) + ",kv_head=" + std::to_string(kv_group_head_idx) +
147 "]: offset=" + std::to_string(k_cache_offset) +
148 ", k_vals=[" + std::to_string(current_layer_kv_cache.k[k_cache_offset]) +
149 "," + std::to_string(current_layer_kv_cache.k[k_cache_offset + 1]) +
150 "," + std::to_string(current_layer_kv_cache.k[k_cache_offset + 2]) + "]");
151 }
153 Logger::error("[ATTN_BATCH_CPU] K cache out of bounds. Token_idx " + std::to_string(token_idx) +
154 " (abs_pos " + std::to_string(current_token_absolute_pos) + "), Q_Head " + std::to_string(h_q) +
155 ", history_pos " + std::to_string(t_hist) +
156 ". Required k_cache_offset " + std::to_string(k_cache_offset + head_dim) +
157 " > cache_k_size " + std::to_string(current_layer_kv_cache.k.size()));
158 scores[t_hist] = -std::numeric_limits<float>::infinity();
159 continue;
160 }
161
162 float current_dot_product = 0.0f;
163 for (int d = 0; d < head_dim; ++d) {
165 }
166 if (token_idx == 0 && h_q == 0 && t_hist < 2) {
167 Logger::info("[CPU_ATTN_SCORE] T0_H0 pos=" + std::to_string(t_hist) +
168 ", q_vals=[" + std::to_string(q_head_for_token_ptr[0]) +
169 "," + std::to_string(q_head_for_token_ptr[1]) + "] " +
170 ", k_vals=[" + std::to_string(current_layer_kv_cache.k[k_cache_offset]) +
171 "," + std::to_string(current_layer_kv_cache.k[k_cache_offset + 1]) + "]" +
172 ", dot=" + std::to_string(current_dot_product) + ", scale=" + std::to_string(attention_scale));
173 }
175
176 }
177
178 softmax_vector_cpu(scores, scores);
179 if (token_idx == 0 && h_q == 0) {
180 std::string scores_str = "";
181 for (int i = 0; i < std::min(3, (int)scores.size()); i++) {
182 scores_str += std::to_string(scores[i]) + " ";
183 }
184 Logger::info("[CPU_SOFTMAX] T0_H0 first_3_probs=[" + scores_str + "]");
185 }
187
188 for (int t_hist = 0; t_hist < history_len; ++t_hist) {
189 if (scores[t_hist] == -std::numeric_limits<float>::infinity() || scores[t_hist] == 0.0f) continue;
190
193 Logger::error("[ATTN_BATCH_CPU] V cache out of bounds. Token_idx " + std::to_string(token_idx) +
194 " (abs_pos " + std::to_string(current_token_absolute_pos) + "), Q_Head " + std::to_string(h_q) +
195 ", history_pos " + std::to_string(t_hist) +
196 ". Required v_cache_offset " + std::to_string(v_cache_offset + head_dim) +
197 " > cache_v_size " + std::to_string(current_layer_kv_cache.v.size()));
198 continue;
199 }
200
201 for (int d = 0; d < head_dim; ++d) {
202 float val_before = (log_details_for_this_head && t_hist < 2 && d < 2) ? current_attn_out_head_ptr[d] : 0.0f;
204 }
205 }
206 }
207 }
208#if defined(__EMSCRIPTEN_PTHREADS__)
209 );
210#endif
211}
static void warning(const std::string &message)
Definition logger.cpp:139
static void info(const std::string &message)
Definition logger.cpp:135
static void error(const std::string &message)
Definition logger.cpp:143
float softcap_score(float s, float c)
size_t j
void parallel_for(int64_t n, F &&fn)
void softmax_vector_cpu(const std::vector< float > &x, std::vector< float > &out)
Definition utils.cpp:675

References Logger::error(), Logger::info(), j, ember::parallel_for(), softcap_score(), softmax_vector_cpu(), and Logger::warning().

Referenced by attention_window_batch_cpu(), CPUBatchProcessor::forward_cpu_batch(), and ember_ir::Interpreter::run_nodes().

◆ attention_batch_cpu_sequence_aware()

void attention_batch_cpu_sequence_aware ( const std::vector< float > &  q_batch_roped,
KVCacheLayer &  current_layer_kv_cache,
std::vector< float > &  batch_attn_output,
int  num_tokens_in_batch,
const std::vector< int > &  sequence_indices,
const std::vector< int > &  position_in_sequence,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
float  attention_scale,
int  max_seq_len_per_sequence 
)

Definition at line 589 of file cpu_attention.cpp.

601 {
603 if (q_batch_roped.size() != expected_q_size) {
604 Logger::error("[ATTN_BATCH_CPU_SEQ_AWARE] q_batch_roped size mismatch. Expected: " + std::to_string(expected_q_size) +
605 ", Got: " + std::to_string(q_batch_roped.size()));
606 std::fill(batch_attn_output.begin(), batch_attn_output.end(), 0.0f);
607 return;
608 }
609
611
615
619
620 for (int h_q = 0; h_q < num_q_heads; ++h_q) {
621 const float* q_head_for_token_ptr = q_batch_roped.data() + q_token_offset + (h_q * head_dim);
623
624 int history_len = pos_in_seq + 1;
625 std::vector<float> scores(history_len);
626
627 for (int t_hist = 0; t_hist < history_len; ++t_hist) {
629
631 scores[t_hist] = -std::numeric_limits<float>::infinity();
632 continue;
633 }
634
635 float current_dot_product = 0.0f;
636 for (int d = 0; d < head_dim; ++d) {
638 }
640 }
641
642 softmax_vector_cpu(scores, scores);
643
645
646 for (int t_hist = 0; t_hist < history_len; ++t_hist) {
647 if (scores[t_hist] == -std::numeric_limits<float>::infinity() || scores[t_hist] == 0.0f) continue;
648
651 continue;
652 }
653
654 for (int d = 0; d < head_dim; ++d) {
656 }
657 }
658 }
659 }
660}

References Logger::error(), j, and softmax_vector_cpu().

Referenced by CPUBatchProcessor::forward_cpu_batch().

◆ attention_bias_batch_cpu()

void attention_bias_batch_cpu ( const std::vector< float > &  q_batch_roped,
const KVCacheLayer &  current_layer_kv_cache,
std::vector< float > &  batch_attn_output,
int  num_tokens_in_batch,
const std::vector< std::vector< int > > &  rows,
const std::vector< int > *  key_pos,
const std::vector< int > &  query_pos,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
float  attention_scale,
const float *  bias,
const std::vector< int > &  buckets,
float  softcap = 0.0f 
)

Definition at line 368 of file cpu_attention.cpp.

383 {
385 batch_attn_output.assign(expected_size, 0.0f);
386 if (q_batch_roped.size() != expected_size || rows.size() != (size_t)num_tokens_in_batch ||
387 query_pos.size() != (size_t)num_tokens_in_batch || buckets.empty() || !bias) {
388 Logger::error("[ATTN_BIAS_CPU] q, row lists, positions or the bias table do not match the batch");
389 return;
390 }
391 const size_t row_floats = (size_t)num_kv_heads * head_dim;
392 const int D = static_cast<int>(buckets.size());
393#if defined(__EMSCRIPTEN_PTHREADS__)
395#else
396#pragma omp parallel for schedule(dynamic)
398#endif
400 const std::vector<int>& visible = rows[token_idx];
401 const int p = query_pos[token_idx];
402 std::vector<float> scores(visible.size());
403 std::vector<int> bucket(visible.size());
404 bool in_range = !visible.empty();
405 for (size_t i = 0; i < visible.size(); ++i) {
406 const int r = visible[i];
407 if (r < 0 || ((size_t)r + 1) * row_floats > current_layer_kv_cache.k.size() ||
408 ((size_t)r + 1) * row_floats > current_layer_kv_cache.v.size() ||
409 (key_pos && (size_t)r >= key_pos->size())) {
410 in_range = false;
411 break;
412 }
413 const int j = key_pos ? (*key_pos)[r] : r;
414 const int n = std::min(std::max(p - j, 0), D - 1);
415 bucket[i] = buckets[n];
416 }
417 if (in_range) {
418 for (int h_q = 0; h_q < num_q_heads; ++h_q) {
419 const float* q_head = q_batch_roped.data() + token_offset + (h_q * head_dim);
420 const int kv_head = h_q / (num_q_heads / num_kv_heads);
421 for (size_t i = 0; i < visible.size(); ++i) {
422 const size_t k_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
423 float dot = 0.0f;
424 for (int d = 0; d < head_dim; ++d) dot += q_head[d] * current_layer_kv_cache.k[k_off + d];
425 // rounded (and capped, revision 1.5), then the bias added and rounded
426 const float s = softcap_score(dot * attention_scale, softcap);
427 scores[i] = s + bias[(size_t)bucket[i] * num_q_heads + h_q];
428 }
429 softmax_vector_cpu(scores, scores);
430 float* out_head = batch_attn_output.data() + token_offset + (h_q * head_dim);
431 for (size_t i = 0; i < visible.size(); ++i) {
432 if (scores[i] == -std::numeric_limits<float>::infinity() || scores[i] == 0.0f) continue;
433 const size_t v_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
434 for (int d = 0; d < head_dim; ++d) out_head[d] += scores[i] * current_layer_kv_cache.v[v_off + d];
435 }
436 }
437 }
438 }
439#if defined(__EMSCRIPTEN_PTHREADS__)
440 );
441#endif
442}
const float * p[kIrDepthSourcesMax]
int n

References Logger::error(), j, n, p, ember::parallel_for(), softcap_score(), and softmax_vector_cpu().

Referenced by ember_ir::Interpreter::run_nodes().

◆ attention_relkv_batch_cpu()

void attention_relkv_batch_cpu ( const std::vector< float > &  q_batch_roped,
const KVCacheLayer &  current_layer_kv_cache,
std::vector< float > &  batch_attn_output,
int  num_tokens_in_batch,
const std::vector< std::vector< int > > &  rows,
const std::vector< int > *  key_pos,
const std::vector< int > &  query_pos,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
float  attention_scale,
const float *  rk,
int  rk_width,
const float *  rv,
int  rv_width,
int  max_distance,
float  softcap = 0.0f 
)

Definition at line 444 of file cpu_attention.cpp.

462 {
464 batch_attn_output.assign(expected_size, 0.0f);
465 const auto width_ok = [&](int w) { return w == head_dim || w == num_q_heads * head_dim; };
466 if (q_batch_roped.size() != expected_size || rows.size() != (size_t)num_tokens_in_batch ||
468 (rv && !width_ok(rv_width))) {
469 Logger::error("[ATTN_RELKV_CPU] q, row lists, positions or the relative tables do not match the batch");
470 return;
471 }
472 const size_t row_floats = (size_t)num_kv_heads * head_dim;
473 // a head's column offset within a table row: 0 when the vectors are shared, h * head_dim per head
475#if defined(__EMSCRIPTEN_PTHREADS__)
477#else
478#pragma omp parallel for schedule(dynamic)
480#endif
482 const std::vector<int>& visible = rows[token_idx];
483 const int p = query_pos[token_idx];
484 std::vector<float> scores(visible.size());
485 std::vector<int> dist(visible.size());
486 std::vector<float> rel_sum((size_t)head_dim);
487 bool in_range = !visible.empty();
488 for (size_t i = 0; i < visible.size(); ++i) {
489 const int r = visible[i];
490 if (r < 0 || ((size_t)r + 1) * row_floats > current_layer_kv_cache.k.size() ||
491 ((size_t)r + 1) * row_floats > current_layer_kv_cache.v.size() ||
492 (key_pos && (size_t)r >= key_pos->size())) {
493 in_range = false;
494 break;
495 }
496 const int j = key_pos ? (*key_pos)[r] : r;
497 dist[i] = std::min(std::max(p - j, 0), max_distance);
498 }
499 if (in_range) {
500 for (int h_q = 0; h_q < num_q_heads; ++h_q) {
501 const float* q_head = q_batch_roped.data() + token_offset + (h_q * head_dim);
502 const int kv_head = h_q / (num_q_heads / num_kv_heads);
503 const size_t rk_col = rk_per_head ? (size_t)h_q * head_dim : 0;
504 for (size_t i = 0; i < visible.size(); ++i) {
505 const size_t k_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
506 const float* rk_row = rk + (size_t)dist[i] * rk_width + rk_col;
507 float dot = 0.0f, rel = 0.0f;
508 for (int d = 0; d < head_dim; ++d) dot += q_head[d] * current_layer_kv_cache.k[k_off + d];
509 for (int d = 0; d < head_dim; ++d) rel += q_head[d] * rk_row[d];
510 const float s = dot + rel; // rounded, then the product
512 }
513 softmax_vector_cpu(scores, scores);
514 float* out_head = batch_attn_output.data() + token_offset + (h_q * head_dim);
515 for (size_t i = 0; i < visible.size(); ++i) {
516 if (scores[i] == -std::numeric_limits<float>::infinity() || scores[i] == 0.0f) continue;
517 const size_t v_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
518 for (int d = 0; d < head_dim; ++d) out_head[d] += scores[i] * current_layer_kv_cache.v[v_off + d];
519 }
520 if (rv) { // the second sum from 0, then added to the first
521 const size_t rv_col = rv_per_head ? (size_t)h_q * head_dim : 0;
522 std::fill(rel_sum.begin(), rel_sum.end(), 0.0f);
523 for (size_t i = 0; i < visible.size(); ++i) {
524 if (scores[i] == -std::numeric_limits<float>::infinity() || scores[i] == 0.0f) continue;
525 const float* rv_row = rv + (size_t)dist[i] * rv_width + rv_col;
526 for (int d = 0; d < head_dim; ++d) rel_sum[d] += scores[i] * rv_row[d];
527 }
528 for (int d = 0; d < head_dim; ++d) out_head[d] = out_head[d] + rel_sum[d];
529 }
530 }
531 }
532 }
533#if defined(__EMSCRIPTEN_PTHREADS__)
534 );
535#endif
536}

References Logger::error(), j, p, ember::parallel_for(), softcap_score(), and softmax_vector_cpu().

Referenced by ember_ir::Interpreter::run_nodes().

◆ attention_rows_batch_cpu()

void attention_rows_batch_cpu ( const std::vector< float > &  q_batch_roped,
const KVCacheLayer &  current_layer_kv_cache,
std::vector< float > &  batch_attn_output,
int  num_tokens_in_batch,
const std::vector< std::vector< int > > &  rows,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
float  attention_scale,
float  softcap = 0.0f 
)

Definition at line 296 of file cpu_attention.cpp.

307 {
309 batch_attn_output.assign(expected_size, 0.0f);
310 if (q_batch_roped.size() != expected_size || rows.size() != (size_t)num_tokens_in_batch) {
311 Logger::error("[ATTN_ROWS_CPU] q or row lists do not match the batch");
312 return;
313 }
314 const size_t row_floats = (size_t)num_kv_heads * head_dim;
315 // The body of attention_window_batch_cpu with the visible list given.
316#if defined(__EMSCRIPTEN_PTHREADS__)
318#else
319#pragma omp parallel for schedule(dynamic)
321#endif
323 const std::vector<int>& visible = rows[token_idx];
324 std::vector<float> scores(visible.size());
325 bool in_range = !visible.empty();
326 for (int r : visible)
327 if (r < 0 || ((size_t)r + 1) * row_floats > current_layer_kv_cache.k.size() ||
328 ((size_t)r + 1) * row_floats > current_layer_kv_cache.v.size())
329 in_range = false;
330 if (in_range) {
331 for (int h_q = 0; h_q < num_q_heads; ++h_q) {
332 const float* q_head = q_batch_roped.data() + token_offset + (h_q * head_dim);
333 const int kv_head = h_q / (num_q_heads / num_kv_heads);
334 for (size_t i = 0; i < visible.size(); ++i) {
335 const size_t k_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
336 float dot = 0.0f;
337 for (int d = 0; d < head_dim; ++d) dot += q_head[d] * current_layer_kv_cache.k[k_off + d];
339 }
340 softmax_vector_cpu(scores, scores);
341 float* out_head = batch_attn_output.data() + token_offset + (h_q * head_dim);
342 for (size_t i = 0; i < visible.size(); ++i) {
343 if (scores[i] == -std::numeric_limits<float>::infinity() || scores[i] == 0.0f) continue;
344 const size_t v_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
345 for (int d = 0; d < head_dim; ++d) out_head[d] += scores[i] * current_layer_kv_cache.v[v_off + d];
346 }
347 }
348 }
349 }
350#if defined(__EMSCRIPTEN_PTHREADS__)
351 );
352#endif
353}
std::vector< float > v

References Logger::error(), j, ember::parallel_for(), softcap_score(), and softmax_vector_cpu().

Referenced by ember_ir::Interpreter::run_nodes().

◆ attention_visible_rows()

std::vector< std::vector< int > > attention_visible_rows ( int  num_tokens_in_batch,
int  start_pos_in_sequence,
int  window,
int  sinks 
)

Definition at line 355 of file cpu_attention.cpp.

356 {
357 std::vector<std::vector<int>> rows(static_cast<size_t>(std::max(num_tokens_in_batch, 0)));
358 for (int t = 0; t < num_tokens_in_batch; ++t) {
359 const int pos = start_pos_in_sequence + t;
360 int sink_hi = 0, win_lo = 0;
362 for (int r = 0; r < sink_hi; ++r) rows[t].push_back(r);
363 for (int r = win_lo; r <= pos; ++r) rows[t].push_back(r);
364 }
365 return rows;
366}
void swa_visible_ranges(int pos, int window, int sinks, int &sink_hi, int &win_lo)

References j, pos, and swa_visible_ranges().

Referenced by ember_ir::Interpreter::run_nodes().

◆ attention_window_batch_cpu()

void attention_window_batch_cpu ( const std::vector< float > &  q_batch_roped,
KVCacheLayer &  current_layer_kv_cache,
std::vector< float > &  batch_attn_output,
int  num_tokens_in_batch,
int  start_pos_in_sequence,
int  num_q_heads,
int  num_kv_heads,
int  head_dim,
float  attention_scale,
int  window,
int  sinks,
float  softcap = 0.0f 
)

Definition at line 219 of file cpu_attention.cpp.

232 {
233 // window 0 is unbounded attention: today's kernel, untouched.
234 if (window <= 0) {
237 return;
238 }
240 batch_attn_output.assign(expected_size, 0.0f);
241 if (q_batch_roped.size() != expected_size) {
242 Logger::error("[ATTN_WINDOW_CPU] q_batch_roped size mismatch. Expected: " + std::to_string(expected_size) +
243 ", Got: " + std::to_string(q_batch_roped.size()));
244 return;
245 }
247 if (needed > current_layer_kv_cache.k.size() || needed > current_layer_kv_cache.v.size()) {
248 Logger::error("[ATTN_WINDOW_CPU] KV cache holds fewer than " +
249 std::to_string(start_pos_in_sequence + num_tokens_in_batch) + " positions");
250 return;
251 }
252
253 // The visible keys in ascending position (sinks, then the window), each
254 // scored, softmaxed and accumulated exactly as attention_batch_cpu does
255 // over its full history: when the window covers [0, pos] the two kernels
256 // perform the same operations in the same order.
257#if defined(__EMSCRIPTEN_PTHREADS__)
259#else
260#pragma omp parallel for schedule(dynamic)
262#endif
264 const int pos = start_pos_in_sequence + (int)token_idx;
265 int sink_hi = 0, win_lo = 0;
267 std::vector<int> visible;
268 visible.reserve((size_t)sink_hi + (pos + 1 - win_lo));
269 for (int t = 0; t < sink_hi; ++t) visible.push_back(t);
270 for (int t = win_lo; t <= pos; ++t) visible.push_back(t);
271 std::vector<float> scores(visible.size());
272
273 for (int h_q = 0; h_q < num_q_heads; ++h_q) {
274 const float* q_head = q_batch_roped.data() + token_offset + (h_q * head_dim);
275 const int kv_head = h_q / (num_q_heads / num_kv_heads);
276 for (size_t i = 0; i < visible.size(); ++i) {
277 const size_t k_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
278 float dot = 0.0f;
279 for (int d = 0; d < head_dim; ++d) dot += q_head[d] * current_layer_kv_cache.k[k_off + d];
281 }
282 softmax_vector_cpu(scores, scores);
283 float* out_head = batch_attn_output.data() + token_offset + (h_q * head_dim);
284 for (size_t i = 0; i < visible.size(); ++i) {
285 if (scores[i] == -std::numeric_limits<float>::infinity() || scores[i] == 0.0f) continue;
286 const size_t v_off = ((size_t)visible[i] * num_kv_heads + kv_head) * head_dim;
287 for (int d = 0; d < head_dim; ++d) out_head[d] += scores[i] * current_layer_kv_cache.v[v_off + d];
288 }
289 }
290 }
291#if defined(__EMSCRIPTEN_PTHREADS__)
292 );
293#endif
294}
void attention_batch_cpu(const std::vector< float > &q_batch_roped, KVCacheLayer &current_layer_kv_cache, std::vector< float > &batch_attn_output, int num_tokens_in_batch, int start_pos_in_sequence, int num_q_heads, int num_kv_heads, int head_dim, float attention_scale, float softcap)

References attention_batch_cpu(), Logger::error(), j, ember::parallel_for(), pos, softcap_score(), softmax_vector_cpu(), and swa_visible_ranges().

Referenced by ember_ir::Interpreter::run_nodes().

◆ softcap_score()

float softcap_score ( float  s,
float  c 
)
inline

Definition at line 9 of file cpu_attention.h.

9{ return c > 0.0f ? c * std::tanh(s / c) : s; }
float c

References c, and j.

Referenced by attention_batch_cpu(), attention_bias_batch_cpu(), attention_relkv_batch_cpu(), attention_rows_batch_cpu(), and attention_window_batch_cpu().

◆ swa_visible_ranges()

void swa_visible_ranges ( int  pos,
int  window,
int  sinks,
int &  sink_hi,
int &  win_lo 
)

Definition at line 213 of file cpu_attention.cpp.

213 {
214 // paperkiln ops.cpp swa_attention, ranges(): [0, sink_hi) then [win_lo, pos].
215 win_lo = pos + 1 > window ? pos + 1 - window : 0;
216 sink_hi = std::min(std::min(sinks, pos + 1), win_lo);
217}

References j, and pos.

Referenced by attention_visible_rows(), attention_window_batch_cpu(), and ember_ir::Interpreter::run_nodes().

◆ update_kv_cache_batch_cpu()

void update_kv_cache_batch_cpu ( KVCache *  kv_cache,
int  layer_idx,
const std::vector< float > &  k_batch_for_layer,
const std::vector< float > &  v_batch_for_layer,
int  num_tokens_in_batch,
int  start_pos_in_sequence,
int  num_kv_heads,
int  head_dim 
)

Definition at line 8 of file cpu_attention.cpp.

17 {
18 if (!kv_cache) {
19 Logger::error("update_kv_cache_batch_cpu: KVCache is null.");
20 return;
21 }
22 if (layer_idx < 0 || static_cast<size_t>(layer_idx) >= kv_cache->layers.size()) {
23 Logger::error("update_kv_cache_batch_cpu: layer_idx " + std::to_string(layer_idx) + " is out of bounds for KVCache layers (size " + std::to_string(kv_cache->layers.size()) + ").");
24 return;
25 }
26 Logger::info("[CPU_KV_UPDATE] Layer=" + std::to_string(layer_idx) +
27 ", start_pos=" + std::to_string(start_pos_in_sequence) +
28 ", num_tokens=" + std::to_string(num_tokens_in_batch) +
29 ", k_batch_first_vals=[" + std::to_string(k_batch_for_layer[0]) +
30 "," + std::to_string(k_batch_for_layer[1]) + "," + std::to_string(k_batch_for_layer[2]) + "]");
33
34 if (k_batch_for_layer.size() != static_cast<size_t>(num_tokens_in_batch * kv_dim)) {
35 Logger::error("[KV_BATCH_UPDATE L" + std::to_string(layer_idx) + "] k_batch_for_layer size mismatch. Expected " +
36 std::to_string(num_tokens_in_batch * kv_dim) + ", got " + std::to_string(k_batch_for_layer.size()));
37 return;
38 }
39
40 if (v_batch_for_layer.size() != static_cast<size_t>(num_tokens_in_batch * kv_dim)) {
41 Logger::error("[KV_BATCH_UPDATE L" + std::to_string(layer_idx) + "] v_batch_for_layer size mismatch. Expected " +
42 std::to_string(num_tokens_in_batch * kv_dim) + ", got " + std::to_string(v_batch_for_layer.size()));
43 return;
44 }
45
46 size_t expected_total_elements_in_layer_cache = static_cast<size_t>(kv_cache->max_seq_len_config_) * static_cast<size_t>(kv_cache->max_batch_size) * kv_dim;
48 Logger::error("[KV_BATCH_UPDATE L" + std::to_string(layer_idx) +
49 "] Precondition failed: Layer cache not sized to max_seq_len_config. K size: " + std::to_string(layer_cache.k.size()) +
50 ", V size: " + std::to_string(layer_cache.v.size()) +
51 ", Expected size: " + std::to_string(expected_total_elements_in_layer_cache) +
52 ". Check KVCache::initialize.");
53 return;
54 }
56 size_t current_token_batch_offset = static_cast<size_t>(token_idx_in_batch) * kv_dim;
57
59
60 if (global_seq_pos >= kv_cache->max_seq_len_config_ * kv_cache->max_batch_size) {
61 Logger::error("[KV_BATCH_UPDATE L" + std::to_string(layer_idx) +
62 "] Error: global_seq_pos (" + std::to_string(global_seq_pos) +
63 ") is out of bounds for total cache size. Skipping update for this token.");
64 continue;
65 }
66
67 size_t destination_offset_in_layer_cache = static_cast<size_t>(global_seq_pos) * kv_dim;
68 size_t k_size_before = layer_cache.k.size();
69 std::string k_vals_to_log = " vals to copy: ";
70 for(int i = 0; i < std::min(3, kv_dim); ++i) { k_vals_to_log += std::to_string(k_batch_for_layer[current_token_batch_offset + i]) + " "; }
71 if (kv_dim > 3) k_vals_to_log += "...";
72
73
77
78
79 size_t v_size_before = layer_cache.v.size();
80 std::string v_vals_to_log = " vals to copy: ";
81 for(int i = 0; i < std::min(3, kv_dim); ++i) { v_vals_to_log += std::to_string(v_batch_for_layer[current_token_batch_offset + i]) + " "; }
82 if (kv_dim > 3) v_vals_to_log += "...";
83
87
88 }
89
90}
Key-Value cache for a single transformer layer.
Definition model.h:136

References Logger::error(), Logger::info(), and j.

Referenced by CPUBatchProcessor::forward_cpu_batch().

◆ update_kv_cache_batch_cpu_sequence_aware()

void update_kv_cache_batch_cpu_sequence_aware ( KVCache *  kv_cache,
int  layer_idx,
const std::vector< float > &  k_batch_for_layer,
const std::vector< float > &  v_batch_for_layer,
int  num_tokens_in_batch,
const std::vector< int > &  sequence_indices,
const std::vector< int > &  position_in_sequence,
int  num_kv_heads,
int  head_dim 
)

Definition at line 538 of file cpu_attention.cpp.

548 {
549 if (!kv_cache) {
550 Logger::error("update_kv_cache_batch_cpu_sequence_aware: KVCache is null.");
551 return;
552 }
553 if (layer_idx < 0 || static_cast<size_t>(layer_idx) >= kv_cache->layers.size()) {
554 Logger::error("update_kv_cache_batch_cpu_sequence_aware: layer_idx " + std::to_string(layer_idx) +
555 " is out of bounds for KVCache layers (size " + std::to_string(kv_cache->layers.size()) + ").");
556 return;
557 }
558
561
563 size_t current_token_batch_offset = static_cast<size_t>(token_idx) * kv_dim;
564
567
568 int sequence_base_offset = seq_idx * kv_cache->max_seq_len_config_;
570 if (actual_cache_position >= kv_cache->max_seq_len_config_ * kv_cache->max_batch_size) {
571 Logger::error("[KV_BATCH_UPDATE_SEQ_AWARE L" + std::to_string(layer_idx) +
572 "] Error: actual_cache_position (" + std::to_string(actual_cache_position) +
573 ") is out of bounds for total cache size. Skipping update for this token.");
574 continue;
575 }
576
577 size_t destination_offset_in_layer_cache = static_cast<size_t>(actual_cache_position) * kv_dim;
578
582
586 }
587}

References Logger::error(), and j.

Referenced by CPUBatchProcessor::forward_cpu_batch().