#include <cstdint>#include <functional>#include <nlohmann/json.hpp>#include <map>#include <string>#include <unordered_map>#include <vector>#include "safetensors_loader.h"#include <memory>#include "quantization.h"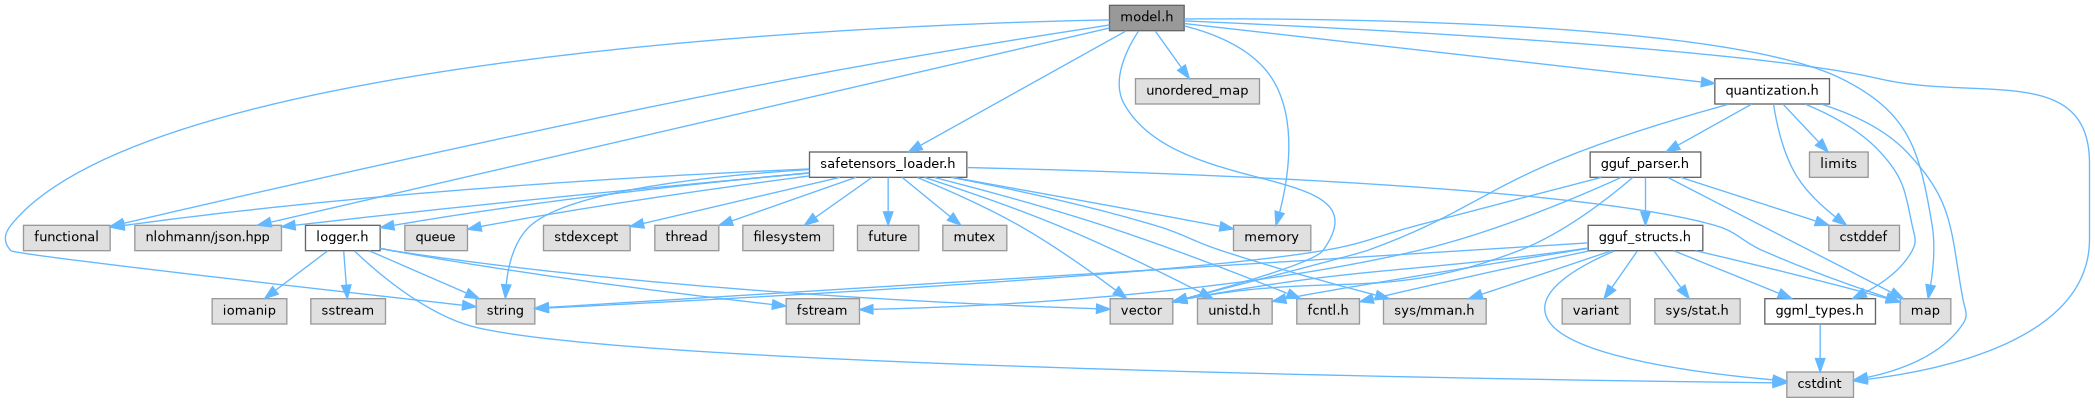
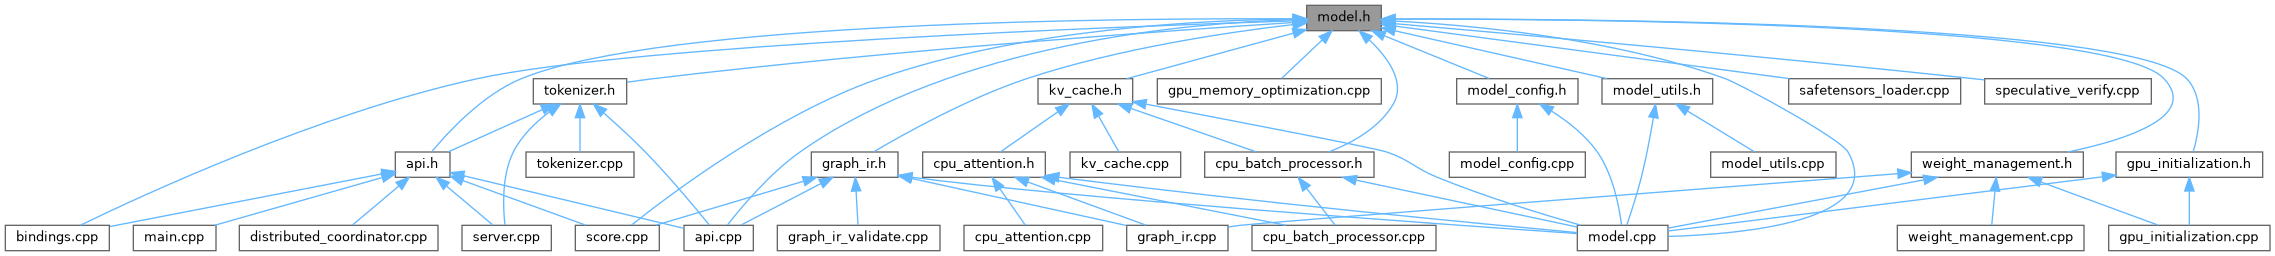
Go to the source code of this file.
Classes | |
| struct | ModelConfig |
| Model configuration structure holding architecture and hyperparameters. More... | |
| struct | KVCacheLayer |
| Key-Value cache for a single transformer layer. More... | |
| struct | KVCache |
| Complete Key-Value cache for all transformer layers. More... | |
| struct | LayerWeights |
| Structure holding all weights for a single transformer layer. More... | |
| class | TinyLlamaModel |
| Main transformer model class for TinyLlama. More... | |
Typedefs | |
| using | ForwardDiagCallback = std::function< void(int layer, const std::string &name, const std::vector< float > &v)> |
Enumerations | |
| enum class | TensorName { Q_PROJ , K_PROJ , V_PROJ , O_PROJ , GATE_PROJ , UP_PROJ , DOWN_PROJ , TOKEN_EMBD , LM_HEAD , UNKNOWN } |
| Enumeration of tensor names used in the TinyLlama model. More... | |
Functions | |
| static std::string | tensor_name_to_string (TensorName tn) |
| ModelConfig | parse_model_config_from_gguf (const GGUFData &gguf) |
| ModelConfig | parse_model_config (const nlohmann::json &json) |
| int | argmax (const std::vector< float > &v) |
| float | bfloat16_to_float32 (uint16_t b16) |
| void | rmsnorm (const std::vector< float > &x, const std::vector< uint16_t > &weight, float eps, std::vector< float > &out) |
| void | matvec_bf16_f32 (const std::vector< uint16_t > &mat, const std::vector< float > &vec, std::vector< float > &out, int M, int N) |
| void | softmax (std::vector< float > &x) |
| std::vector< uint16_t > | uint8_vector_to_uint16_vector (const std::vector< uint8_t > &bytes, size_t numel) |
| void | log_vector_summary (const std::string &name, const std::vector< float > &v, int head_count=5) |
| void | log_vector_summary_batch (const std::string &name, const std::vector< float > &batch_vector, int num_tokens_in_batch, int single_token_vector_size, int head_count=5) |
Typedef Documentation
◆ ForwardDiagCallback
Enumeration Type Documentation
◆ TensorName
|
strong |
Enumeration of tensor names used in the TinyLlama model.
This enum class defines the different types of tensors used in the transformer architecture, including attention projections, feed-forward layers, and embeddings.
Function Documentation
◆ argmax()
| int argmax | ( | const std::vector< float > & | v | ) |
Definition at line 186 of file utils.cpp.
References Logger::debug(), Logger::error(), j, and v.
◆ bfloat16_to_float32()
Definition at line 145 of file utils.cpp.
References bfloat16::EXPONENT_MASK, j, bfloat16::MANTISSA_MASK, bfloat16::NEG_ZERO, bfloat16::SHIFT_BITS, bfloat16::SIGN_BIT, and bfloat16::ZERO.
◆ log_vector_summary()
| void log_vector_summary | ( | const std::string & | name, |
| const std::vector< float > & | v, | ||
| int | head_count = 5 |
||
| ) |
Definition at line 208 of file utils.cpp.
References Logger::info(), j, name, SAFE_MIN, and v.
Referenced by TinyLlamaModel::forward().
◆ log_vector_summary_batch()
| void log_vector_summary_batch | ( | const std::string & | name, |
| const std::vector< float > & | batch_vector, | ||
| int | num_tokens_in_batch, | ||
| int | single_token_vector_size, | ||
| int | head_count = 5 |
||
| ) |
◆ matvec_bf16_f32()
| void matvec_bf16_f32 | ( | const std::vector< uint16_t > & | mat, |
| const std::vector< float > & | vec, | ||
| std::vector< float > & | out, | ||
| int | M, | ||
| int | N | ||
| ) |
◆ parse_model_config()
| ModelConfig parse_model_config | ( | const nlohmann::json & | json | ) |
Definition at line 20 of file model_config.cpp.
References ModelConfig::hidden_size, Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, ModelConfig::LLAMA_SENTENCEPIECE, ModelConfig::UNKNOWN, and Logger::warning().
◆ parse_model_config_from_gguf()
| ModelConfig parse_model_config_from_gguf | ( | const GGUFData & | gguf | ) |
Definition at line 75 of file model_config.cpp.
References Logger::info(), j, ModelConfig::LLAMA3_TIKTOKEN, ModelConfig::LLAMA_SENTENCEPIECE, type, ModelConfig::UNKNOWN, Logger::warning(), and ModelConfig::WORD_LEVEL.
Referenced by TinyLlamaModel::TinyLlamaModel(), and ember_ir::tuned_llama_match().
◆ rmsnorm()
| void rmsnorm | ( | const std::vector< float > & | x, |
| const std::vector< uint16_t > & | weight, | ||
| float | eps, | ||
| std::vector< float > & | out | ||
| ) |
◆ softmax()
| void softmax | ( | std::vector< float > & | x | ) |
◆ tensor_name_to_string()
|
static |
Definition at line 51 of file model.h.
References DOWN_PROJ, GATE_PROJ, j, K_PROJ, LM_HEAD, O_PROJ, Q_PROJ, TOKEN_EMBD, UP_PROJ, and V_PROJ.
◆ uint8_vector_to_uint16_vector()
| std::vector< uint16_t > uint8_vector_to_uint16_vector | ( | const std::vector< uint8_t > & | bytes, |
| size_t | numel | ||
| ) |
