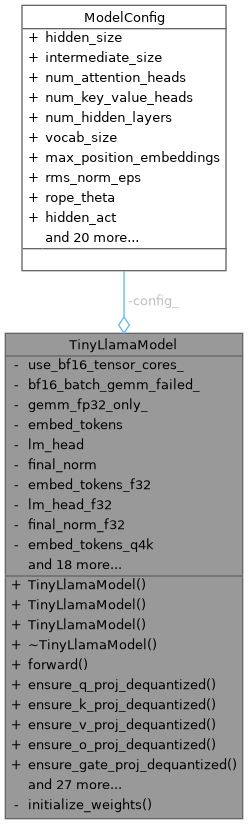
Main transformer model class for TinyLlama. More...
#include <model.h>
Private Member Functions | |
| void | initialize_weights (const SafeTensorsLoader *loader, const GGUFData *gguf) |
Friends | |
| class | CPUBatchProcessor |
| void | map_gguf_weights (const GGUFData &gguf, TinyLlamaModel &model) |
Detailed Description
Main transformer model class for TinyLlama.
Handles weight loading, forward pass, and GPU/CPU offloading logic. Supports both GGUF and SafeTensors formats.
Constructor & Destructor Documentation
◆ TinyLlamaModel() [1/3]
| TinyLlamaModel::TinyLlamaModel | ( | const ModelConfig & | config, |
| const SafeTensorsLoader & | loader | ||
| ) |
Construct a TinyLlamaModel from a SafeTensorsLoader.
- Parameters
-
config Model configuration. loader SafeTensorsLoader instance.
Definition at line 143 of file model.cpp.
References config_, Logger::info(), initialize_gpu_and_rope(), initialize_weights(), ModelConfig::is_gguf_file_loaded, and j.
◆ TinyLlamaModel() [2/3]
| TinyLlamaModel::TinyLlamaModel | ( | const ModelConfig & | initial_config, |
| const std::string & | model_path | ||
| ) |
Construct a TinyLlamaModel from a model path (GGUF or SafeTensors).
- Parameters
-
initial_config Initial model configuration (may be overridden by file metadata). model_path Path to the model file or directory.
Definition at line 153 of file model.cpp.
References ModelConfig::architecture, c, config_, Logger::error(), ember_ir::find_ir(), gguf_data_, ModelConfig::hidden_size, Logger::info(), initialize_gpu_and_rope(), initialize_weights(), ModelConfig::intermediate_size, ir_only_, ModelConfig::is_gguf_file_loaded, j, load_gguf_meta(), SafeTensorsLoader::load_model_config_from_json(), ModelConfig::max_position_embeddings, model_path_, ModelConfig::num_attention_heads, ModelConfig::num_cpu_offload_layers, ModelConfig::num_hidden_layers, ModelConfig::num_key_value_heads, parse_model_config_from_gguf(), ember_ir::tuned_llama_match(), ModelConfig::use_mmap_for_gguf, ModelConfig::vocab_size, Logger::warning(), and why.
◆ TinyLlamaModel() [3/3]
| TinyLlamaModel::TinyLlamaModel | ( | const ModelConfig & | config_from_session, |
| std::unique_ptr< GGUFData > | gguf_data_from_session | ||
| ) |
Construct a TinyLlamaModel from pre-loaded GGUFData.
- Parameters
-
config_from_session Model configuration. gguf_data_from_session Unique pointer to GGUFData.
Definition at line 357 of file model.cpp.
References config_, gguf_data_, Logger::info(), initialize_gpu_and_rope(), initialize_weights(), ModelConfig::is_gguf_file_loaded, j, model_path_, ModelConfig::num_cpu_offload_layers, ModelConfig::num_hidden_layers, and Logger::warning().
◆ ~TinyLlamaModel()
| TinyLlamaModel::~TinyLlamaModel | ( | ) |
Destructor. Cleans up all allocated resources.
Definition at line 386 of file model.cpp.
References config_, Logger::error(), Logger::info(), j, layers, ModelConfig::num_cpu_offload_layers, ModelConfig::num_hidden_layers, and p.
Member Function Documentation
◆ clear_layer_dequantized_weights()
Definition at line 115 of file weight_management.cpp.
References EMBER_RECOVERABLE, Logger::info(), j, layers, and Logger::warning().
Referenced by forward().
◆ dequantize_all_if_small()
Definition at line 32 of file weight_management.cpp.
References config_, dequantize_vector_q8_0_to_f32(), embed_tokens_f32, embed_tokens_q4k, embed_tokens_q5k, embed_tokens_q6k, embed_tokens_q8_0, embed_tokens_q8k, ensure_down_proj_dequantized(), ensure_embed_tokens_dequantized(), ensure_gate_proj_dequantized(), ensure_k_proj_dequantized(), ensure_lm_head_dequantized(), ensure_o_proj_dequantized(), ensure_q_proj_dequantized(), ensure_up_proj_dequantized(), ensure_v_proj_dequantized(), GGML_QK8_0, ModelConfig::hidden_size, ModelConfig::intermediate_size, j, layers, lm_head_f32, lm_head_q4k, lm_head_q5k, lm_head_q6k, lm_head_q8_0, lm_head_q8k, n, ModelConfig::num_attention_heads, ModelConfig::num_hidden_layers, ModelConfig::num_key_value_heads, and ModelConfig::vocab_size.
◆ ensure_bf16_concatenated_weights_loaded()
| void TinyLlamaModel::ensure_bf16_concatenated_weights_loaded | ( | ) |
◆ ensure_down_proj_dequantized()
Definition at line 232 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, ModelConfig::intermediate_size, j, and layers.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ ensure_embed_tokens_dequantized()
| void TinyLlamaModel::ensure_embed_tokens_dequantized | ( | ) |
Definition at line 13 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), embed_tokens, embed_tokens_f32, embed_tokens_q4k, embed_tokens_q5k, embed_tokens_q6k, embed_tokens_q8_0, embed_tokens_q8k, ModelConfig::hidden_size, j, and ModelConfig::vocab_size.
Referenced by dequantize_all_if_small(), initialize_gpu_and_rope(), and initialize_weights().
◆ ensure_f32_concatenated_weights_loaded()
| void TinyLlamaModel::ensure_f32_concatenated_weights_loaded | ( | ) |
◆ ensure_gate_proj_dequantized()
Definition at line 198 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, ModelConfig::intermediate_size, j, and layers.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ ensure_k_proj_dequantized()
Definition at line 150 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, j, layers, ModelConfig::num_attention_heads, and ModelConfig::num_key_value_heads.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ ensure_layer_weights_on_gpu()
◆ ensure_lm_head_dequantized()
| void TinyLlamaModel::ensure_lm_head_dequantized | ( | ) |
Definition at line 77 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, j, lm_head, lm_head_f32, lm_head_q4k, lm_head_q5k, lm_head_q6k, lm_head_q8_0, lm_head_q8k, and ModelConfig::vocab_size.
Referenced by dequantize_all_if_small(), forward(), forward_cpu_logits_batch(), and initialize_gpu_and_rope().
◆ ensure_o_proj_dequantized()
Definition at line 182 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, j, and layers.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ ensure_q_proj_dequantized()
Definition at line 96 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, Logger::info(), j, and layers.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ ensure_up_proj_dequantized()
Definition at line 215 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, ModelConfig::intermediate_size, j, and layers.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ ensure_v_proj_dequantized()
Definition at line 166 of file weight_management.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q8_k(), dequantize_vector_q4k_to_f32(), dequantize_vector_q5k_to_f32(), dequantize_vector_q6k_to_f32(), dequantize_vector_q8_0_to_f32(), ModelConfig::hidden_size, j, layers, ModelConfig::num_attention_heads, and ModelConfig::num_key_value_heads.
Referenced by dequantize_all_if_small(), forward(), CPUBatchProcessor::forward_cpu_batch(), and forward_cpu_batch_generation().
◆ forward()
| std::vector< float > TinyLlamaModel::forward | ( | std::vector< float > & | input, |
| int | n_tokens, | ||
| KVCache * | kv_cache, | ||
| const std::vector< int > * | attention_mask | ||
| ) |
Run the forward pass for the model on CPU layers.
- Parameters
-
input Input vector (modified in-place). n_tokens Current token position. kv_cache Pointer to the key-value cache. attention_mask Optional attention mask.
- Returns
- Output logits or intermediate activations.
Definition at line 595 of file model.cpp.
References apply_rope_vector(), bf16vec_to_float_vec(), clear_layer_dequantized_weights(), config_, ModelConfig::enable_memory_efficient_layers, ensure_down_proj_dequantized(), ensure_gate_proj_dequantized(), ensure_k_proj_dequantized(), ensure_lm_head_dequantized(), ensure_o_proj_dequantized(), ensure_q_proj_dequantized(), ensure_up_proj_dequantized(), ensure_v_proj_dequantized(), Logger::error(), final_norm, final_norm_f32, gelu_new_cpu(), ModelConfig::hidden_act, ModelConfig::hidden_size, Logger::info(), ModelConfig::intermediate_size, ModelConfig::is_gguf_file_loaded, j, layers, lm_head, lm_head_f32, lm_head_q4k, lm_head_q6k, lm_head_q8_0, lm_head_q8k, log_vector_summary(), matvec_bf16_f32_vector_cpu(), matvec_f32_f32_vector_cpu(), matvec_q4k_f32_vector_cpu(), matvec_q6k_f32_vector_cpu(), matvec_q8_0_f32_vector_cpu(), matvec_q8k_f32_vector_cpu(), ModelConfig::max_position_embeddings, moe_ffn_f32_cpu(), ModelConfig::num_attention_heads, ModelConfig::num_cpu_offload_layers, ModelConfig::num_experts, ModelConfig::num_experts_used, ModelConfig::num_hidden_layers, ModelConfig::num_key_value_heads, precomputed_freqs_cis_, ModelConfig::rms_norm_eps, rmsnorm_vector_cpu(), silu_cpu(), softmax_vector_cpu(), v, and ModelConfig::vocab_size.
◆ forward_cpu_batch()
| std::vector< float > TinyLlamaModel::forward_cpu_batch | ( | const std::vector< float > & | batch_input_activations, |
| int | num_tokens_in_batch, | ||
| int | num_cpu_layers_to_process, | ||
| int | start_pos_in_sequence, | ||
| KVCache * | kv_cache, | ||
| const std::vector< int > & | prompt_lengths = {} |
||
| ) |
Definition at line 2498 of file model.cpp.
References cpu_batch_processor_, and j.
◆ forward_cpu_batch_generation()
| std::vector< std::vector< float > > TinyLlamaModel::forward_cpu_batch_generation | ( | const std::vector< float > & | batch_input_activations, |
| const std::vector< int > & | token_positions, | ||
| const std::vector< int > & | original_sequence_indices, | ||
| int | num_tokens_in_batch, | ||
| KVCache * | kv_cache | ||
| ) |
Definition at line 1395 of file model.cpp.
References apply_rope_vector(), bf16vec_to_float_vec(), config_, ensure_down_proj_dequantized(), ensure_gate_proj_dequantized(), ensure_k_proj_dequantized(), ensure_o_proj_dequantized(), ensure_q_proj_dequantized(), ensure_up_proj_dequantized(), ensure_v_proj_dequantized(), Logger::error(), forward_cpu_logits_batch(), ModelConfig::hidden_size, Logger::info(), ModelConfig::intermediate_size, ModelConfig::is_gguf_file_loaded, j, layers, matmul_f32_f32_batch_cpu(), matmul_q4k_f32_batch_cpu(), matmul_q6k_f32_batch_cpu(), matmul_q8_0_f32_batch_cpu(), ModelConfig::max_position_embeddings, ModelConfig::num_attention_heads, ModelConfig::num_cpu_offload_layers, ModelConfig::num_key_value_heads, pos, precomputed_freqs_cis_, ModelConfig::rms_norm_eps, rmsnorm_batch_cpu(), SAFE_SQRT, simd_dot_product(), simd_scaled_add(), softmax_vector_cpu(), and ModelConfig::vocab_size.
◆ forward_cpu_logits_batch()
| std::vector< float > TinyLlamaModel::forward_cpu_logits_batch | ( | const std::vector< float > & | final_batch_activations, |
| int | num_tokens_in_batch | ||
| ) |
Definition at line 1329 of file model.cpp.
References bf16vec_to_float_vec(), config_, ensure_lm_head_dequantized(), Logger::error(), final_norm, final_norm_f32, ModelConfig::hidden_size, Logger::info(), ModelConfig::is_gguf_file_loaded, j, lm_head, lm_head_f32, lm_head_q4k, lm_head_q6k, lm_head_q8_0, matmul_f32_f32_batch_cpu(), matmul_q4k_f32_batch_cpu(), matmul_q6k_f32_batch_cpu(), matmul_q8_0_f32_batch_cpu(), ModelConfig::rms_norm_eps, rmsnorm_batch_cpu(), and ModelConfig::vocab_size.
Referenced by forward_cpu_batch_generation().
◆ free_bf16_concatenated_weights()
| void TinyLlamaModel::free_bf16_concatenated_weights | ( | ) |
Definition at line 1246 of file weight_management.cpp.
References Logger::info().
◆ free_layer_gpu_weights()
◆ gemm_fp32_only()
|
inline |
◆ get_config()
|
inline |
◆ get_embed_tokens()
◆ get_gguf_data()
Definition at line 539 of file model.h.
References gguf_data_.
◆ get_gguf_data_ptr()
|
inline |
◆ get_layers()
|
inline |
◆ get_lm_head()
◆ get_vocab_size()
| int TinyLlamaModel::get_vocab_size | ( | ) | const |
Get the vocabulary size for the model.
- Returns
- Vocabulary size.
Definition at line 256 of file model_utils.cpp.
References config_, and ModelConfig::vocab_size.
◆ initialize_gpu_and_rope()
| void TinyLlamaModel::initialize_gpu_and_rope | ( | ) |
Definition at line 17 of file gpu_initialization.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q4_k_m(), dequantize_q6_k(), dequantize_q8_0_block(), ember::deterministic(), ember::deterministic_cublas_env(), embed_tokens, embed_tokens_f32, embed_tokens_q4k, embed_tokens_q6k, embed_tokens_q8_0, ensure_embed_tokens_dequantized(), ensure_lm_head_dequantized(), Logger::error(), final_norm, final_norm_f32, float32_to_bfloat16(), GGML_QK8_0, GGML_QK_K, ModelConfig::hidden_size, Logger::info(), ModelConfig::intermediate_size, j, layers, lm_head, lm_head_f32, lm_head_q4k, lm_head_q6k, lm_head_q8_0, ModelConfig::max_position_embeddings, ModelConfig::num_attention_heads, ModelConfig::num_cpu_offload_layers, ModelConfig::num_hidden_layers, ModelConfig::num_key_value_heads, p, pos, precomputed_freqs_cis_, Logger::ptrToString(), ModelConfig::rope_theta, use_bf16_tensor_cores_, ModelConfig::vocab_size, Logger::warning(), and bfloat16::ZERO.
Referenced by TinyLlamaModel(), TinyLlamaModel(), and TinyLlamaModel().
◆ initialize_rope_freqs()
| void TinyLlamaModel::initialize_rope_freqs | ( | ) |
Definition at line 196 of file model_utils.cpp.
References config_, Logger::error(), ModelConfig::hidden_size, Logger::info(), j, ModelConfig::max_position_embeddings, rope::MAX_SEQUENCE_LENGTH, ModelConfig::num_attention_heads, pos, precomputed_freqs_cis_, ModelConfig::rope_theta, rope::ROPE_THETA, and Logger::warning().
◆ initialize_weights()
|
private |
Definition at line 39 of file model.cpp.
References bf16vec_to_float_vec(), config_, embed_tokens_f32, ensure_embed_tokens_dequantized(), Logger::error(), Logger::fatal(), final_norm, final_norm_f32, gguf_data_, ModelConfig::hidden_size, Logger::info(), ModelConfig::intermediate_size, j, layers, lm_head_f32, map_gguf_weights, ModelConfig::num_hidden_layers, and ModelConfig::vocab_size.
Referenced by TinyLlamaModel(), TinyLlamaModel(), and TinyLlamaModel().
◆ ir_only()
|
inline |
◆ lookup_embedding()
Lookup the embedding vector for a given token ID.
- Parameters
-
token_id The token ID to lookup.
- Returns
- The embedding vector as a std::vector<float>.
Definition at line 11 of file model_utils.cpp.
References bf16vec_to_float_vec(), config_, dequantize_q4_k_m(), dequantize_q5_k(), dequantize_q6_k(), dequantize_q8_0_block(), embed_tokens, embed_tokens_f32, embed_tokens_q4k, embed_tokens_q5k, embed_tokens_q6k, embed_tokens_q8_0, Logger::error(), GGML_QK8_0, GGML_QK_K, ModelConfig::hidden_size, Logger::info(), j, SAFE_MIN, and ModelConfig::vocab_size.
◆ set_gemm_fp32_only()
Definition at line 385 of file model.h.
References gemm_fp32_only_, and j.
Referenced by tinyllama::TinyLlamaSession::score_rows().
Friends And Related Symbol Documentation
◆ CPUBatchProcessor
|
friend |
◆ map_gguf_weights
|
friend |
Definition at line 879 of file weight_management.cpp.
Referenced by initialize_weights().
Member Data Documentation
◆ bf16_batch_gemm_failed_
◆ config_
|
private |
Definition at line 573 of file model.h.
Referenced by dequantize_all_if_small(), ensure_down_proj_dequantized(), ensure_embed_tokens_dequantized(), ensure_gate_proj_dequantized(), ensure_k_proj_dequantized(), ensure_lm_head_dequantized(), ensure_o_proj_dequantized(), ensure_q_proj_dequantized(), ensure_up_proj_dequantized(), ensure_v_proj_dequantized(), forward(), CPUBatchProcessor::forward_cpu_batch(), forward_cpu_batch_generation(), forward_cpu_logits_batch(), get_config(), get_vocab_size(), initialize_gpu_and_rope(), initialize_rope_freqs(), initialize_weights(), lookup_embedding(), TinyLlamaModel(), TinyLlamaModel(), TinyLlamaModel(), and ~TinyLlamaModel().
◆ cpu_batch_processor_
|
private |
Definition at line 701 of file model.h.
Referenced by forward_cpu_batch().
◆ embed_tokens
|
private |
Definition at line 578 of file model.h.
Referenced by ensure_embed_tokens_dequantized(), get_embed_tokens(), initialize_gpu_and_rope(), and lookup_embedding().
◆ embed_tokens_f32
|
private |
Definition at line 581 of file model.h.
Referenced by dequantize_all_if_small(), ensure_embed_tokens_dequantized(), initialize_gpu_and_rope(), initialize_weights(), and lookup_embedding().
◆ embed_tokens_q4k
|
private |
Definition at line 582 of file model.h.
Referenced by dequantize_all_if_small(), ensure_embed_tokens_dequantized(), initialize_gpu_and_rope(), and lookup_embedding().
◆ embed_tokens_q5k
|
private |
Definition at line 583 of file model.h.
Referenced by dequantize_all_if_small(), ensure_embed_tokens_dequantized(), and lookup_embedding().
◆ embed_tokens_q6k
|
private |
Definition at line 584 of file model.h.
Referenced by dequantize_all_if_small(), ensure_embed_tokens_dequantized(), initialize_gpu_and_rope(), and lookup_embedding().
◆ embed_tokens_q8_0
|
private |
Definition at line 585 of file model.h.
Referenced by dequantize_all_if_small(), ensure_embed_tokens_dequantized(), initialize_gpu_and_rope(), and lookup_embedding().
◆ embed_tokens_q8k
|
private |
Definition at line 586 of file model.h.
Referenced by dequantize_all_if_small(), and ensure_embed_tokens_dequantized().
◆ f32_concatenated_weights_loaded_
◆ final_norm
|
private |
Definition at line 580 of file model.h.
Referenced by forward(), forward_cpu_logits_batch(), initialize_gpu_and_rope(), and initialize_weights().
◆ final_norm_f32
|
private |
Definition at line 581 of file model.h.
Referenced by forward(), forward_cpu_logits_batch(), initialize_gpu_and_rope(), and initialize_weights().
◆ final_norm_q4k
|
private |
◆ final_norm_q6k
|
private |
◆ gemm_fp32_only_
Definition at line 576 of file model.h.
Referenced by gemm_fp32_only(), and set_gemm_fp32_only().
◆ gguf_data_
|
private |
Definition at line 696 of file model.h.
Referenced by get_gguf_data(), get_gguf_data_ptr(), initialize_weights(), TinyLlamaModel(), and TinyLlamaModel().
◆ ir_only_
Definition at line 697 of file model.h.
Referenced by ir_only(), and TinyLlamaModel().
◆ layers
|
private |
Definition at line 587 of file model.h.
Referenced by clear_layer_dequantized_weights(), dequantize_all_if_small(), ensure_down_proj_dequantized(), ensure_gate_proj_dequantized(), ensure_k_proj_dequantized(), ensure_o_proj_dequantized(), ensure_q_proj_dequantized(), ensure_up_proj_dequantized(), ensure_v_proj_dequantized(), forward(), CPUBatchProcessor::forward_cpu_batch(), forward_cpu_batch_generation(), get_layers(), initialize_gpu_and_rope(), initialize_weights(), and ~TinyLlamaModel().
◆ lm_head
|
private |
Definition at line 579 of file model.h.
Referenced by ensure_lm_head_dequantized(), forward(), forward_cpu_logits_batch(), get_lm_head(), and initialize_gpu_and_rope().
◆ lm_head_f32
|
private |
Definition at line 581 of file model.h.
Referenced by dequantize_all_if_small(), ensure_lm_head_dequantized(), forward(), forward_cpu_logits_batch(), initialize_gpu_and_rope(), and initialize_weights().
◆ lm_head_q4k
|
private |
Definition at line 582 of file model.h.
Referenced by dequantize_all_if_small(), ensure_lm_head_dequantized(), forward(), forward_cpu_logits_batch(), and initialize_gpu_and_rope().
◆ lm_head_q5k
|
private |
Definition at line 583 of file model.h.
Referenced by dequantize_all_if_small(), and ensure_lm_head_dequantized().
◆ lm_head_q6k
|
private |
Definition at line 584 of file model.h.
Referenced by dequantize_all_if_small(), ensure_lm_head_dequantized(), forward(), forward_cpu_logits_batch(), and initialize_gpu_and_rope().
◆ lm_head_q8_0
|
private |
Definition at line 585 of file model.h.
Referenced by dequantize_all_if_small(), ensure_lm_head_dequantized(), forward(), forward_cpu_logits_batch(), and initialize_gpu_and_rope().
◆ lm_head_q8k
|
private |
Definition at line 586 of file model.h.
Referenced by dequantize_all_if_small(), ensure_lm_head_dequantized(), and forward().
◆ model_path_
|
private |
Definition at line 698 of file model.h.
Referenced by TinyLlamaModel(), and TinyLlamaModel().
◆ precomputed_freqs_cis_
Definition at line 694 of file model.h.
Referenced by forward(), CPUBatchProcessor::forward_cpu_batch(), forward_cpu_batch_generation(), initialize_gpu_and_rope(), and initialize_rope_freqs().
◆ use_bf16_tensor_cores_
Definition at line 574 of file model.h.
Referenced by initialize_gpu_and_rope().
The documentation for this class was generated from the following files:
