Weight quantization structures and functions for model compression. More...
#include <cstddef>#include <cstdint>#include <limits>#include <vector>#include "ggml_types.h"#include "gguf_parser.h"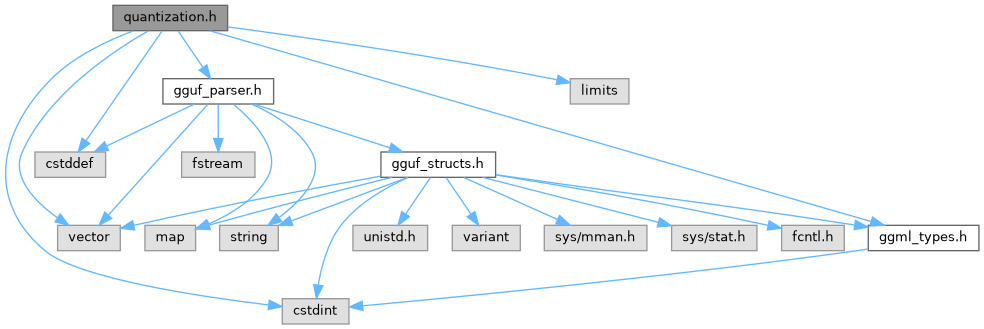
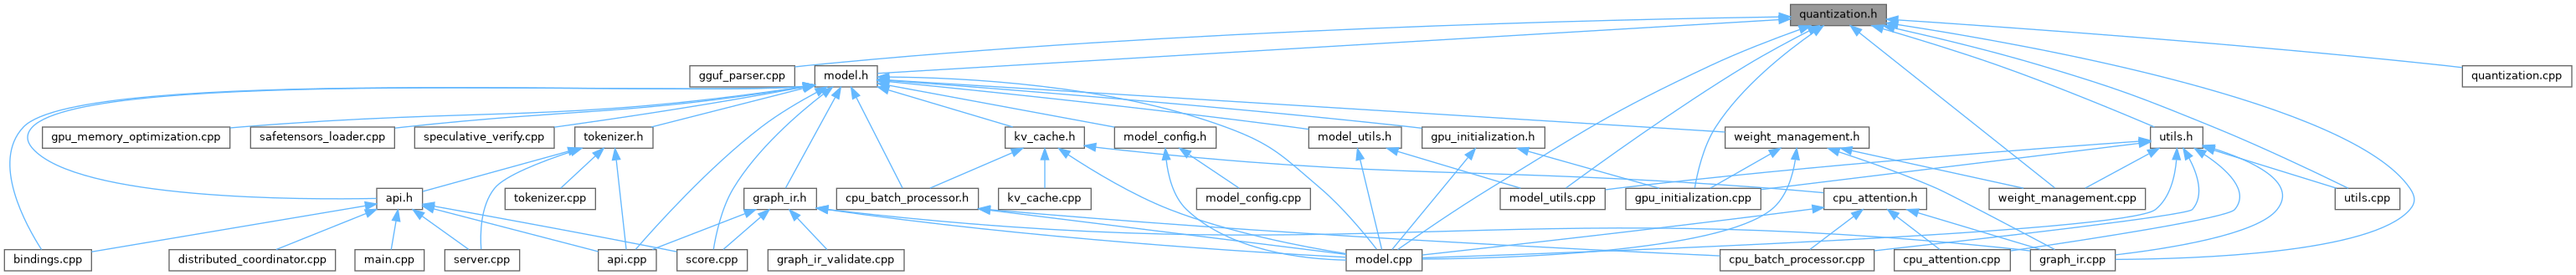
Go to the source code of this file.
Classes | |
| struct | block_q4_K |
| 4-bit K-quantized block structure More... | |
| struct | block_q5_K |
| 5-bit K-quantized block structure (ggml's block_q5_K) More... | |
| struct | block_q6_K |
| 6-bit K-quantized block structure More... | |
| struct | block_q2_K |
| 2-bit K-quantized block structure More... | |
| struct | block_q3_K |
| 3-bit K-quantized block structure More... | |
| struct | block_q8_K |
| 8-bit K-quantized block structure with block sums More... | |
| struct | block_q8_0 |
| Simple 8-bit quantized block structure. More... | |
Macros | |
| #define | RESTRICT __restrict__ |
Detailed Description
Weight quantization structures and functions for model compression.
This file contains the definitions for various quantization formats and functions to convert between them. The quantization methods include Q2_K, Q3_K, Q4_K, Q6_K, and Q8_0 formats, each offering different compression ratios and precision tradeoffs.
Definition in file quantization.h.
Macro Definition Documentation
◆ RESTRICT
| #define RESTRICT __restrict__ |
Definition at line 15 of file quantization.h.
Function Documentation
◆ dequantize_q2_k()
| void dequantize_q2_k | ( | const void * | q_data, |
| float * | f_data, | ||
| int | num_weights_in_block, | ||
| bool | log_details_for_this_block = false |
||
| ) |
Dequantizes a Q2_K quantized block to float32.
- Parameters
-
q_data Pointer to quantized data f_data Output float array num_weights_in_block Number of weights to dequantize log_details_for_this_block Whether to log dequantization details
◆ dequantize_q3_k()
Dequantizes a Q3_K quantized block to float32.
- Parameters
-
q_data Pointer to quantized data f_data Output float array num_weights_in_block Number of weights to dequantize
Definition at line 509 of file quantization.cpp.
References fp16_to_fp32(), GGML_QK_K, j, and K_SCALE_VALUES.
◆ dequantize_q4_k_m()
| void dequantize_q4_k_m | ( | const block_q4_K * | qblock, |
| float *RESTRICT | output_f32, | ||
| int | num_elements, | ||
| bool | log_this_block = false |
||
| ) |
Dequantizes a Q4_K quantized block to float32.
- Parameters
-
qblock Pointer to Q4_K block output_f32 Output float array num_elements Number of elements to dequantize log_this_block Whether to log dequantization details
◆ dequantize_q5_k()
| void dequantize_q5_k | ( | const block_q5_K * | qblock, |
| float *RESTRICT | output_f32 | ||
| ) |
Dequantizes a Q5_K block (256 weights) to float32, as ggml's dequantize_row_q5_K.
- Parameters
-
qblock Pointer to Q5_K block output_f32 Output float array (GGML_QK_K values)
◆ dequantize_q6_k()
| void dequantize_q6_k | ( | const block_q6_K * | qblock, |
| float *RESTRICT | output_f32, | ||
| int | num_elements, | ||
| bool | log_this_block = false |
||
| ) |
Dequantizes a Q6_K quantized block to float32.
- Parameters
-
qblock Pointer to Q6_K block output_f32 Output float array num_elements Number of elements to dequantize log_this_block Whether to log dequantization details
◆ dequantize_q8_0_block()
| void dequantize_q8_0_block | ( | const block_q8_0 * | qblock, |
| float * | output | ||
| ) |
Dequantizes a Q8_0 block to float32.
- Parameters
-
qblock Pointer to Q8_0 block output Output float array
Definition at line 1092 of file quantization.cpp.
References fp16_to_fp32(), GGML_QK8_0, and j.
Referenced by dequant_span_to_f32(), dequantize_vector_q8_0_to_f32(), TinyLlamaModel::initialize_gpu_and_rope(), TinyLlamaModel::lookup_embedding(), and matvec_q8_0_f32_vector_cpu().
◆ dequantize_vector_q4k_to_f32()
| void dequantize_vector_q4k_to_f32 | ( | const std::vector< block_q4_K > & | q_weights, |
| std::vector< float > & | f32_weights, | ||
| size_t | total_num_elements, | ||
| int | log_first_n_blocks = 0 |
||
| ) |
Dequantizes a vector of Q4_K blocks to a vector of float32.
- Parameters
-
q_weights Input vector of Q4_K blocks f32_weights Output vector of float32 values (will be resized) total_num_elements Total number of float elements expected after dequantization log_first_n_blocks Number of initial blocks to log dequantization details for (0 for no logging)
Definition at line 1154 of file quantization.cpp.
References dequantize_q4_k_m(), Logger::error(), GGML_QK_K, j, and Logger::warning().
Referenced by TinyLlamaModel::ensure_down_proj_dequantized(), TinyLlamaModel::ensure_embed_tokens_dequantized(), TinyLlamaModel::ensure_gate_proj_dequantized(), TinyLlamaModel::ensure_k_proj_dequantized(), TinyLlamaModel::ensure_lm_head_dequantized(), TinyLlamaModel::ensure_o_proj_dequantized(), TinyLlamaModel::ensure_q_proj_dequantized(), TinyLlamaModel::ensure_up_proj_dequantized(), and TinyLlamaModel::ensure_v_proj_dequantized().
◆ dequantize_vector_q5k_to_f32()
| void dequantize_vector_q5k_to_f32 | ( | const std::vector< block_q5_K > & | q_weights, |
| std::vector< float > & | f32_weights, | ||
| size_t | total_num_elements | ||
| ) |
Dequantizes a vector of Q5_K blocks to float32 (total_num_elements a multiple of GGML_QK_K)
Definition at line 247 of file quantization.cpp.
References dequantize_q5_k(), GGML_QK_K, and j.
Referenced by TinyLlamaModel::ensure_down_proj_dequantized(), TinyLlamaModel::ensure_embed_tokens_dequantized(), TinyLlamaModel::ensure_gate_proj_dequantized(), TinyLlamaModel::ensure_k_proj_dequantized(), TinyLlamaModel::ensure_lm_head_dequantized(), TinyLlamaModel::ensure_o_proj_dequantized(), TinyLlamaModel::ensure_q_proj_dequantized(), TinyLlamaModel::ensure_up_proj_dequantized(), and TinyLlamaModel::ensure_v_proj_dequantized().
◆ dequantize_vector_q6k_to_f32()
| void dequantize_vector_q6k_to_f32 | ( | const std::vector< block_q6_K > & | q_weights, |
| std::vector< float > & | f32_weights, | ||
| size_t | total_num_elements, | ||
| int | log_first_n_blocks = 0 |
||
| ) |
Dequantizes a vector of Q6_K blocks to a vector of float32.
- Parameters
-
q_weights Input vector of Q6_K blocks f32_weights Output vector of float32 values (will be resized) total_num_elements Total number of float elements expected after dequantization log_first_n_blocks Number of initial blocks to log dequantization details for (0 for no logging)
Definition at line 1099 of file quantization.cpp.
References dequantize_q6_k(), Logger::error(), GGML_QK_K, j, and Logger::warning().
Referenced by TinyLlamaModel::ensure_down_proj_dequantized(), TinyLlamaModel::ensure_embed_tokens_dequantized(), TinyLlamaModel::ensure_gate_proj_dequantized(), TinyLlamaModel::ensure_k_proj_dequantized(), TinyLlamaModel::ensure_lm_head_dequantized(), TinyLlamaModel::ensure_o_proj_dequantized(), TinyLlamaModel::ensure_q_proj_dequantized(), TinyLlamaModel::ensure_up_proj_dequantized(), and TinyLlamaModel::ensure_v_proj_dequantized().
◆ dequantize_vector_q8_0_to_f32()
| void dequantize_vector_q8_0_to_f32 | ( | const std::vector< block_q8_0 > & | q_weights, |
| std::vector< float > & | f32_weights, | ||
| size_t | total_num_elements, | ||
| int | log_first_n_blocks = 0 |
||
| ) |
Dequantizes a vector of Q8_0 blocks to a vector of float32.
- Parameters
-
q_weights Input vector of Q8_0 blocks f32_weights Output vector of float32 values (will be resized) total_num_elements Total number of float elements expected after dequantization log_first_n_blocks Number of initial blocks to log dequantization details for (0 for no logging)
Definition at line 1210 of file quantization.cpp.
References dequantize_q8_0_block(), Logger::error(), GGML_QK8_0, j, and Logger::warning().
Referenced by ember_ir::Interpreter::bind_tensor(), TinyLlamaModel::dequantize_all_if_small(), TinyLlamaModel::ensure_down_proj_dequantized(), TinyLlamaModel::ensure_embed_tokens_dequantized(), TinyLlamaModel::ensure_gate_proj_dequantized(), TinyLlamaModel::ensure_k_proj_dequantized(), TinyLlamaModel::ensure_lm_head_dequantized(), TinyLlamaModel::ensure_o_proj_dequantized(), TinyLlamaModel::ensure_q_proj_dequantized(), TinyLlamaModel::ensure_up_proj_dequantized(), and TinyLlamaModel::ensure_v_proj_dequantized().
◆ fp16_to_fp32()
Converts a 16-bit floating point number to 32-bit float.
- Parameters
-
h The 16-bit float value to convert is_gguf_scale_field Whether this value is from a GGUF scale field
- Returns
- The converted 32-bit float value
Definition at line 47 of file quantization.cpp.
References j.
Referenced by dequant_span_to_f32(), dequantize_q2_k(), dequantize_q3_k(), dequantize_q4_k_m(), dequantize_q5_k(), dequantize_q6_k(), dequantize_q8_0_block(), dequantize_q8_k(), vec_dot_q4_k_q8_k_cpu(), and vec_dot_q6_k_q8_k_cpu().
◆ fp32_to_fp16()
Converts a 32-bit float to 16-bit floating point.
- Parameters
-
f The 32-bit float value to convert
- Returns
- The converted 16-bit float value
Definition at line 92 of file quantization.cpp.
References j.
Referenced by quantize_fp32_to_q8_K(), quantize_q4_k_m(), and quantize_q6_k().
◆ ggml_type_block_size()
Gets the block size for a GGML type.
- Parameters
-
type The GGML type
- Returns
- Block size in elements
Definition at line 727 of file quantization.cpp.
References GGML_QK_K, GGML_TYPE_BF16, GGML_TYPE_F16, GGML_TYPE_F32, GGML_TYPE_I16, GGML_TYPE_I32, GGML_TYPE_I8, GGML_TYPE_Q2_K, GGML_TYPE_Q3_K, GGML_TYPE_Q4_0, GGML_TYPE_Q4_1, GGML_TYPE_Q4_K, GGML_TYPE_Q5_0, GGML_TYPE_Q5_1, GGML_TYPE_Q5_K, GGML_TYPE_Q6_K, GGML_TYPE_Q8_0, and type.
Referenced by load_gguf_meta().
◆ ggml_type_name()
Gets the string name of a GGML type.
- Parameters
-
type The GGML type
- Returns
- String representation of the type
Definition at line 634 of file quantization.cpp.
References GGML_TYPE_BF16, GGML_TYPE_COUNT, GGML_TYPE_F16, GGML_TYPE_F32, GGML_TYPE_I16, GGML_TYPE_I32, GGML_TYPE_I8, GGML_TYPE_Q2_K, GGML_TYPE_Q3_K, GGML_TYPE_Q4_0, GGML_TYPE_Q4_1, GGML_TYPE_Q4_K, GGML_TYPE_Q5_0, GGML_TYPE_Q5_1, GGML_TYPE_Q5_K, GGML_TYPE_Q6_K, GGML_TYPE_Q8_0, GGML_TYPE_Q8_1, GGML_TYPE_Q8_K, and type.
Referenced by ember_ir::Interpreter::bind_tensor(), dequant_legacy_to_f32(), and load_gguf_meta().
◆ ggml_type_size()
Gets the size in bytes of a GGML type.
- Parameters
-
type The GGML type
- Returns
- Size in bytes
Definition at line 679 of file quantization.cpp.
References GGML_TYPE_BF16, GGML_TYPE_COUNT, GGML_TYPE_F16, GGML_TYPE_F32, GGML_TYPE_I16, GGML_TYPE_I32, GGML_TYPE_I8, GGML_TYPE_Q2_K, GGML_TYPE_Q3_K, GGML_TYPE_Q4_0, GGML_TYPE_Q4_1, GGML_TYPE_Q4_K, GGML_TYPE_Q5_0, GGML_TYPE_Q5_1, GGML_TYPE_Q5_K, GGML_TYPE_Q6_K, GGML_TYPE_Q8_0, GGML_TYPE_Q8_1, GGML_TYPE_Q8_K, j, and type.
Referenced by ember_ir::Interpreter::bind_tensor(), dequant_legacy_to_f32(), dequant_span_to_f32(), and load_gguf_meta().
◆ handle_i8_tensor()
Handles conversion of int8 tensor data to float32.
- Parameters
-
i8_data Input int8 data f_data Output float array num_elements Number of elements to convert
Definition at line 301 of file quantization.cpp.
References j.
◆ matvec_q4k_q8k_cpu()
| void matvec_q4k_q8k_cpu | ( | const std::vector< block_q4_K > & | mat_q4k, |
| const std::vector< block_q8_K > & | vec_q8k, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols, | ||
| bool | log_calls | ||
| ) |
Computes matrix-vector product between Q4_K matrix and Q8_K vector on CPU.
- Parameters
-
mat_q4k Q4_K matrix vec_q8k Q8_K vector out_f32 Output float vector rows Number of matrix rows cols Number of matrix columns log_calls Whether to log computation details
Definition at line 1025 of file quantization.cpp.
References GGML_QK_K, j, and vec_dot_q4_k_q8_k_cpu().
◆ matvec_q6k_q8k_cpu()
| void matvec_q6k_q8k_cpu | ( | const std::vector< block_q6_K > & | mat_q6k, |
| const std::vector< block_q8_K > & | vec_q8k, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols, | ||
| bool | log_calls | ||
| ) |
Computes matrix-vector product between Q6_K matrix and Q8_K vector on CPU.
- Parameters
-
mat_q6k Q6_K matrix vec_q8k Q8_K vector out_f32 Output float vector rows Number of matrix rows cols Number of matrix columns log_calls Whether to log computation details
Definition at line 940 of file quantization.cpp.
References GGML_QK_K, j, and vec_dot_q6_k_q8_k_cpu().
◆ quantize_fp32_to_q8_K()
| std::vector< block_q8_K > quantize_fp32_to_q8_K | ( | const std::vector< float > & | f_data | ) |
Quantizes float32 data to Q8_K format.
- Parameters
-
f_data Input float vector
- Returns
- Vector of Q8_K blocks
Definition at line 762 of file quantization.cpp.
References Logger::debug(), fp32_to_fp16(), GGML_QK_K, id, j, Q8K_SCALE_FACTOR, SAFE_MAX, and SAFE_MIN.
◆ quantize_q4_k_m()
Quantizes float32 data to Q4_K format.
- Parameters
-
f_data Input float array q_data Output quantized data num_elements Number of elements to quantize
Definition at line 309 of file quantization.cpp.
References fp32_to_fp16(), GGML_QK_K, GGUF_EPSILON, GGUF_SMALL_VAL, j, k, K_MIN_VALUES, K_SCALE_VALUES, Q4K_OFFSET, Q4K_SCALE_FACTOR, SAFE_MAX, and SAFE_MIN.
◆ quantize_q6_k()
Quantizes float32 data to Q6_K format.
- Parameters
-
f_data Input float array q_data Output quantized data num_elements Number of elements to quantize
Definition at line 582 of file quantization.cpp.
References fp32_to_fp16(), GGML_QK_K, GGUF_EPSILON, j, Q6K_OFFSET, Q6K_SCALE_FACTOR, block_q6_K::ql, SAFE_MAX, SAFE_MIN, scale, and sub.
◆ vec_dot_q4_k_q8_k_cpu()
| float vec_dot_q4_k_q8_k_cpu | ( | int | n, |
| const std::vector< block_q4_K > & | x_vec, | ||
| const std::vector< block_q8_K > & | y_vec, | ||
| bool | log_this_call | ||
| ) |
Computes dot product between Q4_K and Q8_K vectors on CPU.
- Parameters
-
n Number of blocks x_vec Q4_K vector y_vec Q8_K vector log_this_call Whether to log computation details
- Returns
- Dot product result
Definition at line 965 of file quantization.cpp.
References Logger::debug(), fp16_to_fp32(), g_vec_dot_q4_k_q8_k_log_count, get_scale_min_indices_q4_K(), GGML_QK_K, j, k, K_MIN_VALUES, K_SCALE_VALUES, n, block_q8_K::qs, scale, and sub.
Referenced by matvec_q4k_q8k_cpu().
◆ vec_dot_q6_k_q8_k_cpu()
| float vec_dot_q6_k_q8_k_cpu | ( | int | n, |
| const std::vector< block_q6_K > & | x, | ||
| const std::vector< block_q8_K > & | y, | ||
| bool | log_this_call | ||
| ) |
Computes dot product between Q6_K and Q8_K vectors on CPU.
- Parameters
-
n Number of blocks x Q6_K vector y Q8_K vector log_this_call Whether to log computation details
- Returns
- Dot product result
Definition at line 815 of file quantization.cpp.
References a, Logger::debug(), fp16_to_fp32(), GGML_QK_K, j, k, n, and scale.
Referenced by matvec_q6k_q8k_cpu().
