#include <vector>#include <string>#include <cstdint>#include <functional>#include "quantization.h"#include "model_constants.h"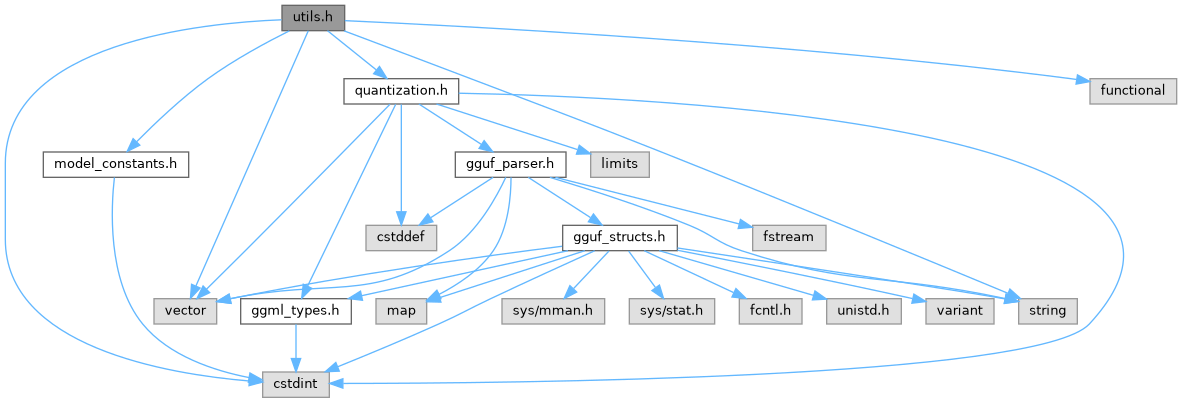

Go to the source code of this file.
Function Documentation
◆ apply_rope_batch_cpu()
| void apply_rope_batch_cpu | ( | std::vector< float > & | q_batch, |
| std::vector< float > & | k_batch, | ||
| int | num_tokens, | ||
| int | num_q_heads, | ||
| int | num_kv_heads, | ||
| int | head_dim, | ||
| int | start_pos_in_sequence, | ||
| const std::vector< std::pair< float, float > > & | all_freqs_cis, | ||
| int | max_pos_embeddings, | ||
| bool | use_adjacent_pairing | ||
| ) |
Definition at line 491 of file utils.cpp.
References Logger::error(), j, and Logger::warning().
Referenced by CPUBatchProcessor::forward_cpu_batch(), and ember_ir::Interpreter::run_nodes().
◆ apply_rope_vector()
| void apply_rope_vector | ( | std::vector< float > & | x, |
| int | num_heads, | ||
| int | head_dim, | ||
| int | current_token_pos, | ||
| const std::vector< std::pair< float, float > > & | all_freqs_cis, | ||
| int | max_pos_embeddings, | ||
| bool | use_adjacent_pairing | ||
| ) |
Definition at line 428 of file utils.cpp.
References Logger::error(), j, and Logger::warning().
Referenced by TinyLlamaModel::forward(), CPUBatchProcessor::forward_cpu_batch(), and TinyLlamaModel::forward_cpu_batch_generation().
◆ argmax()
| int argmax | ( | const std::vector< float > & | v | ) |
◆ bf16vec_to_float_vec()
| std::vector< float > bf16vec_to_float_vec | ( | const std::vector< uint16_t > & | v_bf16 | ) |
Definition at line 199 of file utils.cpp.
References bfloat16_to_float32(), and j.
Referenced by TinyLlamaModel::ensure_down_proj_dequantized(), TinyLlamaModel::ensure_embed_tokens_dequantized(), TinyLlamaModel::ensure_gate_proj_dequantized(), TinyLlamaModel::ensure_k_proj_dequantized(), TinyLlamaModel::ensure_lm_head_dequantized(), TinyLlamaModel::ensure_o_proj_dequantized(), TinyLlamaModel::ensure_q_proj_dequantized(), TinyLlamaModel::ensure_up_proj_dequantized(), TinyLlamaModel::ensure_v_proj_dequantized(), TinyLlamaModel::forward(), CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), TinyLlamaModel::forward_cpu_logits_batch(), TinyLlamaModel::initialize_gpu_and_rope(), TinyLlamaModel::initialize_weights(), and TinyLlamaModel::lookup_embedding().
◆ bfloat16_to_float32()
Definition at line 145 of file utils.cpp.
Referenced by bf16vec_to_float_vec(), bfloat16_vector_to_float32(), and matvec_bf16_f32_vector_cpu().
◆ bfloat16_vector_to_float32()
| std::vector< float > bfloat16_vector_to_float32 | ( | const std::vector< uint16_t > & | bf16_vec | ) |
Definition at line 166 of file utils.cpp.
References bfloat16_to_float32(), and j.
◆ calculate_attention_scores()
| void calculate_attention_scores | ( | const std::vector< float > & | Q, |
| const std::vector< float > & | K, | ||
| std::vector< float > & | scores, | ||
| int | seq_len, | ||
| int | head_dim, | ||
| float | scale | ||
| ) |
Definition at line 1258 of file utils.cpp.
References attention::ATTENTION_SCALE_BASE, j, attention::MAX_SCALE, attention::MIN_SCALE, and scale.
◆ dequantize_q8_k()
| void dequantize_q8_k | ( | const std::vector< block_q8_K > & | q8k_vec, |
| std::vector< float > & | out_f32, | ||
| int | n, | ||
| bool | log_this_block | ||
| ) |
Definition at line 1052 of file quantization.cpp.
References Logger::debug(), fp16_to_fp32(), GGML_QK_K, j, and n.
Referenced by TinyLlamaModel::ensure_down_proj_dequantized(), TinyLlamaModel::ensure_embed_tokens_dequantized(), TinyLlamaModel::ensure_gate_proj_dequantized(), TinyLlamaModel::ensure_k_proj_dequantized(), TinyLlamaModel::ensure_lm_head_dequantized(), TinyLlamaModel::ensure_o_proj_dequantized(), TinyLlamaModel::ensure_q_proj_dequantized(), TinyLlamaModel::ensure_up_proj_dequantized(), TinyLlamaModel::ensure_v_proj_dequantized(), and matvec_q8k_f32_vector_cpu().
◆ float32_to_bfloat16()
◆ gelu_cpu()
| void gelu_cpu | ( | const std::vector< float > & | x, |
| std::vector< float > & | out | ||
| ) |
◆ gelu_new_cpu()
| void gelu_new_cpu | ( | const std::vector< float > & | x, |
| std::vector< float > & | out | ||
| ) |
Definition at line 860 of file utils.cpp.
Referenced by TinyLlamaModel::forward().
◆ load_rmsnorm_bin()
| std::vector< std::vector< float > > load_rmsnorm_bin | ( | const std::string & | filename, |
| int | num_tokens, | ||
| int | hidden_size | ||
| ) |
◆ log_raw_float_pointer()
◆ log_vec_stats()
| void log_vec_stats | ( | const std::string & | name, |
| const std::vector< float > & | v | ||
| ) |
◆ log_vector_summary()
| void log_vector_summary | ( | const std::string & | name, |
| const std::vector< float > & | v, | ||
| int | head_count | ||
| ) |
◆ log_vector_summary_detailed()
| void log_vector_summary_detailed | ( | const std::string & | name, |
| const std::vector< float > & | v, | ||
| int | current_pos, | ||
| int | current_layer, | ||
| int | N = 5 |
||
| ) |
◆ log_vector_summary_with_tail()
| void log_vector_summary_with_tail | ( | const std::string & | name, |
| const std::vector< float > & | v, | ||
| int | head_count, | ||
| int | tail_count | ||
| ) |
Definition at line 235 of file utils.cpp.
References Logger::info(), j, name, SAFE_MIN, and v.
◆ matmul_f32_f32_batch_cpu()
| void matmul_f32_f32_batch_cpu | ( | const std::vector< float > & | mat_weights, |
| const std::vector< float > & | batch_input_activations, | ||
| std::vector< float > & | batch_output_activations, | ||
| int | num_tokens, | ||
| int | output_dim, | ||
| int | input_dim | ||
| ) |
Definition at line 872 of file utils.cpp.
References dot_f32_as_f64(), Logger::error(), j, and ember::parallel_for().
Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), TinyLlamaModel::forward_cpu_logits_batch(), ember_ir::Interpreter::mor_step(), and ember_ir::Interpreter::run_nodes().
◆ matmul_q4k_f32_batch_cpu()
| void matmul_q4k_f32_batch_cpu | ( | const std::vector< block_q4_K > & | mat_q4k, |
| const std::vector< float > & | batch_input_activations, | ||
| std::vector< float > & | batch_output_activations, | ||
| int | num_tokens, | ||
| int | output_dim, | ||
| int | input_dim | ||
| ) |
Definition at line 1155 of file utils.cpp.
References Logger::error(), j, and matvec_q4k_f32_vector_cpu().
Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), and TinyLlamaModel::forward_cpu_logits_batch().
◆ matmul_q6k_f32_batch_cpu()
| void matmul_q6k_f32_batch_cpu | ( | const std::vector< block_q6_K > & | mat_q6k, |
| const std::vector< float > & | batch_input_activations, | ||
| std::vector< float > & | batch_output_activations, | ||
| int | num_tokens, | ||
| int | output_dim, | ||
| int | input_dim | ||
| ) |
Definition at line 1117 of file utils.cpp.
References Logger::error(), j, and matvec_q6k_f32_vector_cpu().
Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), and TinyLlamaModel::forward_cpu_logits_batch().
◆ matmul_q8_0_f32_batch_cpu()
| void matmul_q8_0_f32_batch_cpu | ( | const std::vector< block_q8_0 > & | mat_q8_0, |
| const std::vector< float > & | batch_input_activations, | ||
| std::vector< float > & | batch_output_activations, | ||
| int | num_tokens, | ||
| int | output_dim, | ||
| int | input_dim | ||
| ) |
Definition at line 1036 of file utils.cpp.
References Logger::error(), j, and matvec_q8_0_f32_vector_cpu().
Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), and TinyLlamaModel::forward_cpu_logits_batch().
◆ matmul_q8k_f32_batch_cpu()
| void matmul_q8k_f32_batch_cpu | ( | const std::vector< block_q8_K > & | mat_q8k, |
| const std::vector< float > & | batch_input_activations, | ||
| std::vector< float > & | batch_output_activations, | ||
| int | num_tokens, | ||
| int | output_dim, | ||
| int | input_dim | ||
| ) |
Definition at line 1074 of file utils.cpp.
References GGML_QK_K, j, and matvec_q8k_f32_vector_cpu().
◆ matmul_rows_f32_batch_cpu()
| void matmul_rows_f32_batch_cpu | ( | const std::function< void(int64_t, float *)> & | row_fn, |
| const float * | batch_input_activations, | ||
| float * | batch_output_activations, | ||
| int | num_tokens, | ||
| int | output_dim, | ||
| int | input_dim | ||
| ) |
Definition at line 916 of file utils.cpp.
References dot_f32_as_f64(), j, and ember::parallel_for().
Referenced by ember_ir::Interpreter::run_nodes().
◆ matvec_bf16_f32_vector_cpu()
| void matvec_bf16_f32_vector_cpu | ( | const std::vector< uint16_t > & | mat_bf16, |
| const std::vector< float > & | vec_f32, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols | ||
| ) |
Definition at line 1192 of file utils.cpp.
References bfloat16_to_float32(), c, Logger::error(), and j.
Referenced by TinyLlamaModel::forward().
◆ matvec_f32_f32_vector_cpu()
| void matvec_f32_f32_vector_cpu | ( | const std::vector< float > & | mat_f32, |
| const std::vector< float > & | vec_f32, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols | ||
| ) |
Definition at line 365 of file utils.cpp.
References dot_f32_as_f64(), Logger::error(), j, and ember::parallel_for().
Referenced by TinyLlamaModel::forward(), and matvec_q8k_f32_vector_cpu().
◆ matvec_q4k_f32_vector_cpu()
| void matvec_q4k_f32_vector_cpu | ( | const std::vector< block_q4_K > & | mat_q4k, |
| const std::vector< float > & | vec_f32, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols, | ||
| bool | log_first_block = false |
||
| ) |
Definition at line 983 of file utils.cpp.
References dequantize_q4_k_m(), GGML_QK_K, and j.
Referenced by TinyLlamaModel::forward(), and matmul_q4k_f32_batch_cpu().
◆ matvec_q6k_f32_vector_cpu()
| void matvec_q6k_f32_vector_cpu | ( | const std::vector< block_q6_K > & | mat_q6k, |
| const std::vector< float > & | vec_f32, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols, | ||
| bool | log_first_block = false |
||
| ) |
Definition at line 930 of file utils.cpp.
References dequantize_q6_k(), GGML_QK_K, and j.
Referenced by TinyLlamaModel::forward(), and matmul_q6k_f32_batch_cpu().
◆ matvec_q8_0_f32_vector_cpu()
| void matvec_q8_0_f32_vector_cpu | ( | const std::vector< block_q8_0 > & | mat_q8_0, |
| const std::vector< float > & | vec_f32, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols, | ||
| bool | log_first_block = false |
||
| ) |
Definition at line 294 of file utils.cpp.
References dequantize_q8_0_block(), GGML_QK8_0, and j.
Referenced by TinyLlamaModel::forward(), and matmul_q8_0_f32_batch_cpu().
◆ matvec_q8k_f32_vector_cpu()
| void matvec_q8k_f32_vector_cpu | ( | const std::vector< block_q8_K > & | mat_q8k, |
| const std::vector< float > & | vec_f32, | ||
| std::vector< float > & | out_f32, | ||
| int | rows, | ||
| int | cols, | ||
| bool | log_first_block = false |
||
| ) |
Definition at line 399 of file utils.cpp.
References dequantize_q8_k(), GGML_QK_K, Logger::info(), j, and matvec_f32_f32_vector_cpu().
Referenced by TinyLlamaModel::forward(), and matmul_q8k_f32_batch_cpu().
◆ moe_ffn_f32_cpu()
| void moe_ffn_f32_cpu | ( | const float * | x, |
| int | d, | ||
| int | d_ff, | ||
| int | E, | ||
| int | k, | ||
| const float * | router, | ||
| const float * | gate_exps, | ||
| const float * | up_exps, | ||
| const float * | down_exps, | ||
| float * | out, | ||
| bool | renorm = true |
||
| ) |
Definition at line 709 of file utils.cpp.
References dot_f32_as_f64(), j, k, and out.
Referenced by TinyLlamaModel::forward(), CPUBatchProcessor::forward_cpu_batch(), and moe_ffn_routed_f32_cpu().
◆ moe_ffn_routed_f32_cpu()
| void moe_ffn_routed_f32_cpu | ( | const float * | x, |
| int | d, | ||
| int | d_ff, | ||
| int | E, | ||
| int | k, | ||
| const float * | router, | ||
| const float * | gate_exps, | ||
| const float * | up_exps, | ||
| const float * | down_exps, | ||
| float * | out, | ||
| bool | renorm, | ||
| bool | sigmoid, | ||
| const float * | bias, | ||
| int | groups_n, | ||
| int | groups_top | ||
| ) |
Definition at line 763 of file utils.cpp.
References a, c, dot_f32_as_f64(), j, k, moe_ffn_f32_cpu(), out, and sigmoid.
Referenced by ember_ir::Interpreter::run_nodes().
◆ rmsnorm_batch_cpu()
| void rmsnorm_batch_cpu | ( | const std::vector< float > & | x_batch, |
| const std::vector< float > & | weight, | ||
| std::vector< float > & | out_batch, | ||
| int | num_tokens, | ||
| int | hidden_size, | ||
| float | eps = numeric::DEFAULT_EPS |
||
| ) |
Definition at line 613 of file utils.cpp.
References Logger::error(), j, and SAFE_SQRT.
Referenced by CPUBatchProcessor::forward_cpu_batch(), TinyLlamaModel::forward_cpu_batch_generation(), TinyLlamaModel::forward_cpu_logits_batch(), and ember_ir::Interpreter::run_nodes().
◆ rmsnorm_vector_cpu()
| void rmsnorm_vector_cpu | ( | const std::vector< float > & | x, |
| const std::vector< float > & | weight, | ||
| std::vector< float > & | out, | ||
| float | eps = numeric::DEFAULT_EPS |
||
| ) |
Definition at line 648 of file utils.cpp.
References Logger::error(), j, numeric::MIN_NORM_EPS, n, out, SAFE_MAX, and SAFE_SQRT.
Referenced by TinyLlamaModel::forward().
◆ silu_cpu()
| void silu_cpu | ( | const std::vector< float > & | x, |
| std::vector< float > & | out | ||
| ) |
Definition at line 842 of file utils.cpp.
Referenced by TinyLlamaModel::forward(), and ember_ir::Interpreter::run_nodes().
◆ simd_dot_product()
Definition at line 36 of file utils.cpp.
Referenced by TinyLlamaModel::forward_cpu_batch_generation().
◆ simd_scaled_add()
Definition at line 93 of file utils.cpp.
Referenced by TinyLlamaModel::forward_cpu_batch_generation().
◆ softmax_vector_cpu()
| void softmax_vector_cpu | ( | const std::vector< float > & | x, |
| std::vector< float > & | out | ||
| ) |
Definition at line 675 of file utils.cpp.
Referenced by attention_batch_cpu(), attention_batch_cpu_sequence_aware(), attention_bias_batch_cpu(), attention_relkv_batch_cpu(), attention_rows_batch_cpu(), attention_window_batch_cpu(), TinyLlamaModel::forward(), and TinyLlamaModel::forward_cpu_batch_generation().
◆ uint8_vector_to_uint16_vector()
| std::vector< uint16_t > uint8_vector_to_uint16_vector | ( | const std::vector< uint8_t > & | bytes, |
| size_t | numel | ||
| ) |
◆ weighted_sum_probs_v()
| void weighted_sum_probs_v | ( | const std::vector< float > & | probs, |
| const std::vector< float > & | V, | ||
| std::vector< float > & | out, | ||
| int | seq_len, | ||
| int | head_dim | ||
| ) |
Definition at line 1227 of file utils.cpp.
References Logger::error(), j, and out.
◆ write_vector_to_file()
| bool write_vector_to_file | ( | const std::string & | filename, |
| const std::vector< float > & | vec | ||
| ) |
Definition at line 1301 of file utils.cpp.
References Logger::error(), Logger::info(), and j.
