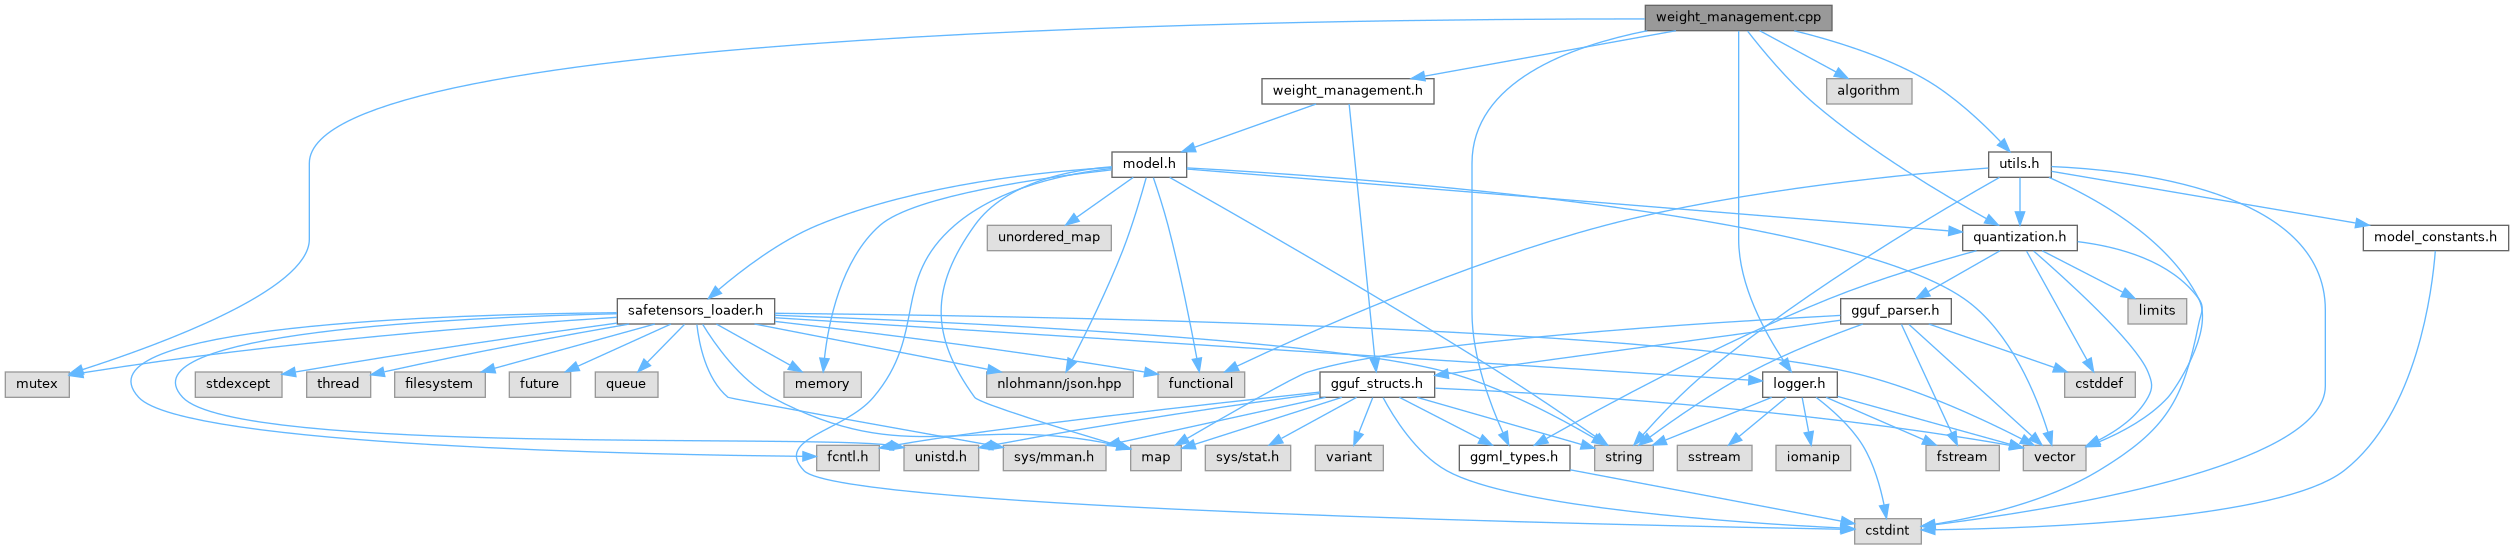
879 {
880 Logger::info(
"Mapping GGUF weights to model fields (ULTRA-OPTIMIZED VERSION)...");
881
883
884
885 if (
gguf.mapped_tensor_data !=
nullptr &&
gguf.mapped_tensor_data_size > 0) {
888 Logger::info(
"map_gguf_weights: Using mmap mode (ZERO-COPY). Size: " +
889 std::to_string(
gguf.mapped_tensor_data_size) +
" bytes.");
890 }
else if (!
gguf.tensor_data.empty()) {
892 Logger::info(
"map_gguf_weights: Using non-mmap mode. Size: " +
893 std::to_string(
gguf.tensor_data.size()) +
" bytes.");
894 } else {
895 Logger::error(
"GGUF tensor data is not available. Cannot map weights.");
896 return;
897 }
898
900 Logger::info(
"Processing " + std::to_string(
num_tensors) +
" tensors with ultra-optimized parallel mapping...");
901
902
903 std::vector<std::pair<std::string, GGUFTensorInfo>>
tensor_pairs;
905 for (
const auto&
pair :
gguf.tensor_infos_map) {
907 }
908
909
913
914 for (
auto&
layer : model.layers) {
922 }
923
924
927
931 }
932
933
936 if (
name[0] ==
'o' ||
name[0] ==
't') {
938 }
else if (
name.size() > 4 &&
name[0] ==
'b' &&
name[1] ==
'l' &&
name[2] ==
'k' &&
name[3] ==
'.') {
939
946 }
949 }
950 }
951 }
952 }
953
958
959
961 try {
965
966
973 break;
974 }
979 break;
980 }
984 break;
985 }
990 break;
991 }
996 break;
997 }
1002 break;
1003 }
1004 default:
1006 break;
1007 }
1009 continue;
1010 }
1011
1013 switch (info.
type) {
1018 break;
1019 }
1023 break;
1024 }
1029 break;
1030 }
1035 break;
1036 }
1041 break;
1042 }
1047 break;
1048 }
1049 default:
1051 break;
1052 }
1054 continue;
1055 }
1056
1064 continue;
1065 }
1066
1067 }
catch (
const std::exception&
e) {
1071 }
1072 }
1073
1074
1075 #pragma omp parallel for schedule(static) if(model.layers.size() > 4)
1079
1081
1082 try {
1087
1088
1090 if (
last_dot == std::string::npos)
continue;
1091
1093
1094
1095 #define LEGACY_OR_THROW(target_f32) \
1096 default: \
1097 if (!dequant_legacy_to_f32(info, tensor_data_ptr, target_f32)) \
1098 throw std::runtime_error(name + ": unsupported tensor type " + ggml_type_name(info.type)); \
1099 break;
1100 #define FAST_COPY_WEIGHT(target_vec, block_type) \
1101 target_vec.resize(info.size_in_bytes / sizeof(block_type)); \
1102 std::memcpy(target_vec.data(), tensor_data_ptr, info.size_in_bytes);
1103
1104
1107
1108 if (
name_len > 10 &&
name.find(
"attn_") != std::string::npos) {
1109 if (
name.find(
"attn_q.weight") != std::string::npos) {
1110 switch (info.
type) {
1119 std::to_string(
layer.q_proj_f32.size()) +
1120 " into layer_idx=" + std::to_string(
layer_idx));
1121 break;
1123 }
1124 }
else if (
name.find(
"attn_k.weight") != std::string::npos) {
1125 switch (info.
type) {
1134 }
1135 }
else if (
name.find(
"attn_v.weight") != std::string::npos) {
1136 switch (info.
type) {
1145 }
1146 }
else if (
name.find(
"attn_output.weight") != std::string::npos) {
1147 switch (info.
type) {
1156 }
1157 }
else if (
name.find(
"attn_norm.weight") != std::string::npos) {
1161 }
1162 }
else if (
name_len > 10 &&
name.find(
"ffn_") != std::string::npos) {
1163 if (
name.find(
"ffn_gate_inp.weight") != std::string::npos) {
1168 }
else if (
name.find(
"_exps.weight") != std::string::npos) {
1169 std::vector<float>&
dst =
name.find(
"ffn_gate_exps") != std::string::npos ?
layer.moe_gate_exps_f32
1170 :
name.find(
"ffn_up_exps") != std::string::npos ?
layer.moe_up_exps_f32
1171 :
layer.moe_down_exps_f32;
1174 throw std::runtime_error(
name +
": MoE expert stacks must be F32, F16 or Q4_0/Q4_1/Q5_0/Q5_1 (got " +
1176 }
else if (
name.find(
"ffn_gate.weight") != std::string::npos) {
1177 switch (info.
type) {
1186 }
1187 }
else if (
name.find(
"ffn_up.weight") != std::string::npos) {
1188 switch (info.
type) {
1197 }
1198 }
else if (
name.find(
"ffn_down.weight") != std::string::npos) {
1199 switch (info.
type) {
1208 }
1209 }
else if (
name.find(
"ffn_norm.weight") != std::string::npos) {
1213 }
1214 }
1215
1216 #undef FAST_COPY_WEIGHT
1217 #undef LEGACY_OR_THROW
1218 }
1220 }
catch (
const std::exception&
e) {
1224 }
1225 }
1226
1228 std::to_string(
num_tensors) +
" tensors processed successfully (errors: " +
1229 std::to_string(
error_count.load()) +
") with ultra-optimized parallel mapping");
1230
1232 throw std::runtime_error(
"GGUF weight mapping failed for " + std::to_string(
error_count.load()) +
1234}
static void info(const std::string &message)
static void error(const std::string &message)
std::vector< block_q6_K > embed_tokens_q6k
std::vector< float > final_norm_f32
std::vector< block_q4_K > lm_head_q4k
std::vector< block_q6_K > lm_head_q6k
std::vector< block_q5_K > lm_head_q5k
std::vector< LayerWeights > layers
std::vector< block_q8_0 > embed_tokens_q8_0
std::vector< block_q4_K > embed_tokens_q4k
std::vector< block_q8_0 > lm_head_q8_0
std::vector< block_q5_K > embed_tokens_q5k
std::vector< block_q8_K > embed_tokens_q8k
std::vector< float > embed_tokens_f32
std::vector< float > lm_head_f32
std::vector< block_q8_K > lm_head_q8k
Information about a tensor stored in a GGUF file.
Structure holding all weights for a single transformer layer.
8-bit K-quantized block structure with block sums
#define FAST_COPY_WEIGHT(target_vec, block_type)
#define LEGACY_OR_THROW(target_f32)