ember.cpp 0.1.0
C++ inference engine for Llama-family and paperkiln models (CPU, CUDA, WebAssembly)
Loading...
Searching...
No Matches
weight_management.h File Reference
#include "gguf_structs.h"
#include "model.h"
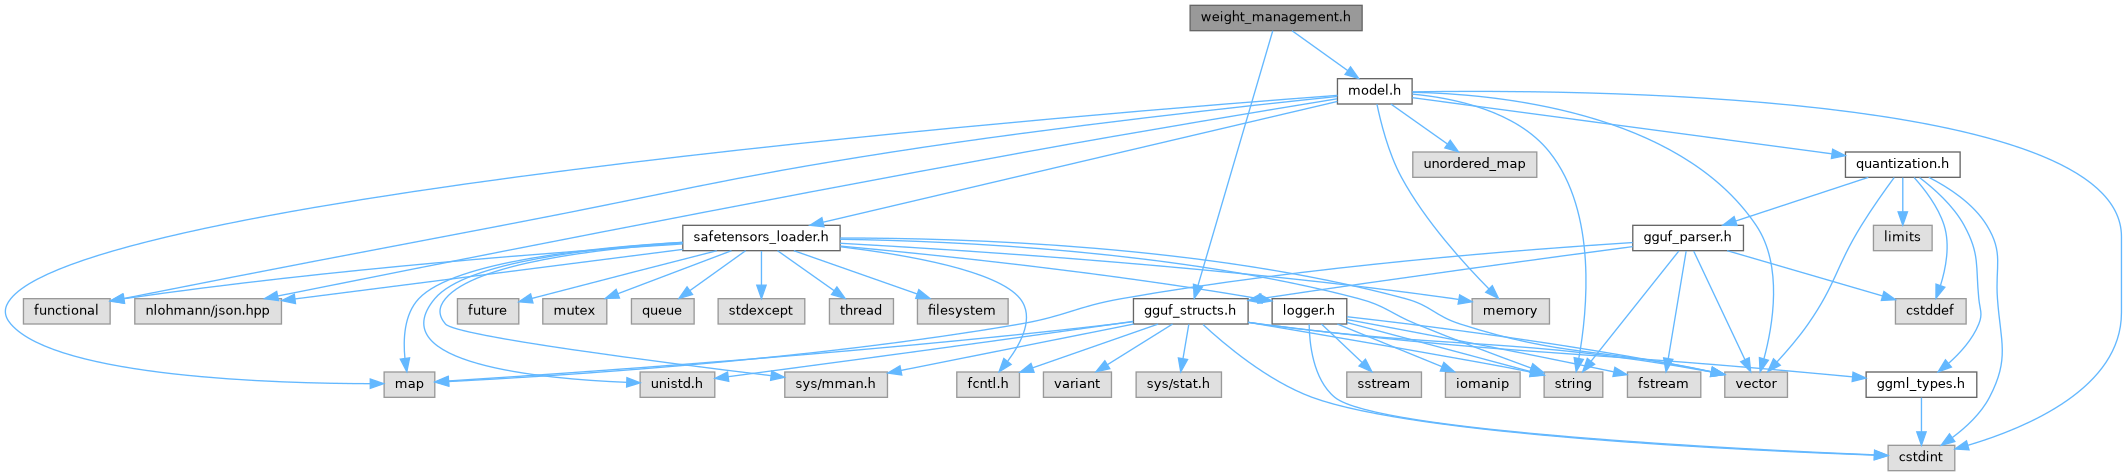
Include dependency graph for weight_management.h:
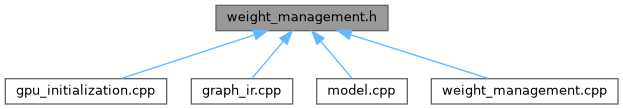
This graph shows which files directly or indirectly include this file:

Go to the source code of this file.

Functions

bool dequant_legacy_to_f32 (const GGUFTensorInfo &info, const uint8_t *src, std::vector< float > &out)
 
bool dequant_span_to_f32 (GGMLType t, const uint8_t *src, size_t first, size_t n, float *out)
 

Function Documentation

◆ dequant_legacy_to_f32()

bool dequant_legacy_to_f32 ( const GGUFTensorInfo &  info,
const uint8_t *  src,
std::vector< float > &  out 
)

Definition at line 767 of file weight_management.cpp.

767 {
768 const GGMLType t = info.type;
769 const size_t n = info.num_elements;
771 out.resize(n);
772 dequant_span_to_f32(t, src, 0, n, out.data());
773 return true;
774 }
778 if (!(q4_0 || q4_1 || q5_0 || q5_1 || k_quant)) return false;
779 const size_t width = k_quant ? GGML_QK_K : 32;
780 if (n % width != 0)
781 throw std::runtime_error(std::string(ggml_type_name(t)) + " tensor with " + std::to_string(n) +
782 " elements (not a multiple of " + std::to_string(width) + ")");
783 const size_t bsz = ggml_type_size(t), nb = n / width;
784 if (info.size_in_bytes < nb * bsz) throw std::runtime_error("legacy-quantised tensor is shorter than its element count implies");
785 out.resize(n);
786 dequant_span_to_f32(t, src, 0, n, out.data());
787 return true;
788}
GGMLType
Enumeration of GGML tensor data types.
Definition ggml_types.h:21
@ GGML_TYPE_BF16
Definition ggml_types.h:40
@ GGML_TYPE_Q5_0
Definition ggml_types.h:27
@ GGML_TYPE_F16
Definition ggml_types.h:23
@ GGML_TYPE_Q6_K
Definition ggml_types.h:35
@ GGML_TYPE_Q4_1
Definition ggml_types.h:25
@ GGML_TYPE_Q5_K
Definition ggml_types.h:34
@ GGML_TYPE_Q5_1
Definition ggml_types.h:28
@ GGML_TYPE_Q4_K
Definition ggml_types.h:33
@ GGML_TYPE_Q4_0
Definition ggml_types.h:24
constexpr size_t GGML_QK_K
Block size constants for different quantization formats.
Definition gguf_parser.h:42
int n
node out
size_t j
size_t ggml_type_size(GGMLType type)
Gets the size in bytes of a GGML type.
const char * ggml_type_name(GGMLType type)
Gets the string name of a GGML type.
size_t size_in_bytes
size_t num_elements
bool dequant_span_to_f32(GGMLType t, const uint8_t *src, size_t first, size_t n, float *out)

References dequant_span_to_f32(), GGML_QK_K, GGML_TYPE_BF16, GGML_TYPE_F16, ggml_type_name(), GGML_TYPE_Q4_0, GGML_TYPE_Q4_1, GGML_TYPE_Q4_K, GGML_TYPE_Q5_0, GGML_TYPE_Q5_1, GGML_TYPE_Q5_K, GGML_TYPE_Q6_K, ggml_type_size(), j, n, GGUFTensorInfo::num_elements, out, GGUFTensorInfo::size_in_bytes, and GGUFTensorInfo::type.

Referenced by ember_ir::Interpreter::bind_tensor().

◆ dequant_span_to_f32()

bool dequant_span_to_f32 ( GGMLType  t,
const uint8_t *  src,
size_t  first,
size_t  n,
float *  out 
)

Definition at line 802 of file weight_management.cpp.

802 {
803 if (t == GGMLType::GGML_TYPE_F16) {
804 const float* table = fp16_table();
805 const uint8_t* p = src + 2 * first;
806 for (size_t i = 0; i < n; ++i) {
807 uint16_t h;
808 std::memcpy(&h, p + 2 * i, 2);
809 out[i] = table[h];
810 }
811 return true;
812 }
813 if (t == GGMLType::GGML_TYPE_BF16) { // the top 16 bits of an f32: exact
814 for (size_t i = 0; i < n; ++i) {
815 uint16_t h;
816 std::memcpy(&h, src + 2 * (first + i), 2);
817 const uint32_t bits = static_cast<uint32_t>(h) << 16;
818 std::memcpy(out + i, &bits, 4);
819 }
820 return true;
821 }
823 const block_q8_0* blocks = reinterpret_cast<const block_q8_0*>(src) + first / GGML_QK8_0;
824 for (size_t b = 0; b < n / GGML_QK8_0; ++b) dequantize_q8_0_block(blocks + b, out + b * GGML_QK8_0);
825 return true;
826 }
827 // K-quants: 256-wide super-blocks (first and n multiples of GGML_QK_K), ember's block dequantisers.
829 const block_q4_K* blocks = reinterpret_cast<const block_q4_K*>(src) + first / GGML_QK_K;
830 for (size_t b = 0; b < n / GGML_QK_K; ++b) dequantize_q4_k_m(blocks + b, out + b * GGML_QK_K, GGML_QK_K);
831 return true;
832 }
834 const block_q5_K* blocks = reinterpret_cast<const block_q5_K*>(src) + first / GGML_QK_K;
835 for (size_t b = 0; b < n / GGML_QK_K; ++b) dequantize_q5_k(blocks + b, out + b * GGML_QK_K);
836 return true;
837 }
839 const block_q6_K* blocks = reinterpret_cast<const block_q6_K*>(src) + first / GGML_QK_K;
840 for (size_t b = 0; b < n / GGML_QK_K; ++b) dequantize_q6_k(blocks + b, out + b * GGML_QK_K, GGML_QK_K);
841 return true;
842 }
845 if (!(q4_0 || q4_1 || q5_0 || q5_1)) return false;
846 const bool has_min = q4_1 || q5_1, five_bit = q5_0 || q5_1;
847 const size_t bsz = ggml_type_size(t), b0 = first / 32, nb = n / 32;
848 for (size_t b = 0; b < nb; ++b) {
849 const uint8_t* p = src + (b0 + b) * bsz;
850 uint16_t dh, mh = 0;
851 std::memcpy(&dh, p, 2);
852 p += 2;
853 if (has_min) { std::memcpy(&mh, p, 2); p += 2; }
854 uint32_t qh = 0;
855 if (five_bit) { std::memcpy(&qh, p, 4); p += 4; }
856 const float d = fp16_to_fp32(dh, false), m = has_min ? fp16_to_fp32(mh, false) : 0.0f;
857 const int offset = has_min ? 0 : (five_bit ? 16 : 8);
858 float* y = out + b * 32;
859 for (int j = 0; j < 16; ++j) {
860 int lo = p[j] & 0x0F, hi = p[j] >> 4;
861 if (five_bit) {
862 lo |= ((qh >> j) & 1) << 4;
863 hi |= ((qh >> (j + 16)) & 1) << 4;
864 }
865 // ggml's dequantize_row_q4_0 / q5_0 write the product alone, q4_1 / q5_1 the product plus m (paperkiln
866 // spec/IR_SPEC.md 4.7): adding a +0 m to a -0 product would give +0, so the 0-offset forms add nothing.
867 if (has_min) {
868 y[j] = static_cast<float>(lo - offset) * d + m;
869 y[j + 16] = static_cast<float>(hi - offset) * d + m;
870 } else {
871 y[j] = static_cast<float>(lo - offset) * d;
872 y[j + 16] = static_cast<float>(hi - offset) * d;
873 }
874 }
875 }
876 return true;
877}
@ GGML_TYPE_Q8_0
Definition ggml_types.h:29
constexpr size_t GGML_QK8_0
Definition gguf_parser.h:43
const float * p[kIrDepthSourcesMax]
void dequantize_q4_k_m(const block_q4_K *qblock, float *output, int num_weights_in_block, bool log_this_block)
void dequantize_q5_k(const block_q5_K *qblock, float *output)
float fp16_to_fp32(uint16_t h, bool is_gguf_scale_field)
Converts a 16-bit floating point number to 32-bit float.
void dequantize_q8_0_block(const block_q8_0 *qblock, float *output)
Dequantizes a Q8_0 block to float32.
void dequantize_q6_k(const block_q6_K *qblock, float *output, int num_weights_in_block, bool log_this_block)
4-bit K-quantized block structure
5-bit K-quantized block structure (ggml's block_q5_K)
6-bit K-quantized block structure
Simple 8-bit quantized block structure.
static const float * fp16_table()

References dequantize_q4_k_m(), dequantize_q5_k(), dequantize_q6_k(), dequantize_q8_0_block(), fp16_table(), fp16_to_fp32(), GGML_QK8_0, GGML_QK_K, GGML_TYPE_BF16, GGML_TYPE_F16, GGML_TYPE_Q4_0, GGML_TYPE_Q4_1, GGML_TYPE_Q4_K, GGML_TYPE_Q5_0, GGML_TYPE_Q5_1, GGML_TYPE_Q5_K, GGML_TYPE_Q6_K, GGML_TYPE_Q8_0, ggml_type_size(), j, n, out, and p.

Referenced by ember_ir::Interpreter::bind_tensor(), dequant_legacy_to_f32(), and ember_ir::Interpreter::run_nodes().
